Understanding Mutation: The Raw Mechanics
A mutation is simply a change in the nucleotide sequence of DNA. That's it. It happens during replication when a polymerase slips, when radiation hits a strand, or when two chromosomes exchange material and something gets copied wrong. Most of the time it doesn't matter. Sometimes it kills the cell. Rarely, it does something the organism can use. I used to think people wanted the textbook definition when they asked about this. They don't. They want to know how to spot one, what it actually does, and why their experiment fell apart. So here's the practical version.
What Is A Mutation
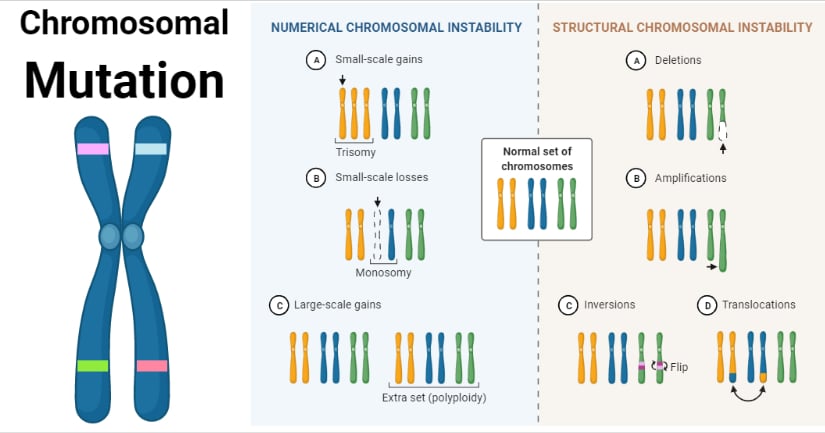
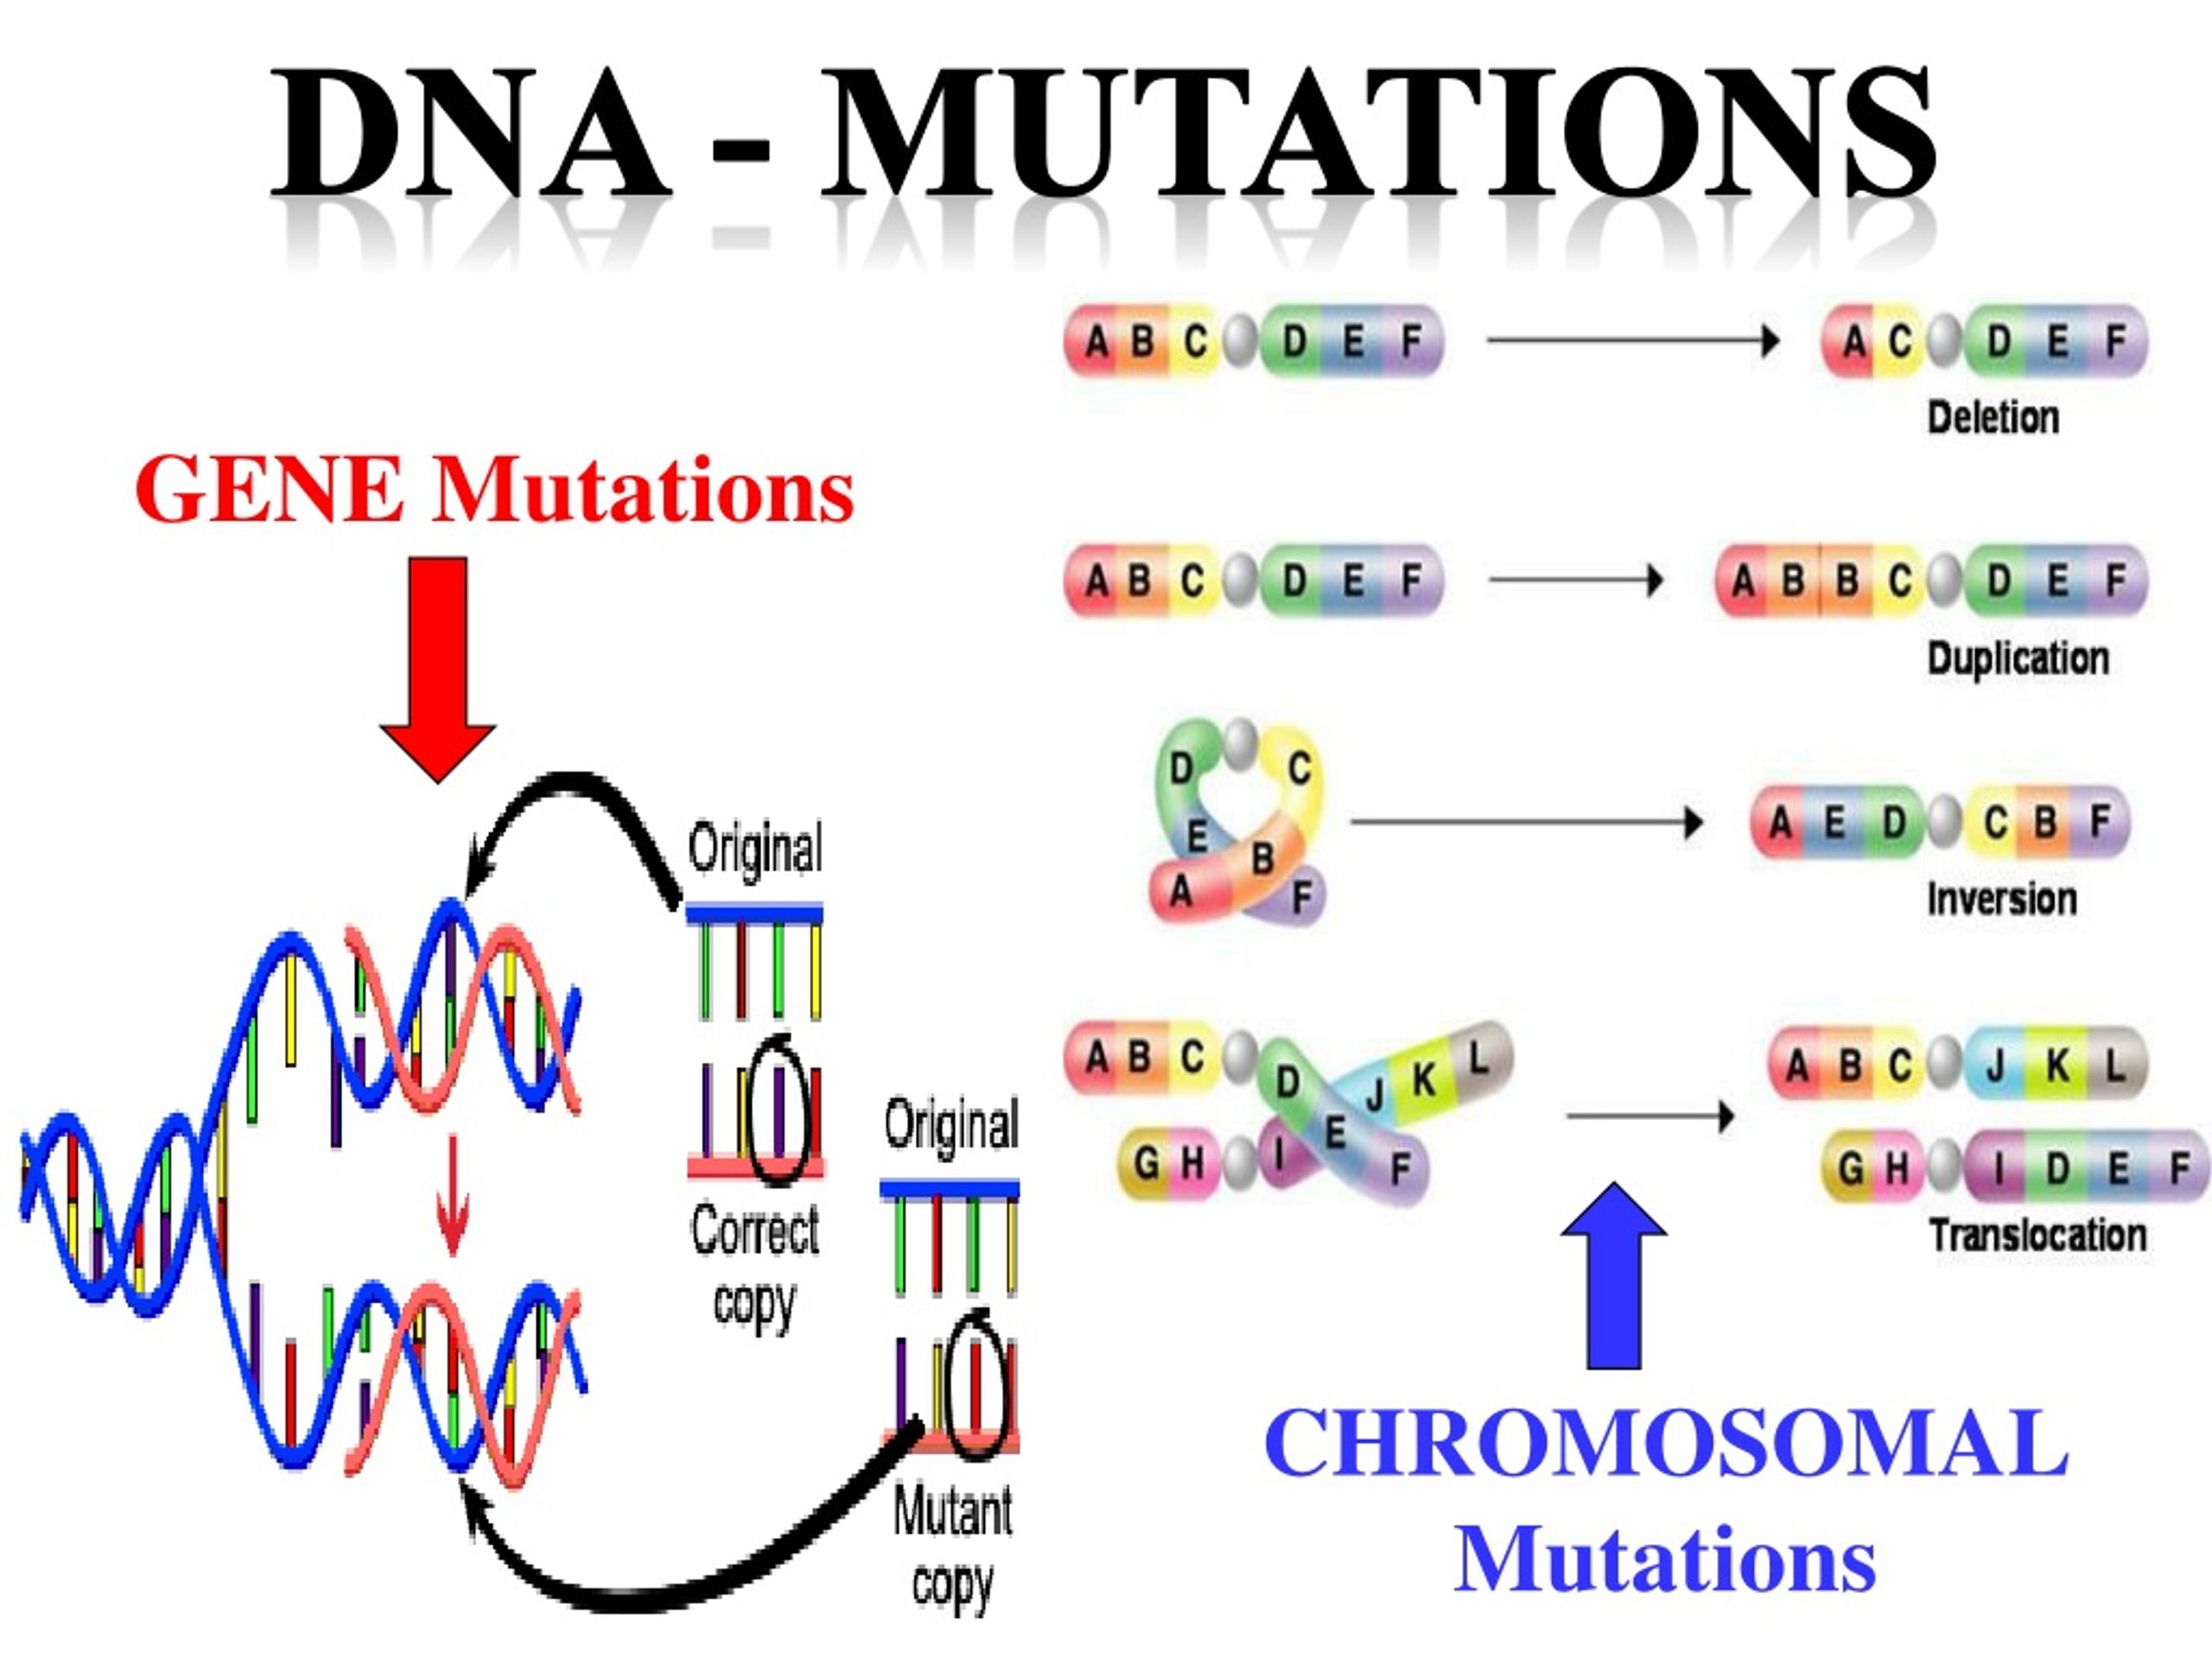
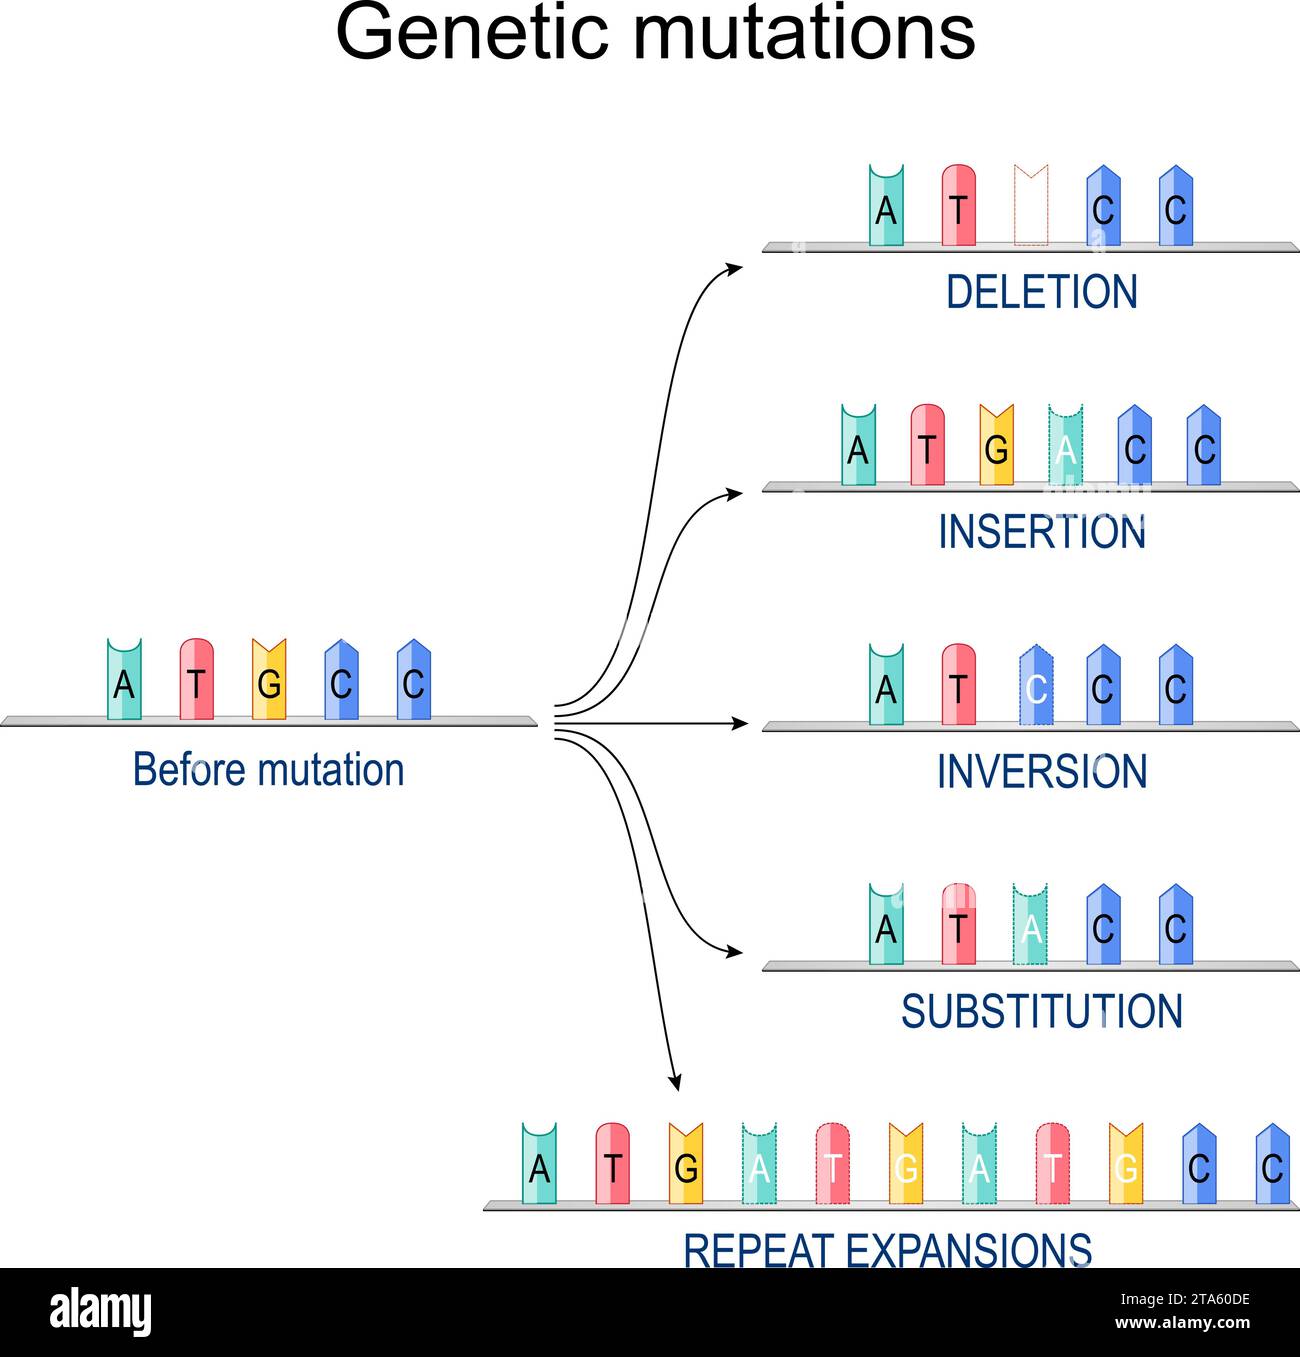
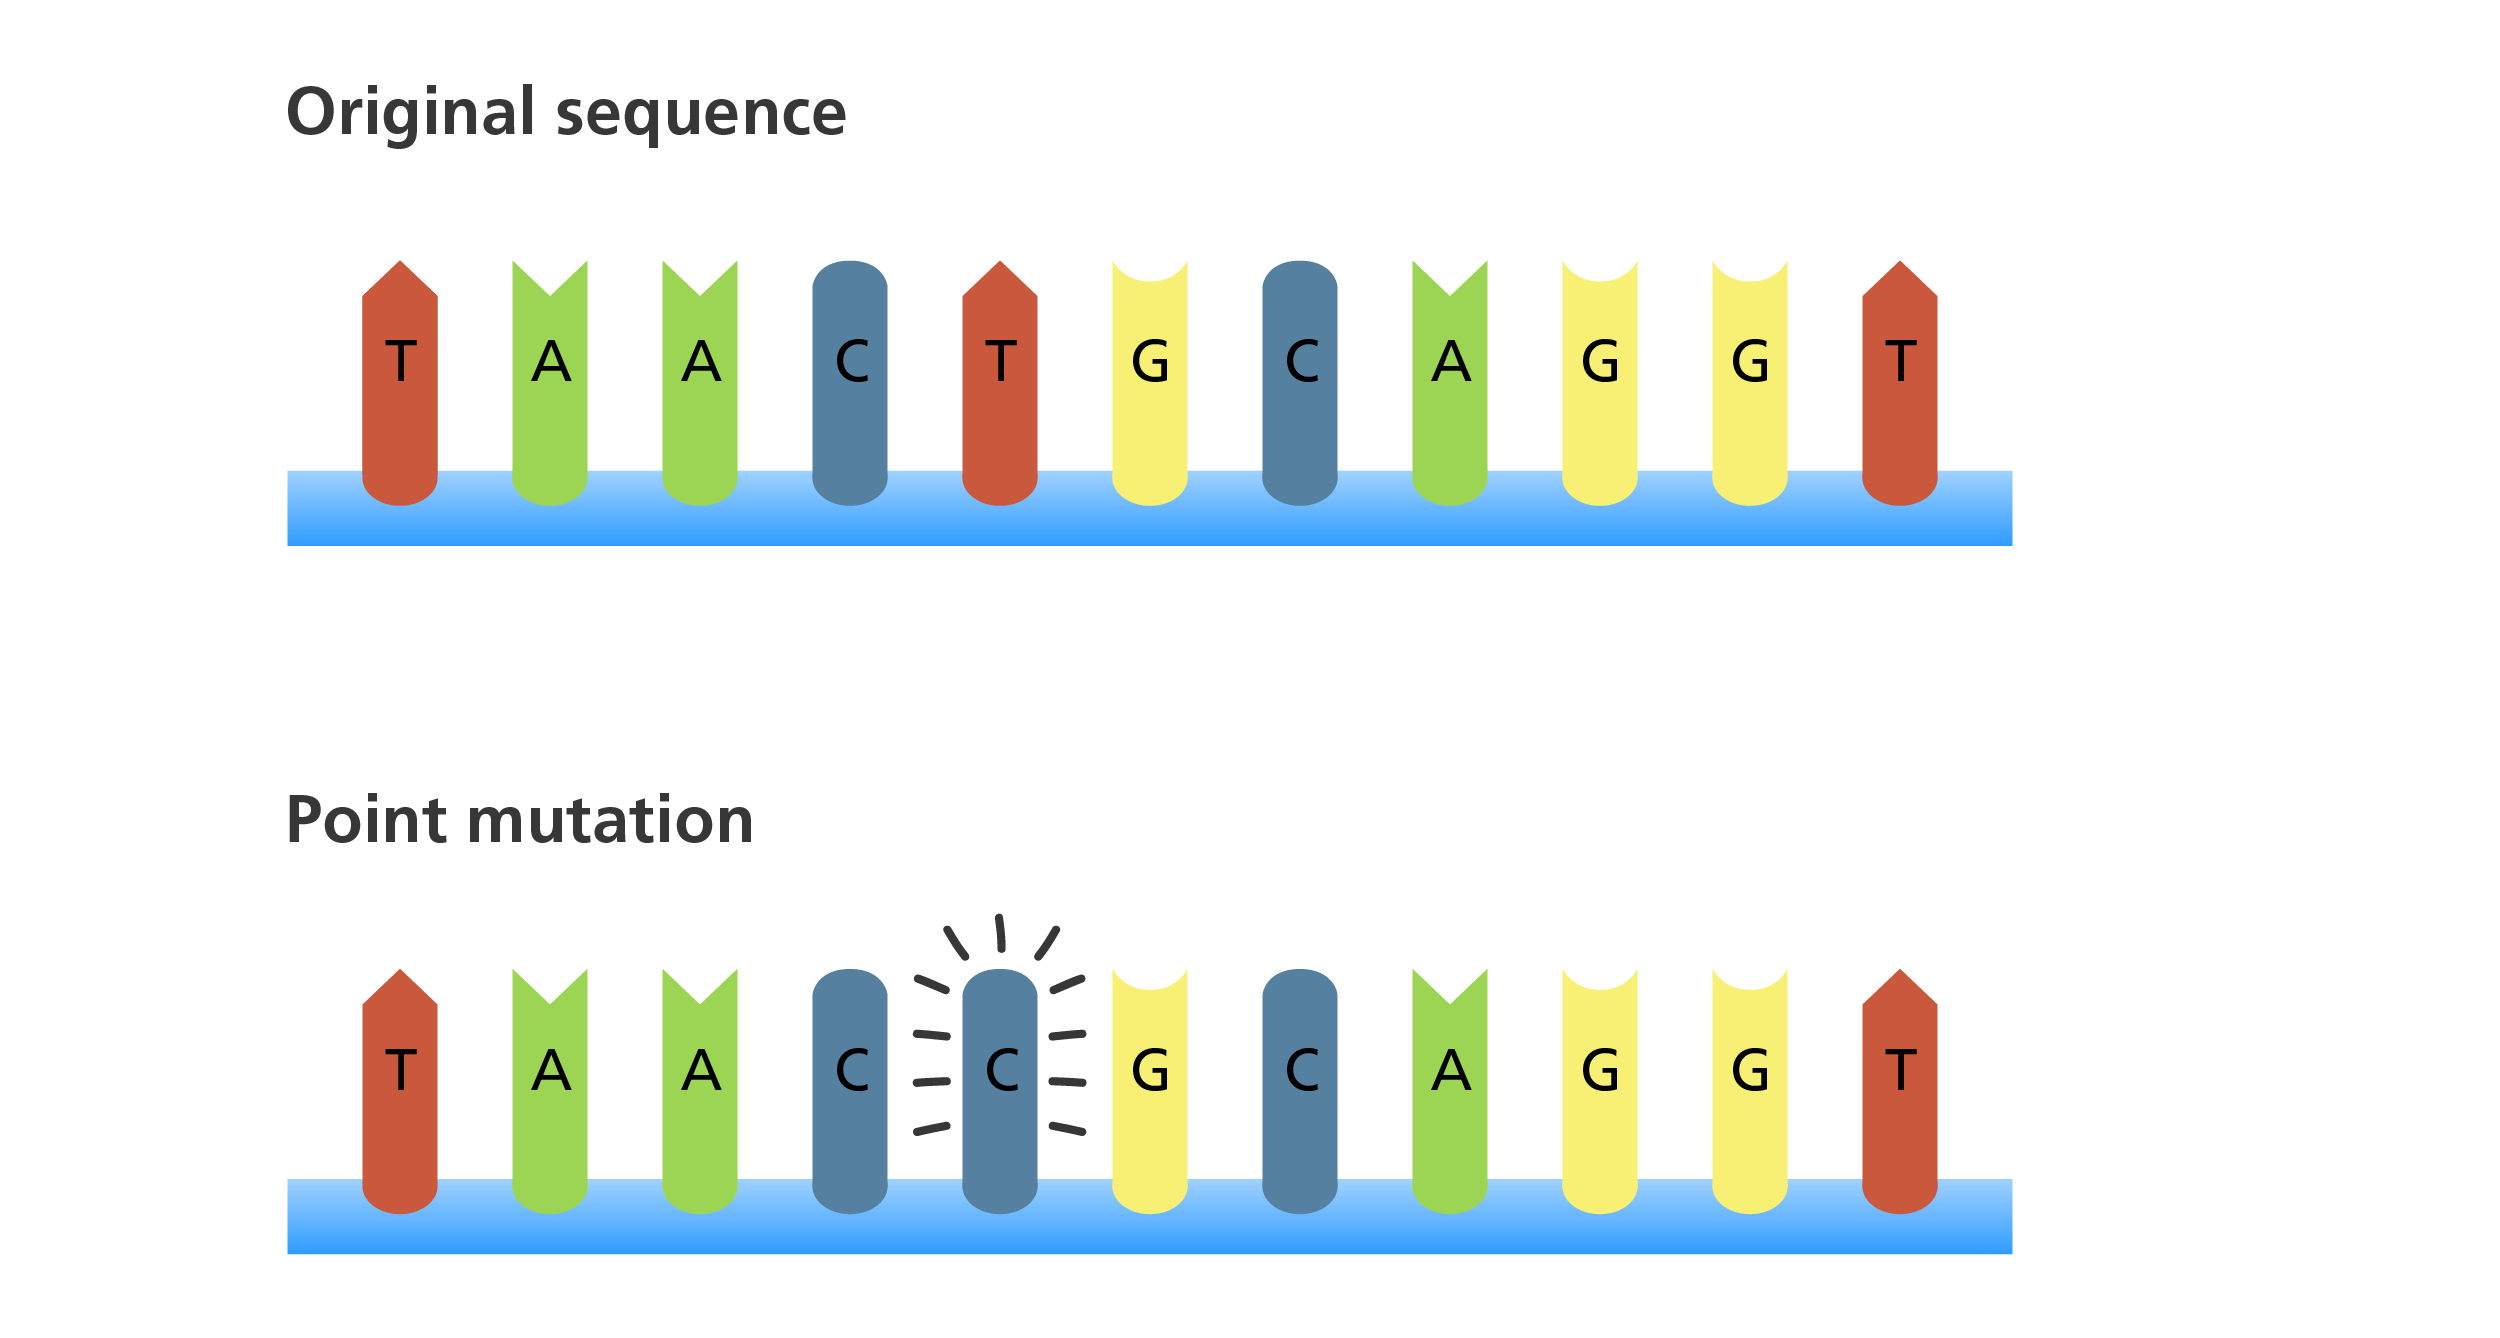
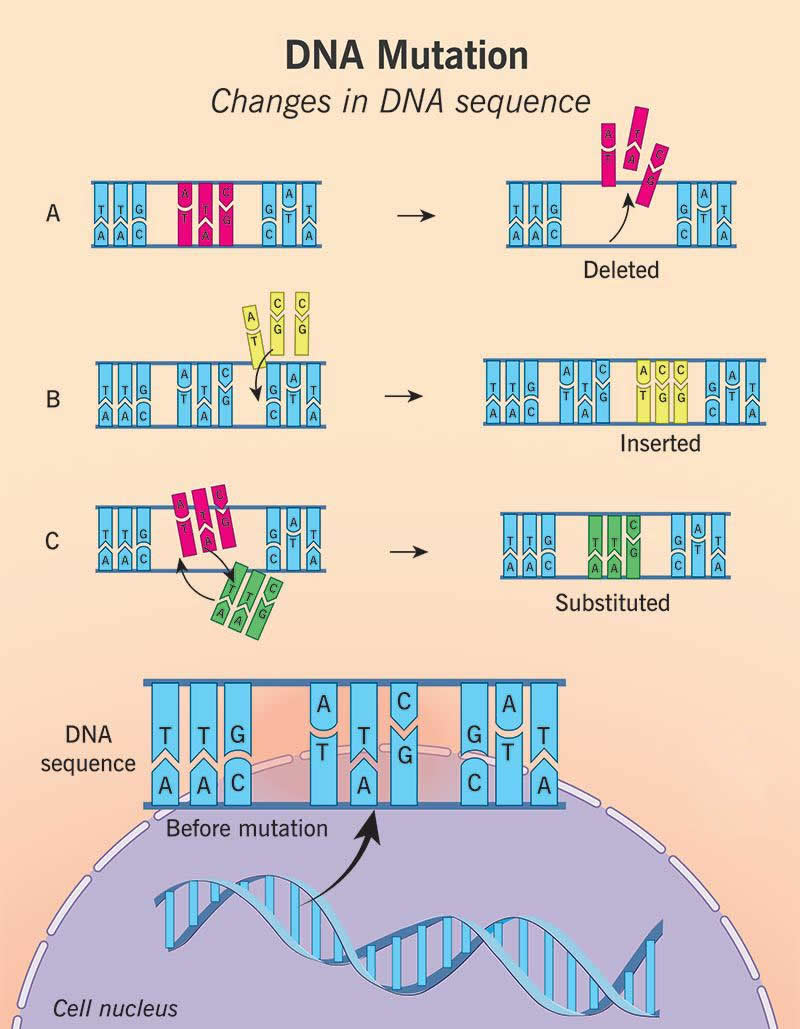
In practice, a mutation is any alteration to the genetic code that gets passed forward. That means point mutations, frameshifts, insertions, deletions, copy-number variations, and structural rearrangements like inversions or translocations. Each one operates differently and has different consequences depending on where it lands in the genome. A point mutation swaps a single base pair. If it lands in a coding region, it might be synonymous — the codon changes but the amino acid stays the same because of degeneracy in the genetic code. Or it might be missense, swapping one amino acid for another. A nonsense mutation turns a codon into a stop signal, and the protein gets truncated. Frameshifts happen when you insert or delete bases in numbers that aren't multiples of three, shifting the entire reading frame downstream. Those are usually devastating for the protein product. The bigger the affected region, the more likely the mutation has a noticeable effect. But size isn't everything. A point mutation in a splice site can wreck an entire gene just as effectively as a deletion covering half the coding sequence. Location matters more than people realize.
I once spent three weeks debugging a PCR-based genotyping assay that kept giving false negatives on a particular strain. The primers were perfect. The cycling conditions were fine. The sample was good. It turned out the strain had a single nucleotide insertion — a frameshift — right in the middle of one primer binding site. The polymerase was still amplifying, just not the right fragment. I redesigned the primers to sit outside the mutation zone and the problem vanished. Nobody in the original protocol design had even considered that a single base shift could break a 20-nucleotide primer entirely.
Get the Full Details
How Mutations Actually Show Up
Somatic mutations occur in non-reproductive cells and are only passed to daughter cells during division. Germline mutations happen in eggs or sperm and get inherited by the next generation. That distinction matters because it determines whether the mutation affects just one individual or an entire population over time. Mutagens accelerate mutation rates. UV light causes thymine dimers. Ionizing radiation creates double-strand breaks. Chemical mutagens like ethyl methanesulfonate alkylate bases and cause mispairing. But here's the thing that surprises people: spontaneous mutations happen constantly without any external trigger. Replication errors alone generate roughly one mutation per 10^9 base pairs per cell division in humans. With ~3 billion base pairs and trillions of cell divisions, every person carries thousands of de novo mutations their parents didn't have. DNA repair mechanisms catch most of these. Mismatch repair, base excision repair, nucleotide excision repair, and homologous recombination all work in overlapping layers. When they fail, the mutation becomes permanent in that lineage. The redundancy is there for a reason — cells can't afford to let errors accumulate unchecked, and yet they also can't achieve perfect fidelity without making replication impossibly slow.
Mutation in Evolutionary Computation
If you're coming at this from a programming or optimization angle, mutation works differently but follows the same basic principle. In genetic algorithms and evolutionary strategies, mutation is a stochastic operator that randomly alters an individual's representation — usually its parameter values or bit string — to maintain diversity and explore new regions of the search space. There's Gaussian mutation, uniform mutation, bit-flip mutation, and swap mutation depending on whether your encoding is real-valued, binary, or permutation-based. The mutation rate is critical. Too low and the algorithm converges prematurely. Too high and it becomes a random walk with no direction. A typical starting point is 0.01 to 0.1 per gene per generation, but optimal values depend heavily on your problem structure. I've seen people set mutation rates at 0.5 or higher and then wonder why their algorithm never converges. The population just bounces around randomly. Other times people set it near zero and get stuck in local optima. The trick is often adaptive mutation — letting the rate respond to the population's diversity level so it increases when stagnation is detected and decreases when progress is being made. Some frameworks do this automatically; others you have to code yourself.
Reading Mutation Data
When you get variant calls from a sequencing run, you're looking at raw positions where the sample differs from the reference genome. VCF files contain the genotype, quality scores, depth information, and filtering flags. The key fields to check are the QUAL score (phred-scaled probability the variant is real), the DP (read depth at that position), and the GQ (genotype quality). A variant with a QUAL of 200 and DP of 50 is solid. A variant with QUAL of 30 and DP of 3 is noise. Don't skip the depth check. I've seen people call heterozygous variants at 2x coverage and report them as real findings. That's not a finding. That's a guess with extra steps. Functional annotation tools like SnpEff or VEP tell you whether a variant falls in a coding region, what amino acid change it produces, and whether conservation scores suggest it's important. But these are predictions. A high CADD score or PolyPhen prediction doesn't prove pathogenicity. Clinical classification requires much more evidence — segregation data, functional assays, population frequency thresholds, and often multiple lines of validation.
Where Things Go Wrong
Mutation is not a solution. It's a mechanism. People treat it like a magic bullet in contexts where it's completely inappropriate. CRISPR gene editing introduces deliberate mutations, and off-target effects remain a real problem even with optimized guide RNAs. Gene drive systems that spread mutations through populations can have unintended ecological consequences that are nearly impossible to reverse once released. Mutation breeding — exposing organisms to radiation or chemicals to generate random mutations and selecting for useful traits — has produced many crop varieties, but it's fundamentally a numbers game. You create thousands of mutants and hope one has the trait you want. Most of the mutations are deleterious. The success rate is low and the process is slow. If you need precision, mutation is the wrong tool. Homology-directed repair with CRISPR, recombinant DNA technology, or selective breeding with known markers will give you far more control. Mutation should be your first step when you're exploring unknown territory and your last resort when everything else has failed. Not the other way around.
The biggest mistake I see is treating mutation data as definitive truth without validation. Sanger sequencing confirmation, independent replicate experiments, and functional follow-up are non-negotiable if you're publishing or making clinical decisions based on mutation calls. Computational predictions are hypotheses, not conclusions. The difference matters more than most people admit.