The Building Block Nobody Actually Explains Well
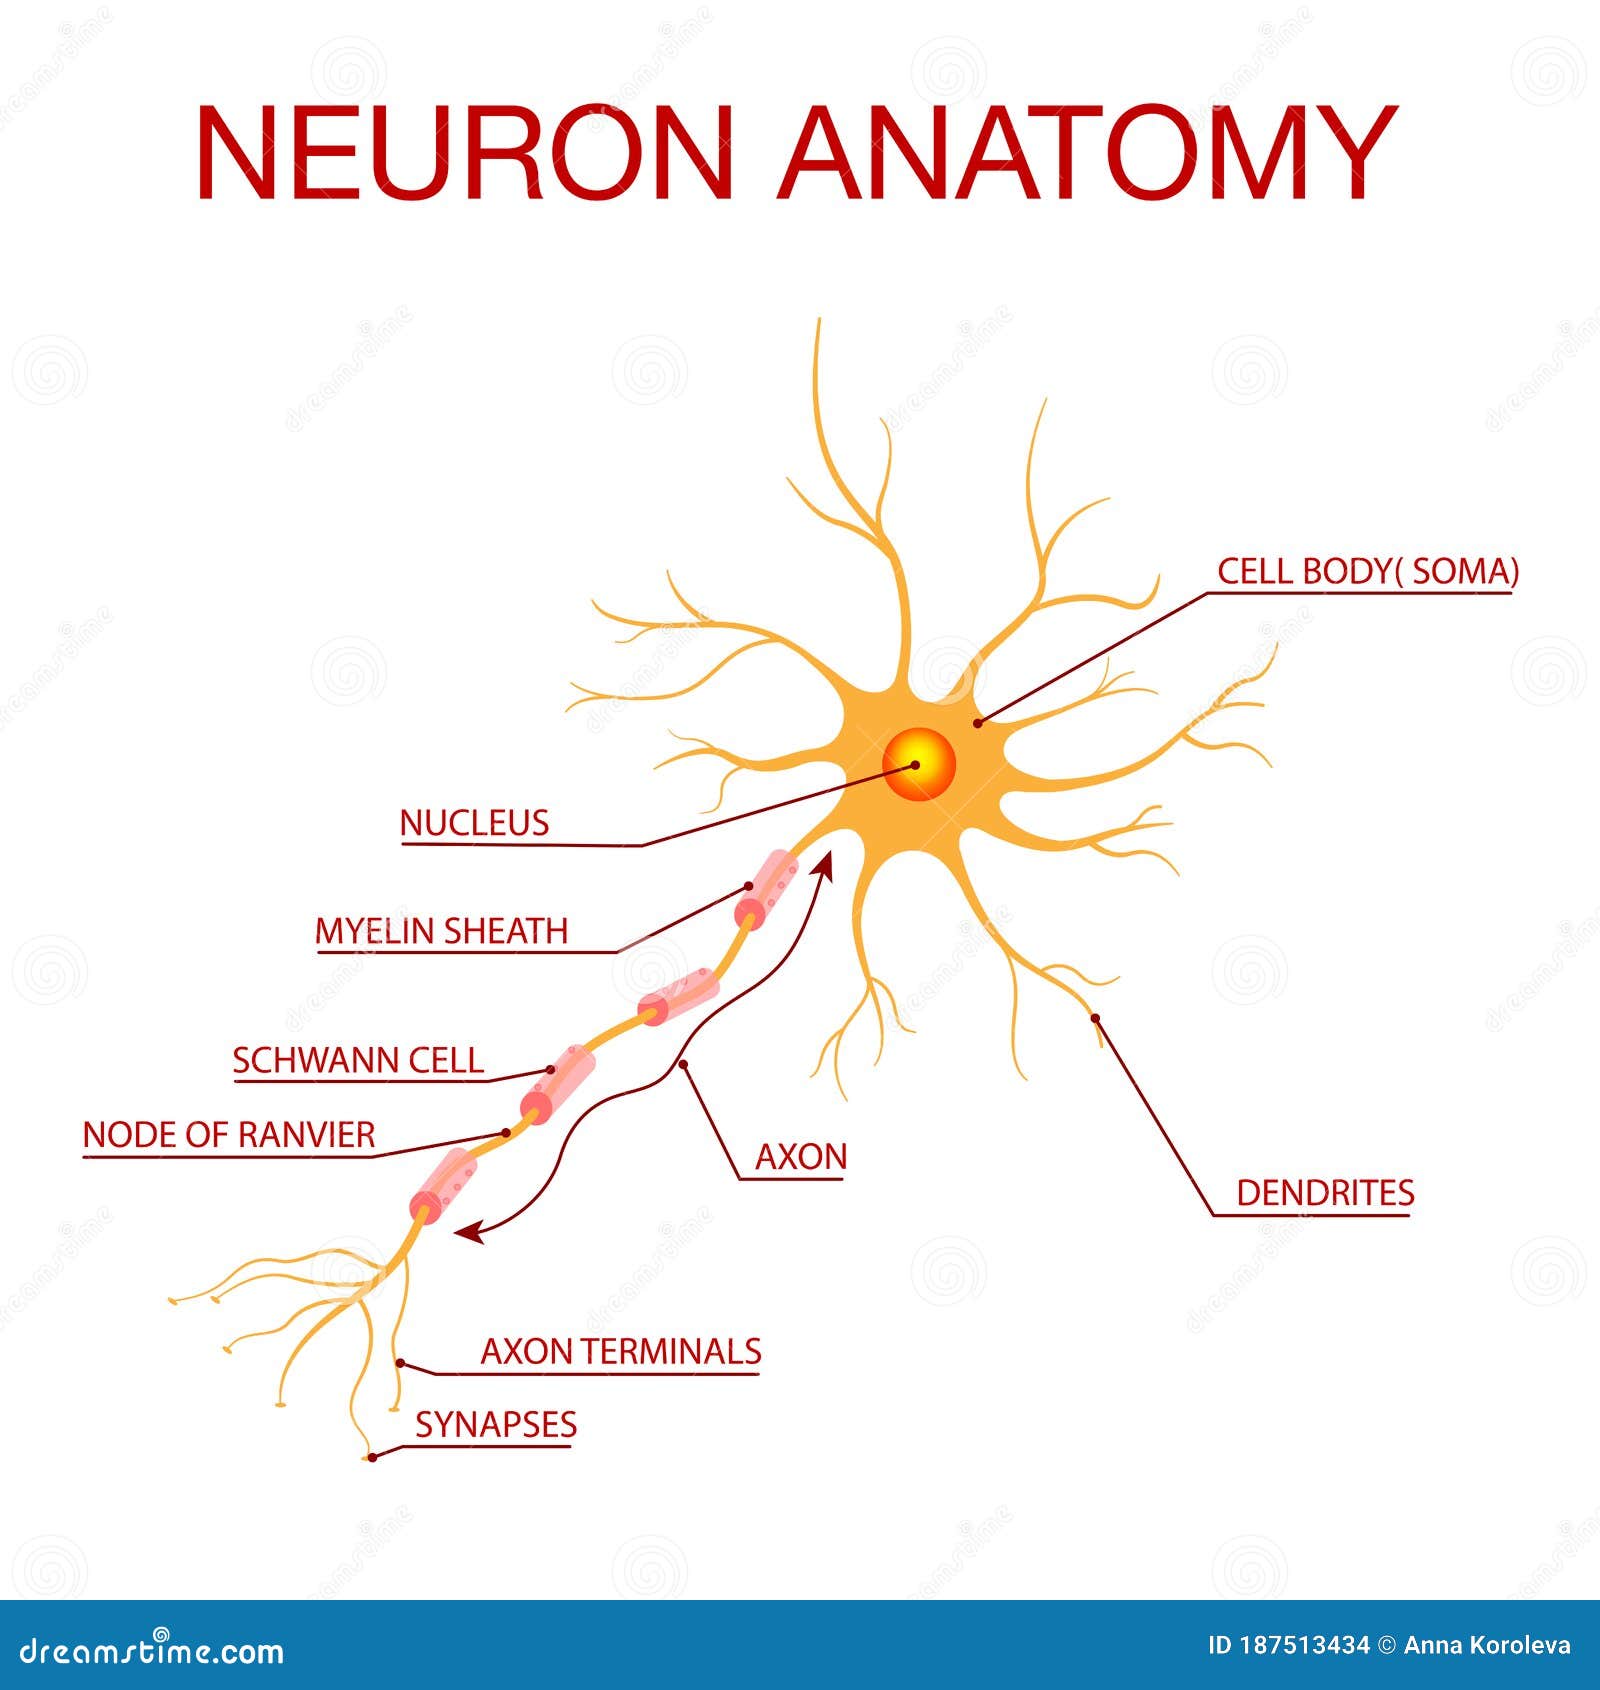
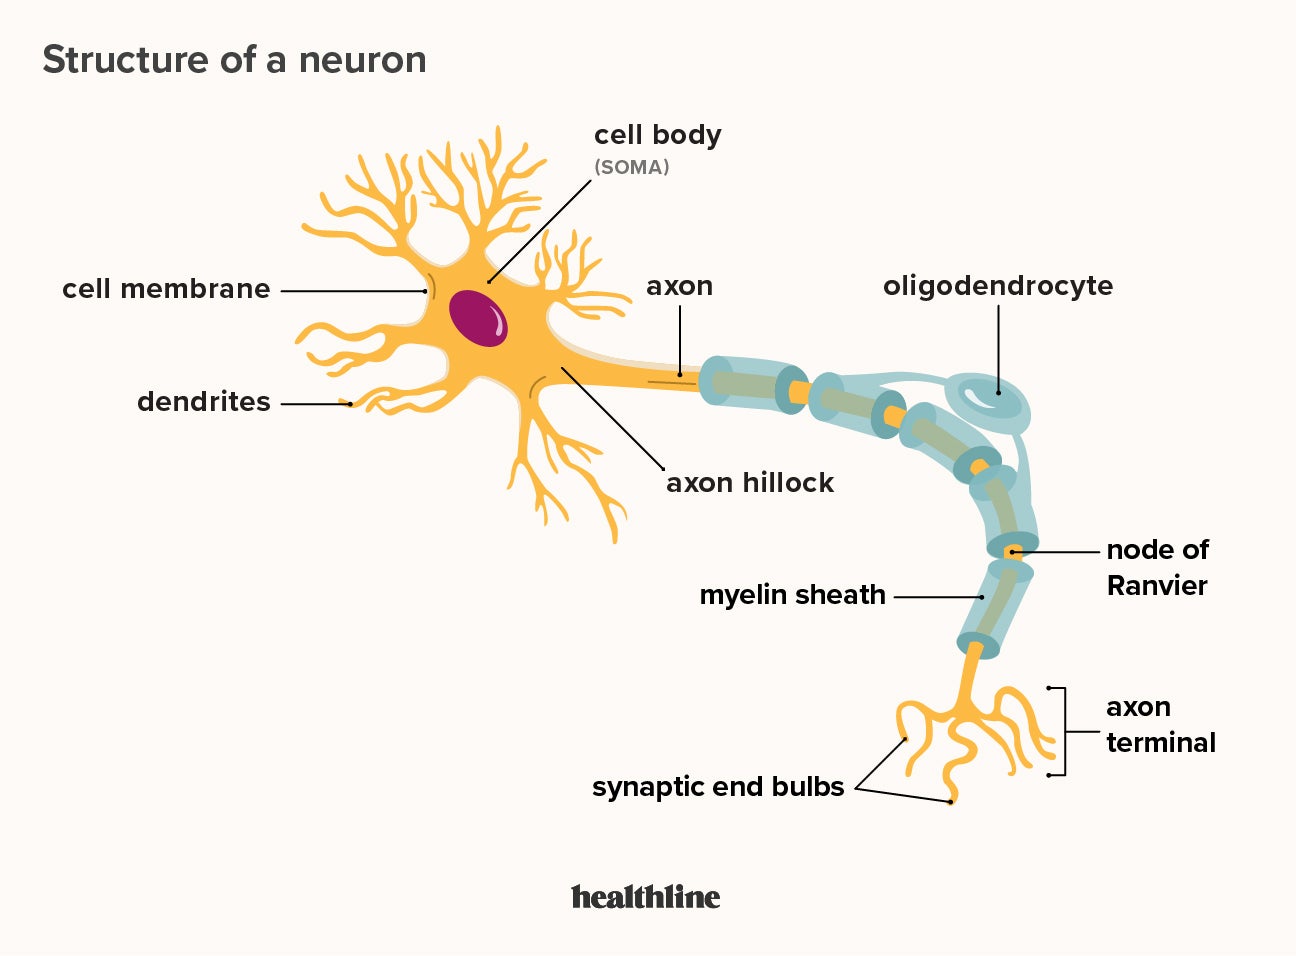
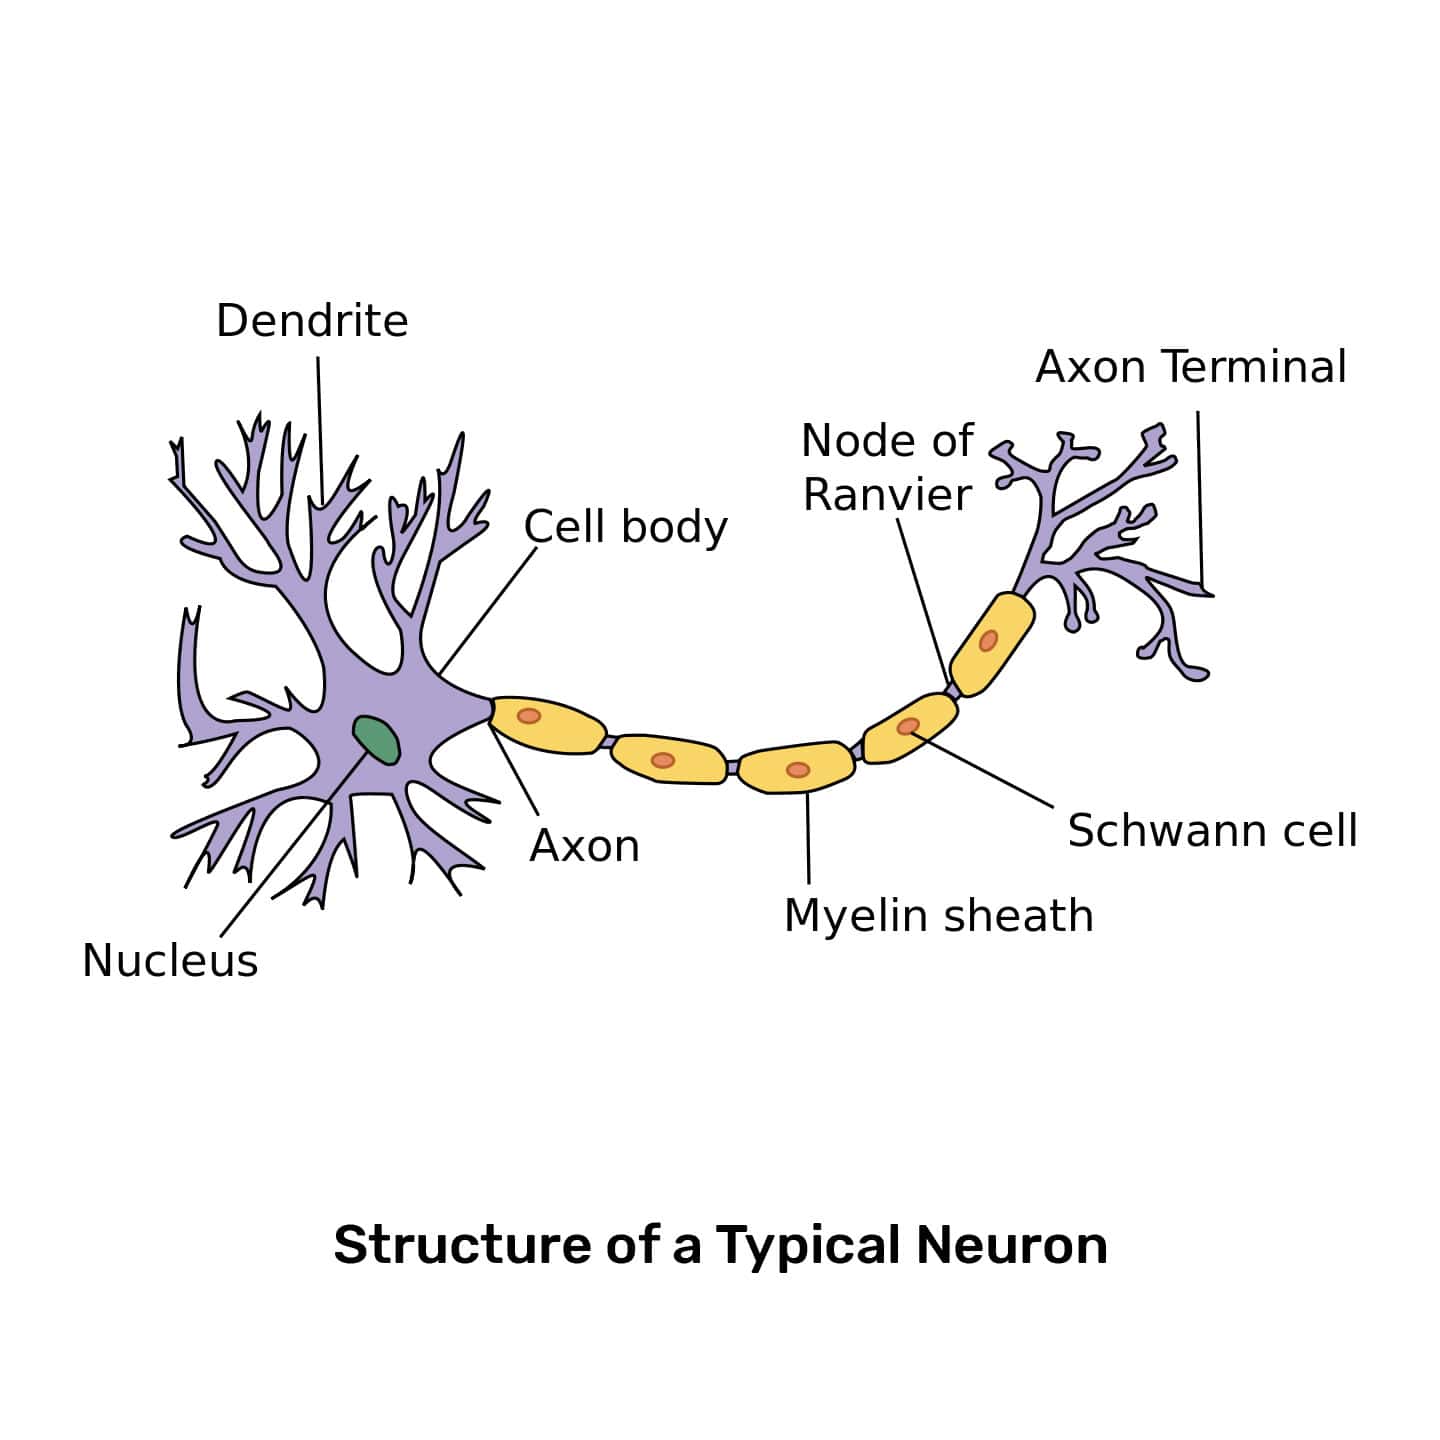
A neuron is just a mathematical function that takes some numbers in, does a few operations, and spits a number out. That is the entire thing. The hype around neural networks makes it sound like magic, but at the lowest level, it is linear algebra with a non-linear twist glued on. You have inputs, you weight them, sum them up, add a bias, and pass the result through an activation function. That is it. Everything else is just stacking more of these together. When I first started building models from scratch instead of using pre-built libraries, I spent a solid week debugging why my network wasn't learning. Turns out I had accidentally initialized all my weights to zero. The neuron outputs were identical across the entire batch, gradients were symmetric, and the model just learned nothing. It is a beginner mistake but one that wastes hours if you are not paying attention. The fix was simple — use a random initialization scheme like He or Xavier depending on your activation function. That alone cut my debug time from days down to minutes. The formal definition you will find in textbooks describes a neuron as computing f(w · x + b) where w is a weight vector, x is the input vector, b is a scalar bias, and f is the activation. But the practical reality is messier. In production systems, you rarely see a single neuron in isolation. They are batched into matrix operations for GPU efficiency. The conceptual model stays the same but the implementation looks completely different because no one computes individual neuron outputs one at a time anymore.
Here is something most guides skip over: the choice of activation function matters far more than people admit. ReLU dominates because it is computationally cheap and mitigates vanishing gradients, but it has a real weakness. If a neuron's weighted input stays negative, ReLU outputs zero and the gradient is also zero. That neuron is effectively dead. It will never activate again because no gradient flows back to update its weights. I ran into this with a deep network for image classification where roughly twelve percent of my neurons went dead after training. The workaround was switching to Leaky ReLU or using proper weight initialization, which reduced the dead neuron count to under two percent. Another thing nobody emphasizes is that a single neuron can only solve linearly separable problems. The XOR problem is the classic example. A single perceptron cannot learn it no matter how you adjust the weights. This limitation is exactly why we stack layers and use multiple neurons across layers to create non-linear decision boundaries. Without that depth, you are just doing fancy linear regression. When implementing your own neuron from scratch, the backward pass is where things get tricky. The chain rule applies straightforwardly in theory but floating point precision issues creep in quickly, especially with deeper networks. I found that normalizing my inputs to zero mean and unit variance before feeding them into the network made training substantially more stable. It is a small preprocessing step but it can reduce training time from several hours to under an hour on the same hardware.
The limitations are worth being honest about. Neurons are brittle. They overfit easily on small datasets, they require large amounts of labeled data to generalize well, and they offer almost no interpretability. When a model makes a wrong prediction, you cannot trace it back to a single neuron's decision the way you would with a rule-based system. This is not a minor inconvenience in fields like healthcare or finance where you need to explain why a decision was made. If interpretability matters for your use case, consider that a single neuron or even a shallow network may not be the right tool regardless of accuracy metrics. For most practical purposes today, you do not need to implement neurons by hand. Libraries like PyTorch and TensorFlow handle all the forward and backward passes efficiently. But understanding what is happening at the neuron level will save you from wasting days chasing bugs that stem from fundamental misunderstandings about how the model actually learns.
Get the Full Details