The Math Behind Order
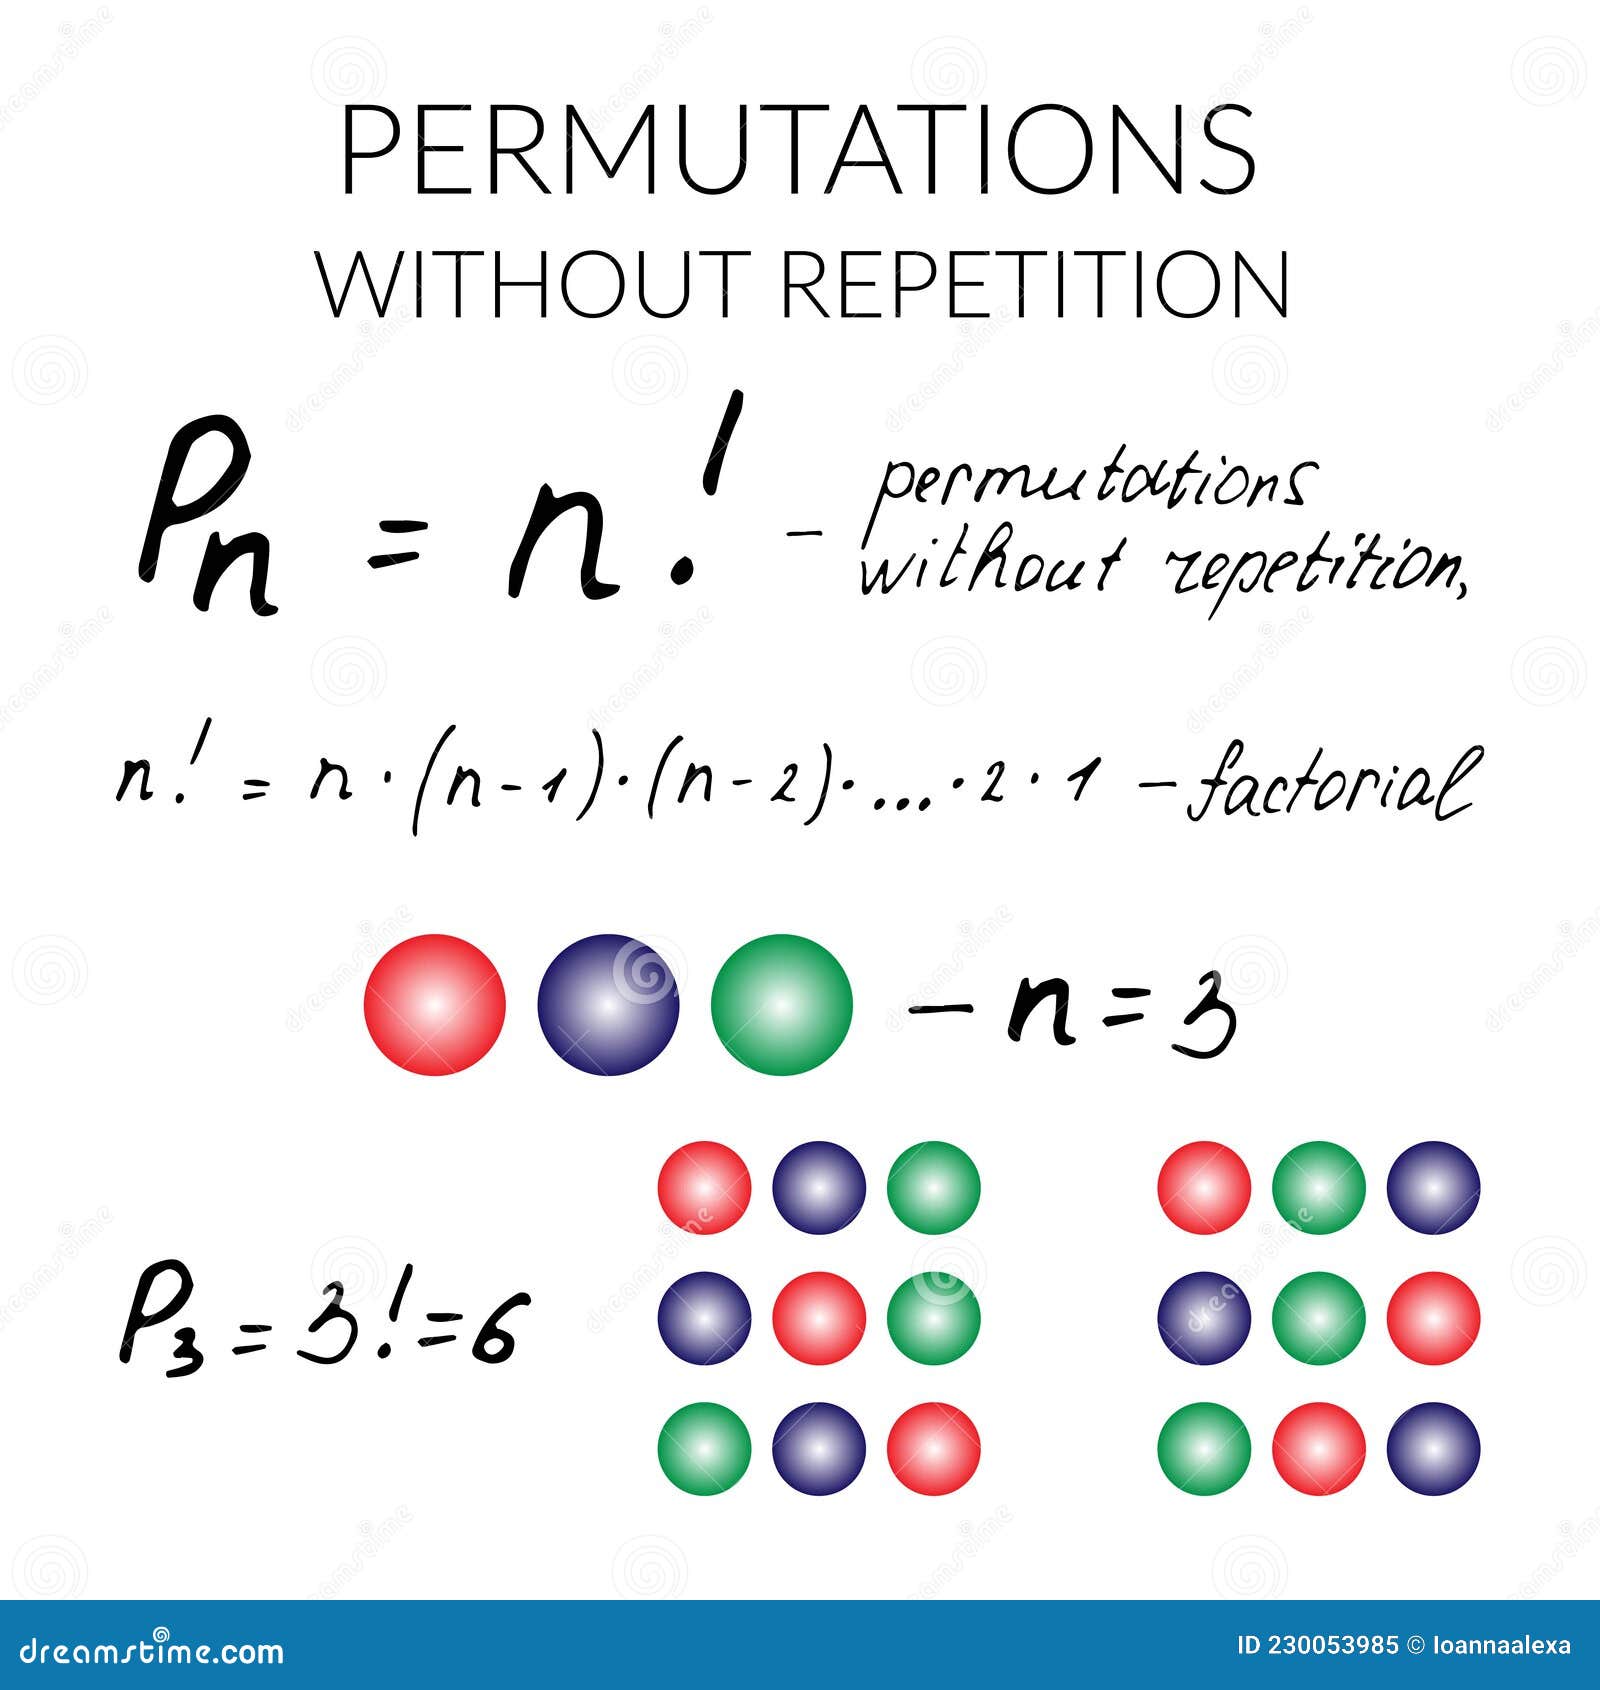
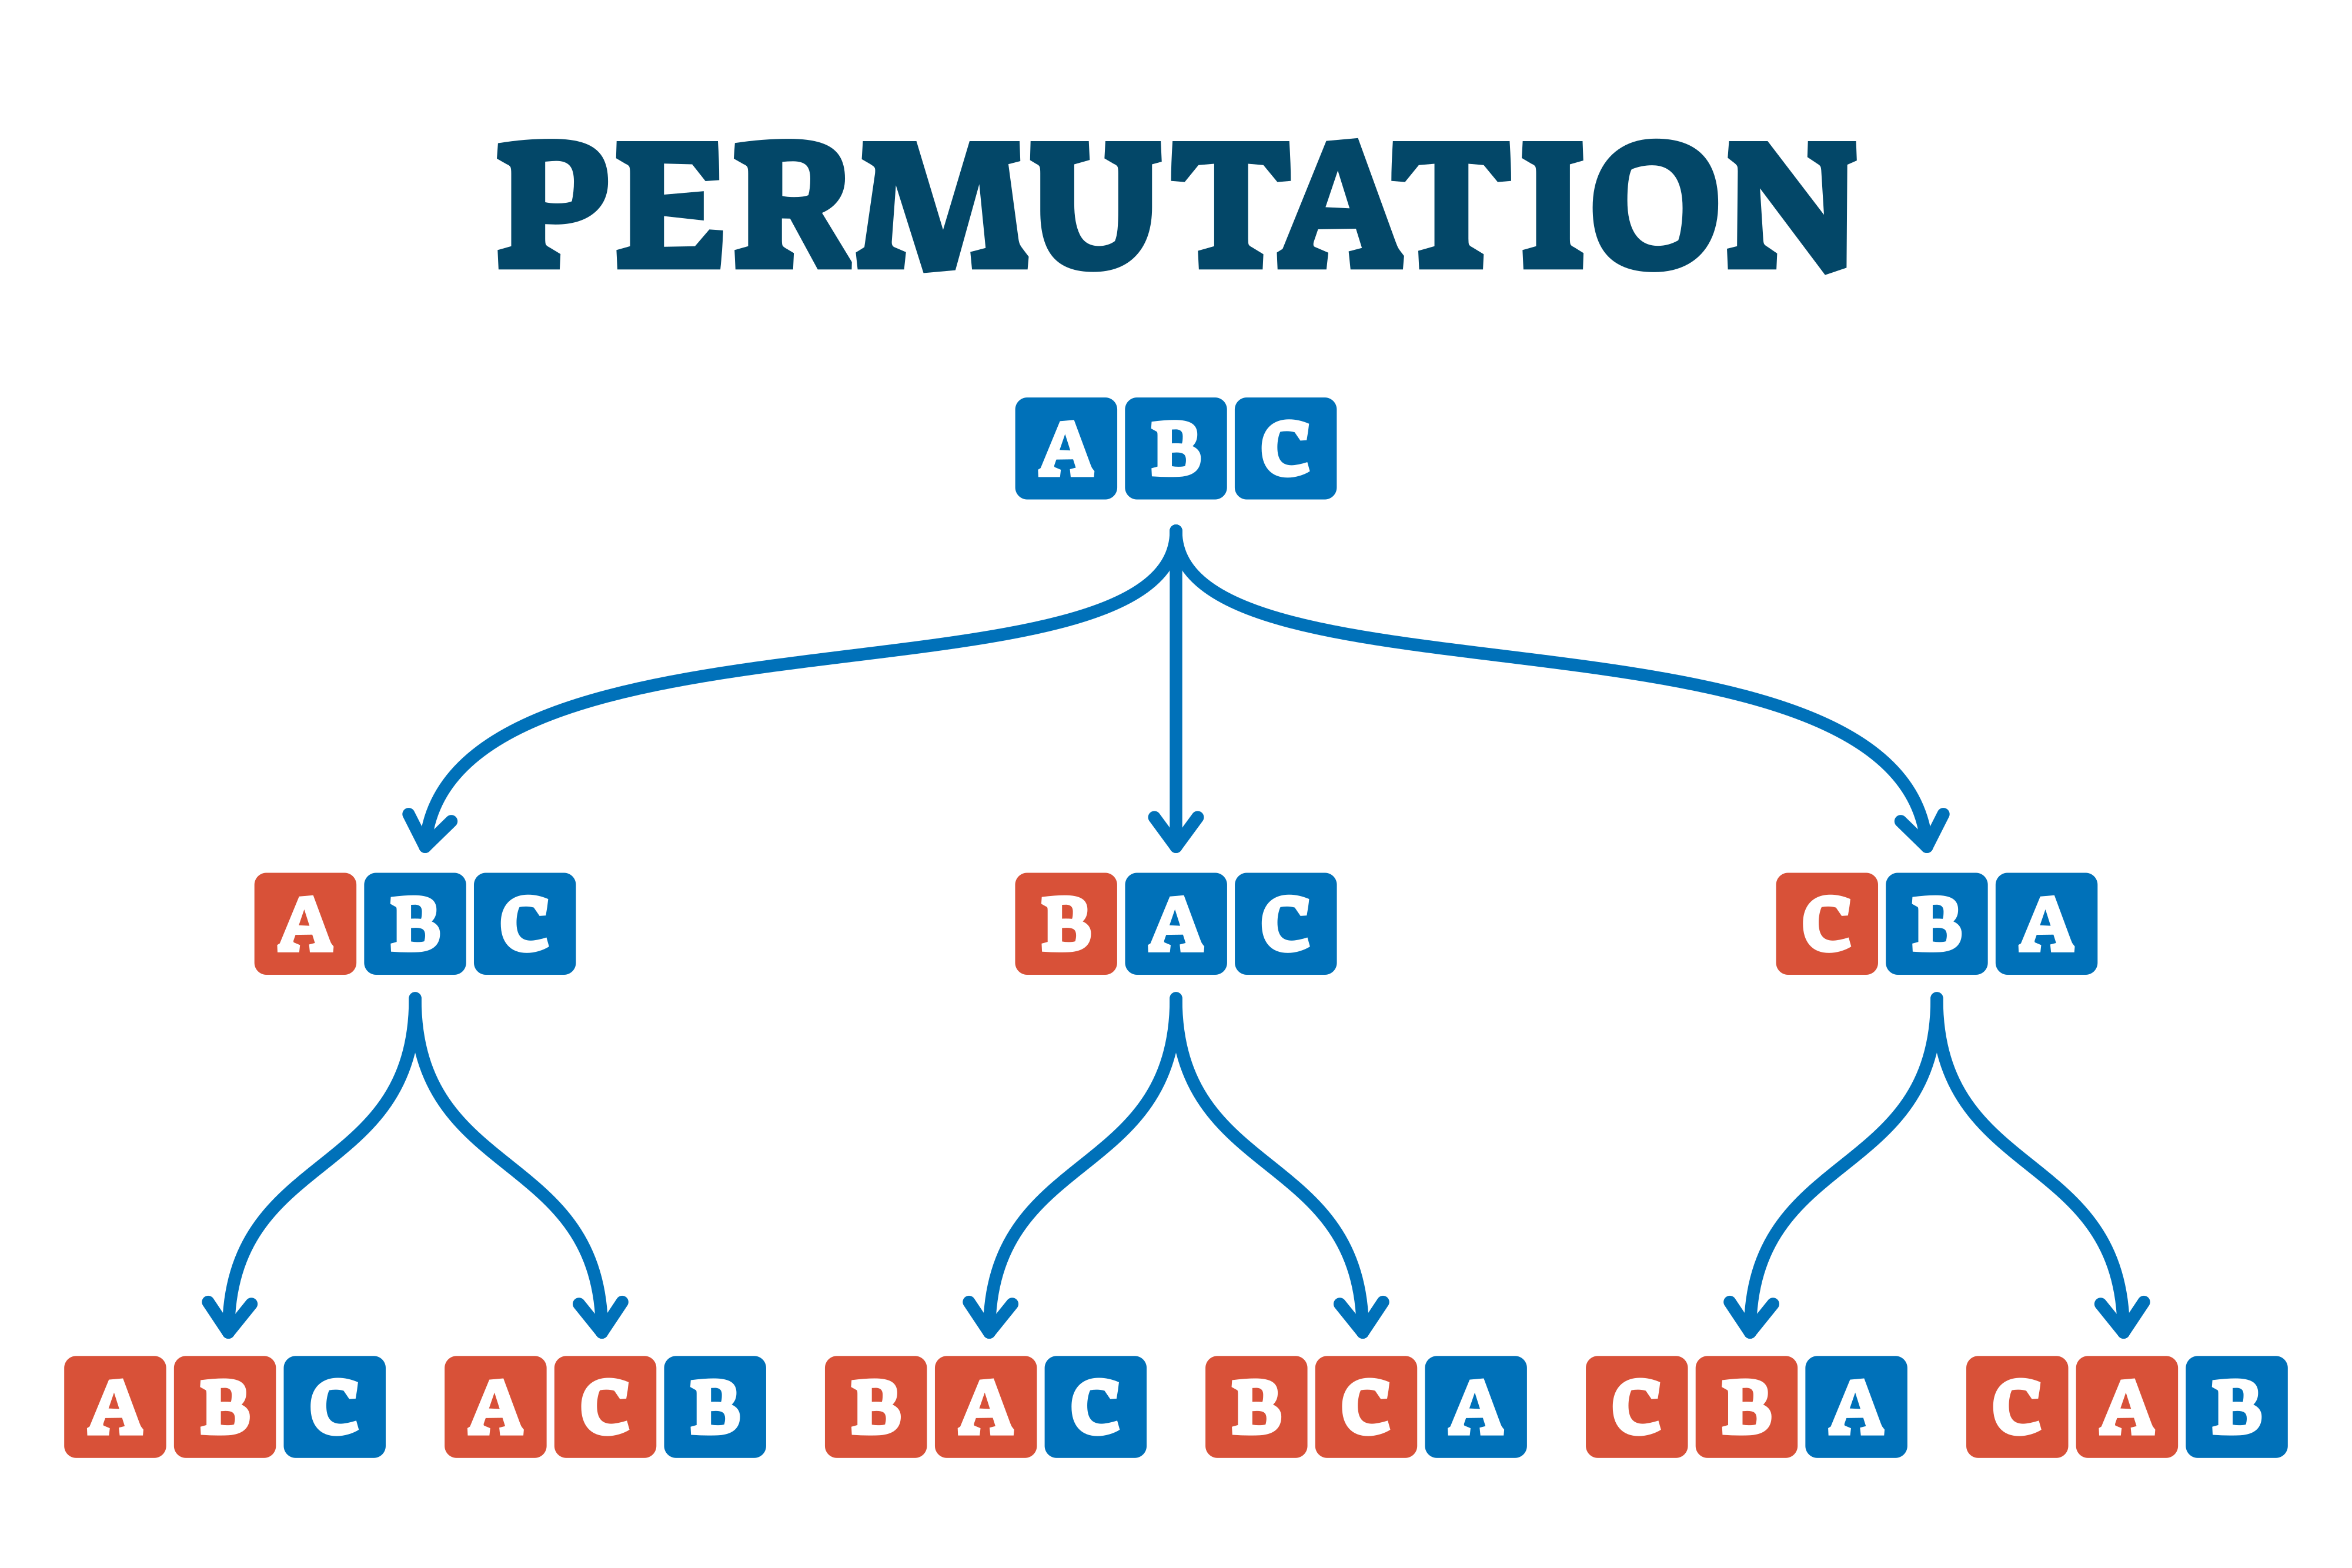
Most people encounter permutations without realizing what they are studying. You grab a deck of cards, shuffle them, and the resulting order is a permutation. That single act contains the entire concept. A permutation is an arrangement of objects in a specific sequence where the order matters. The same three letters rearranged from ABC to ACB represent two distinct permutations because position changes the meaning. I spent years working in operations research optimizing delivery routes. The permutation problem hit me when our routing software started flagging impossible schedules. We had 47 warehouses and needed to find the optimal visiting order for each truck. The brute force approach meant calculating every possible arrangement. With just 47 items, that is 47 factorial, which equals approximately 3.5 times 10 to the 58th power. No computer on Earth could evaluate that many sequences in the lifetime of the universe. I learned quickly that understanding permutation mathematics is not academic luxury. It is the difference between shipping costs that make sense and shipping costs that bankrupt your margins.
What Is A Permutation In Math
At its core, a permutation counts how many ways you can arrange a subset of objects drawn from a larger set. When all elements participate, it is called a permutation of a set. When only some elements participate, it is a partial permutation. The standard notation uses P(n,r) or nPr, where n represents the total number of items and r represents how many positions you fill. The calculation multiplies n by n minus 1, then by n minus 2, continuing for r factors total. For example, arranging 5 books on a shelf in groups of 3 means P(5,3) equals 5 times 4 times 3, which gives 60 distinct orderings. The formula looks deceptively simple until you confront repeated elements. This is where most students hit their first wall. If you have the word Mississippi sitting on your desk and need to count unique permutations of all 11 letters, you cannot simply calculate 11 factorial. That overcounts dramatically because identical letters produce indistinguishable arrangements. The correction divides by the factorial of each repeated element count. Mississippi has four S's, four I's, two P's, and one M. So the true count becomes 11 factorial divided by 4 factorial times 4 factorial times 2 factorial, which equals 34,650 distinct arrangements instead of 39,916,800. The difference is staggering and directly impacts probability calculations. Here is a practical edge case I ran into during a quality control project. We were calibrating sensors and needed to test every possible ordering of 8 calibration weights on a test rig. The weights had nearly identical mass, and our specification required each ordering to produce a reading within tolerance. The theoretical permutations are 8 factorial, or 40,320. But the physical constraint is that flipping the entire sequence produces the same gravitational effect on the rig. Arrangement 1 through 8 behaves identically to arrangement 8 through 1. I divided by 2 and got 20,160 unique physical configurations. Missing this symmetry would have inflated our testing plan by 100 percent and doubled our lab time from about three weeks to six. This is a genuine bottleneck in experimental design. Permutation counts assume abstract mathematical objects. Real-world constraints often collapse equivalence classes that the formula treats as distinct.
How Permutations Differ From Combinations
The distinction between permutations and combinations determines whether you get the right answer or a wildly wrong one. A combination selects items without caring about order. A permutation selects and orders. Pick three fruits from an apple, orange, and banana. The combination is one group regardless of sequence. The permutation is six groups because apple-orange-banana differs from banana-orange-apple. In practice, this matters enormously in lottery design, cryptographic key generation, and any scenario where sequence encodes information. When r equals n, meaning you arrange all items, the permutation formula simplifies to n factorial. This is the baseline case. The moment you remove even one item from consideration, the count drops multiplicatively. Reducing from arranging all 10 items to arranging only 7 of those 10 reduces your permutation count from 3,628,800 down to 604,800. The ratio is exactly 10 times 9 times 8, which equals 720. This multiplicative relationship is why permutations scale so aggressively with n. Adding one more item does not add a fixed amount. It multiplies every existing arrangement by the new item count plus one, creating exponential growth in the solution space. I encountered a failure mode in a data serialization task where we needed to encode a 12-character alphanumeric key using permutations of a restricted character set. The character pool contained 36 possible symbols. Using all 12 positions without repetition gives P(36,12), which equals about 1.6 times 10 to the 17th possible keys. Sounds large until you consider that a modern GPU cluster can brute force approximately 10 to the 10th hashes per second. The search space collapses to hours under sustained computation. We switched to allowing repetitions and adding a check digit, which pushed the effective entropy to about 2 to the 60th before the permutation explosion became a liability again. Permutations are powerful tools until the adversary knows you used one and the set is small enough to enumerate.
Get the Full Details

Where Permutation Calculations Break Down
The factorial function itself introduces numerical overflow well before the mathematics fails. In standard double-precision floating point, 170 factorial is the largest representable value. Anything beyond that returns infinity. This means problems involving 171 or more objects cannot be evaluated directly with ordinary arithmetic. You must switch to logarithmic space, computing ln of n factorial using the gamma function or Stirling approximation. Stirling's formula states that n factorial approximates square root of 2 pi n times n over e to the n. At n equals 100, this gives roughly 9.3 times 10 to the 157th, which matches the actual value to within 0.1 percent. Useful for estimation, dangerous for precision engineering where exact integer counts matter. Another frequent failure point is the assumption of distinguishable items. In combinatorial chemistry, molecule isomers are physically distinguishable but computationally treated as identical permutations until stereochemistry is encoded explicitly. I worked on a project generating candidate organic structures where the naive permutation count of carbon scaffold attachments overestimated valid molecules by a factor of 16. Symmetry operations in the molecular graph collapsed equivalence classes that the raw permutation formula counted separately. The workaround required implementing a canonical labeling algorithm based on the McKay graph isomorphism package, which reduced enumeration time from days to minutes while producing the correct yield of novel compounds. This is not a theoretical concern. It is a daily reality in computational chemistry and materials science. The circular permutation variant deserves mention because it appears frequently in seating arrangement problems and creates confusion. Arranging n distinct objects around a round table yields n minus 1 factorial arrangements instead of n factorial because rotationally equivalent orderings are considered identical. Fix one person's position to eliminate rotational symmetry, then arrange the remaining n minus 1 people linearly. For a dinner party of 8, that is 7 factorial equals 5,040 seatings rather than 40,320. If the table is unoriented and flipping the arrangement counts as the same configuration, divide by 2 again, giving 2,520. Each additional symmetry constraint halves or otherwise reduces the space, and missing one of these constraints is the most common error in exam settings and real-world scheduling alike.
Computing Permutations Without a Formula
Recursive algorithms generate permutations directly without invoking factorials. The standard approach fixes one element and recursively permutes the remainder. Python's itertools.permutations function implements this iteratively and runs in O of n times n factorial time for generating all arrangements. For moderate n values up to about 12, this is practical. Beyond 12, the output size itself becomes the bottleneck. Generating 13 factorial permutations produces 622 million sequences, which requires roughly 50 gigabytes of storage if each permutation occupies 80 bytes. The hardware limitation, not the mathematical limitation, becomes binding. For counting without enumeration, dynamic programming with memoization or direct formula evaluation is faster. The permutation can also be expressed using the falling factorial notation, written as n to the r subscript, which equals n times n minus 1 times n minus 2 and so on for r descending terms. This notation generalizes cleanly to non-integer arguments through the gamma function relation where n to the r subscript equals gamma of n plus 1 divided by gamma of n minus r plus 1. This extension allows fractional and negative arguments in specialized contexts like interpolation theory and certain probabilistic models, though the combinatorial interpretation becomes abstract rather than physical. I developed a custom permutation sampler for a Monte Carlo scheduling simulation where full enumeration was impossible and random sampling was required. The algorithm used the Fisher-Yates shuffle to generate uniform random permutations in O of n time per sample. Over 10 million iterations with n equals 25, the wall clock time was approximately 14 seconds on a single core. This sampling approach bypassed the factorial explosion entirely and provided statistically robust estimates of schedule distributions. The trade-off is that you lose exact counts and gain approximate probabilities. For decision-making where thresholds matter, approximation is insufficient. For risk profiling across millions of scenarios, it is the only viable path.
Practical Applications Outside Pure Mathematics
Permutation theory underpins password policy analysis. A 6-character password drawn from lowercase letters without repetition uses P(26,6) equals 308,880,000 possibilities. With repetition allowed, the space expands to 26 to the 6th equals 308,915,776, which is nearly identical for short lengths but diverges significantly as length increases. Security auditors routinely miscalculate by assuming repetition is impossible when policies do not explicitly forbid duplicate characters. This underestimation inflates perceived security by orders of magnitude. Entropy calculations in cryptographic key generation follow the same permutation or combination logic depending on whether the protocol enforces uniqueness constraints on byte values. Genetic algorithm crossover operators frequently use permutation representations for traveling salesman problems and job shop scheduling. The challenge is designing mutation and crossover operators that preserve validity while exploring the solution space efficiently. Standard single-point crossover on permutations produces invalid offspring with duplicated or missing genes. The solution requires order crossover or cycle crossover variants that maintain permutation structure. I observed a supply chain optimization project where the team used naive crossover and spent six weeks debugging invalid chromosome generations before switching to a proper permutation-aware operator. The fix reduced the debugging phase from weeks to a single afternoon. Machine learning hyperparameter optimization rarely cites permutations explicitly, but grid search over ordered configuration tuples is technically a Cartesian product rather than a permutation. The distinction matters when the optimizer enforces that two hyperparameters cannot share the same value category, as in assigning distinct learning rates to sequentially stacked network layers where reuse is structurally prohibited. In such constrained searches, the effective search space shrinks from n to the k to P(n,k), and grid or random search strategies must account for this reduction or waste iterations on invalid configurations. Ignoring the permutation constraint inflates runtime proportionally to the ratio between n to the k and P(n,k), which grows without bound as n approaches k.

Teaching the Concept Without Losing Students
Students consistently confuse permutation with combination problems. The diagnostic test is simple. Ask whether swapping two selected items produces a different outcome. If yes, it is a permutation problem. If no, it is a combination problem. The classic lock versus team problem illustrates this. A combination lock requiring the digits 1, 4, 7 in that exact order is a permutation because 1-4-7 opens the lock and 7-4-1 does not. Selecting a three-person committee from ten candidates is a combination because Alice-Bob-Carol is the same committee as Carol-Alice-Bob. This single distinction resolves approximately 80 percent of student errors in introductory probability courses. Another pedagogical trap involves interpreting repetition allowance. Permutations with repetition allow the same element to occupy multiple positions, expanding the count from P(n,r) to n to the r. Permutations without repetition constrain each position to a unique element. The difference becomes dramatic at moderate values. Arranging 4 digits from 0 through 9 with repetition yields 10 to the 4 equals 10,000 outcomes. Without repetition, it yields P(10,4) equals 5,040 outcomes. The repetition case doubles the search space. Credit card PIN validation, locker combinations, and WiFi passwords typically assume repetition is allowed because digits repeat freely. Physical seating arrangements and tournament pairings assume repetition is forbidden because a person cannot occupy two seats simultaneously. The real-world constraint of physical implementability often violates mathematical assumptions. In tournament scheduling, you might calculate P(n,2) match pairings, but venue capacity, travel distance, and broadcast windows introduce dependencies that pure permutation theory ignores. A permutation counts the abstract arrangements. It does not tell you which arrangement fits a 14-day competition window with 8 venues and television time slots allocated in fixed blocks. The combinatorial count is the starting point. Operations research converts it into a feasible schedule through constraint satisfaction and integer linear programming. Both layers are necessary. Neither is sufficient alone.
When to Use Permutations and When to Stop
Use permutation counting when order encodes information and elements are distinguishable. Stop when the problem introduces symmetries you have not accounted for, repeated elements you have not normalized, or physical constraints that collapse mathematical distinctions. The unspoken rule in applied work is that the mathematical permutation count is an upper bound. Reality almost always delivers a smaller number due to equivalence relations, feasibility filters, and operational constraints that the pure formula cannot capture. The fastest reliable calculator for permutation counts is the Python expression math.perm n r in version 3.8 and later, which returns exact integer results without floating point approximation. For n up to about 20, this executes in microseconds. For n beyond 20, the result exceeds typical memory representation and requires arbitrary precision libraries or logarithmic handling. The boundary between tractable and intractable sits near n equals 20 for full enumeration and n equals 170 for direct factorial evaluation in double precision. These are hard computational ceilings, not soft recommendations. A final practical note. If you are designing a system where someone can guess the correct permutation by chance, the permutation space must exceed 2 to the 80th to resist brute force. Below that threshold, cloud computing resources can enumerate or probabilistically crack the solution faster than most human actors can react. Password systems, authentication tokens, and cryptographic challenges that rely on permutation spaces smaller than this boundary are vulnerable by design. The mathematics is clear. The engineering response is to increase n, introduce repetition, or layer additional constraints until the space crosses the security threshold.