Understanding How Genes Stack Up
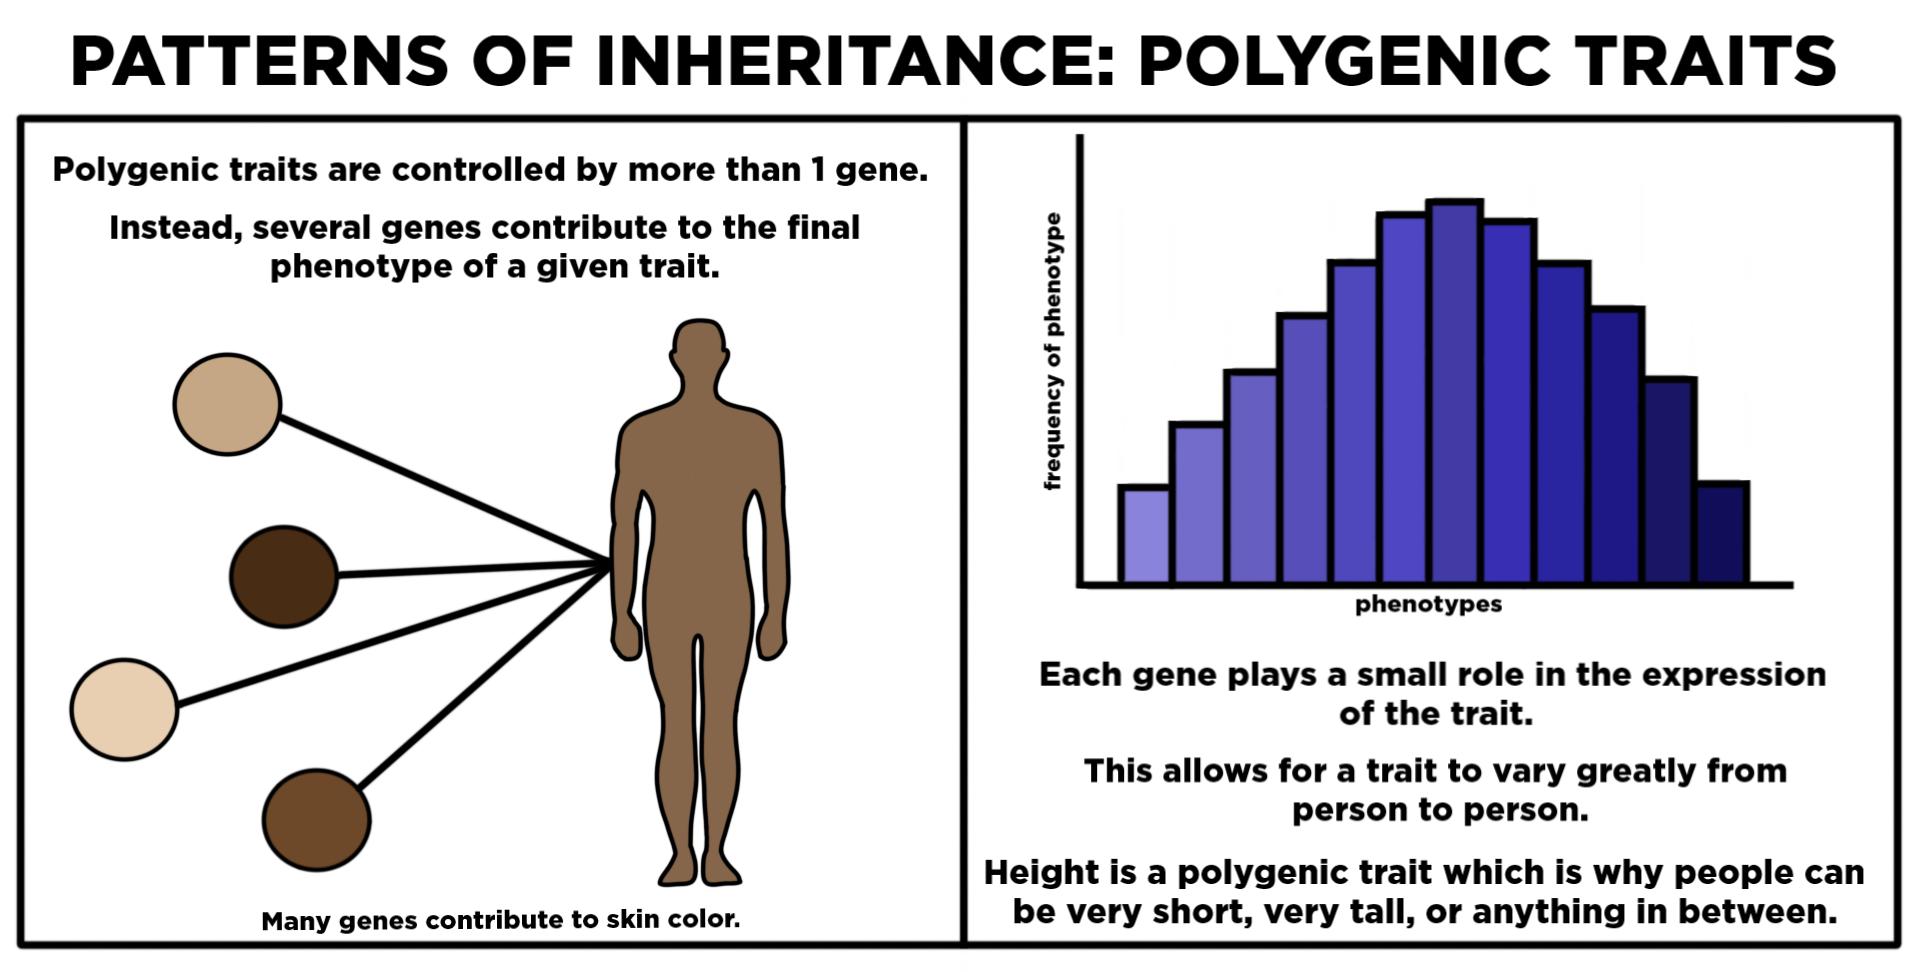
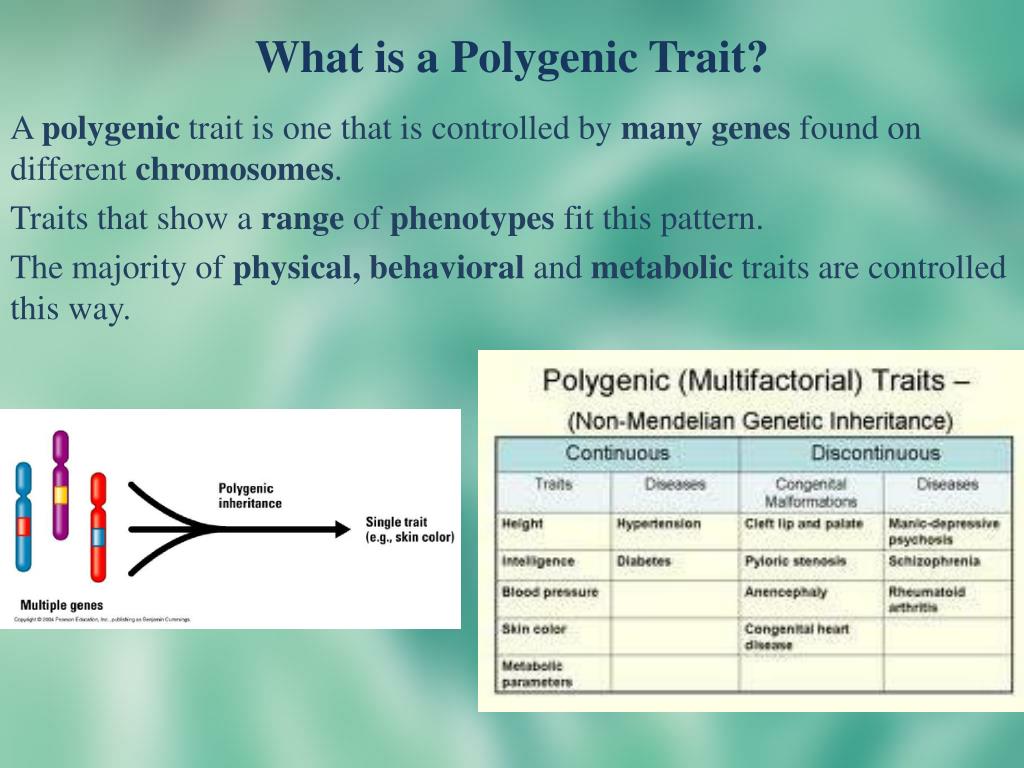
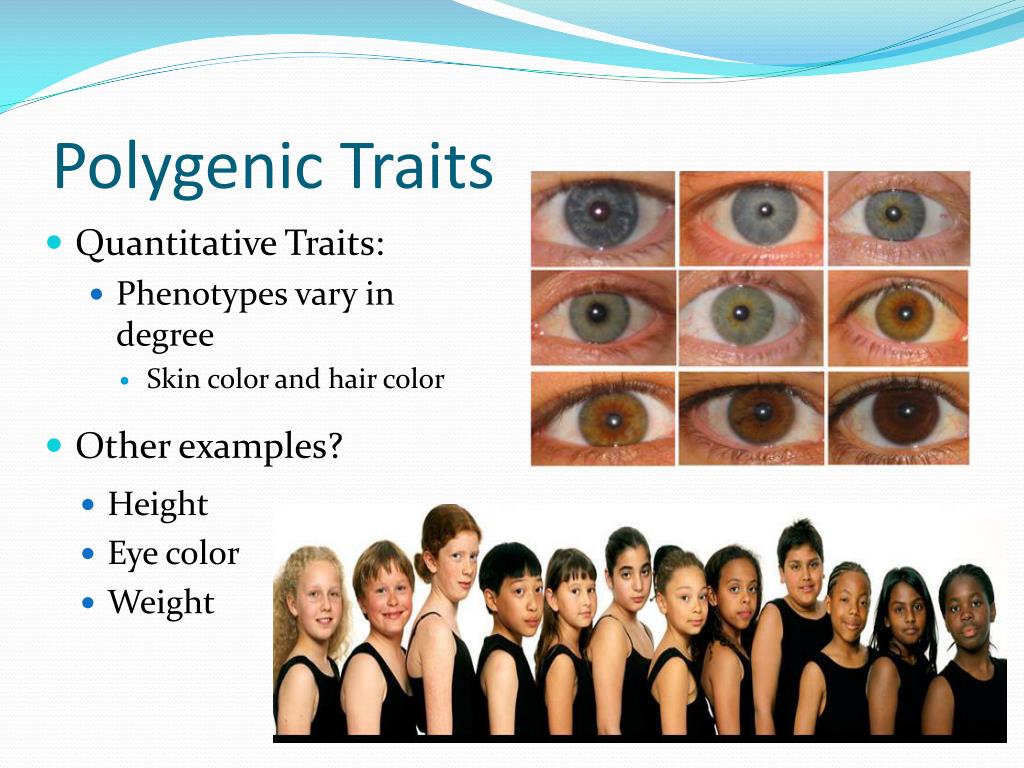
When I first started looking into quantitative genetics, I kept tripping over simple traits like eye color because people explain them like they're straightforward Mendelian stories. They're not. Real biology doesn't work that way for most things that actually matter. Height, skin tone, blood pressure, susceptibility to diabetes—none of those follow neat dominant-recessive patterns. They're polygenic, which means they come from lots of different gene variants each contributing a small amount to the overall trait. A polygenic trait is one influenced by multiple genetic loci, often dozens or hundreds of them, combined with environmental factors. That's really the whole definition. But the practical side is where things get interesting, and also where most people mess up.
What Is A Polygenic Trait in Practice
I spent months working with GWAS data on a project where we were trying to predict something as mundane as fasting glucose levels across a population cohort. What I learned is that calling a trait polygenic is almost too simple. The real challenge is that you're dealing with tiny effect sizes per variant. We're talking odds ratios hovering around 1.02 or 1.05 for individual SNPs. Your average person reads a news headline saying scientists found the "gene for obesity" and has no idea that what actually happened is one variant out of thousands shifted the statistical needle by a fraction of a percent. The workaround I ended up using was building a polygenic risk score weighted by effect sizes from the largest available meta-analysis, then cross-validating it against my own cohort's data instead of trusting published coefficients blindly. The published estimates tend to be inflated, especially for non-European populations, which turned out to be our population. The score dropped from an R² of 0.14 down to 0.07 when I applied it locally. That's a big difference if you're making decisions based on this stuff. One thing nobody tells you about polygenic traits: the heritability estimates you see in literature are usually narrow-sense heritability, meaning additive genetic variance only. They don't capture dominance or epistatic interactions, and for a lot of traits those non-additive effects are real but nearly impossible to pin down without enormous sample sizes. So when someone says a trait is 60% heritable, what they're actually saying is that 60% of the variation in that trait within that specific population at that specific time can be attributed to additive genetic differences. It's not a fixed number. It changes depending on how much environmental variation exists in the population you're studying.
Another counter-intuitive point that comes up constantly: a trait can be highly polygenic and still not respond well to selection in a breeding context if the genetic architecture includes a lot of rare variants with larger effects rather than common variants with tiny effects. Standard GBLUP models assume infinitesimal inheritance, which works okay for many agricultural traits but falls apart when you're dealing with structural variants or copy number polymorphisms that standard SNP arrays miss entirely. I ran into this when working with livestock data where imputation from a reference panel was clearly underestimating the true genetic variance. Switching to a sequence-level approach bumped the accuracy up noticeably, but it also tripled the compute time and required a completely different pipeline. Here's the blunt truth about polygenic traits though: they're often overhyped in consumer genetic testing. A polygenic score for height might explain 20% of variance in a well-powered European cohort. That sounds impressive until you realize the other 80% includes environment, measurement error, and non-additive genetic effects, and the predictive power drops dramatically outside the population the model was trained on. Ethnic mismatch isn't a minor issue. It's the single biggest source of error, and most companies selling these reports don't talk about it honestly. If you're getting into this work, start with the basics of linkage disequilibrium and population structure, because both will bite you if you ignore them. Then learn to read the supplementary materials of GWAS papers, not just the abstract. The methods section tells you what assumptions were baked into every number they report.
Get the Full Details