Population in practice
A population is the complete set of individuals, items, or observations that share at least one definable characteristic and from which you're drawing your sample. That's the textbook line. The version that matters is the one that survives contact with a real dataset. I used to treat "population" as whatever list I could export from a database. Then I spent three weeks building a model on a customer cohort before realizing the population boundary was wrong. The churn definition in the CRM only applied to active subscribers, but my analysis included expired accounts. Every coefficient was fine. The intercept was off by a meaningful amount, and any policy recommendation based on it would have been misleading. I fixed it by redefining the population as only customers with a confirmed subscription start date within the window I was studying. The fix took an afternoon, not a semester.
What Is A Population
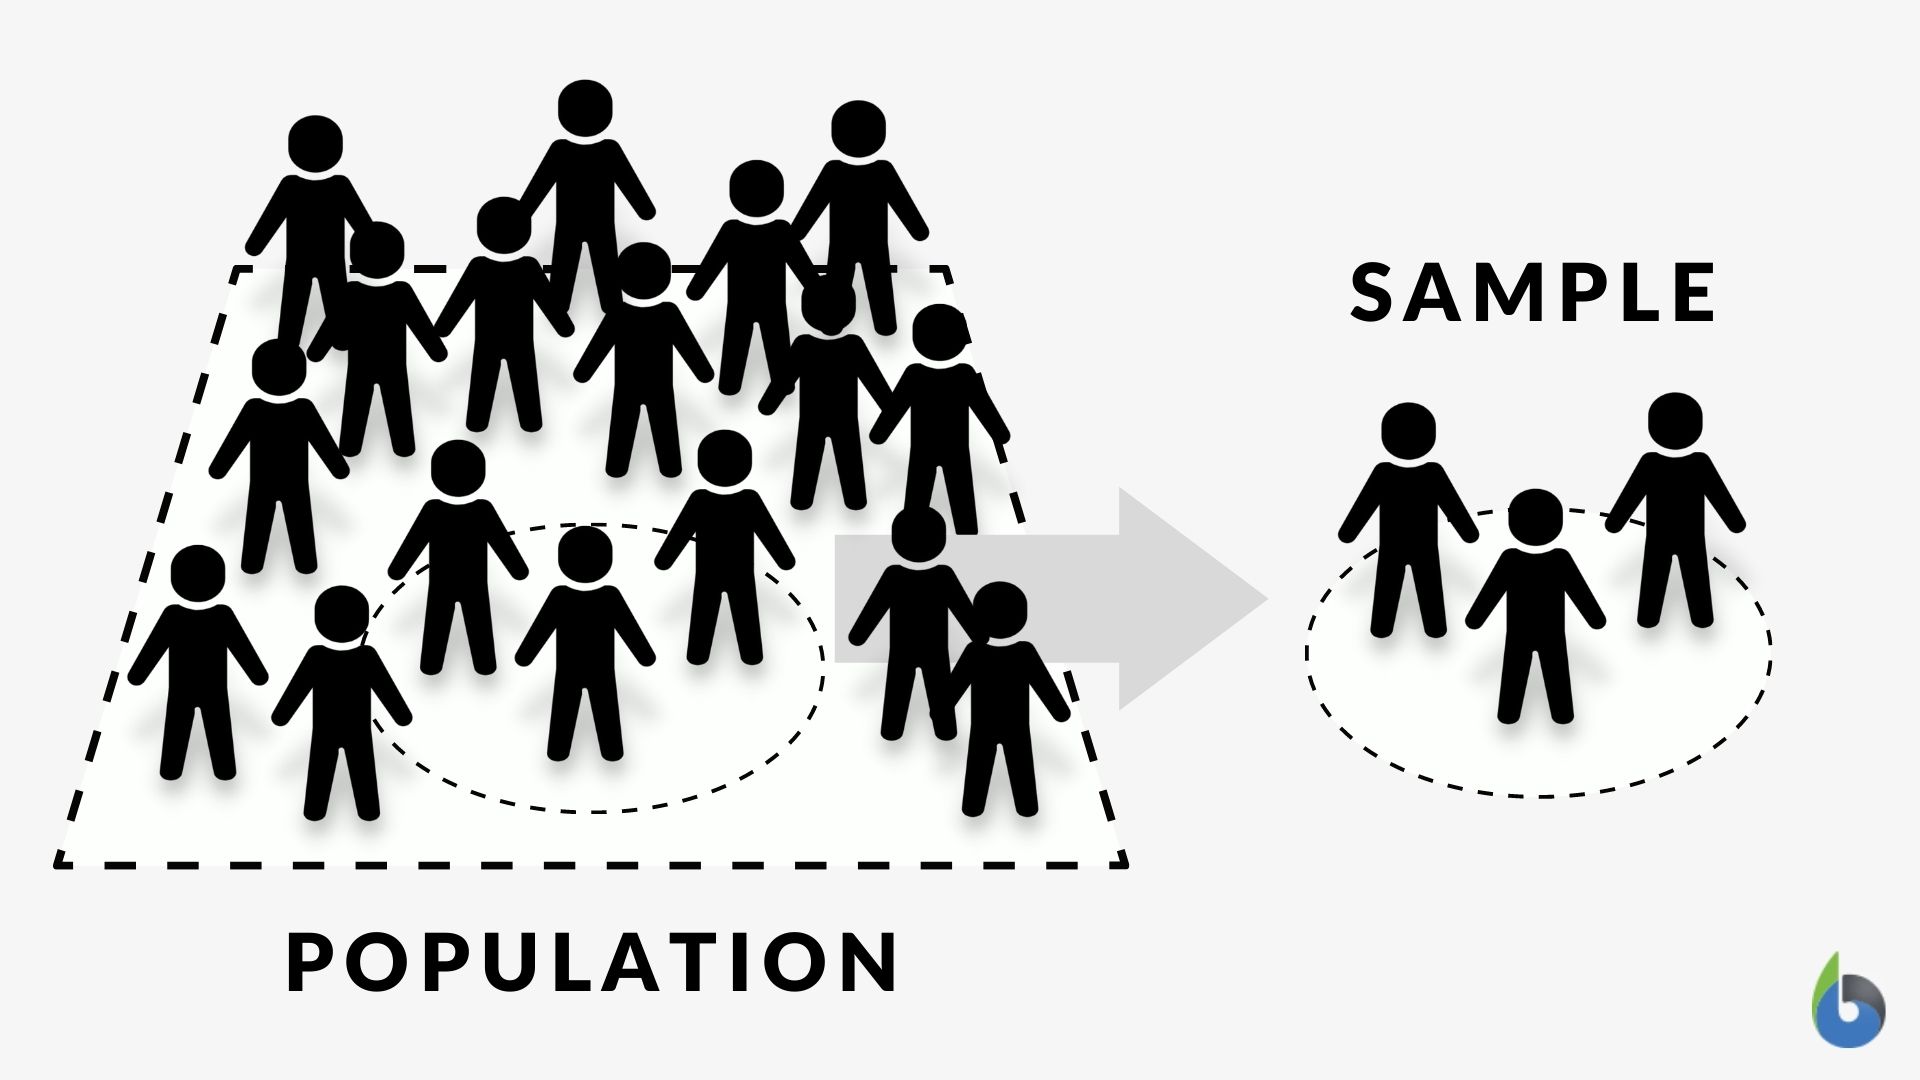
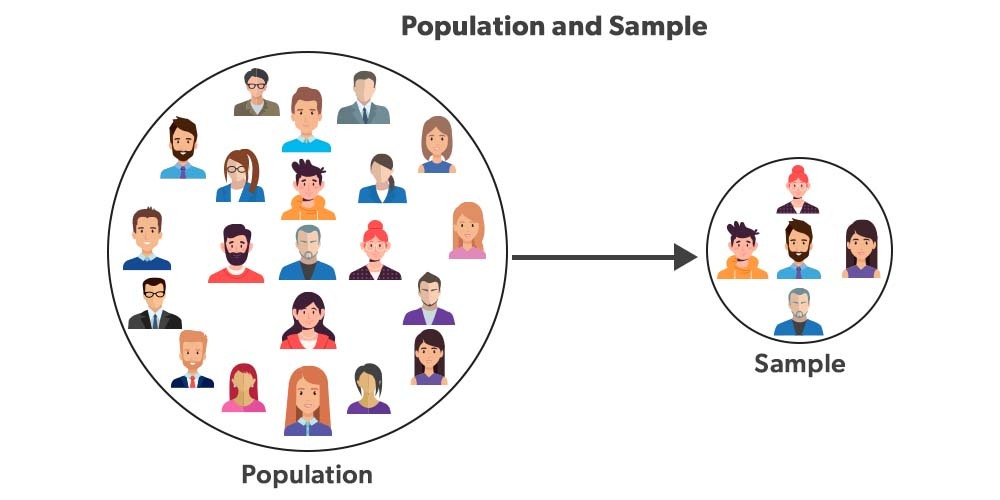
In statistics and research, the term has a precise enough meaning that most disputes come down to boundary definition, not conceptual confusion. The population is the full set of units you care about making claims about. Your sample is the subset you actually observe. The relationship between them is what drives everything else. If you're estimating the average blood pressure of adults in a country, the population is every adult resident in that country who meets your inclusion criteria. If you're measuring the mean output of a production line, the population is all units produced during the time window your inference applies to. Sometimes that list is finite and countable. Sometimes it's effectively infinite, like all possible future demand observations in a continuous process. Both are still populations. The math just changes slightly. Finite versus infinite populations is where beginners fumble. A finite population has a known, countable size. You can apply the finite population correction when your sample represents a significant fraction of the whole. The usual cutoff is a sampling fraction above five percent, though some people use ten percent depending on how conservative they want to be. An infinite population assumes the source is large enough or the process continuous enough that the correction factor is negligible. Most real-world cases fall somewhere in between, and the right call depends on what you're measuring.
How to define your population so it actually works
I start by writing down three things before I touch any data: the unit of analysis, the inclusion criteria, and the time window. Missing any one of those creates ambiguity that shows up later as inconsistent results or arguments with reviewers who noticed something you didn't. The unit of analysis is the thing you're counting or measuring. It might be a person, a transaction, a device, a hospital stay, a sentence in a corpus. Pick one level and stick with it. Mixing units is how you get an effective sample size that makes no sense and confidence intervals that look reasonable until someone checks the denominator. Inclusion criteria should be specific enough that another researcher could replicate the same list without guessing. Age ranges, geography, status flags, measurement thresholds. If your criterion is "relevant users," you're not defining a population. You're describing a mood.
Get the Full Details
The time window matters more than people admit. A cross-sectional snapshot is a different population from a longitudinal one, even if the people are the same. If you're studying annual revenue, the population is annual revenue observations, not customers. Those are different distributions with different variances.
Common traps that sink projects quietly
The biggest mistake I see is confusing the target population with the accessible population. Your target might be all smartphone users in a country. Your accessible population is the people reachable through a particular app store or survey panel. The gap between them is coverage error, and it's almost never zero. If your accessible population is younger, wealthier, or more tech-savvy than the target, your estimates will drift in predictable directions. The drift is rarely huge on average, but it's systematic, which means it doesn't cancel out with a bigger sample. Another trap is treating a convenience sample as a census. A hundred respondents from one forum thread is not a population. It's a sample from a very narrow subpopulation. Drawing conclusions about "people" from that is a category error, not a statistical one. Edge case from my own work: I once analyzed support ticket resolution times and reported population-level averages without realizing the ticket system auto-closed stale tickets after thirty days. Tickets older than that were censored. The observed mean was faster than the true mean because the slowest cases were missing from the data. I corrected by treating it as a right-censored dataset and using survival analysis methods instead of plain arithmetic means. The difference was about fourteen percent on the average, which sounded small until someone tried to staff a team based on it.
Methods for working with populations
If you know the population size and have complete data, you calculate descriptive statistics directly. The population mean is the sum of all values divided by the population size. The population variance uses N in the denominator, not N minus one. That distinction matters when you're reporting population parameters versus sample estimates. When you only have a sample, you use sampling theory. Simple random sampling gives you unbiased estimators with standard errors that shrink as your sample grows. Stratified sampling can reduce variance if you can divide the population into homogeneous groups and sample proportionally or optimally within each stratum. Cluster sampling is cheaper but usually less precise for the same total sample size because observations within a cluster tend to correlate. For finite populations, apply the finite population correction factor: square root of one minus the sampling fraction. It tightens your confidence intervals when you've sampled a non-trivial portion of the population. Ignoring it when you should is a small sin. Applying it when you shouldn't is worse because it understates uncertainty.
Sample size calculation is the practical engine here. You need an estimate of the population variance, your desired margin of error, and your confidence level. The formula is straightforward for means and proportions. The hard part is getting a realistic variance estimate without running the study first. Pilot studies help, but they cost time. Using published variance from similar contexts is common and usually acceptable, provided the contexts are similar enough.
Tools and workflows
Most analysis happens in standard environments. R handles complex survey designs well with the survey package. Python has statsmodels for basic inference and scipy for distributions. SPSS and Stata are fine for standard workloads if that's what your team knows. The software choice rarely matters as much as the methodology choice. I keep a population definition template as a plain text file alongside every project. It forces me to state the unit, criteria, window, and any exclusions before I load data. Five minutes of writing prevents three days of doubt later.
Where this breaks down
Population inference assumes your sample is representative of the population you defined. When that assumption fails, no amount of weighting or adjustment fully repairs it. Post-stratification can help with known demographic margins, but it can't recover variables you never measured. If your survey doesn't ask about income and your outcome correlates with income, you're stuck. Non-response bias is the other common failure mode. High non-response doesn't just reduce precision. It biases estimates if the people who don't respond differ systematically from those who do. Weighting by response propensity helps, but only if you have data on responders versus non-responders across relevant dimensions. For highly mobile or ephemeral populations, like daily active users of a shifting platform or transient workers in a gig economy, the population itself may change during your study window. That makes the concept of a fixed population meaningless. In those cases, switching to a superpopulation framework, where you treat observed data as draws from an underlying process, is more honest than pretending the boundary is stable.

The bottom line is that population is not just a definition problem. It's an operational one. Get the boundary right, acknowledge what your data actually covers, and report the gap honestly. Everything else follows.


