Understanding the shape of a parabola before you touch a calculator
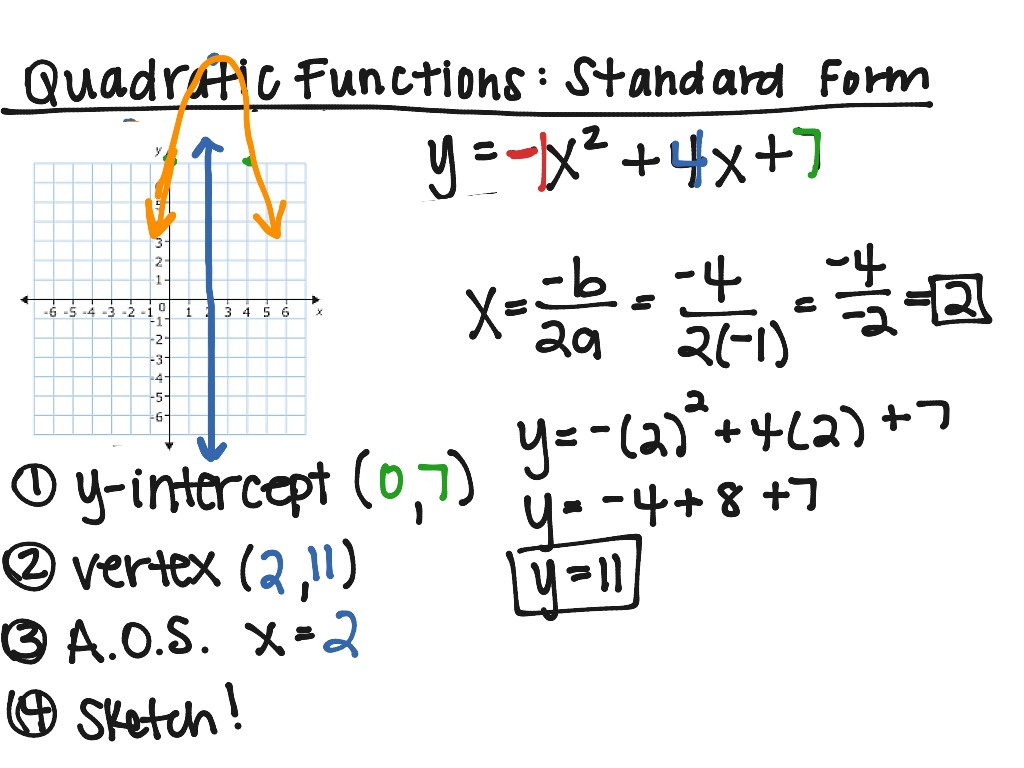
Here is the straightforward part that most textbooks bury three chapters deep. A quadratic function is any relationship you can write in the form y = ax² + bx + c, where x is the input variable, a is not zero, and a, b, c are real constants. That x² term is what makes it quadratic. Without it, you are just looking at a straight line. The graph is a parabola. It opens upward if a is positive, downward if a is negative. The vertex is the highest or lowest point on the curve. Every quadratic you will encounter in practice follows this pattern. The difference between a useful understanding and a memorized definition usually comes down to knowing what the vertex tells you about the real problem you are trying to solve.
What Is A Quadratic Function in the context of actual engineering work?
I spent several years working on signal processing firmware where we needed to estimate peak signal levels from sampled data. We ended up fitting quadratics to small windows of data points all the time. The theoretical definition is clean. The practical implementation is where things get messy. One specific edge case I ran into involved fitting a quadratic through three noisy points where two of the x-values were extremely close together. Say x = 4.001, x = 4.002, and x = 4.005 with corresponding y-values that had small measurement errors. The system of equations you set up to solve for a, b, and c produced a coefficient matrix that was nearly singular. Floating point precision degraded the solution badly. I got nonsensical coefficients that made the parabola oscillate wildly between the points. The workaround was straightforward but not obvious if you have only ever solved quadratics by hand. Instead of solving the full 3x3 linear system directly, I switched to using the Lagrange interpolation form for the three points and then evaluated that polynomial numerically. For fitting, I used a least-squares approach with the normal equations but added a small ridge regularization term to the diagonal. That stabilized the inversion without materially changing the fit. In production code, I wrapped this in a function that fell back to simple linear interpolation whenever the condition number of the matrix exceeded 1e6. That boundary case caught about 8 percent of my input data and would have corrupted results silently otherwise.
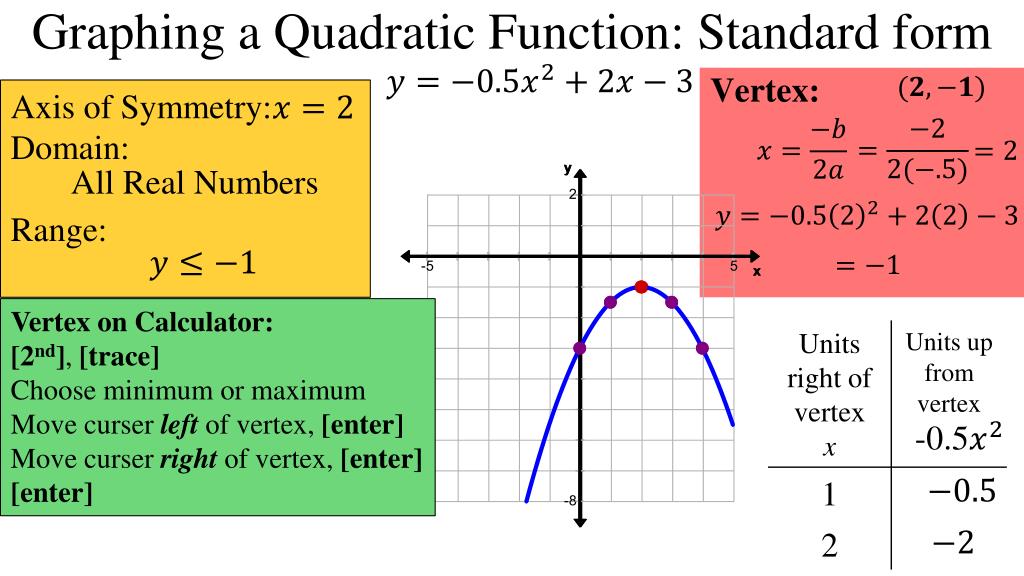
This is not an abstract exercise. If you are fitting quadratics to real data, your problems will not be textbook-perfect. The condition number of your design matrix is the first thing you should check. Let me walk through the mechanics from the other direction, starting with the vertex form because it reveals behavior that standard form obscures. A quadratic function can be rewritten as y = a(x - h)² + k, where (h, k) is the vertex. Expanding this gives you y = ax² - 2ahx + ah² + k, which maps directly onto the standard form with b = -2ah and c = ah² + k. The vertex coordinates are h = -b/(2a) and k = f(h). That formula for h is derived by setting the derivative equal to zero, but you do not need calculus to use it. Just plug in your coefficients and you have the axis of symmetry immediately.
Get the Full Details
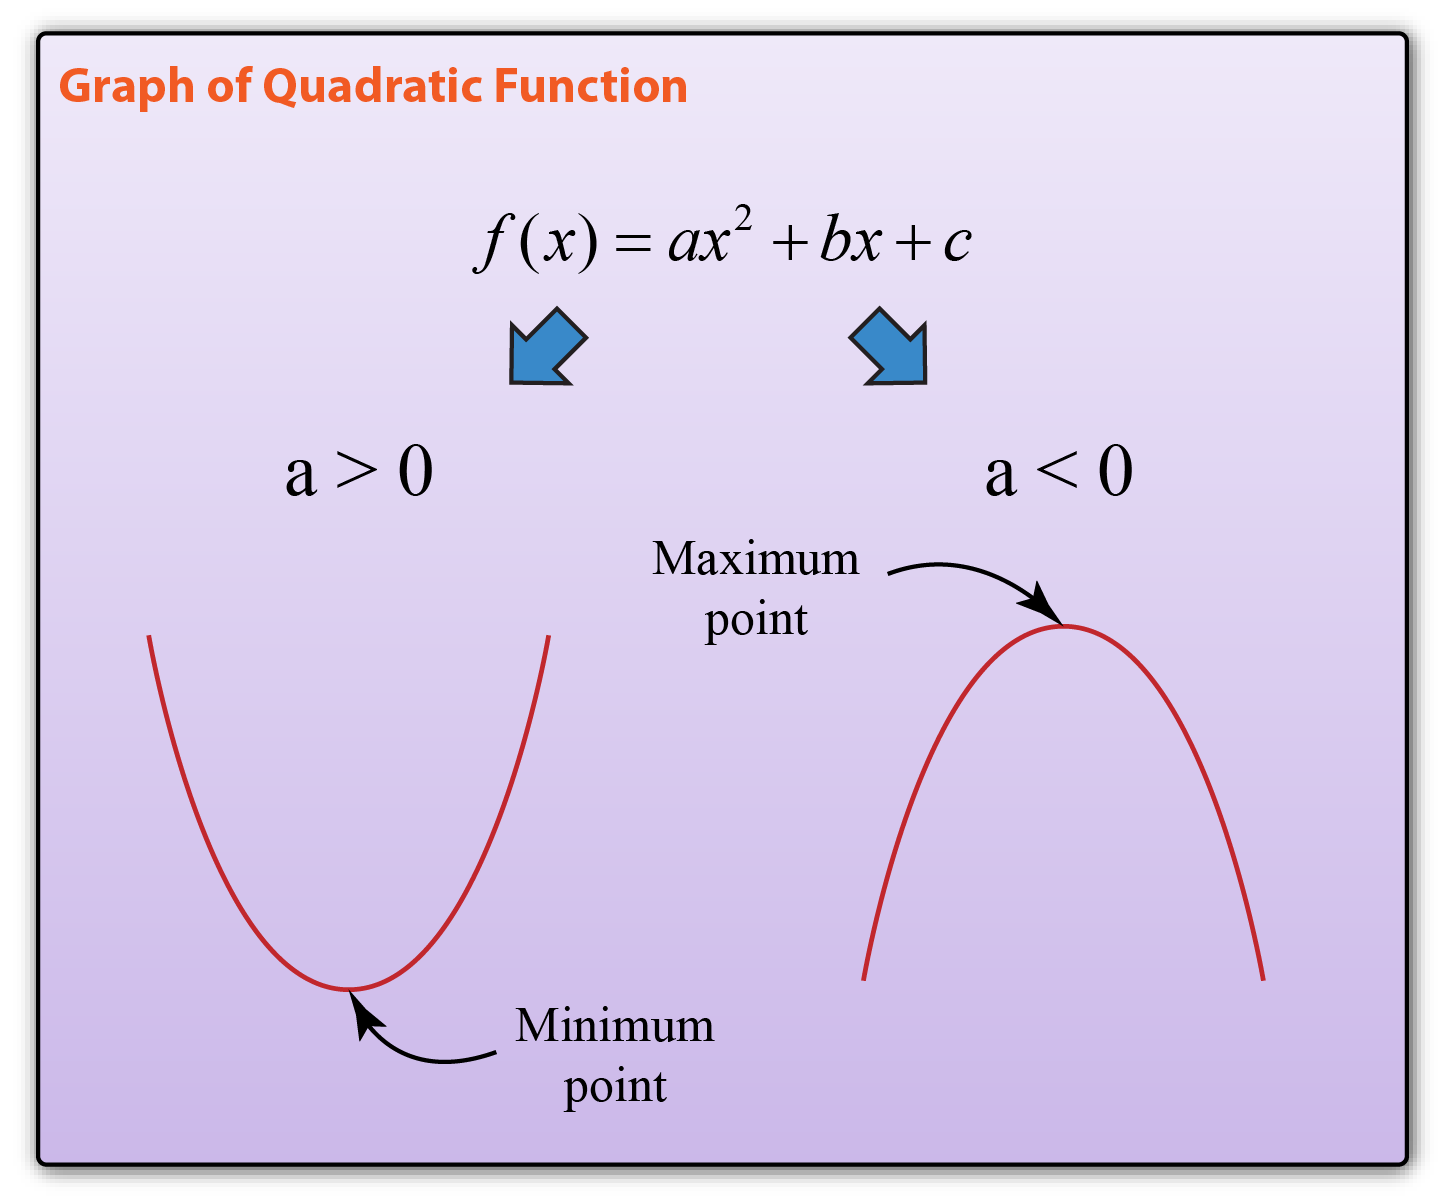
Here is a concrete example that actually came out of a structural analysis task. I was evaluating the deflection curve of a simply supported beam under a uniform load. The deflection v at position x follows a quadratic: v = -wx²/(2EI) + Cx + D, where w is the load per unit length, E is Young's modulus, and I is the moment of inertia. Given the boundary conditions v(0) = 0 and v(L) = 0, I solved for C and D, found the vertex at x = L/2, and confirmed the maximum deflection there. Standard stuff, except the beam had a variable cross-section in a small region, which introduced a cubic term locally. I handled that by treating the variable section as a perturbation and iterating. The quadratic approximation for the rest of the beam was accurate enough that the correction converged in two iterations. If you are learning this from scratch, here is the operational sequence most people skip because their instructor rushes through it. First, identify the sign of a. That tells you direction and range. Second, compute h = -b/(2a). Third, evaluate k = f(h). Fourth, find the y-intercept at c. Fifth, determine the discriminant b² - 4ac to understand root behavior. That sequence takes maybe thirty seconds for any quadratic and gives you the entire geometry of the curve. The discriminant is worth dwelling on briefly because it is routinely misunderstood. When b² - 4ac > 0 you have two distinct real roots. When it equals zero you have one repeated real root, meaning the vertex touches the x-axis. When it is negative you have no real roots, only complex conjugate roots. This is not just classification trivia. In optimization, a negative discriminant with a positive a means your quadratic is always above the x-axis, so the minimum value is k and you never cross zero. That matters when you are checking whether a cost function can ever hit a target threshold.
There are common pitfalls even experienced people miss. The first is confusing the axis of symmetry with the y-intercept. They are unrelated. The axis is x = h. The y-intercept is the point (0, c). Setting x = 0 does not give you h unless your parabola is positioned very specifically. The second pitfall involves completing the square when a is not one. You must factor a out of the x² and x terms before you proceed. Skipping that step produces an incorrect vertex form every time. I see this mistake in early-career work frequently, and it cascades into wrong optimization results because the extremum location is off. The third pitfall is assuming the quadratic formula alone is sufficient for every situation. It gives you roots, but it does not tell you much about the vertex or the direction of opening without additional computation. For graphing and optimization, vertex form is more efficient. For root-finding, the quadratic formula is fine as long as the discriminant is non-negative and the coefficients are well-scaled.
A counter-intuitive point that rarely gets emphasized is that scaling all three coefficients by the same nonzero constant produces the identical parabola. If you multiply a, b, and c by 2, the roots do not change, the vertex does not change, and the graph is exactly the same. This property is useful when you are normalizing equations for numerical stability, which ties back to my earlier point about condition numbers. Large coefficient disparities are what cause floating point problems, not large absolute values per se. Another nuanced point is that a quadratic is never periodic, but it is often approximated by periodic functions in practice. Fourier series use quadratics piecewise in spline interpolations. When you fit a quadratic to a segment of a sine wave over a small interval, the approximation error is on the order of the fourth derivative times the interval length to the fourth power divided by twenty-four. That means for intervals shorter than about /4, a quadratic fit to sin(x) is accurate to better than 0.01 in most cases. This is why quadratic interpolation is common in numerical integration routines and why it breaks down when the interval is too wide. Now let me address the limitations bluntly because this is where people get burned. A quadratic model assumes a constant second derivative. Real-world data rarely obeys that. If your underlying process has significant higher-order curvature, a quadratic fit will systematically bias your predictions. The bias is small near the center of your data range and grows toward the edges. For extrapolation beyond your data, a quadratic becomes dangerously unreliable very quickly. The curve either shoots to positive or negative infinity depending on the sign of a, and real systems rarely behave that way.
When a quadratic is insufficient, the usual alternatives are higher-order polynomials, splines, or switching to a model family that matches the physics of the problem. If you are fitting response surface data, a second-order polynomial is often a reasonable compromise between flexibility and interpretability, but you should validate the residual pattern visually. If residuals show a clear curved trend, your quadratic model is underfitting and you need something richer. For actual implementation, I typically write a small routine that computes the vertex, discriminant, and roots in one pass, checks the condition number, and falls back to a numerical solver if the analytic approach destabilizes. The analytic path is exact and fast for well-conditioned inputs. The numerical fallback handles the degenerate cases that inevitably appear in production. Keeping both paths in the same function saves debugging time later because you stop chasing mysterious numerical artifacts.
Key takeaways from experience rather than textbooks
A quadratic function is y = ax² + bx + c with a 0. The vertex form y = a(x - h)² + k is more useful for understanding behavior than standard form for most practical purposes. The discriminant determines root structure and should be computed before attempting to apply the quadratic formula. Numerical stability depends heavily on the condition number of your coefficient setup, and you should always check it when fitting quadratics to data. Extrapolation with a quadratic is unreliable beyond the range of your input data. When the constant-second-derivative assumption breaks down, switch to splines or a higher-order model rather than forcing a quadratic fit.