Putting A Line Through The Mess
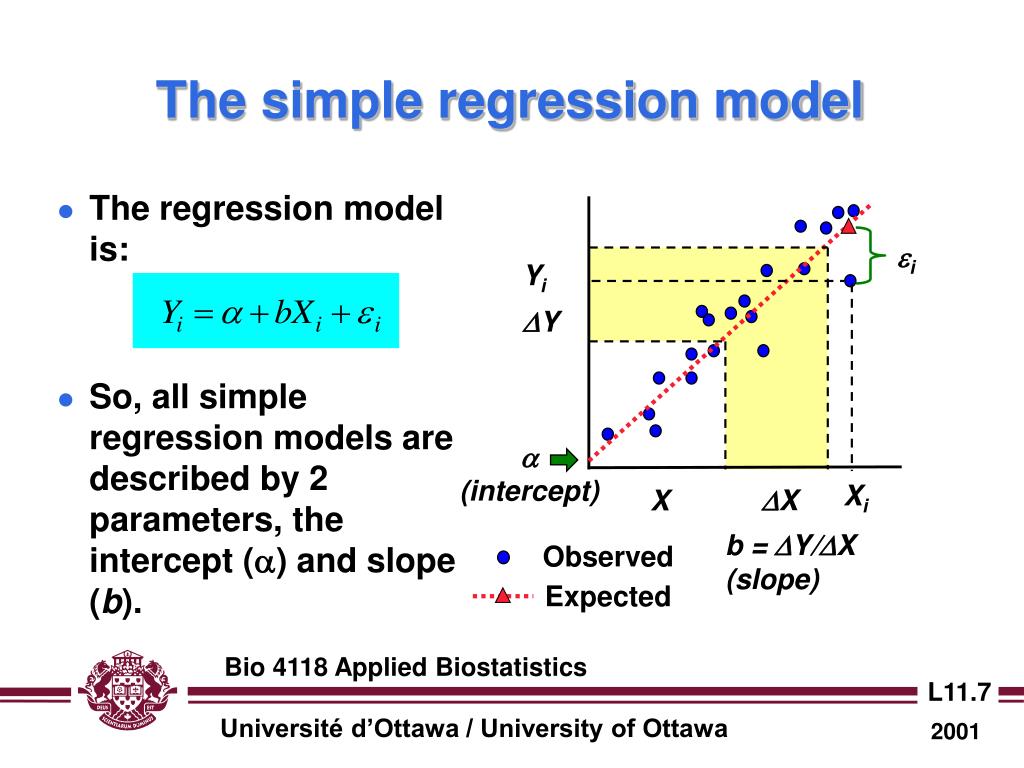
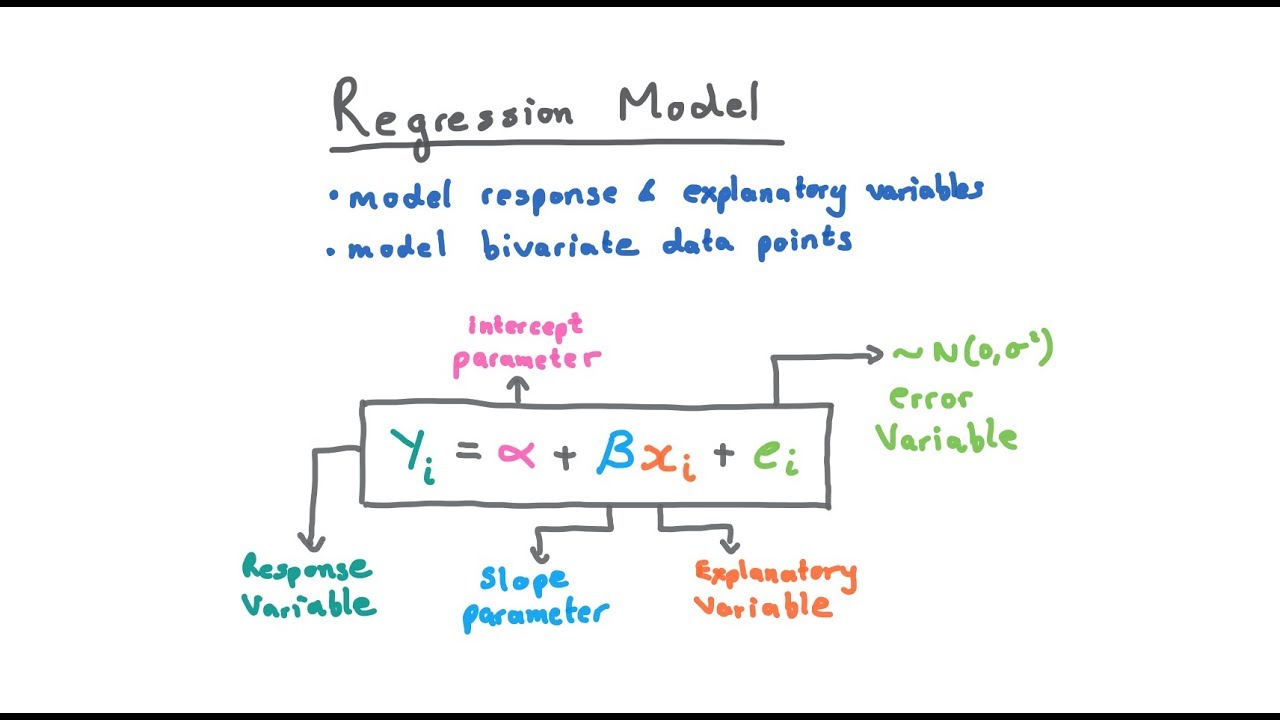
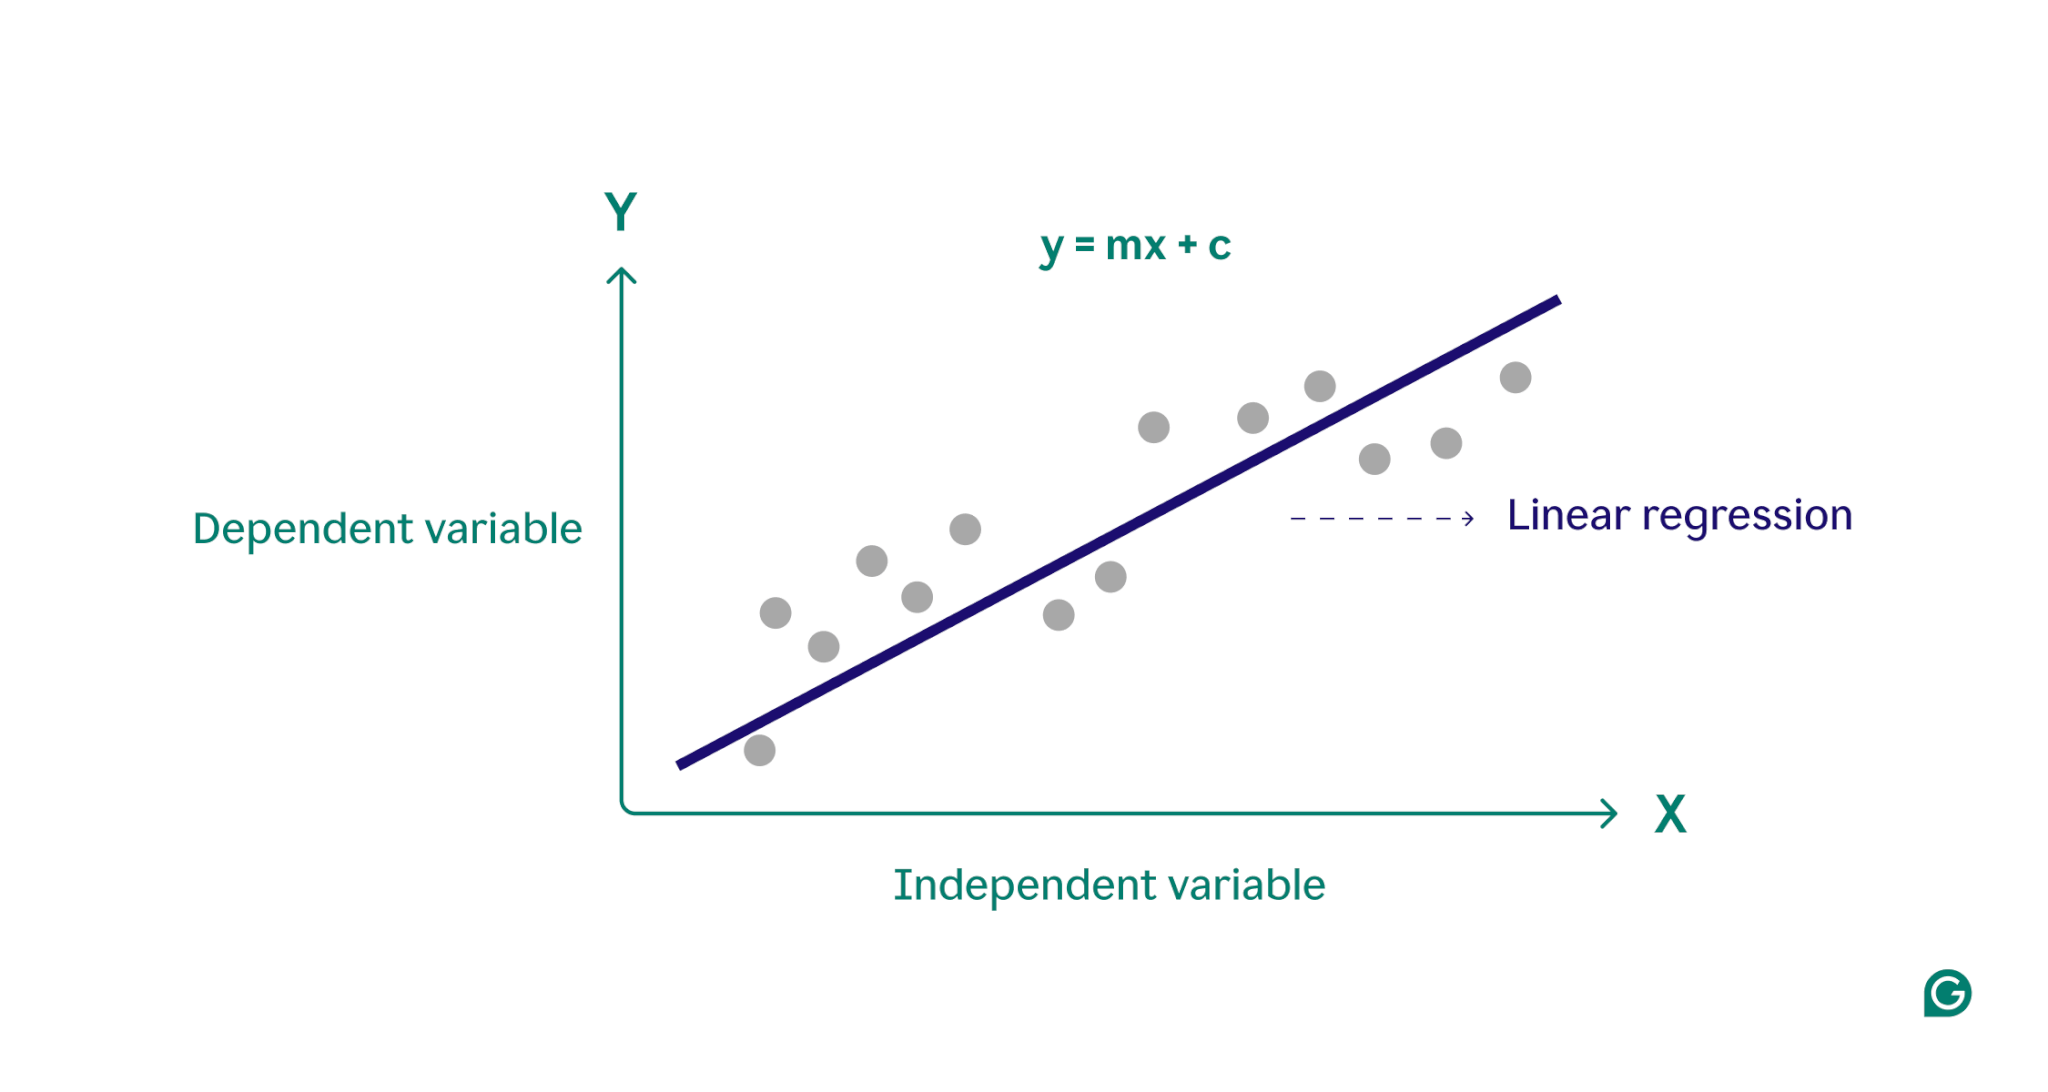
I still remember a project from a few years back where we were modeling revenue against ad spend across twelve different markets. The model looked perfect on paper. Then we tried to use it for a budget forecast and it suggested allocating $3.4 million to a market that barely had a distributor. The culprit was a single outlier country that happened to have a massive one-time bulk purchase skewing the entire regression. It took me two days to realize what was happening. We ended up using robust regression with Huber loss instead, which downweights outliers without just deleting them. That experience taught me something most intro courses don't: regression isn't about finding the best fit. It's about finding the right fit for what you actually need the model to do. At its core, a regression model estimates the relationship between a dependent variable and one or more independent variables. Linear regression fits a hyperplane to your data by minimizing the sum of squared residuals. That means it's trying to make the total vertical distance between every actual data point and the predicted value as small as possible. You've probably seen the equation y = mx + b or the multiple regression version with beta coefficients. The math is straightforward. The interpretation is where things get messy. There are several flavors depending on what you're modeling. Linear regression works for continuous outcomes. Logistic regression is for binary classification, even though it has "regression" in the name. Poisson regression handles count data. Ridge, Lasso, and elastic net add regularization penalties to the cost function to handle multicollinearity and feature selection. Each variant exists because the basic ordinary least squares approach breaks down under specific conditions, and those conditions show up constantly in real data.
Let me walk through how I actually build one, because the order matters more than people realize. I start with the target variable and map out every feature I think could plausibly influence it. Then I look at the distribution of that target. If it's heavily right-skewed, like revenue or response time, I'll take a log transform before fitting anything. Skipping this step is one of the most common mistakes I see, and it silently invalidates your confidence intervals and p-values. Next I check for multicollinearity. Variance inflation factors above 5 or 10 are a red flag. When two features are highly correlated, the model can't tell which one is actually driving the outcome. The coefficients become unstable and flip signs between training and validation sets. I deal with this by either dropping one of the correlated features, combining them into a composite score, or switching to ridge regression which penalizes large coefficient values and stabilizes the estimates. Lasso does feature selection by shrinking some coefficients all the way to zero, but it can be arbitrary when features are correlated and will pick one randomly between them. After that comes the train-validation split. I use a time-based split whenever the data has any temporal component because random splitting leaks future information into the training set. A model trained on data from January through August and tested on September won't tell you how it'll perform next month. It'll tell you how well it remembers the past. For cross-sectional data without a time element, I use stratified k-fold with five folds and a random seed for reproducibility. I record the validation metrics after every fold and only look at them once the full pipeline is locked down.
Feature engineering happens alongside modeling, not after. I create interaction terms for features that theoretically amplify each other. I bin continuous variables when the relationship looks nonlinear but I don't want to jump to tree-based methods. I encode categoricals with target encoding for high-cardinality features and one-hot encoding for low-cardinality ones. One-hot encoding with too many categories creates a sparse matrix that eats memory and slows training without adding information. The actual fitting process varies by tool. In Python with scikit-learn, it's usually a few lines: instantiate the regressor, call fit on the training data, call predict on the validation set, then evaluate with mean squared error, root mean squared error, and R-squared. In R, the lm() function handles ordinary least squares and glm() covers generalized linear models. Both give you coefficient tables, standard errors, and diagnostic statistics out of the box. The default diagnostics in R are actually useful if you know how to read them. Residuals versus fitted plots, Q-Q plots, scale-location plots, and Cook's distance for influential observations. Most people skip them entirely. Validation metrics deserve more attention than they get. R-squared is almost always reported and almost never useful on its own. A model can have an R-squared of 0.92 and still be completely unusable for prediction if the residuals show a clear pattern. That pattern means your model is missing something systematic. I always check residual plots against every feature and against the predicted values. If you see a funnel shape, you have heteroscedasticity and your standard errors are wrong. If you see a curve, you have a nonlinear relationship you haven't captured. If you see clusters, you have unmodeled subpopulations.
Get the Full Details
Root mean squared error is more interpretable than mean squared error because it's in the same units as your target variable. A RMSE of 4700 on a revenue model means your typical prediction is off by about four thousand seven hundred dollars. That's actionable. It tells you whether the model is precise enough for the decision it needs to support. Adjusted R-squared accounts for the number of predictors and penalizes adding features that don't improve the model. It's better than raw R-squared but still shouldn't be the primary metric. I use it as a sanity check alongside out-of-sample performance. Here's something that surprises people: regularization often produces better predictive models than unregularized regression, even when the true underlying relationship is linear. Ridge regression shrinks coefficients toward zero, which reduces variance at the cost of a small amount of bias. The bias-variance tradeoff usually favors this. In practice, I find elastic net gives the best results because it combines L1 and L2 penalties and handles groups of correlated features better than either method alone. The hyperparameters for the penalty strength and the mix between L1 and L2 require grid search or randomized search with cross-validation. I use three to five minutes of grid search time for initial exploration and expand from there if the results look promising. Another thing people miss is that regression assumes linearity in the parameters, not necessarily in the features. You can include polynomial terms, splines, or logarithmic transforms and still be doing linear regression because the model is linear in the betas. Generalized additive models take this further by allowing each feature to have its own smooth function. They're available in both Python and R and they often capture structure that polynomial terms miss without the black-box nature of random forests.
The biggest limitation of regression models is their assumption that the relationship observed in training data holds in production. This fails when the data generating process changes. A pricing model built during a period of stable supply chains will produce nonsense during a supply shock. A churn model trained on pre-pandemic behavior won't generalize after a major policy shift. I learned this the hard way with a customer lifetime value model that performed beautifully for fourteen months and then started systematically overpredicting by about forty percent after a competitor entered the market. The feature relationships hadn't changed, but the baseline distribution had. The fix was retraining on a rolling window of the most recent eighteen months instead of the full historical dataset. Regression also struggles with sparse categorical features and complex interactions that tree-based methods capture naturally. If your data has hundreds of high-cardinality categoricals and you need to model interactions without specifying them explicitly, you're better off with gradient boosting. XGBoost, LightGBM, and CatBoost handle these cases better and often achieve higher accuracy. But they're harder to explain to stakeholders and they don't give you interpretable coefficients. When you need to justify a decision or understand which factors matter, regression remains the best tool available. If you're getting started, the practical path is to install scikit-learn and pandas in Python, load a dataset with a numeric target, and fit a basic linear regression. Look at the coefficients. Check the residuals. Then add regularization and watch the coefficients change. Compare predictions on held-out data. Move to logistic regression with a binary target. Then try a decision tree and compare its predictions to the linear model. The differences will teach you more than any textbook explanation.
R-squared is not a measure of model quality. It's a measure of variance explained, and a high value doesn't mean your model is valid. Check the diagnostics. The assumptions matter more than the metrics. Outliers, heteroscedasticity, nonlinearity, and multicollinearity will silently degrade your model long before the R-squared drops to anything alarming. Regularization isn't cheating. It's acknowledging that your data is noisy and your sample is finite. Unregularized regression fits the training data perfectly and then fails on anything new. Regularization accepts a little bias in exchange for dramatically lower variance. That's usually the right trade. The best regression model is the simplest one that captures the structure you care about. Adding features until R-squared stops improving is a losing game. Every added parameter increases the risk of overfitting and decreases interpretability. I usually stop adding features when the validation RMSE stops decreasing for three consecutive additions and the adjusted R-squared plateaus.

For learning resources, scikit-learn's documentation has excellent tutorials with executable code. The book "An Introduction to Statistical Learning" is freely available online and covers the theory without excessive math. For production deployment, make sure your preprocessing pipeline is saved alongside the model. Feature transformations, imputation strategies, and encoding schemes need to be applied identically to new data. A model that can't be reproduced on fresh inputs is just a collection of numbers.