Spooling in practice
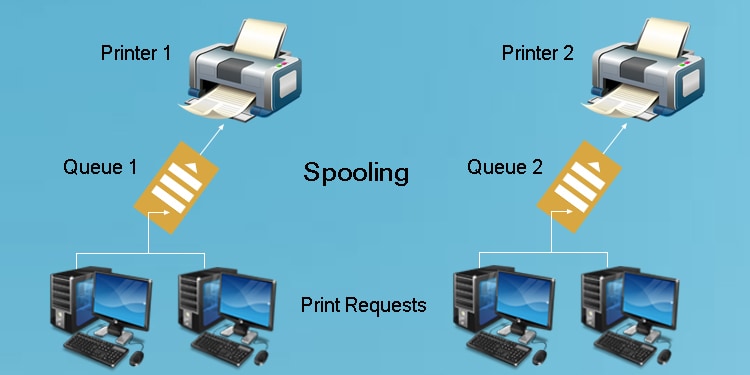
Spooling is one of those fundamentals that nobody thinks about until it breaks and then your entire office is stuck waiting for a single document to finish printing. The term itself is an acronym that most people in the field just accept without really unpacking it. It stands for Simultaneous Peripheral Operations On-Line. That sounds like corporate jargon until you actually work with it, at which point it describes exactly what happens: the system takes output meant for a slow peripheral device, stores it somewhere temporarily, and feeds it out at whatever pace the device can handle. The classic example is a network printer. Without spooling, if ten people on a network all send documents to the same printer at once, the printer literally receives ten different streams of data at the same time and everything collides. Jobs get corrupted, pages print half-complete, and you end up with a garbled mess. Spooling solves that by intercepting each print job, stashing it in a designated area on disk, and then feeding the data to the printer one job at a time in orderly sequence.
What Is A Spooling
At its core, spooling is about decoupling the producer from the consumer. The application generating the output thinks it is writing directly to a device. In reality, it is writing to a buffer or a queue. A background process called a spooler then reads from that buffer and pushes data to the actual hardware at the hardware's own speed. This means a fast CPU can dump a massive document to the spool area in seconds and go do other work while the spooler slowly feeds the printer over the next five minutes. In Windows, the print spooler service (Spooler) handles this for all standard printers. On Linux systems, CUPS manages the equivalent function. Both operate on the same principle even though their implementation details differ. The spool files typically land in C:\Windows\System32\spool\PRINTERS on Windows and in /var/spool/cups on Linux. I ran into a situation a few years back with a shared laser printer on a Windows Server 2012 box. Someone had installed an old PostScript driver that didn't handle large PDF files well through the spooler. What would happen is the first two or three pages would print fine and then the spool file would corrupt mid-job, freezing the entire queue. Every subsequent job sat there indefinitely and nothing moved. Standard troubleshooting didn't catch it because the queue looked normal from the interface. The workaround was to enable direct printing to the printer in the printer properties for that specific driver, which bypasses the spooler entirely. It was slower for large jobs because the application holds onto the data instead of handing it off, but it eliminated the corruption issue completely. The tradeoff was obvious: you lose the ability for users to cancel jobs mid-print, but you gain reliability.
There is a common misconception that spooling only applies to printing. It does not. Any scenario where a fast device sends data to a slow device uses spooling principles. Batch processing of data feeds into databases, output from computational simulations written to disk before being consumed by visualization tools, even the way modern web browsers stage file downloads before they fully arrive. The pattern is everywhere once you recognize it. Another thing that trips people up is the assumption that the spool always lives on disk. It does not have to. Memory-based spooling is faster because it eliminates disk I/O latency entirely, but it is also more fragile. If the system crashes, everything in the memory spool disappears. Disk-based spooling survives reboots, which is why most production environments default to it despite the slight performance penalty. The decision between RAM and disk for the spool area usually comes down to how critical job persistence is versus how fast throughput needs to be. One counter-intuitive detail about spooling that I wish more people understood: spooling does not actually make the printer faster. It makes the system feel faster for the people submitting work. The total time to produce all the printed pages remains the same because the printer operates at its fixed mechanical speed. What spooling changes is concurrency. Without it, users block each other. With it, users submit jobs and immediately return to their work. The printer itself is still just as slow as it always was.
Get the Full Details

Here are the practical downsides that nobody advertises. A full spool directory can silently consume disk space until related processes start failing. I have seen servers where the spool folder ballooned to dozens of gigabytes because stale jobs were never cleaned up properly, usually due to crashed applications that left orphaned spool files behind. There is no automatic garbage collection in many default configurations. You have to monitor it or write a cleanup routine. Security is another area that gets overlooked. Spooled print jobs on disk are often stored in readable formats. If someone gains access to the spool directory, they can potentially read the contents of documents that were queued but not yet printed. This is a real concern in environments handling sensitive data. The workaround is encrypting the print stream or using secure pull-print solutions that require authentication at the device before any job is released. If you need to manually clear a stuck spool queue, the process is straightforward but requires a specific order. Stop the spooler service, delete or move the contents of the spool directory, then restart the service. On Windows that means opening an elevated command prompt and running net stop spooler, clearing the files, and then net start spooler. On Linux you would use sudo systemctl stop cups followed by cleaning /var/spool/cups and restarting. Skipping the service stop step first is a mistake I see repeatedly. The spooler locks those files while running, and any attempt to delete them will fail silently or partially, leaving the queue in a worse state than before.
Another practical detail: the spool format matters. Some drivers spool raw data, meaning the printer receives unprocessed bytes and has to interpret them itself. Others spool as enhanced metafiles or EMF, which lets the computer do the rendering work before sending pages to the printer. The EMF approach is generally faster for the printer because the heavy lifting happens on the host machine, but it is less flexible when dealing with complex documents that might render differently on another driver. Raw spooling is more universal but puts more strain on the printer's processor. For most everyday situations, you do not need to think about spooling at all. It works in the background and handles the complexity automatically. But when something goes wrong, understanding the mechanism is what separates someone who restarts the service blindly from someone who actually diagnoses the problem. The spool directory, the service state, the driver's spool mode, and the available disk space are the four things to check in that order when a print queue behaves unexpectedly. In my experience, those four checks resolve the vast majority of spool-related issues without needing deeper intervention.