The Real Definition Nobody Gives You
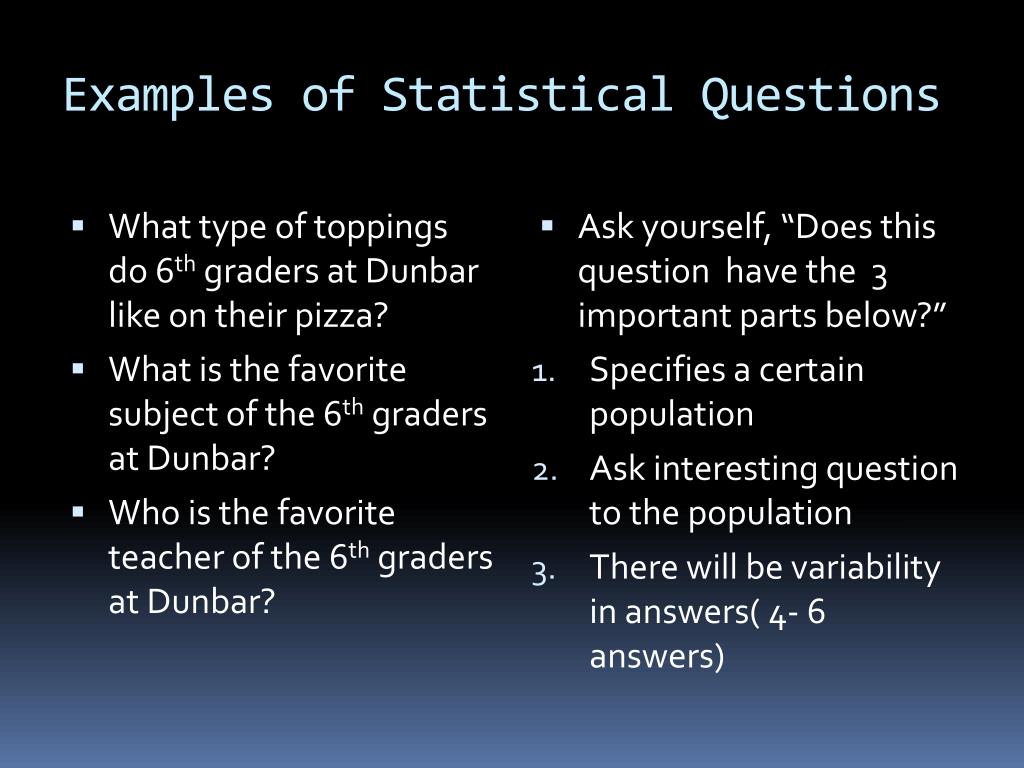
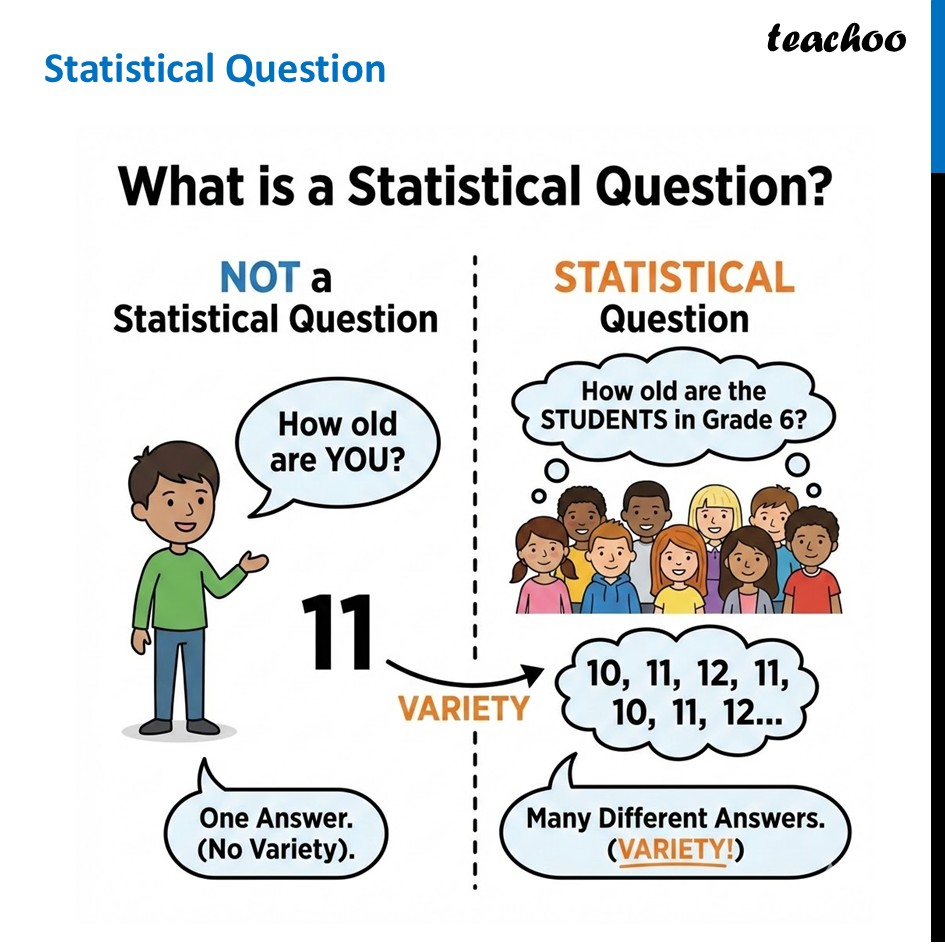
A statistical question is one where the answer depends on collecting data that varies. That's it. The core requirement is variability in the population you're measuring. If every member of your target group would give the same answer, you have a non-statistical question, even if you need to ask people to find out what that answer is. Here's the practical way to check. Before you design a study, ask yourself: if I measured five random individuals, would I expect five different answers? If yes, you're dealing with a statistical question. If no, you're not. The variability has to be real and measurable, not theoretical. I spent three years teaching this concept in high school statistics courses, and the single biggest confusion point is that people think any question requiring data collection is statistical. It's not. "What is the capital of France?" requires data collection if you're uncertain, but there's no variability in the answer. It's a factual question, not a statistical one.
What Is A Statistical Question
The formal definition, the one that actually works in practice, is this: a question that anticipates variability in the data collected related to the question and accounts for it in the analysis. Notice the word "anticipates." That's the part that matters most. You need to expect variation before you start. If your research design doesn't account for variability, you're not doing statistics, you're just doing measurement. Consider two examples that look identical on the surface but are fundamentally different. "How old is the average employee at Company X?" is non-statistical. There is one true average age, a single number derived from the complete workforce. You calculate it, you get a result. "How old are employees at Company X?" is statistical because you're describing a distribution. The variability in ages is the entire point of the question.
The distinction becomes critical when you're writing a methods section for a research paper or designing a survey instrument. Reviewers will specifically look for whether you framed your research questions as statistical and whether your analysis plan actually accounts for the variability those questions imply. A non-statistical question analyzed with confidence intervals looks like you don't understand the difference.
Get the Full Details

Edge Cases Where This Gets Messy
I ran into a situation a few years ago that still comes up in my work. We were studying customer satisfaction scores across a chain of retail locations. Someone framed the question as "What is the average satisfaction score?" and expected me to treat it as non-statistical because we had complete population data from every store. The average was a fixed number. We weren't sampling. The problem is that the question implicitly asked about variability in satisfaction patterns across locations. Even with a complete census, the distribution of scores matters. If location A consistently scores 4.5 and location B consistently scores 2.3, the average alone hides the actual pattern. I reframed the question to explicitly ask about the distribution of scores and used a variance decomposition to separate within-location variability from between-location variability. The original framing was wrong for the analysis needed. Another common trap appears in time series data. Questions like "What will next month's sales be?" look predictive rather than statistical. But they are statistical because they involve forecasting with uncertainty. The variability comes from the model error terms and the inherent randomness in future observations. Ignoring that variability by giving a point forecast without a prediction interval is a mistake that costs people their credibility.
How to Design Around Statistical Questions
The practical workflow is straightforward. First, write your question so that it explicitly requires variability. Then determine what type of variability matters. Is it between subjects? Between groups? Over time? Within a single measurement? For between-subject variability, you need random sampling or random assignment. For between-group variability, you need distinct groups with meaningful differences. For temporal variability, you need repeated measurements across time periods. Each type demands a different analytical approach. Sample size calculations follow directly from the question type. If your question is about estimating a mean with a specific margin of error, you calculate n based on the expected standard deviation. If your question is about comparing two proportions, you calculate n based on the expected effect size and variability in each group. The question determines the calculation, not the other way around.
I use a simple template to avoid mistakes. Before starting any project, I write: "I am asking a statistical question about [parameter] in [population] with expected variability described by [distribution assumption]. My analysis will account for this variability by [method]." If I can't fill in any part of that template, the question isn't ready to be framed statistically.

Common Pitfalls in Practice
The most frequent error I see is conflating the variability in your data with the variability in your parameter estimate. These are not the same thing. Your sample data has spread. Your estimate of the population parameter has a standard error. Treating them as interchangeable leads to incorrect confidence intervals and wrong conclusions about precision. Another pitfall involves dichotomous data. When your variable is binary, like yes or no responses, the variability is constrained. The standard deviation equals sqrt(p times 1-p), where p is the proportion. You don't need to estimate variability separately. Many analysts waste time computing descriptive statistics for binary data when the variance is completely determined by the proportion itself. There's also the issue of ecological fallacy. Aggregate-level variability does not tell you about individual-level variability. A city might show high variability in income levels, but that says nothing about how much an individual person's income varies over time. Questions framed at one level of analysis cannot reliably answer questions at another level.
Limitations You Should Know About
Statistical questions are only useful when the underlying data exists and is measurable. You can frame any question as statistical, but if you cannot observe the relevant variability, the question is unanswerable regardless of your analytical technique. I've seen teams spend weeks designing elaborate sampling plans for questions where the variability they needed simply didn't exist in any accessible data source. Another limitation is that statistical questions do not tell you which question to ask. They only tell you what kind of question you can answer with data. Deciding whether a question is important, interesting, or worth answering requires domain expertise that statistics alone cannot provide. The method handles variability. It does not handle significance. Finally, there is a boundary condition where statistical questions become impractical. When the cost of observing enough variability exceeds the value of the information gained, you need to shift to a different approach. Causal inference methods, simulation studies, or sensitivity analyses may be more appropriate than trying to collect ever-larger samples to answer the same question.