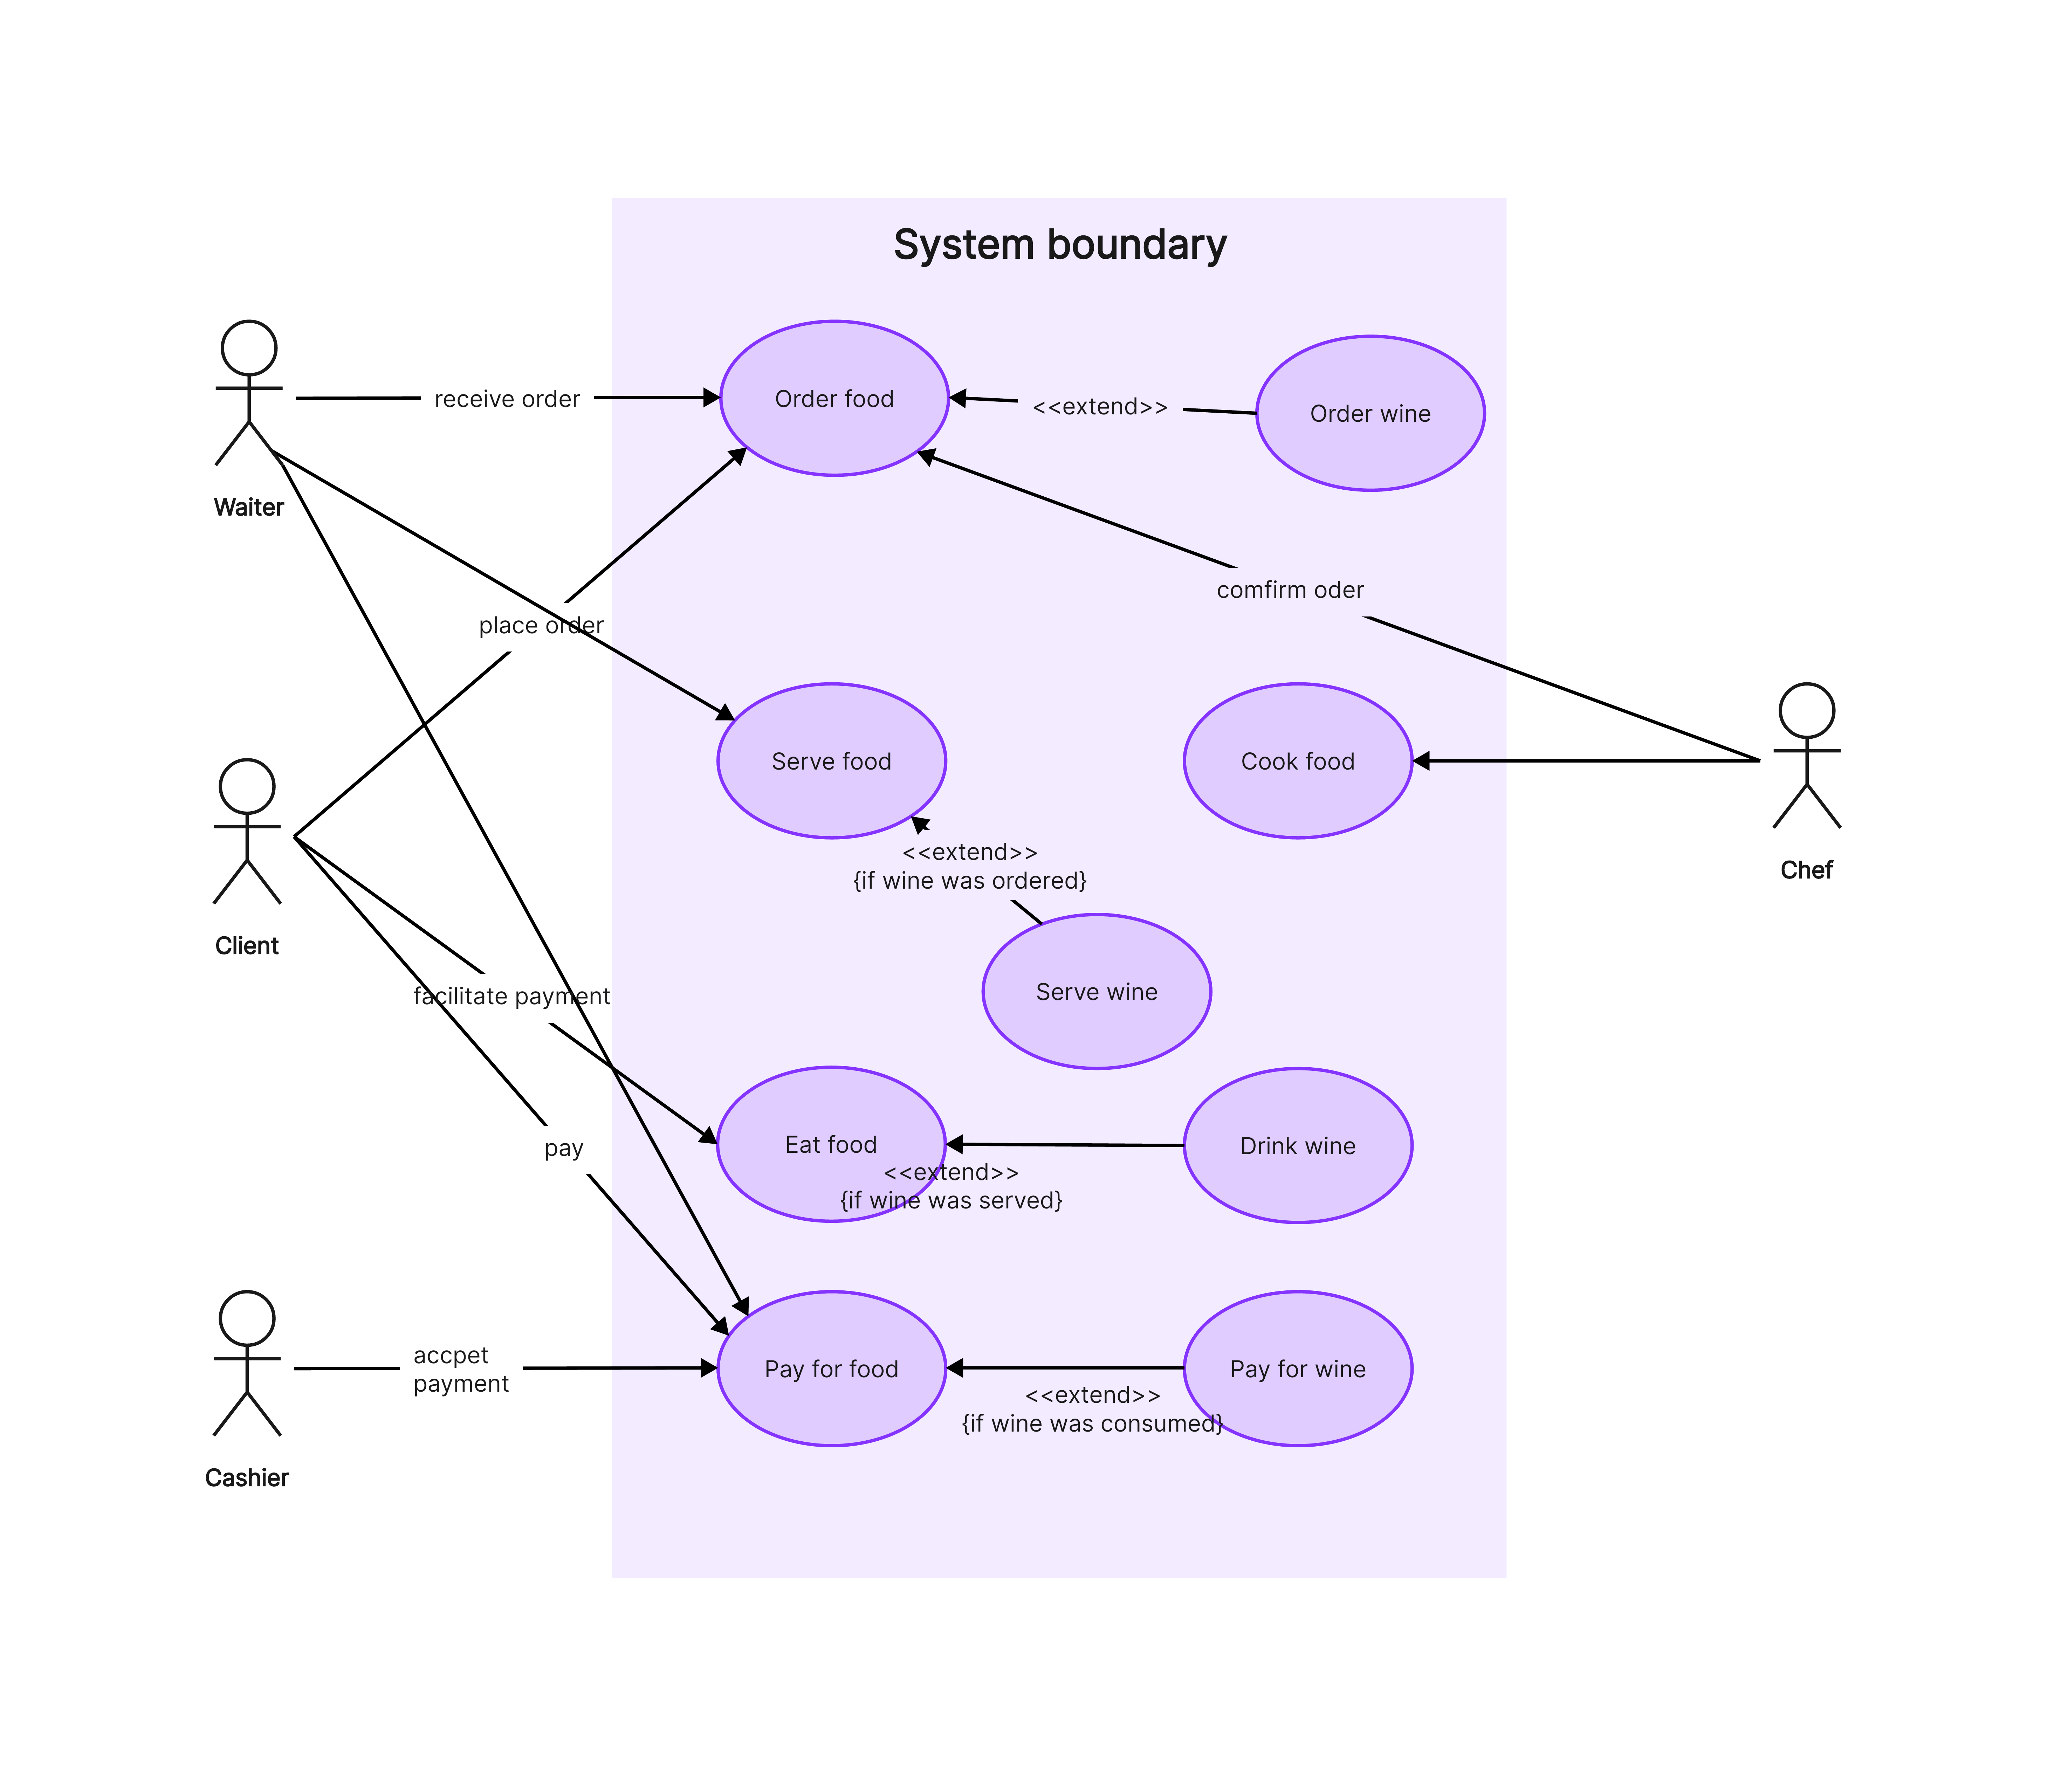
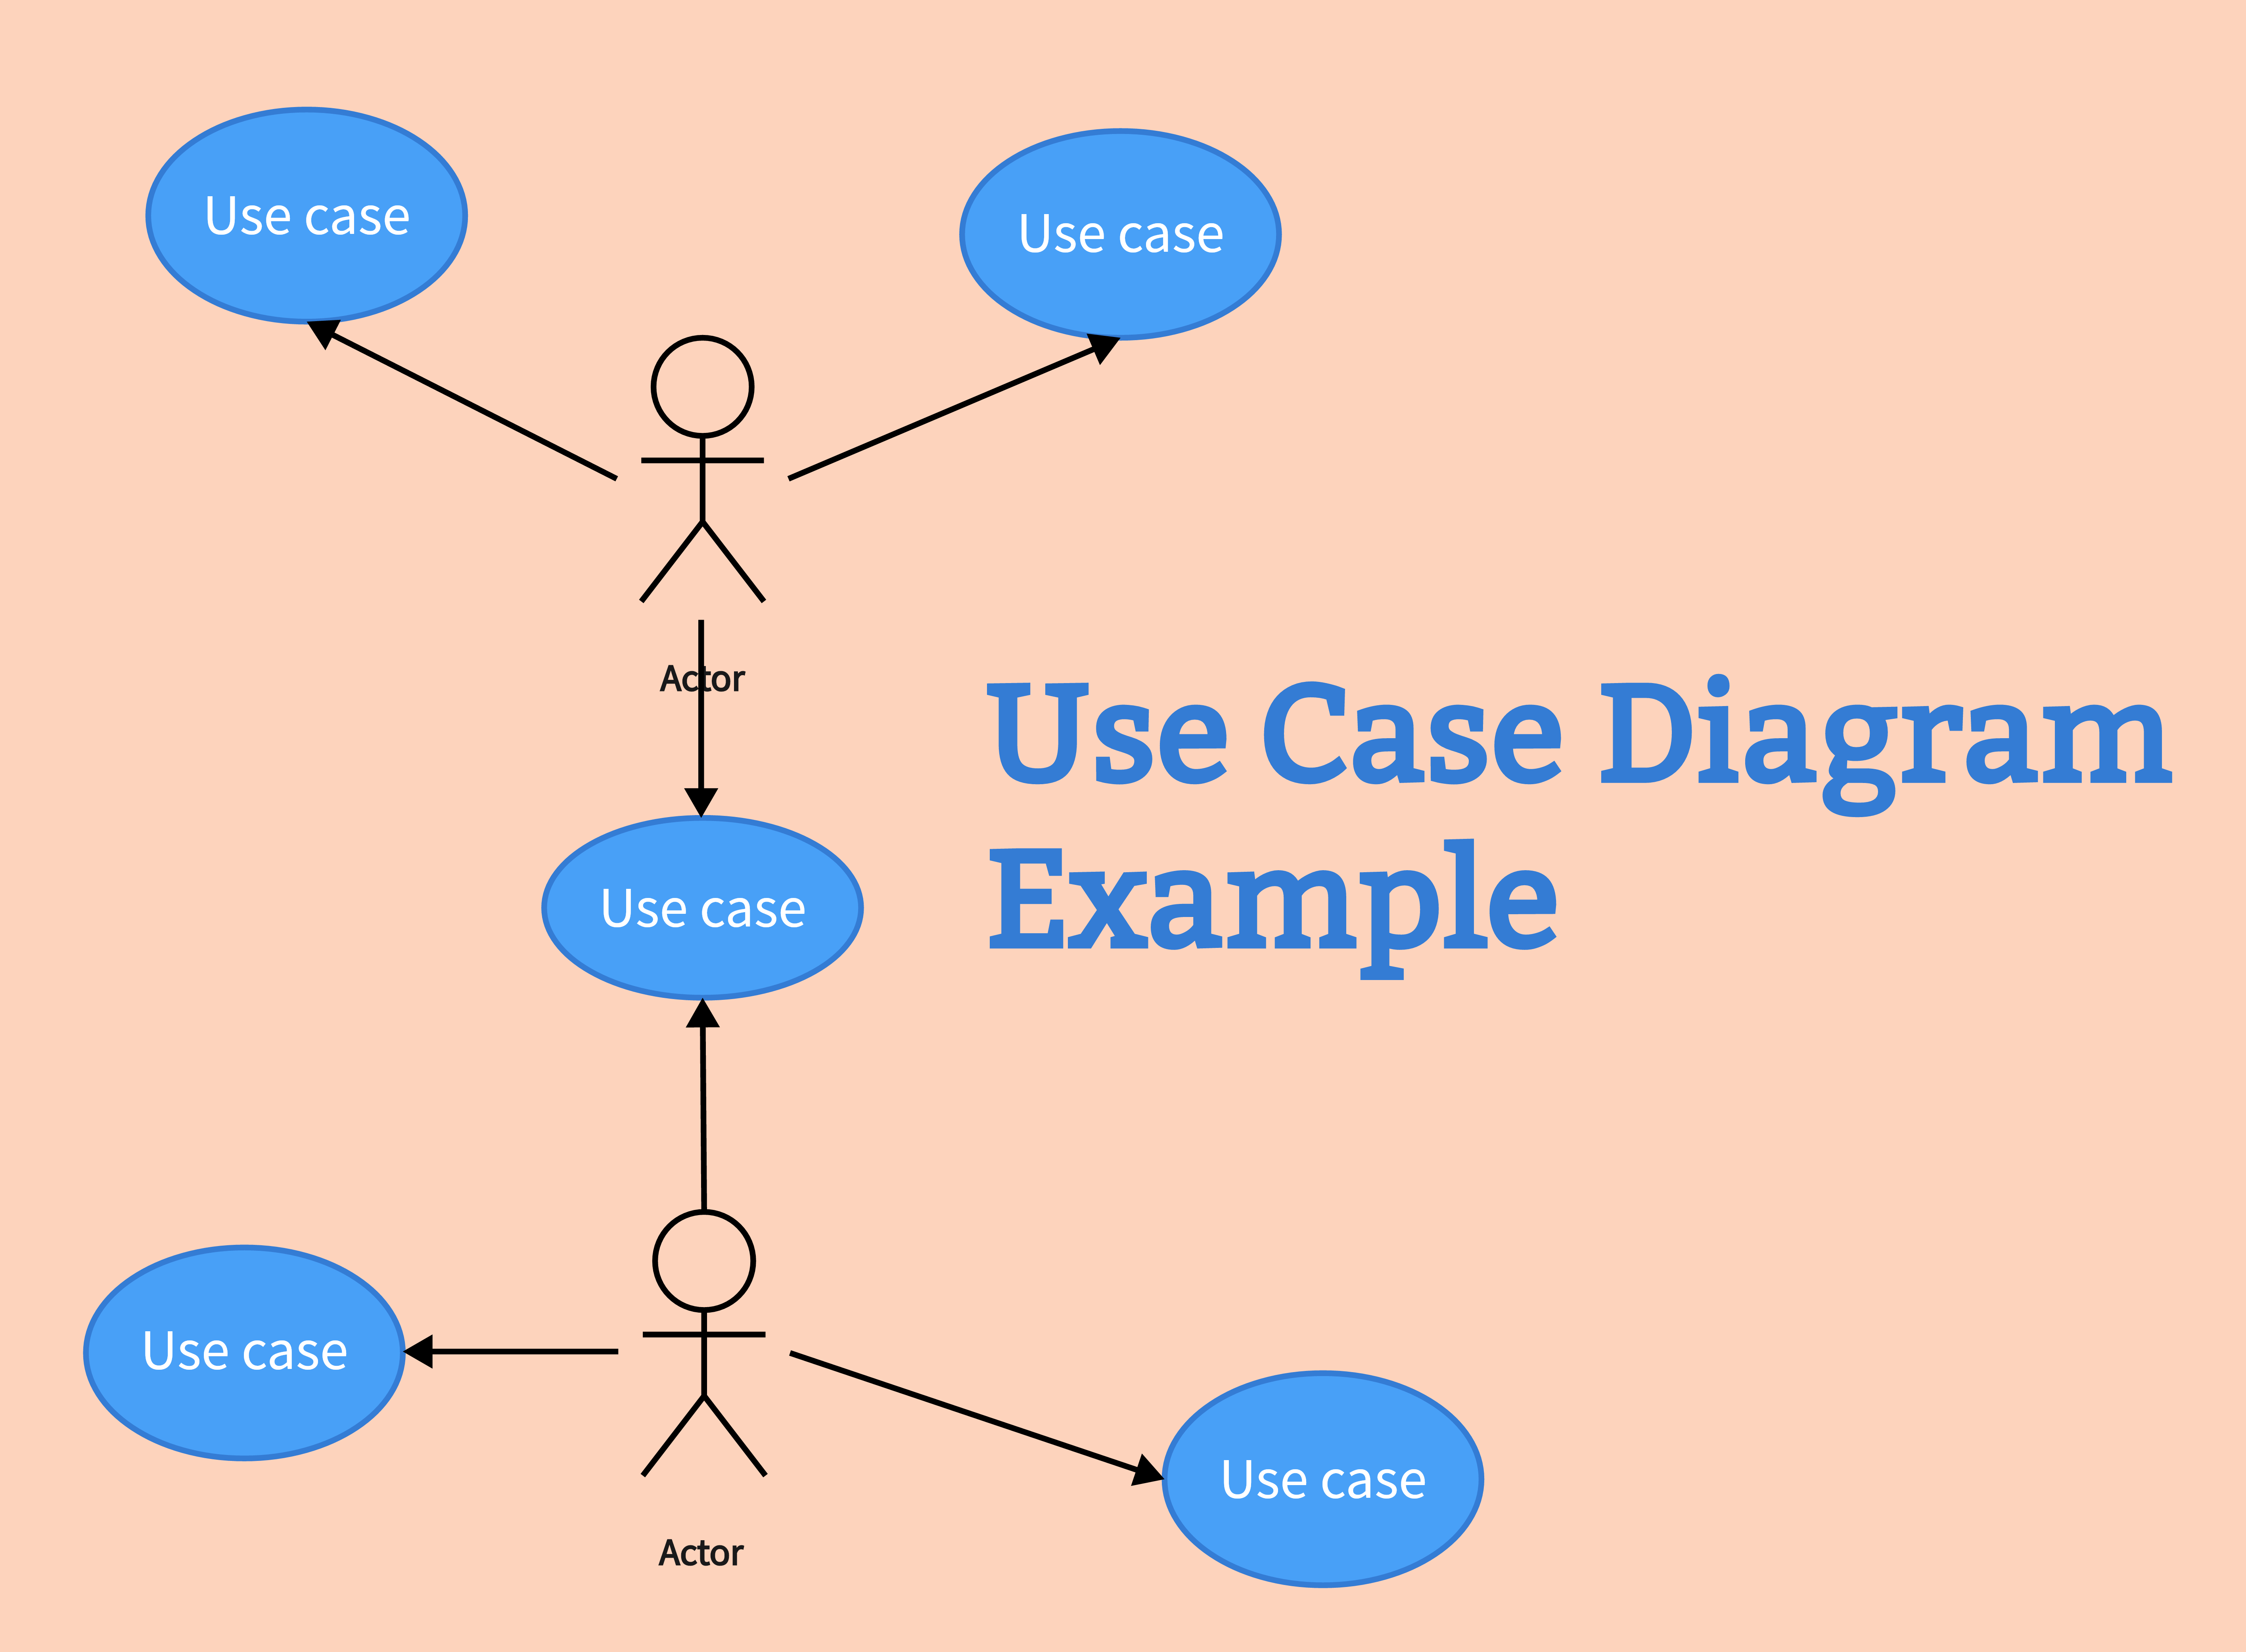
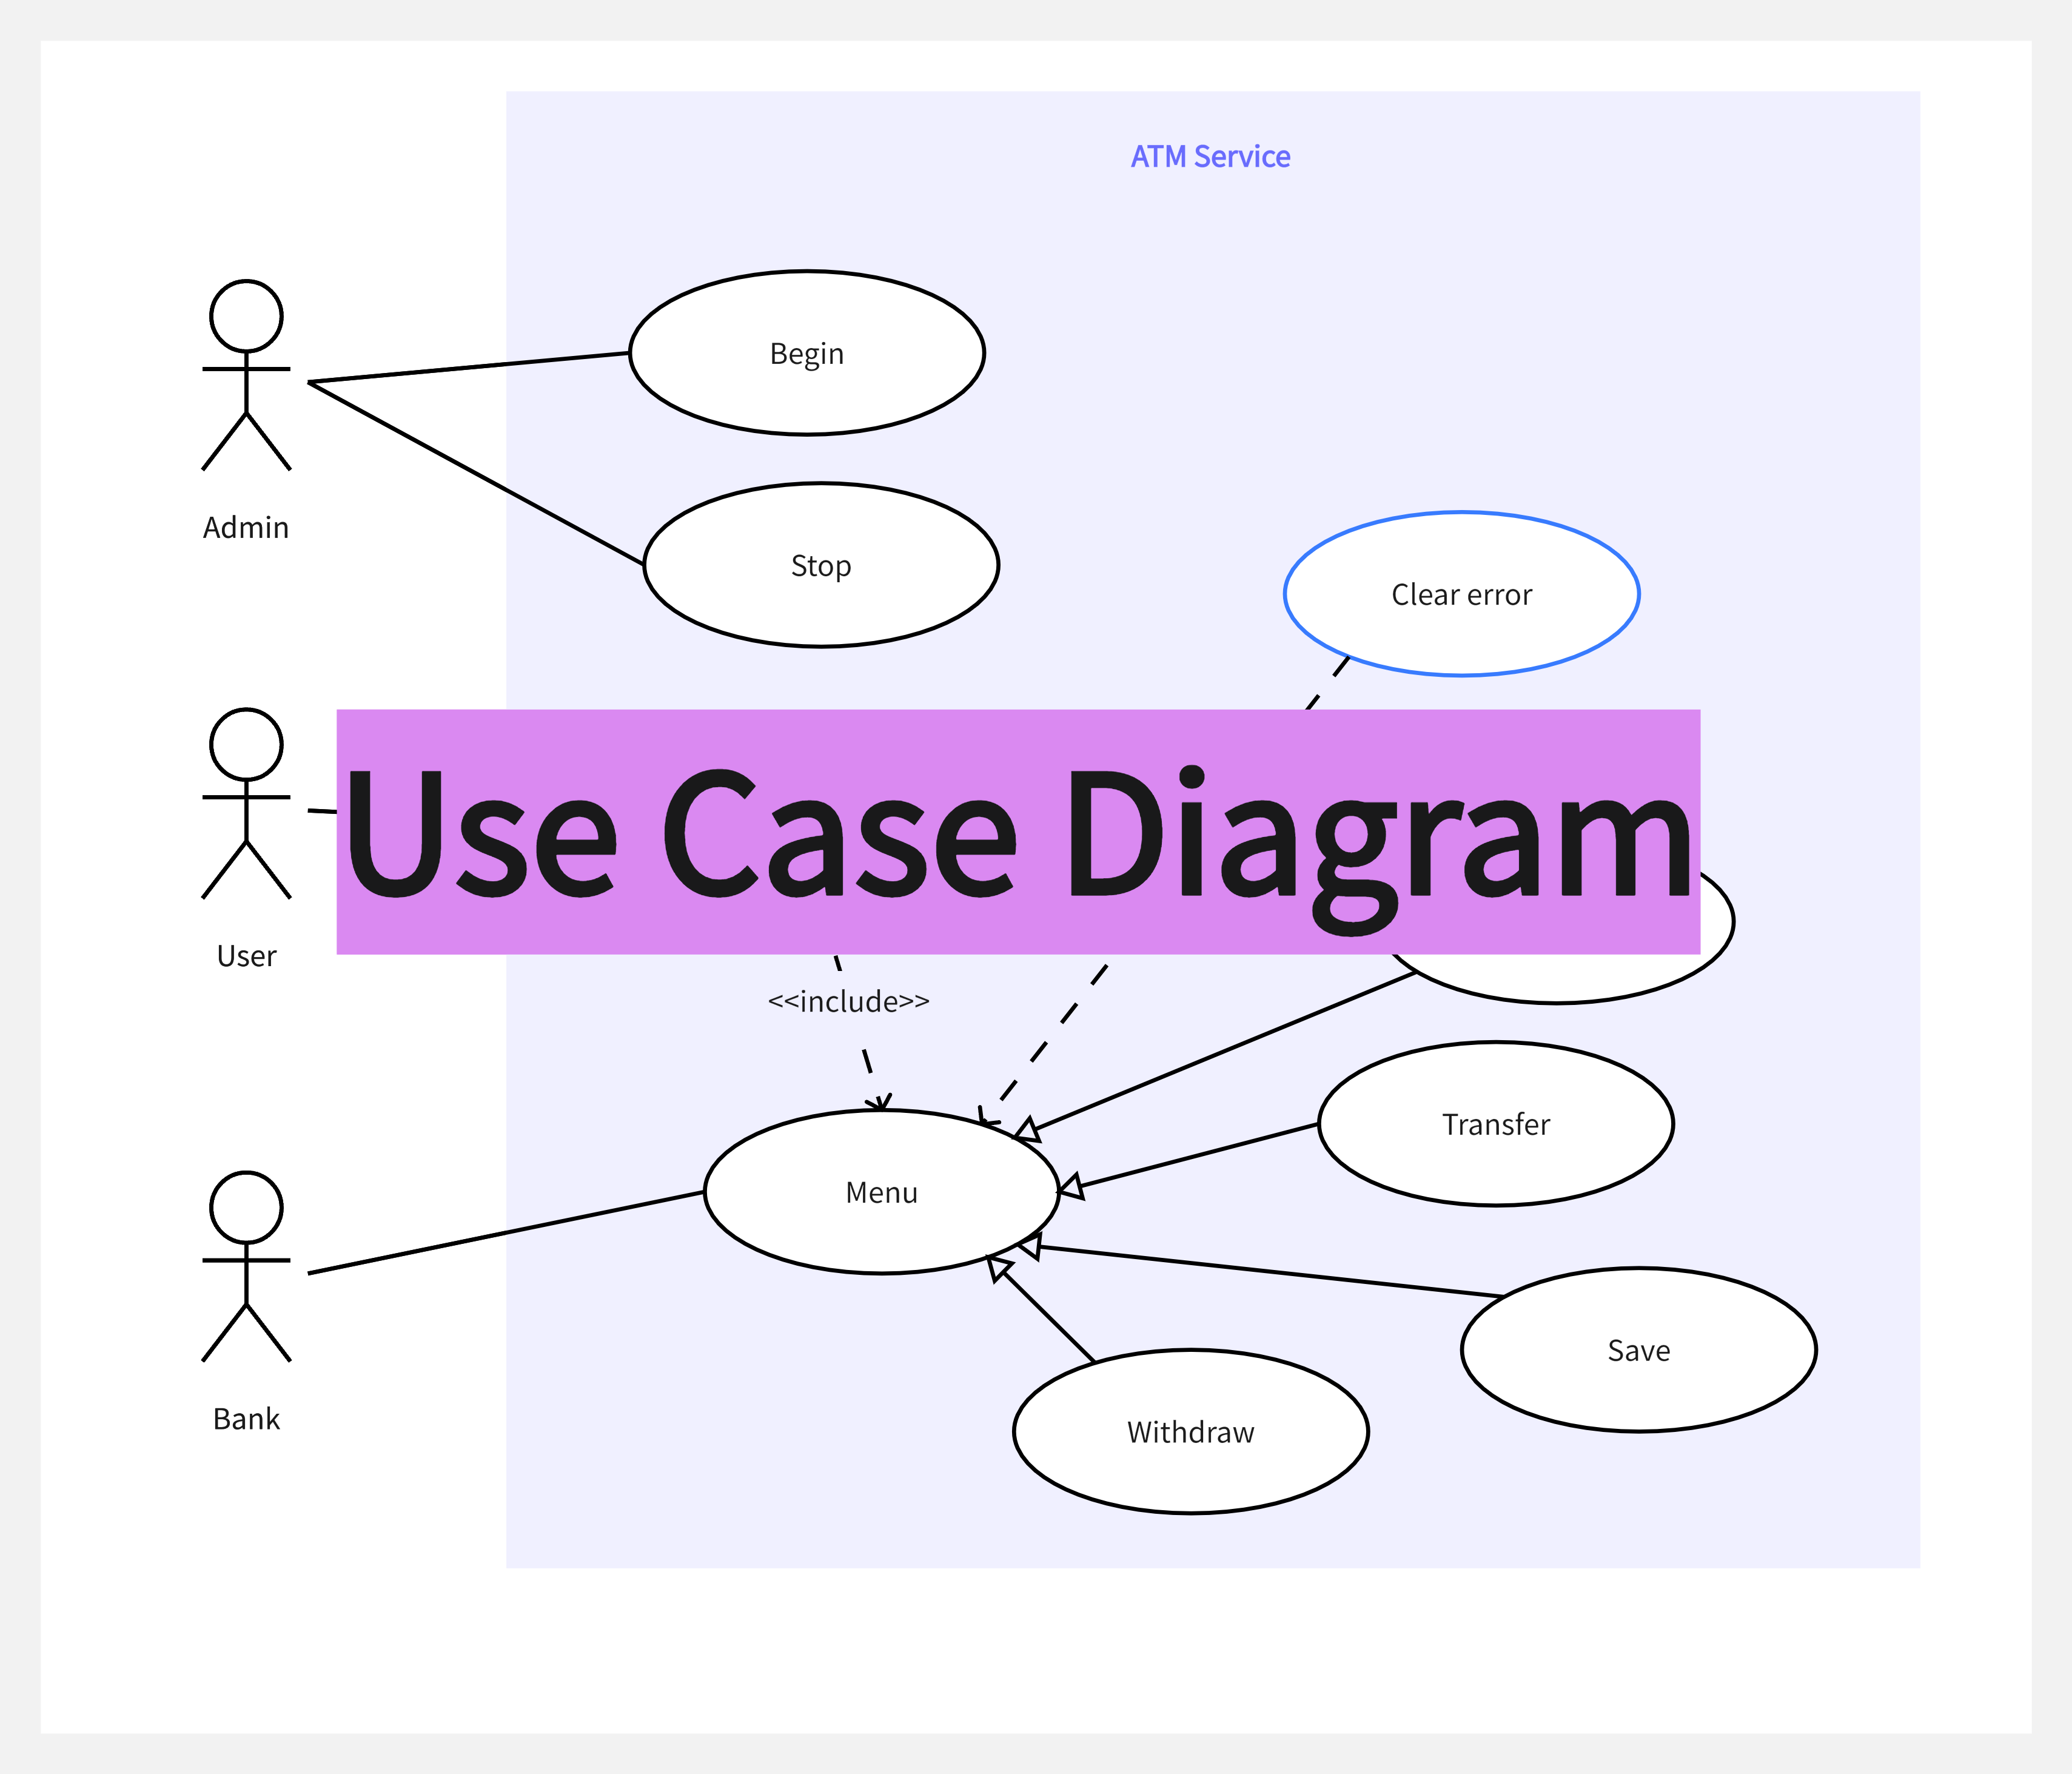
Use cases are the bridge between what stakeholders say they want and what engineers actually ship.
I've spent more years than I want to count watching teams either skip them entirely or produce these sprawling twenty-page documents nobody reads after the kickoff meeting. The version that actually works is far simpler. It's a structured description of how a single actor interacts with a system to accomplish one specific goal. That's it. No ceremony attached. At its core, a use case captures a discrete scenario. You identify an actor, which is any external entity that interacts with the system, and then you describe the step-by-step sequence that leads from that actor initiating an action to the system delivering a result. The standard construct includes the use case name, the primary actor, a brief purpose statement, preconditions that must hold before the scenario starts, the main success flow, alternative flows for deviations, and postconditions describing the system state once the scenario completes. The template has been around since the UML spec landed in the late nineties, and honestly it hasn't changed meaningfully since then. That's not because the template is perfect, it's because the underlying problem hasn't changed. You need a way to communicate behavioral requirements without drifting into vague stakeholder language or diving straight into database schemas. Use cases sit in that middle ground.
I remember working on a healthcare platform where the initial use case document for the patient registration flow was about forty pages long. Every edge case, every validation rule, every permission check was documented as its own separate alternate flow. The engineering team spent three weeks reading it and still ended up building something different from what the product team expected. What happened is that the alternate flows collided. One flow described a scenario where the patient had no insurance, another covered the case where the insurance card was missing, and a third handled the situation where the insurance provider was unknown. Taken individually they were fine. Together they created contradictory branches that none of the developers could reconcile during implementation. The fix was straightforward but nobody wanted to do it at first. I restructured the entire registration use case into a single main success flow covering the happy path and consolidated all the variations into a separate decision table. The main success flow dropped to twelve steps. The decision table captured the insurance logic in a grid format that matched the actual implementation. The team finished reading it in an afternoon instead of three weeks, and the resulting code was closer to what everyone actually needed. It wasn't a perfect translation but it was close enough that rework dropped from about four hundred bug tickets to roughly forty during QA. Here's the thing most people miss when they're writing their first few use cases. The main success flow should describe what happens when everything goes right, not what the system does under normal conditions. There's a difference. "Normal conditions" implies typical user behavior and reasonable data. "Everything goes right" means the input is well-formed, all validations pass, all external services respond successfully, and the actor completes the action without interruption. If you conflate those two, your use case becomes a description of average behavior rather than a specification of success, and you lose the ability to reason about what failure looks like.
Another thing that trips people up is the distinction between an actor and a role. An actor is anything outside the system boundary that interacts with it. It can be a human, another system, a hardware device, a scheduled trigger. A role is the function that actor plays within a specific use case. The same human can be multiple actors across different use cases and can play different roles within the same one. I've seen teams collapse all actors for a given user type into a single actor definition and then wonder why the authorization logic became impossible to implement without conditional branches that looked like spaghetti. Preconditions matter more than people realize. They're not just bureaucratic checkboxes. A precondition defines the exact state the system must be in before the scenario can begin. If you get this wrong, your test cases will fail for reasons that have nothing to do with the actual logic you wrote. In practice I've found that the most useful preconditions are the ones that are false more often than you'd expect. Things like "the user account is active and not suspended" or "the payment method has not expired." Those get overlooked during development and cause the most expensive failures later. Postconditions are the flip side. They describe what must be true after the scenario completes, regardless of whether it succeeded or failed through an alternate flow. A lot of teams skip this section entirely. When they do, they end up with incomplete cleanup logic. I once worked on a batch processing system where the main success flow completed but left orphaned records in a staging table because nobody had written a postcondition for that scenario. The alternate flow for a validation failure did include cleanup, which meant successful runs leaked data while failed runs were properly handled. Asymmetric postconditions like that are a recipe for data corruption over time.
Get the Full Details

Now let me address the part about alternatives, because this is where things get practical. Not every interaction needs a use case. I've seen teams try to document every possible button click in the system as a separate use case. That approach produces hundreds of trivially thin use cases that add almost nothing to understanding and actually make the documentation harder to navigate. The rule of thumb I've settled on is that a use case is worth writing when the interaction involves at least two steps, has at least one meaningful alternative flow, and the outcome affects something outside the immediate screen or component. If it's a single button click with no state change and no branching logic, you don't need a use case. A comment in the code is sufficient. There's also a question about granularity that doesn't get discussed enough. Should you write one high-level use case that covers a whole business process, or many fine-grained ones that each cover a small interaction? The answer depends on who's going to read them and what you're trying to achieve. If you're writing for product managers and business analysts, a higher level of abstraction tends to work better because they care about outcomes, not implementation details. If you're writing for engineers who need to implement the logic, finer granularity is usually more useful. The hybrid approach that I've found most effective is to write the main success flow at a higher level and expand the alternate flows at a lower level. This keeps the document readable while still providing enough detail for implementation. The biggest limitation of use cases is that they capture behavior in isolation. They don't model the sequence of use cases that an actor performs over time, and they don't represent the data relationships between different scenarios. If your system has complex state machines or deeply interconnected business processes, use cases alone will leave you with gaps. In those situations I supplement them with state diagrams for the object lifecycle and sequence diagrams for the cross-cutting interactions. Neither of those replaces use cases. They complement them. Use cases tell you what happens in a single scenario. State diagrams tell you what states an object can be in. Sequence diagrams tell you how objects communicate. Using all three gives you coverage that no single artifact can provide.
Another honest limitation is that use cases don't scale well to Agile workflows where requirements change every two weeks. The traditional idea of a use case document as a living artifact that gets updated continuously tends to break down in practice. What I've done instead is treat individual use cases as just-in-time artifacts. I write or update them right before the sprint in which the corresponding functionality will be built. The documentation effort is small enough that it doesn't become a bottleneck, and it's fresh enough that it's actually useful. After the sprint, if the requirements shift again, the use case either gets discarded or rewritten for the next relevant sprint. This is not the textbook approach, but it's what actually works in a fast-moving environment. The core insight that I keep coming back to is that a use case is a tool for communication, not a deliverable for approval. The value isn't in having a document that passes a review gate. The value is in having a shared mental model between the people who describe what the system should do and the people who build it. If the use case achieves that, it's doing its job. If it becomes a artifact that exists solely to satisfy a process requirement, it's added overhead with no real benefit. When you're starting out with this, the most practical approach is to pick one non-trivial feature of your system and write a single use case for it using the structure I described. Keep the main success flow to no more than ten steps. If you find yourself writing more, you're probably describing multiple scenarios in one instead of one scenario in detail. Write out the preconditions carefully. Define the postconditions. Then draft one or two realistic alternate flows that cover the failure modes you've actually seen in your domain. That's a complete use case. Anything beyond that is usually documentation for its own sake rather than documentation that serves a purpose.