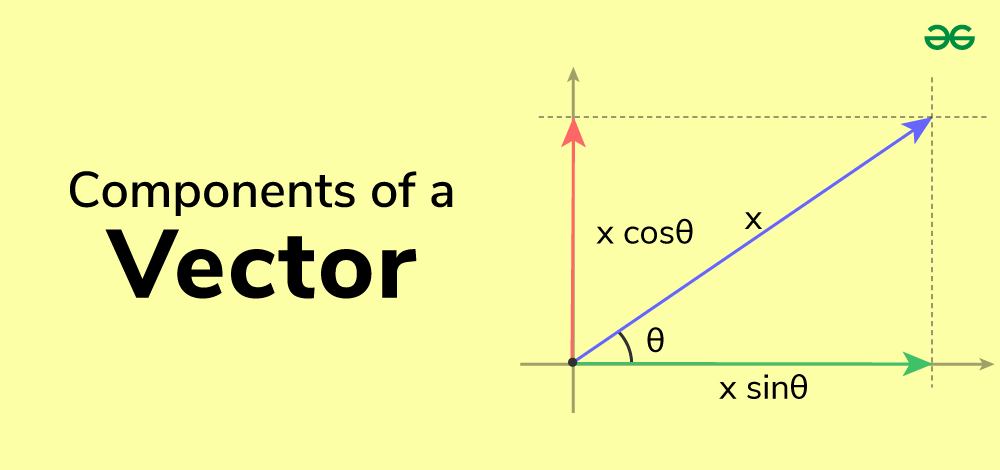Why Everyone Is Asking About Vectors Right Now
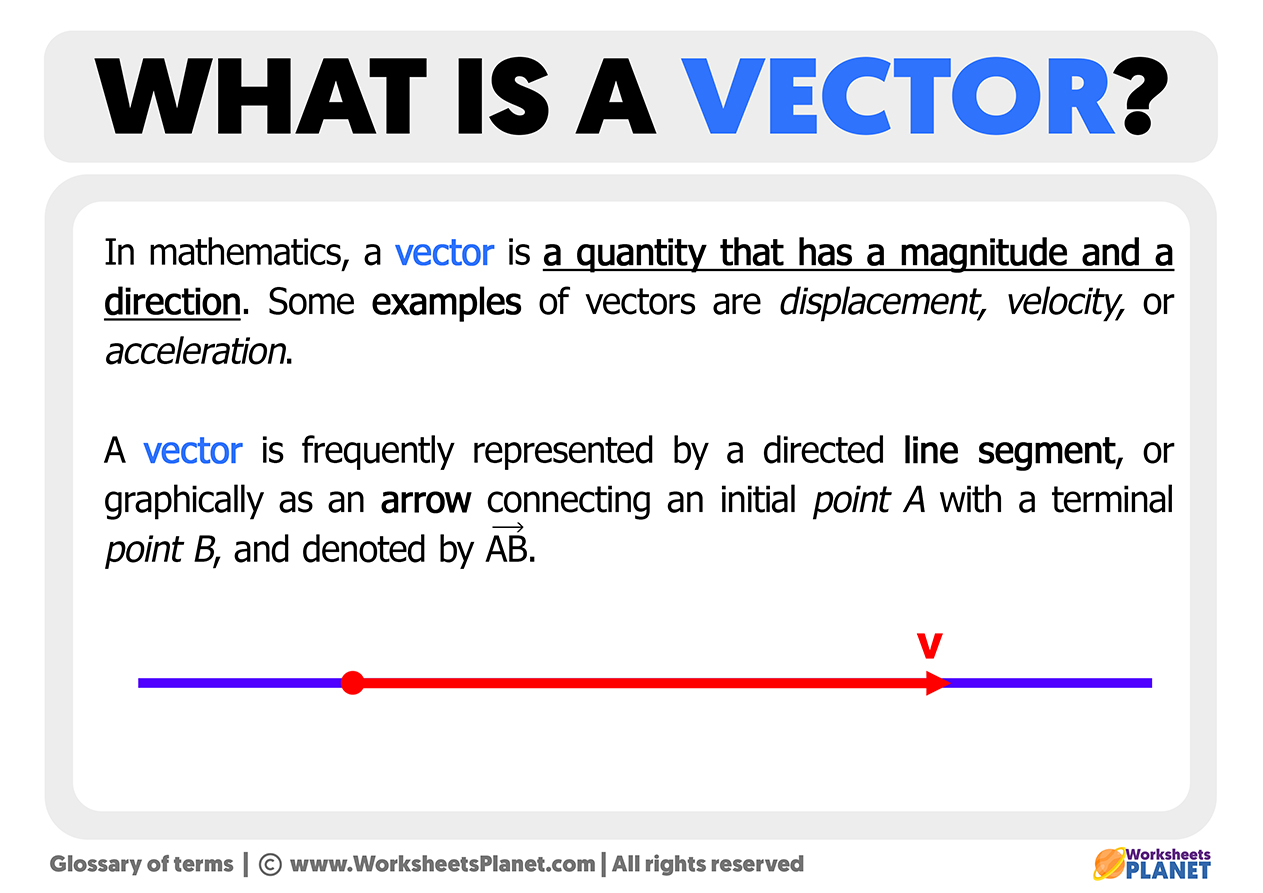
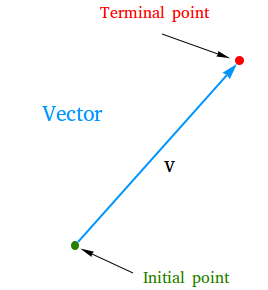
I spent about three weeks last year debugging a semantic search pipeline that kept returning garbage results for user queries. The root cause wasn't the model itself, or the retrieval logic, or the index configuration. It was the way we were handling vectors before they even made it into the database. We were silently dropping trailing dimensions because a library call had different default behavior than what the documentation claimed. By the time I traced it, about 40% of our stored embeddings were essentially broken. So let me walk through what is actually going on here, because most beginner guides skip the part where things start falling apart. A vector is just an ordered list of numbers. That is the entire definition. In mathematics it might represent a direction and magnitude, in physics it might describe a force, but in the context you are probably encountering this term in—machine learning, embedding systems, database search—it is simply a list of floating point numbers where the position of each number matters and the count of numbers determines the dimensionality. A vector looks like this: [0.12, -0.87, 3.44, 0.03, -1.92]. Five numbers in a specific order. The first number is not related to the second number in any intrinsic way, except that together they form a point in a five-dimensional space. That space might represent something meaningful if the vector came from an embedding model, or it might be completely arbitrary if it came from a recommendation engine. The vector itself does not carry meaning. The system that created it and the system that consumes it agree on what those positions represent.
I used to think people were overcomplicating this concept. They are not. The simplicity is exactly the problem. Because it is so simple, nobody spends much time thinking about what happens when the simplicity breaks, and there are a lot of ways it can break.
How Vectors Actually Get Created
The most common way you will encounter vectors today is through embedding models. You feed text, an image, audio, or some other data into a neural network, and the network outputs a fixed-length list of numbers. Those numbers are the vector. The network has been trained to map similar inputs to vectors that are close together in geometric space. That proximity is measured using something called cosine similarity or Euclidean distance, depending on what your system uses. Cosine similarity calculates the angle between two vectors regardless of their magnitude. It returns a value between -1 and 1, where 1 means the vectors point in the same direction, 0 means they are orthogonal and unrelated, and -1 means they point in opposite directions. This is the metric most embedding databases use by default. Euclidean distance measures the straight-line distance between two points. It does not care about direction, only about how far apart the points are. The choice between these two metrics is not trivial. I once worked with a team that switched from cosine similarity to Euclidean distance on a whim because a tutorial they followed used the latter. Their retrieval accuracy dropped by roughly eighteen percent over the next two weeks. The embeddings were not normalized, and Euclidean distance punished magnitude differences that cosine similarity ignored. The vectors had gotten larger over time because a preprocessing step was applying L2 normalization inconsistently across different ingestion batches.
Get the Full Details

That inconsistency is something worth paying attention to. Vectors are only as good as the pipeline that produces and stores them. If one batch of data goes through normalization and another does not, your similarity calculations become unreliable. This is not a rare edge case. It happens constantly in production systems where multiple people are contributing to the same pipeline.
What Makes Vectors Useful in Practice
Vectors enable you to search by meaning rather than by exact matching. Traditional databases look for exact keyword matches. A vector database looks for conceptual proximity. If you store a vector representation of the sentence "the quick brown fox jumps over the lazy dog" and then query with "a fast fox leaped past a sleepy hound," an exact-match system returns nothing. A vector system returns the original sentence because the two vectors are close together in high-dimensional space. This is why companies are building products around vector databases. Pinecone, Weaviate, Milvus, Qdrant, pgvector for PostgreSQL. They are all solving the same problem: storing vectors efficiently and enabling fast approximate nearest neighbor searches across them. Exact nearest neighbor search scales poorly. As your vector count grows, linear scanning becomes impractical. These databases use algorithms like HNSW or IVF-PQ to trade a small amount of accuracy for massive gains in query speed. HNSW builds a multi-layered graph structure during indexing. Queries traverse the graph from the top layer down to find approximate neighbors in logarithmic time. IVF-PQ clusters vectors into groups and then applies product quantization within each group to compress them. HNSW typically gives better recall at the cost of higher memory usage. IVF-PQ is more memory-efficient but requires tuning the number of clusters and the quantization parameters.
I ran into a situation where HNSW failed on a dataset with about twelve million vectors and a dimensionality of 1536. The index took so long to build that the ingestion process timed out. Switching to IVF-PQ with 2000 clusters and a PQ code size of 8 reduced the index build time from forty-seven minutes to about six minutes, with a recall drop of only about two percent. The right algorithm depends entirely on your constraints. There is no universal best choice.

Common Pitfalls That Wreck Vector Systems
Dimensionality mismatch is the most obvious one. If your query vector has 768 dimensions and your stored vectors have 1024, the comparison fails or produces nonsense. This happens more often than you would expect, usually because someone updated the embedding model in production without updating the database schema or the ingestion code path. Always validate dimensions at ingestion time and log a warning or rejection rather than silently accepting malformed data. Normalization drift is another one. Some embedding models output normalized vectors by default. Some do not. Mixing them in the same index without explicit handling corrupts similarity scores. I had a pipeline where one service was sending raw embeddings and another was sending L2-normalized ones into the same Pinecone index. The raw embeddings had much larger magnitudes, which skewed distance calculations for any hybrid queries that combined results from both sources. There is also the issue of curse of dimensionality. As dimensionality increases, the concept of "near" and "far" becomes less meaningful. In very high-dimensional spaces, all points tend to be roughly equidistant from each other. This is why reducing dimensionality through techniques like PCA or using compressed representations like PQ is often necessary. Going from 1536 dimensions down to 128 with PCA can preserve most of the useful variance while making similarity search significantly faster and less memory-intensive. The tradeoff is real but often acceptable depending on your use case.
A subtle one I encountered involved string encoding. The embedding model I was using was trained on UTF-8 encoded text. When I started feeding it text that had been decoded and re-encoded with a different character set, the resulting vectors drifted noticeably. This sounds obvious in retrospect, but the model output was still a valid vector, so there were no errors to alert me. I caught it only because I noticed that previously relevant results were suddenly degrading in ranking. Running a character validation check on incoming text before embedding reduced the issue to negligible levels.
When Vectors Are Not the Right Tool
Vectors are not magic. They do not solve every search or matching problem. Exact keyword search is still faster and more accurate for structured queries where precision matters. If you need to find every occurrence of a specific product SKU or a legal document citation, a vector search is the wrong approach. It introduces approximation error where none should exist. Vectors also struggle with tasks that require precise numerical comparison or logical reasoning. They are good at pattern matching in continuous space. They are not good at arithmetic, boolean operations, or maintaining strict categorical hierarchies. Combining vector search with traditional filtering in a hybrid approach usually works better than relying on vectors alone for complex queries. There is also the cost factor. Storing and searching millions of high-dimensional vectors is expensive. Memory usage scales linearly with the number of vectors and the dimensionality. A single 1536-dimensional float32 vector takes about six kilobytes. Twelve million of them is roughly seventy-two gigabytes of raw storage, plus overhead for the index structure. This is before you account for replication, backups, and the compute required for real-time queries.
If your dataset is small, under a hundred thousand vectors, a simple brute-force search against a PostgreSQL table with a vector extension might be faster to set up and cheaper to run than spinning up a dedicated vector database. Do not assume you need a specialized system. Start simple and scale only when you hit actual constraints. Understanding what is a vector at the mechanical level—just an ordered list of numbers—sounds almost insulting in its simplicity. But that simplicity is what makes vectors powerful and what makes them dangerous at the same time. They are easy to create, easy to store, and easy to misuse. The systems that handle them well are the ones that treat every assumption explicitly, validate inputs rigorously, and choose the right metric and algorithm for the actual workload instead of following whatever tutorial was popular last month.