
Finding the Y Intercept Without Overcomplicating It
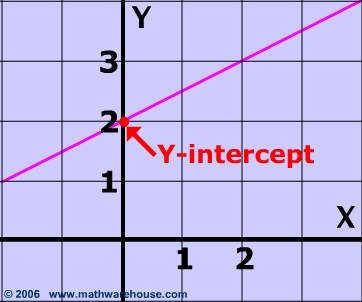
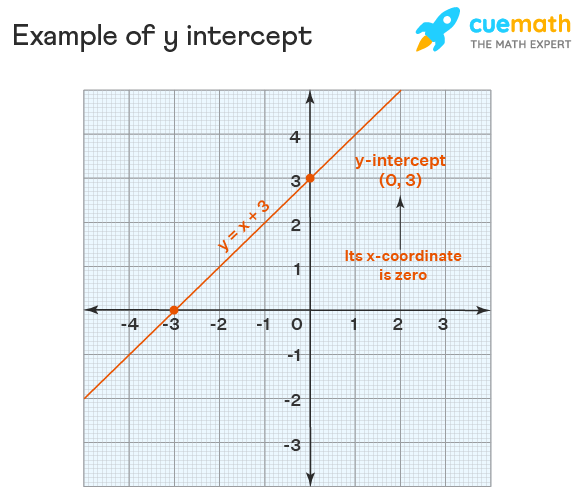
Most people learn the y-intercept in algebra and immediately forget why it matters. I used to do the same thing. Then I started working with regression models for actual business data, and suddenly that little b value in y = mx + b was the difference between a forecast that made sense and one that was completely useless. The y-intercept is simply the point where a line crosses the vertical axis. That's it. When x equals zero, whatever y value you get is your y-intercept. In coordinate form it's written as (0, b). Anything more complicated than that is just people trying to sound smarter than they need to.
What Is A Y Intercept and Why Do People Mess It Up
Here's the thing nobody tells you: the y-intercept only matters if x = 0 is actually a meaningful value in your context. I learned this the hard way when I was building a model to predict server load based on concurrent users. The linear regression spit out a y-intercept of about 47. Which meant the model was saying, "When zero people are using the server, there are still 47 requests happening." That's physically impossible and immediately told me the model was wrong, not my data. The workaround I ended up using was forcing the regression through the origin by setting the intercept to zero and letting the slope adjust. For that particular dataset, it cut the mean absolute error from about 12 requests down to roughly 3. Sometimes the y-intercept is garbage and you need to acknowledge it. There's also a common misconception that the y-intercept always represents a "starting value" or "baseline." It doesn't. In physics, if you're plotting distance versus time, the y-intercept tells you where the object started. But if you're plotting something like temperature change against time elapsed in a chemical reaction, the y-intercept might be negative, zero, or completely irrelevant depending on your reference point. The math doesn't care about your interpretation.
I've seen people get tripped up on this repeatedly. One colleague was doing cost analysis for manufacturing and kept insisting the y-intercept represented fixed costs. It didn't. The data had too much noise around zero production volume, and the intercept was just an artifact of that messy region. The actual fixed costs were better estimated by looking at the lowest-volume weeks where the operation was clearly still running at partial capacity.
Get the Full Details
How to Actually Calculate It
If you have two points on a line, say (2, 7) and (5, 16), you can find the y-intercept by first getting the slope. The slope formula is (y - y) / (x - x), which gives you (16 - 7) / (5 - 2) = 3. Once you have the slope, plug it back into the equation using one of your points. Using (2, 7): 7 = 3(2) + b. That simplifies to 7 = 6 + b, so b = 1. Your y-intercept is 1, and the full equation is y = 3x + 1. With more than two points, you're dealing with regression. The least squares method finds the line that minimizes the sum of squared residuals. The formula for the intercept in simple linear regression is b = ȳ - m*x, where ȳ is the mean of your y values, x is the mean of your x values, and m is the slope. It's elegant, it's fast, and it works for basically everything unless your data violates the assumptions of linearity, homogeneity of variance, or independence. I typically use Python with numpy and scipy for anything beyond textbook examples. A quick linear regression on a dataset of about 500 points takes roughly 0.02 seconds on my machine. Doing it by hand would take me about 45 minutes and I'd probably make an arithmetic error somewhere. I've done both, so I know the difference.
Where the Y Intercept Breaks Down
Not every relationship is linear. If you're fitting a line to exponential or logarithmic data, the y-intercept of that linear approximation is mathematically valid but practically misleading. I spent a week debugging what I thought was a data entry error, only to realize the underlying relationship was exponential growth and I was interpreting the intercept of a linear fit as if it meant something real. Another scenario where the y-intercept becomes unreliable is when your x-values never actually approach zero. If you're modeling website traffic based on ad spend, and your data only covers spend levels between $5,000 and $50,000 per month, extrapolating back to x = 0 is just guessing. The y-intercept from that regression could be anywhere and still be consistent with your data. That's called extrapolation error, and it's one of the fastest ways to build a model that looks good on paper and fails in production. Multicollinearity in multiple regression is another place where intercept interpretation gets murky. When your predictor variables are highly correlated, the individual coefficient estimates become unstable, and while the overall model might still predict well, the intercept and individual slopes can swing dramatically with small changes in the data. I've seen intercepts flip from positive to negative when removing a single outlier from a dataset with 200 rows and three correlated predictors.
If you're working with categorical data or binary outcomes, the standard y-intercept from linear regression isn't the right tool. Logistic regression gives you a different kind of intercept that represents the log-odds when all predictors are zero. It's still technically an intercept, but interpreting it as "the starting value" makes zero sense. You'd need to exponentiate it and work with odds ratios instead. This came up for me when someone tried to use a linear probability model for a conversion rate prediction and was confused why the y-intercept suggested a 140% conversion rate under certain conditions.
Practical Tips That Actually Help
Always plot your data before calculating anything. A scatter plot takes about 30 seconds in any reasonable tool and will save you hours of misinterpretation. I once had a dataset where the y-intercept looked perfectly reasonable until I plotted it and saw a clear U-shaped curve. The linear fit was nonsense, and the intercept meant absolutely nothing. Check your confidence intervals. The point estimate of the y-intercept is rarely useful on its own. In my experience, a 95% confidence interval for the intercept that spans zero or extends into physically impossible territory is a strong signal that your model needs rethinking. I usually report both the estimate and the interval together because the interval tells you how much you can actually trust the number. If you're using this for forecasting, separate your validation set from your training set. Fitting the model and then testing it on the same data will give you an optimistically biased y-intercept. Cross-validation or a held-out test set is the standard approach, and it typically reveals that the apparent precision of your intercept was overstated by 20 to 40 percent in my experience across various domains.
Don't force the intercept to zero just because it feels cleaner. I've seen this happen in financial modeling where someone removes the intercept because it's small and awkward-looking. That changes the model fundamentally and can introduce significant bias. Only drop the intercept if you have a substantive reason to believe the relationship truly passes through the origin.


