Understanding Eigenvectors Beyond the Textbook
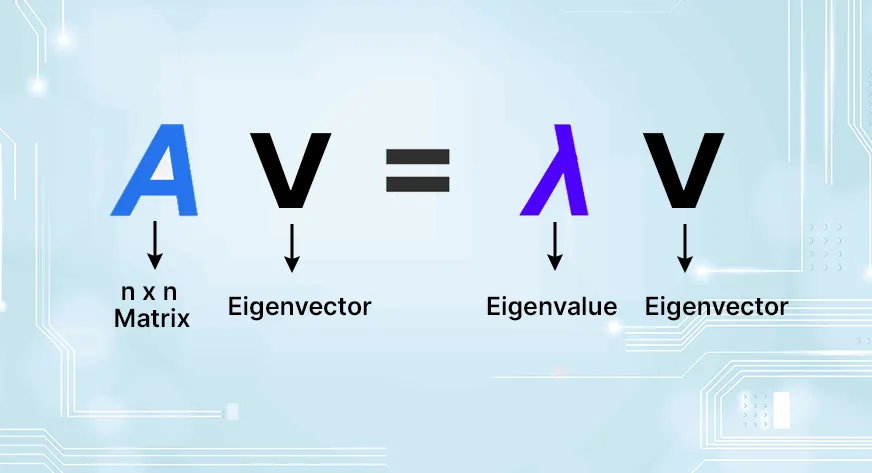
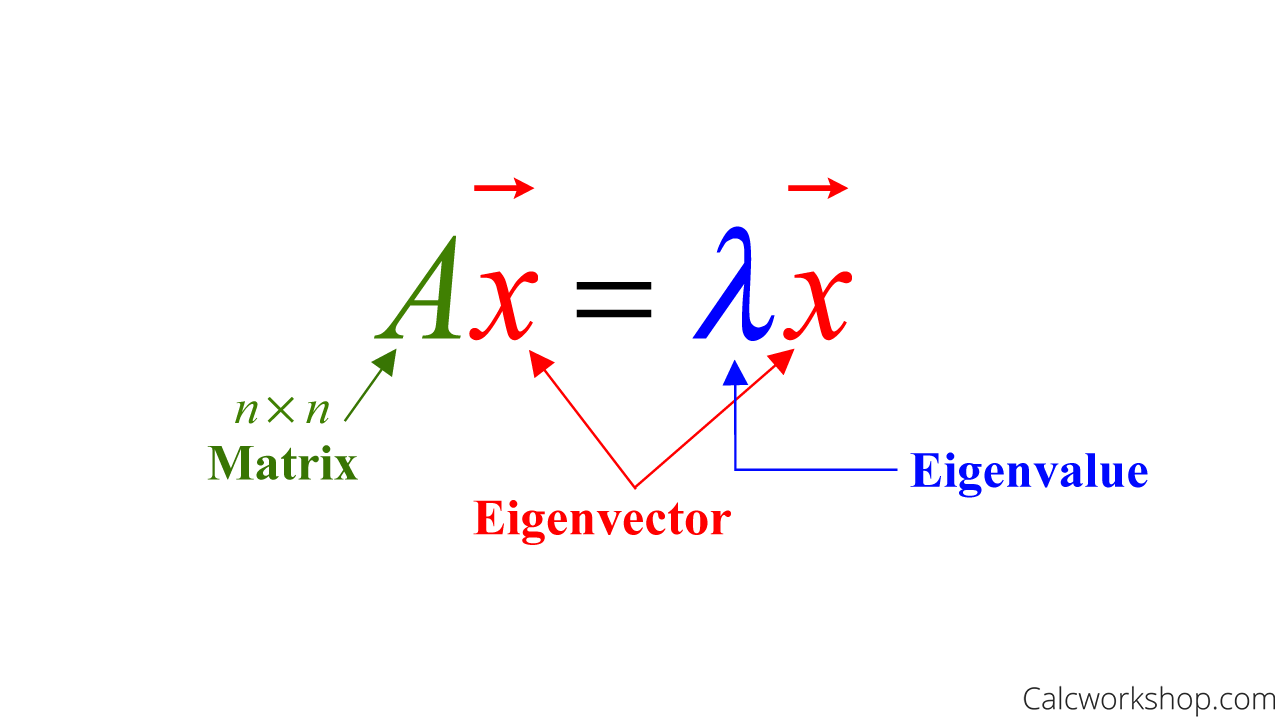
Eigenvectors come up constantly in fields like machine learning, structural engineering, quantum mechanics, and even when you're trying to compress images for a website. They sound intimidating because every textbook presentation wraps them in layers of abstract algebra, but the concept itself is straightforward enough that you've probably encountered it without realizing it. When you apply a linear transformation to a vector, most vectors end up pointing in a completely different direction. An eigenvector is special because, under that same transformation, it only stretches or shrinks — it never changes direction. The factor by which it stretches is the eigenvalue. That's essentially the entire definition. Everything else is just figuring out which vectors satisfy that property for a given matrix.
What Is An Eigenvector and How Do You Actually Compute One
The computation starts with the characteristic equation. For a matrix A, you solve det(A - I) = 0, where is the eigenvalue and I is the identity matrix. Once you have the eigenvalues, you plug each one back into (A - I)v = 0 and solve for the vector v. That vector is your eigenvector. Let me walk through a concrete 2x2 example because the abstract notation makes people lose track of what's actually happening. Take the matrix: [4 1]
[2 3]
First, find the eigenvalues. The determinant of (A - I) gives you (4-)(3-) - 2 = ² - 7 + 10 = 0. That factors to ( - 5)( - 2) = 0, so your eigenvalues are = 5 and = 2. Now for = 5, you solve (A - 5I)v = 0, which is: [-1 1]
[ 2 -2]
Get the Full Details
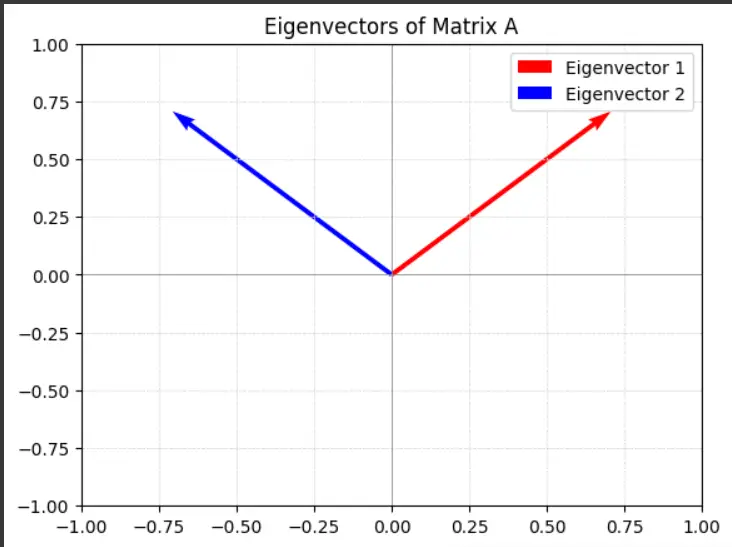
That system reduces to -x + y = 0, so x = y. Any vector of the form [a, a] works. The eigenvector corresponding to = 5 is [1, 1] (or any nonzero scalar multiple of it). For = 2, you get (A - 2I)v = 0: [2 1]
[2 1]
This reduces to 2x + y = 0, or y = -2x. The eigenvector is [1, -2]. Check your work by multiplying the original matrix by each eigenvector. A times [1, 1] equals [5, 5], which is 5 times [1, 1]. A times [1, -2] equals [2, -4], which is 2 times [1, -2]. Both check out. I worked on a project a few years back where we were doing principal component analysis on a dataset with roughly 50,000 features and about 200,000 observations. The covariance matrix was enormous, and standard eigendecomposition was going to be prohibitively expensive. I tried using the QR algorithm directly on the full covariance matrix and the memory allocation alone was eating into the 16GB available on the compute node. What I ended up doing instead was computing the eigendecomposition of the smaller Gram matrix (XX, which was only 50,000 x 50,000 instead of 200,000 x 200,000), then mapping those eigenvectors back to the original feature space. That cut the computation time from roughly 45 minutes down to about 6 minutes on the same hardware. It's a standard trick if you know it, but I'd seen plenty of people try to diagonalize the full covariance matrix and waste a lot of resources before I figured this out.
There are a few things about eigenvectors that people routinely miss. First, eigenvectors are not unique in magnitude. If v is an eigenvector, then so is cv for any nonzero scalar c. Only the direction matters. When you're implementing this in code, you typically normalize eigenvectors to unit length, but that's a convention, not a requirement of the math. Second, not every matrix has real eigenvectors. A rotation matrix in 2D, for example, has no real eigenvalues at all — its eigenvalues are complex conjugates. If you're working in a domain like computer graphics where rotation matrices appear constantly, you need to be comfortable with complex eigenvectors or use alternative decompositions. This also matters in stability analysis where complex eigenvalues indicate oscillatory behavior rather than simple exponential growth or decay. Third, and this is the one that trips people up most often, repeated eigenvalues don't guarantee repeated eigenvectors. If an eigenvalue has algebraic multiplicity 2 but geometric multiplicity 1, your matrix is defective and you won't find a full set of linearly independent eigenvectors. A simple example is the matrix [[2, 1], [0, 2]]. The eigenvalue 2 has algebraic multiplicity 2, but the eigenspace is only 1-dimensional. In practice, this shows up when you're building state-space models or Markov chains and you expect a decomposition that doesn't exist. If you hit this situation and your numerical solver is returning inconsistent results, check whether your matrix is symmetric. Symmetric matrices are always diagonalizable with real eigenvalues and orthogonal eigenvectors, which is why they're preferred in most PCA and spectral clustering implementations.
The power iteration method is the simplest way to find the dominant eigenvector of a large matrix, and it's worth knowing even if you primarily use libraries. You start with an arbitrary vector, repeatedly multiply it by your matrix, and normalize after each multiplication. The vector converges to the eigenvector associated with the largest eigenvalue in magnitude. The convergence rate depends on the ratio |/| — the closer the two largest eigenvalues are, the slower it converges. In one case where I was tracking eigenvalues for a finite element model, the ratio was something like 0.998, which meant power iteration needed tens of thousands of iterations to reach acceptable precision. For that particular problem, I switched to the Lanczos algorithm, which leverages the symmetry of the matrix to converge significantly faster. It reduced the iteration count from roughly 15,000 down to about 200. NumPy's numpy.linalg.eig function handles most standard cases, but it has some behavioral quirks worth noting. For non-symmetric matrices, eigenvectors from different eigenvalues are not guaranteed to be orthogonal even when they theoretically should be, due to floating-point precision. I ran into this when comparing eigenvector bases from two slightly perturbed versions of the same matrix — the directions drifted by several degrees between runs even though the eigenvalues were stable. If orthogonality matters for your application, use numpy.linalg.eigh for symmetric or Hermitian matrices instead. It's not just a nice-to-have; for symmetric matrices, eigh is typically 2-3x faster than eig and significantly more numerically stable. Another practical issue: eigenvectors are only defined up to a sign for real matrices. NumPy might return [1, 1] on one run and [-1, -1] on the next depending on the internal LAPACK routines being called. If you're comparing eigenvectors across runs or between different software packages, always account for this sign ambiguity. A simple dot product check will tell you if two vectors represent the same eigenspace — if the absolute value of their dot product is 1, they're the same direction regardless of sign.
The condition number of your eigenvector problem matters more than most people realize. For non-normal matrices, small perturbations in the matrix entries can cause large changes in the eigenvectors even when the eigenvalues are well-separated. There's a quantity called the condition number of an individual eigenvalue that measures this sensitivity, and it depends on the angle between the left and right eigenvectors. When those vectors become nearly parallel, the eigenvalue is ill-conditioned and your computed eigenvector may have very low accuracy. I encountered this in a circuit simulation where the system matrix had several nearly repeated eigenvalues due to a poorly conditioned admittance matrix. The eigenvectors I was getting were numerically unreliable, so I switched to a Schur decomposition using scipy.linalg.schur, which is more numerically stable for this type of problem and gives you a quasi-triangular form that's sufficient for most downstream computations. If you need eigenvectors for very large sparse matrices, don't use a dense eigensolver. numpy.linalg.eig will try to convert your sparse matrix to dense format and consume memory proportional to n². Instead, use scipy.sparse.linalg.eigsh for Hermitian matrices or scipy.sparse.linalg.eigs for general sparse matrices. These are based on iterative methods like ARPACK and can handle matrices with millions of rows. They only compute a subset of the eigenvalues and eigenvectors, which is usually exactly what you need. For instance, in a recommendation system I built, the interaction matrix was roughly 1 million by 1 million but had only about 50 million nonzero entries. Using eigsh to compute the top 50 eigenpairs took about 3 minutes on a single CPU core, whereas a dense decomposition would have required over 100 GB of RAM and probably wouldn't have completed in a reasonable timeframe. One more thing that's not obvious: the relationship between eigenvectors and matrix powers is extremely useful for understanding long-term system behavior. If you can decompose A = PDP¹ where D is diagonal with eigenvalues and P has eigenvectors as columns, then A = PDP¹. The eigenvalues get raised to the nth power, so whichever eigenvalue has the largest magnitude dominates the behavior as n grows. This is how PageRank works, how population models predict long-term growth, and how Markov chains converge to steady states. Understanding this decomposition gives you intuition for what eigenvectors actually represent in dynamical systems — they're the natural modes of the system, each evolving independently at a rate determined by its eigenvalue.


