The Short Answer
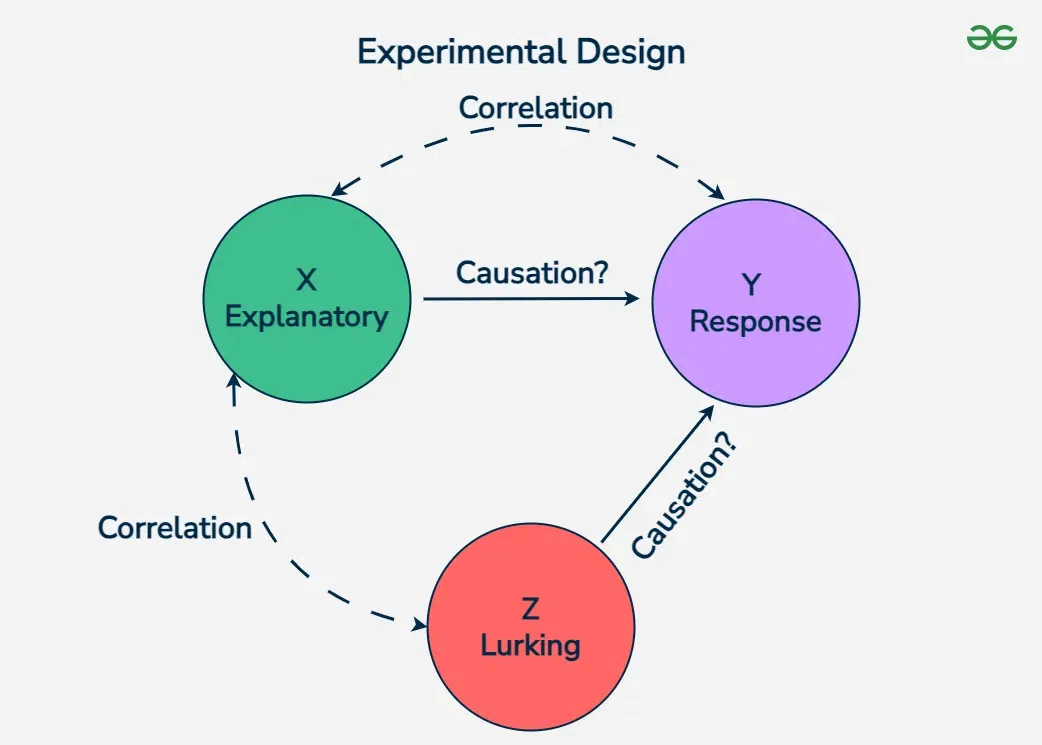
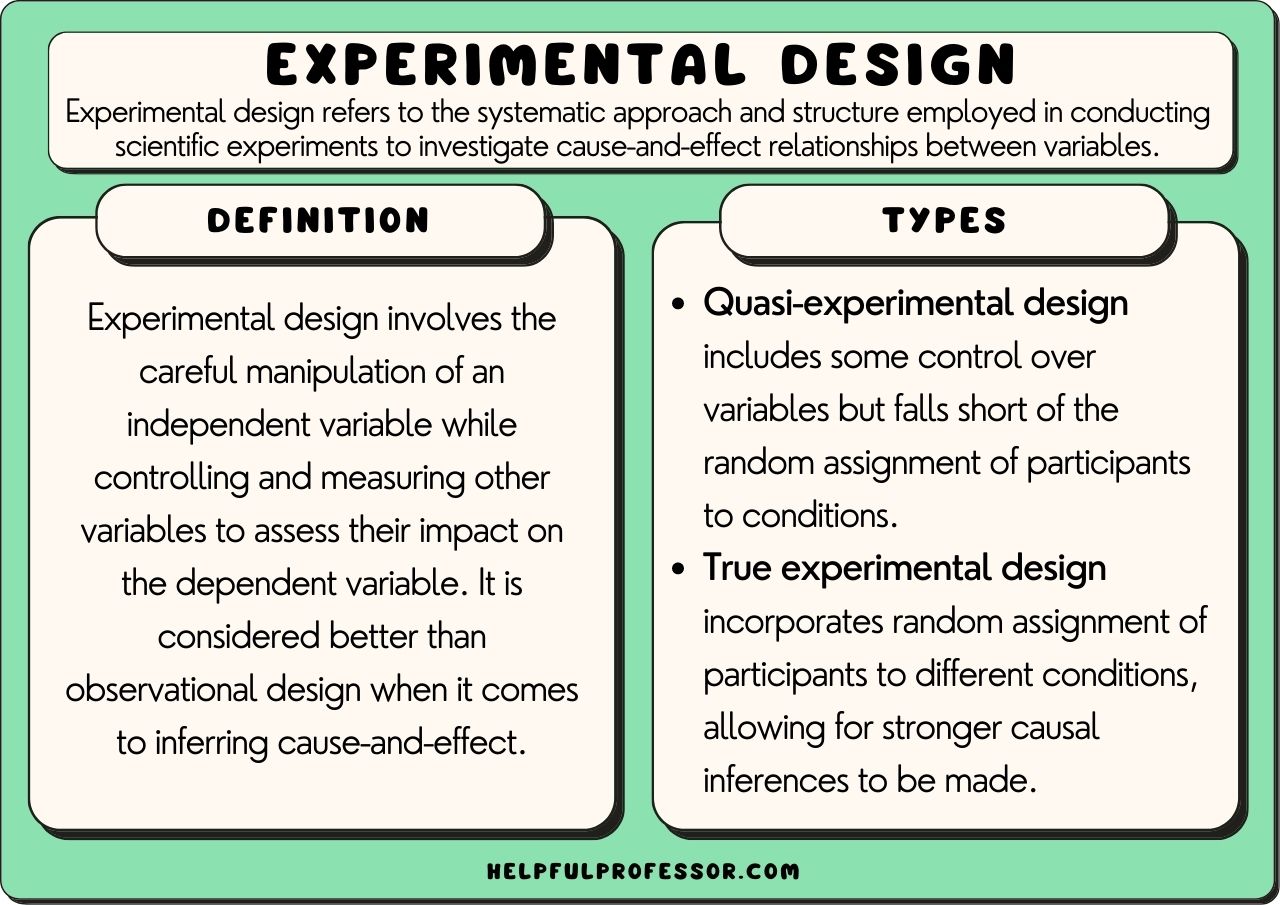
An experimental design is the plan that determines how you organize variables, controls, and observations so that the results you get actually tell you something real instead of noise. People usually talk about it in stats classes, but in practice it is the thing that separates a project that ships from a project that gets filed away after someone realizes the data is useless. At its core it is just a structured way to impose causality on a messy world. You pick a factor you want to test, you hold everything else constant or randomize it away, you measure an outcome, and you repeat enough times that the signal survives the variance. That is the entire concept. The complications come from the edges. I learned this the hard way on a pricing experiment for an e-commerce platform about three years ago. We set up a randomized A/B test with a new discount rule. The test ran for two weeks. The numbers looked great, p-value well under 0.05, click-through and conversion both moved in the right direction. Then we rolled it out site-wide and revenue dropped.
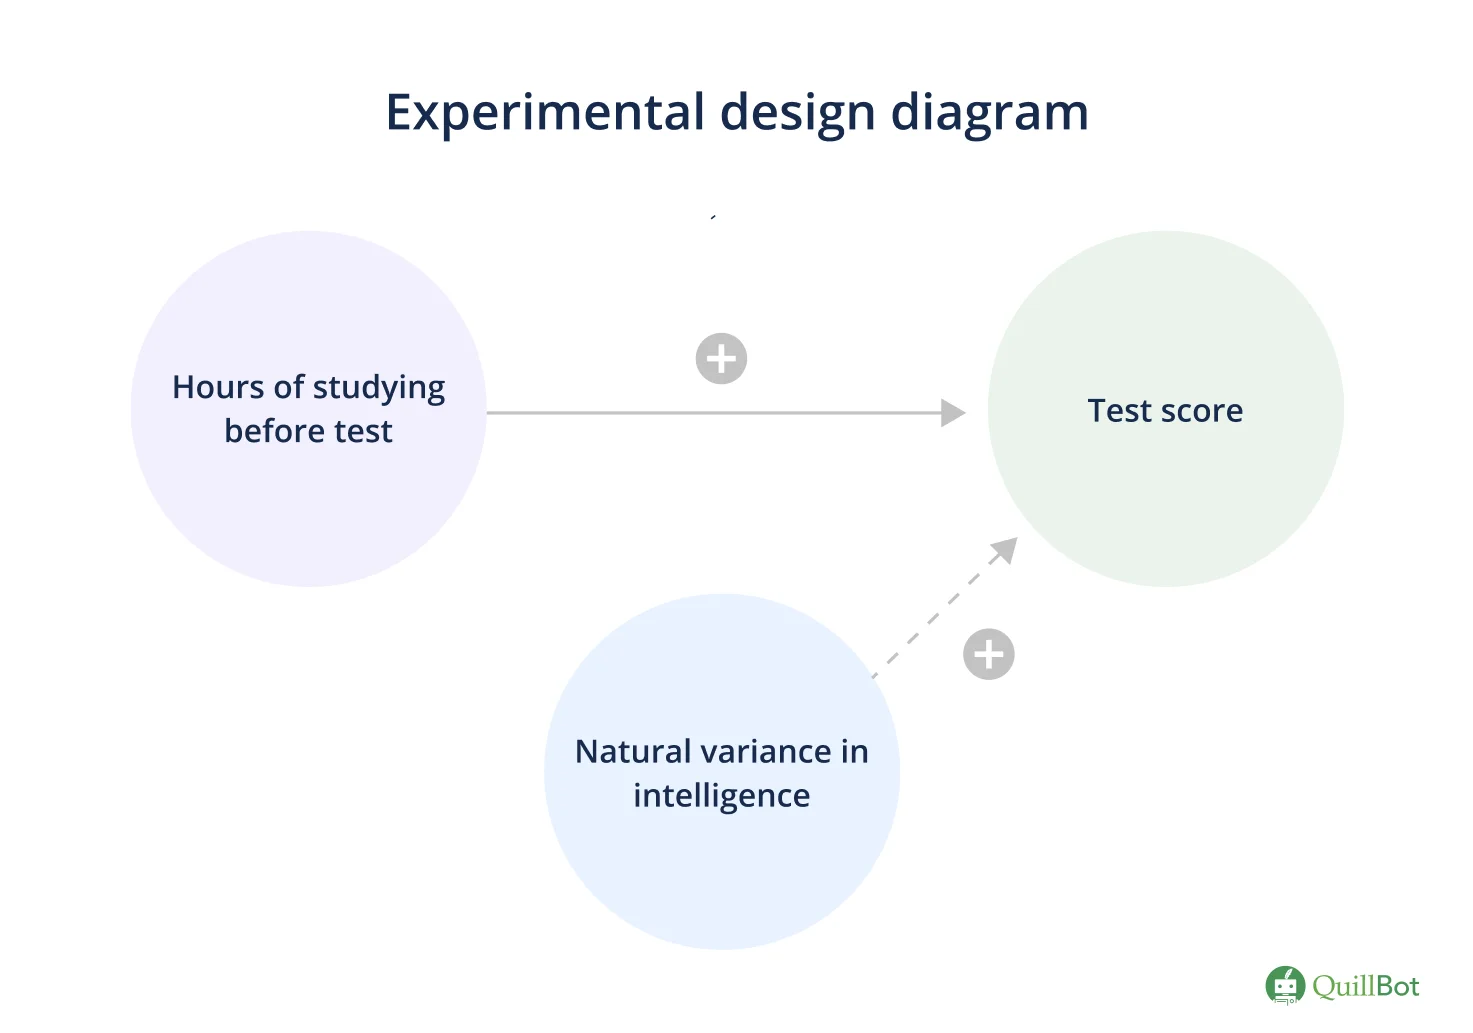
The problem was selection bias baked into the randomization. We assigned users to treatment and control by user_id hash, which seemed fine, but the traffic mix changed mid-test because a marketing campaign pulled in a wave of referral users who behaved completely differently. The test group swallowed more of those referrers than the control group. The effect was not the discount. It was the audience shift masquerading as a treatment effect. My workaround was straightforward once I saw it. I switched to a clustered randomization by session cohort with week-level blocking, then added stratified sampling on traffic source as a covariate in the analysis model. I also ran a pre-registration style specification before the next test and locked the randomization seed. The follow-up test took longer to reach significance, but the conclusion matched the post-launch results within a few percentage points, which is about as good as these things get. The takeaway is not that randomization is bad. It is that randomization assumptions are easy to forget when you are racing to a decision.
The Components You Need To Specify Before You Start
You have to define five things up front or the experiment is already broken, even if the code looks clean. Treatment and control conditions. This sounds obvious until you realize most failed experiments fail because the treatment condition was underspecified. A button color is a treatment. A new checkout flow with a different payment provider and a copy rewrite is not a single treatment, it is a bundle, and you will not know which part drove the result. The unit of randomization. User, session, device, page view, account, region. Pick one and be honest about why. If you randomize by user but analyze by session, your standard errors will be wrong and your confidence intervals will lie to you.
Get the Full Details
The outcome metric. Primary and secondary. Primary should be a single number you would bet real money on. Secondary metrics catch side effects. Revenue per visitor, conversion rate, time to task completion, retention at day seven. Don't pick ten primary metrics and then pretend you are doing one test. That is fishing. Sample size and power. Calculate this before you run anything. Use a realistic estimate of baseline variance, not the best case you have seen in a dashboard. Underpowered tests produce false negatives and false positives at roughly the same rate when people start p-hacking them. I usually aim for 80 percent power with a two-sided alpha of 0.05 unless the decision stakes push me higher. The analysis plan. Write it down. Intention-to-treat or per-protocol, which model you will use, how you will handle missing data, whether you will adjust for multiple comparisons, and when you will stop looking at the data. If you do not do this now, you will change the plan later to make the ugly result look acceptable, and everyone will know because the pattern is obvious in retrospect.
Common Designs And When To Use Them
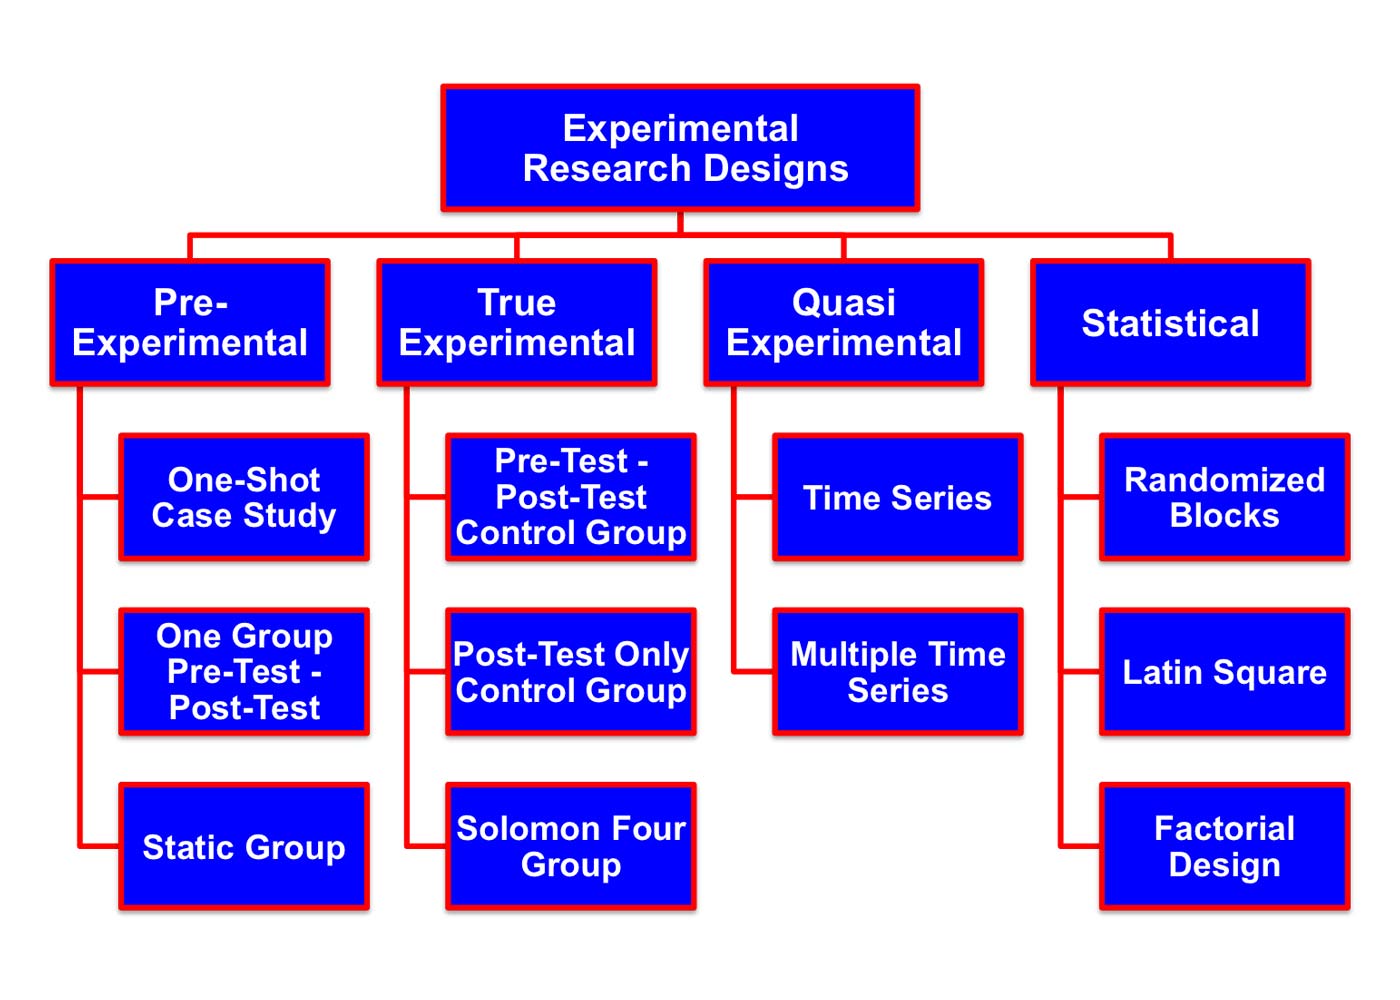
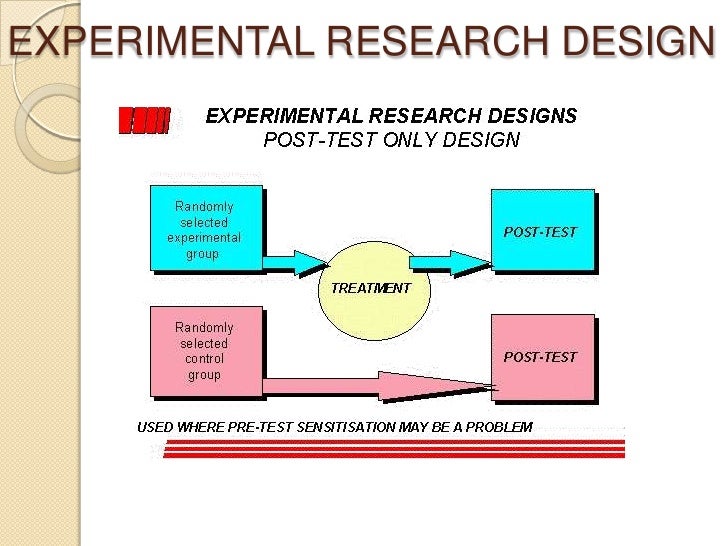
Not every problem needs a full randomized controlled trial. Pick the simplest design that answers the question. Completely randomized design. The default. Good when the population is large and homogeneous enough that chance balance works. If you randomize 1,000 users per group, covariate imbalance is usually small. If you randomize 20, it is not. Blocked or stratified design. Use this when you know a strong predictor exists before treatment. Device type, geography, account tier, recency of last purchase. Blocking reduces variance and lets you detect smaller effects with the same sample size. It also protects against the kind of traffic shift that ruined my pricing test.
Cross-over design. Subjects receive treatment and control in sequence. Useful when the outcome is temporary and you can wash out carryover effects. Dangerous when the treatment has a lasting effect, like a brand repositioning or a policy change. I have seen teams run cross-over tests on notification frequency without an adequate washout period and then argue the second phase proved the first phase wrong. Factorial design. Test two or more factors simultaneously. A 2x2 factorial gives you main effects and an interaction with four groups instead of testing each factor separately. This is where most people waste time. Factorial designs double or triple the sample size requirement. Only use them when you actually expect interactions or when testing factors in isolation would miss a critical dependency. Regression discontinuity design. Assignment hinges on a cutoff. Tuition waivers at a GPA threshold, eligibility at an age limit, feature flags at a version number. This is not randomization, but it approximates local randomization near the cutoff. The assumptions are fragile. If agents can manipulate the assignment variable, the design falls apart. I once saw a RD analysis on login behavior break because the platform changed the error message wording at the same cutoff, and the message change drove the observed effect.
What People Miss About Statistical Power And Sample Size
Power is not a magic number you set and then ignore. It depends on the true effect size, which you do not know. Most practitioners pick a minimum detectable effect based on a gut feel or a target business impact, then run the test and wonder why it takes six weeks to reach significance. The fix is usually to narrow the population, reduce variance through blocking, or accept a larger minimum detectable effect. Another thing nobody mentions enough: peeking at results mid-test inflates the false positive rate. If you check daily and stop when p drops below 0.05, your actual Type I error can climb to 15 or 20 percent depending on how often you peek. Use sequential analysis methods like alpha spending functions, or just wait until the pre-specified look time. The second option is simpler and almost always sufficient.
The Hard Truths About Experimental Design
It does not solve bad product questions. If you are testing whether to change a font size because you think it will move revenue, a clean experiment will give you a clean answer that you still may not like. It will not tell you if the question is worth asking. It does not protect you from external validity failures. A test that runs only on iOS during a sale period will not generalize to Android users in November. If you need external validity, run the test longer, across more segments, or use a field study design instead of an online A/B test. It breaks completely when the treatment leaks across groups. Network effects are the usual suspect. If treatment users start influencing control users through social connections or shared resources, your estimate is biased toward zero and you will understate the true effect. I have worked on features where the spillover was large enough that the measured lift was half the real lift. The only honest move there is to randomize at a higher level, like region or cohort, and accept the larger sample size cost.
A Quick Checklist Before You Launch
Write the protocol. Define the unit, the treatment, the outcome, the sample size, the analysis model, the stopping rule. Simulate the test with synthetic data if you can, even crudely, to catch implementation bugs. Run a small pilot. Check that the randomization actually balanced the covariates you care about. Monitor for early anomalies like tracking failures or uneven rollout. Do not ship until the protocol is locked and someone who did not write the code reviews it.