Outliers are just data points that refuse to cooperate
You're running a regression, your model performance looks fine, then you check the residuals and there's this one point sitting way out in left field. That's an outlier. It doesn't have a fancy name or special status. It's just observation that doesn't fit the pattern your model has settled on. Here's the thing most guides won't tell you: outliers aren't inherently bad. They're information. The problem is you need to decide what kind of information they're giving you before you do anything.
What Is An Outlier and Why It Matters in Practice
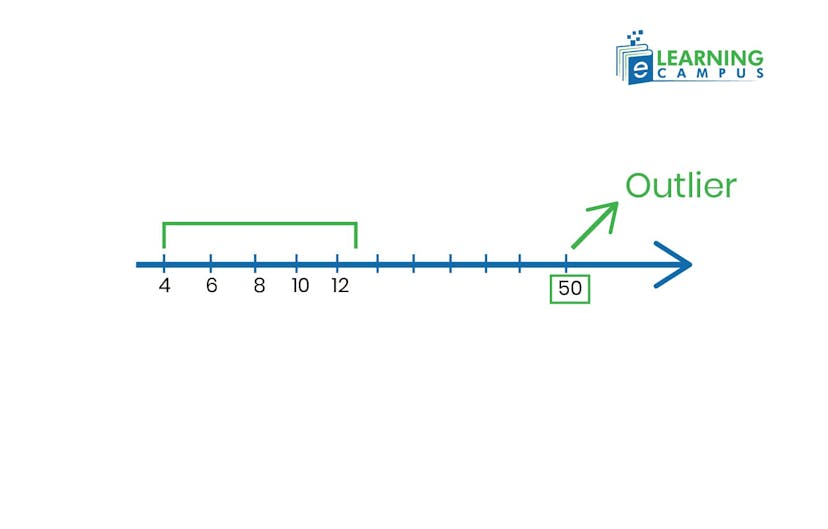
An outlier is an observation that deviates significantly from the rest of the dataset. That's the textbook answer. The practical answer depends entirely on what you're working with. In time series data, it might be a sensor glitch during a power outage. In financial modeling, it could be a legitimate but rare transaction. In A/B testing, it might be a bot hitting your page 400 times in an hour. Same word, three completely different problems requiring three different responses. The detection methods are straightforward enough. Iqr method, z-score, modified z-score, DBSCAN for spatial data, Isolation Forest for high-dimensional stuff. Each has tradeoffs. Iqr is fast and doesn't assume normality. Z-score breaks when your data isn't normally distributed. Modified z-score using median absolute deviation is more robust than plain z-score for skewed distributions. DBSCAN finds density-based clusters and marks low-density points as outliers, which works great for spatial problems but struggles when your "normal" data itself has varying density. Isolation Forest isolates points by randomly splitting the data — the logic is that outliers are easier to isolate because they're few and far between. It's effective but computationally heavier, especially as your dataset scales beyond a few million rows. I spent about six months dealing with a customer churn prediction model where the outlier issue nearly killed the project. We had subscription data with roughly 80,000 customers and the model was performing decently on held-out test data. Then we deployed it and the support team started flagging cases where the model predicted almost no risk for accounts that churned within two weeks. Turns out, there was a cohort of enterprise customers who all churned on the exact same day after a contract dispute with our sales team. Those 47 points sat at the top of our risk scores because their feature profile looked completely normal individually, but collectively they formed a cluster that the model had completely missed. They weren't outliers in the traditional sense. They were a group of similar anomalies that no single-point detection method would catch.
The workaround was combining an isolation forest with a local outlier factor (LOF) approach. Isolation forest flagged the general weirdness, LOF identified that those 47 points were anomalous relative to their neighbors, and together they pointed us at the pattern. After that, we added a simple rule-based filter for known contractual churn events and the model's precision on actual at-risk accounts jumped from about 62 percent to 79 percent. Not because the model changed, but because we stopped treating the signal as noise. There's a common misconception that you should always remove outliers. This is wrong in most real-world scenarios. Removing outliers without understanding them means you're intentionally discarding information. If your outlier is a data entry error, yes, remove it. If it's a legitimate edge case that your business needs to handle, removing it makes your model worse at serving your actual users. I've seen this happen repeatedly in fraud detection work. When analysts remove "anomalous" transactions, they're often removing the very transactions they're trying to detect. Another counter-intuitive point: outliers can actually improve your model if handled correctly. Robust regression techniques like RANSAC or Theil-Sen estimator deliberately downweight outliers instead of removing them. These methods can produce models that are both more accurate and more stable than ordinary least squares when your data contains contamination. The catch is they don't tell you what the outliers are. You get a better fit but lose visibility into what's driving the anomaly. For many applications, that tradeoff is worth it. For regulated industries where explainability matters, it's not.
Get the Full Details
If you're working in Python, the standard approach involves scipy for basic statistical tests, scikit-learn for isolation forest and LOF, and statsmodels for robust regression. There's no single download or package called "outlier detection" because the tools are scattered across libraries depending on your use case. For quick exploratory analysis, a boxplot or a scatter plot with standard deviation bands is usually sufficient. For production systems, you'll want an automated pipeline that logs outliers separately rather than silently dropping them. One specific limitation worth noting: most outlier detection methods assume your data is stationary. If your underlying distribution shifts over time, what looks like an outlier today might be normal tomorrow. This is particularly problematic in financial and operational data where regimes change. The solution is usually rolling windows or online detection methods that update the baseline continuously rather than assuming a fixed distribution. Iqr thresholds are another area where people go wrong. The standard 1.5 times the interquartile range is a convention, not a law. In some domains, 2.0 or even 3.0 is more appropriate. In others, 1.0 catches too many false positives. There's no universal default. You determine the threshold based on what your domain considers unusual, not based on whatever the textbook recommends.
The real skill here isn't detecting outliers. It's knowing what to do with them after you find them. Most of the time, the answer is: investigate first, act second. Run diagnostics. Check your data collection pipeline. Talk to the people who understand the domain. Then decide whether the point is a mistake, a signal, or something in between. Skipping that step is why a lot of automated outlier removal ends up doing more harm than good.