Fitting Lines to Data and Understanding the Intercept Term
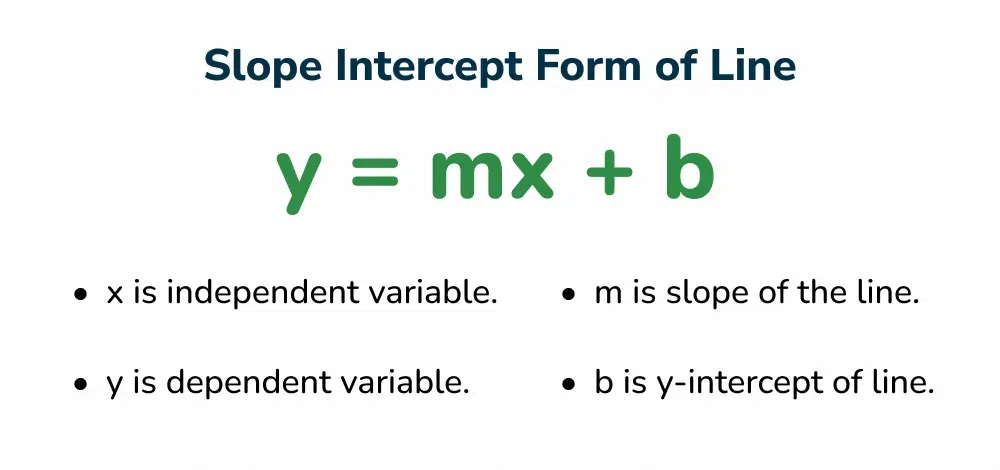
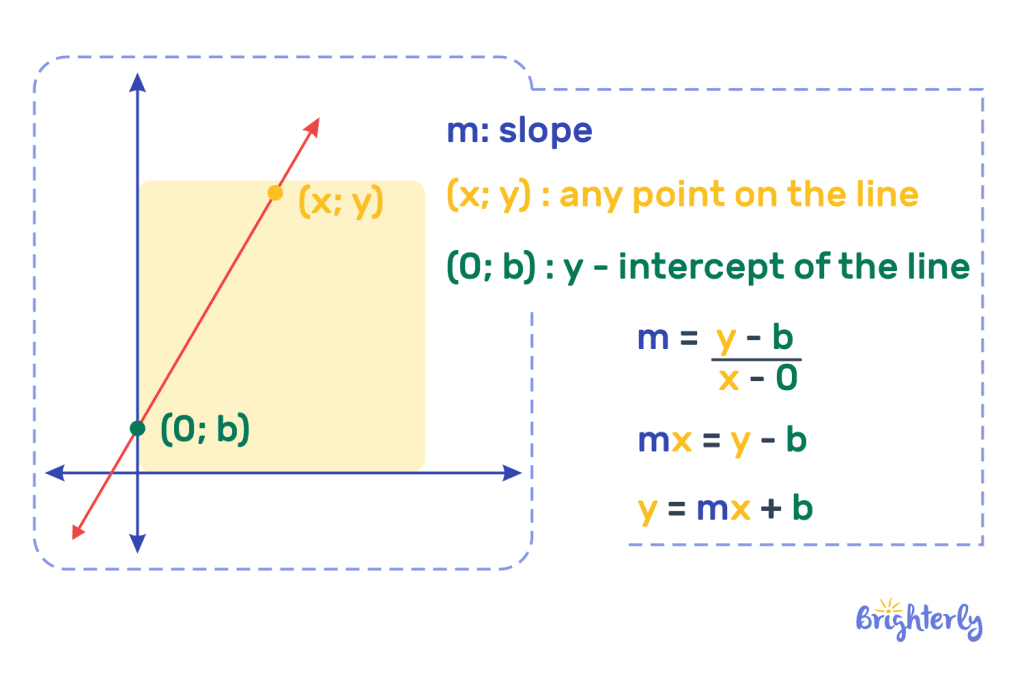
I have been fitting straight lines to datasets for longer than I care to admit, and I still occasionally get tripped up by the intercept. The equation y = mx + b shows up in college algebra, in engineering notebooks, in data science tutorials, and in casual conversation about trends. People throw it around without really thinking about what each piece does. That tends to cause problems later. B is the y-intercept. It is the value of y when x equals zero. On a graph, it is where the line crosses the vertical axis. In plain terms, it represents the baseline of your dependent variable before the independent variable contributes any change. The m term is the slope, which controls how steep the line is. The x term is your input. Multiply them together and add b, and you get the predicted y value for that x. I remember a specific project a few years back where I was modeling the relationship between hours spent studying and test scores. The slope came out to about 2.1 points per hour, which felt reasonable. The intercept, though, was negative. A score of negative twelve points does not make sense on a standard test. I stared at the spreadsheet for twenty minutes wondering if I had entered the data wrong. I had not. The issue was that the linear relationship simply does not hold near zero study time. Students who do not study at all tend to score around twenty or thirty percent from guessing, not negative numbers. The model was fine within the range of my data, maybe one to ten hours, but extrapolating to zero produced garbage. I ended up centering the predictor variable around the mean instead of leaving it raw, which pushed the intercept into a meaningful range and made the output easier to interpret. That shift alone changed how I thought about the intercept in every project after that.
One thing beginners consistently miss is that b is not just a mathematical placeholder. It carries real meaning in context. If you are modeling the cost of a phone plan with a monthly fee and per-minute charges, b is the monthly fee. If you are tracking the growth of a plant measured in centimeters over weeks, b is the starting height. The slope handles the rate, and b handles the starting condition. Confusing the two leads to wrong conclusions about what your data actually says. There is also a practical limit to relying on y = mx + b for everything. If your data follows an exponential curve, a linear fit will miss the pattern entirely. A relationship between population and time, or compound interest, will never look straight no matter how you tilt it. In those cases, you need a different equation. Logarithmic, quadratic, and exponential models exist for a reason. Picking the right one matters more than forcing a line through points that clearly do not want to be linear. Sometimes b looks wrong even when the model is technically correct. I worked with experimental physics data once where the intercept was slightly above zero when theory predicted exactly zero. The non-zero value came from a small calibration error in the sensor, not from the underlying phenomenon. Rather than ignoring it, I adjusted the zero point and re-ran the fit. The slope improved slightly after the correction. This is a normal part of working with real data, not a failure of the method.
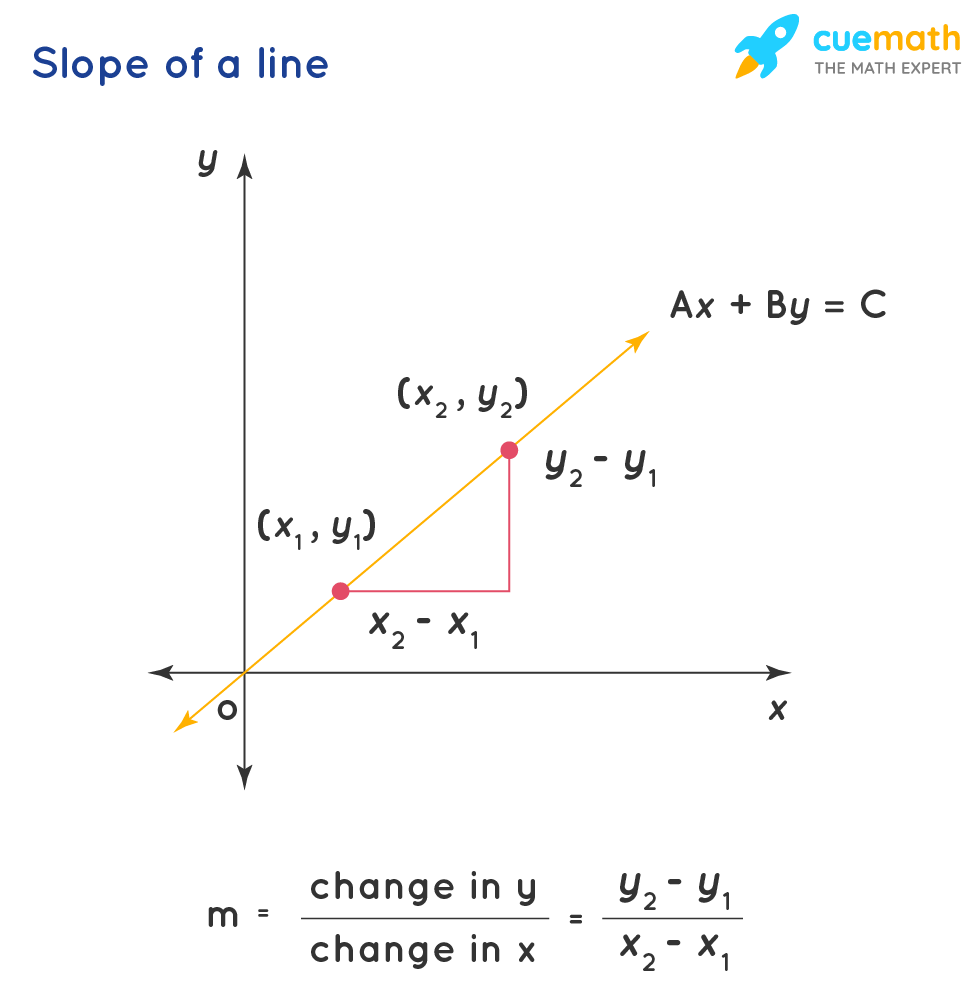
The formula for calculating b in a least squares regression is straightforward if you already have m. You take the mean of all y values, subtract m times the mean of all x values, and what remains is b. Written out: b = ȳ m·x. It is one of those equations that looks intimidating on paper but becomes second nature after doing it a dozen times. The slope m itself is calculated as the covariance of x and y divided by the variance of x. Both pieces fit together cleanly when your data behaves. A common mistake is to assume that a larger absolute value of b means a better model. It does not. A large intercept might simply indicate that your variables are on a large scale or that there is a substantial baseline effect unrelated to your predictor. What actually matters is how well the line explains the variation in your data, usually measured by R-squared or the sum of squared residuals. The intercept is part of the fit, but it is not the primary quality metric. When the slope is very small relative to the scale of your data, the line appears nearly flat, and b dominates the prediction. This happens frequently in observational studies where the independent variable has little explanatory power. The model will still produce numbers, but those numbers will not be useful. In those situations, reporting b alongside a note about the weak relationship is more honest than presenting the line as if it reveals a meaningful pattern.
Get the Full Details
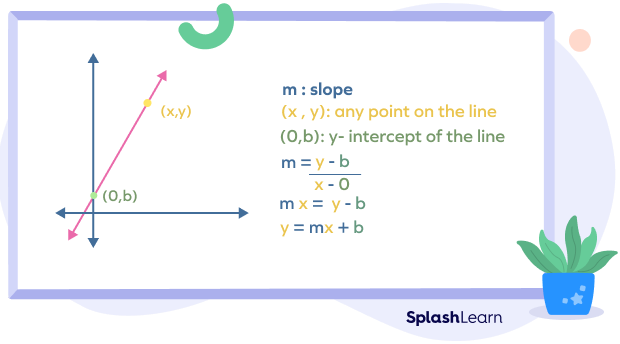
Another edge case I encountered involved data with extreme outliers. A single point far from the rest can pull the line toward it, shifting both m and b in unpredictable directions. Ordinary least squares minimizes squared errors, so outliers receive disproportionate weight. If you suspect outliers, consider robust regression methods or simply inspect your data before fitting. The visual check is cheap and often prevents expensive mistakes later. For a simple concrete example, take three data points: x values of 1, 2, 3 and y values of 3, 5, 7. The slope here is clearly 2, since y increases by 2 for every increase of 1 in x. The intercept works out to 1, because plugging x = 1 into y = 2(1) + 1 gives 3, which matches the first point. Checking the other two points confirms the equation: 2 times 2 plus 1 is 5, and 2 times 3 plus 1 is 7. The line fits perfectly, and b is 1. Linear equations are simple enough that people sometimes underestimate how easily they break outside their intended range. The equation y = mx + b is a tool, not a law of nature. Use it where it applies, understand what b actually represents in your specific situation, and do not be afraid to move to a different model when the data demands it. That practice alone will save you from a lot of avoidable confusion.