What Actually Happens When Two Systems Talk
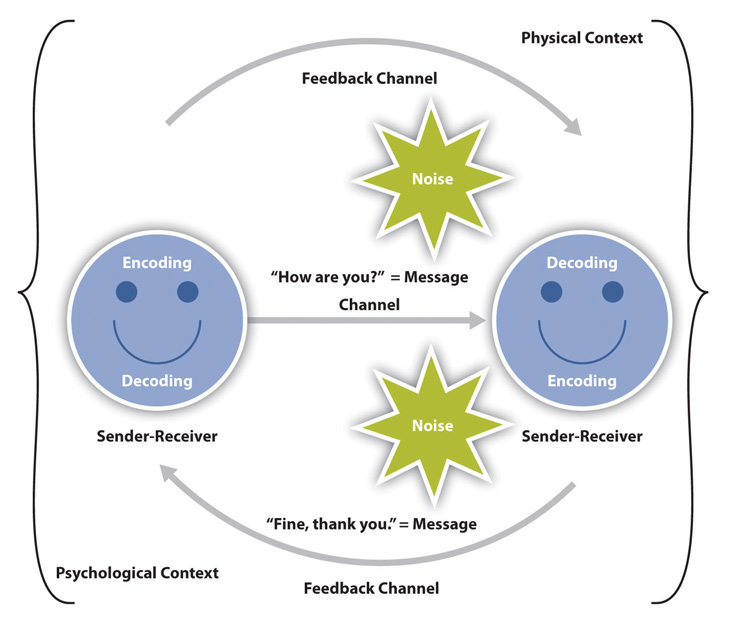
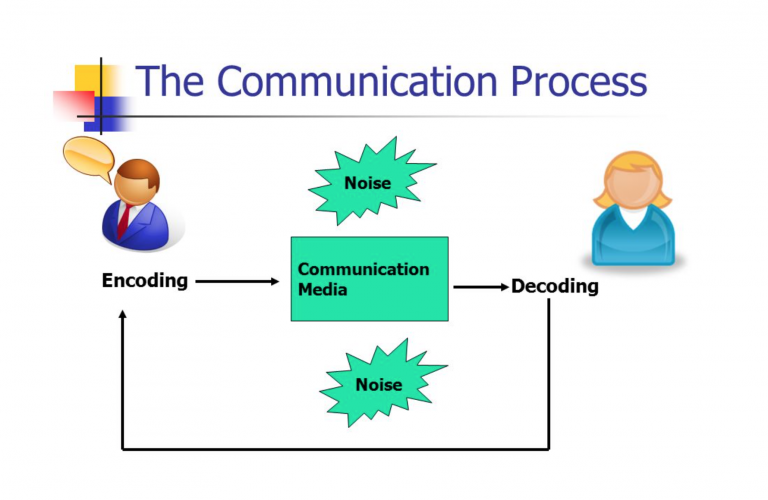
You build a function that sends a message from service A to service B. It works on your machine. Then you deploy it and suddenly everything breaks because nobody thought about what happens when the network drops mid-transfer, or when service B is running version 3 but service A still thinks it's talking to version 2. This is where communication channels become relevant, not as some abstract concept, but as the literal plumbing between processes. A communication channel is simply a defined path through which data moves from one point to another. That's it. In practice, it can be a TCP socket, a Unix pipe, a message queue, a WebSocket, a named mutex with shared memory, or even a file written to disk that another process polls. The medium varies. The problem it solves doesn't. I spent three weeks debugging what I thought was a race condition in a Python microservice. It turned out to be a communication channel issue — specifically, a Flask app writing JSON to a Redis queue faster than the worker could deserialize it, and the worker was occasionally grabbing a half-written frame. The fix wasn't adding locks. It was switching from raw string pushes to using Redis's LIST type with a fixed-max length and having the consumer ACK before processing. Took me forty-five minutes after three weeks of staring at code.
How Channels Actually Work Under the Hood
Every communication channel has three properties that matter: directionality, buffering, and lifetime. Directionality tells you whether data flows one way or two. Buffering determines whether the sender blocks when the receiver isn't ready. Lifetime controls whether messages survive a crash, a reconnect, or a restart. Most people get this wrong because they treat all channels as if they're the same. They're not. A socket channel is duplex and unbuffered by default in the application layer — data sits in OS kernel buffers, but from your code's perspective it's synchronous. A message queue is single-directional at the API level, buffered in the broker, and the producer doesn't know when the consumer reads it. A shared memory channel is bidirectional but requires explicit synchronization primitives or it degenerates into undefined behavior. Here's the counter-intuitive part that nobody teaches: a channel with no buffering is often safer than a buffered one, even though it feels worse to write against. When you block on send, you get backpressure built in. The system naturally throttles itself instead of quietly accumulating thousands of orphaned messages until the disk fills up and your monitoring dashboard shows nothing because the alert fired yesterday and you missed it.
Picking a Channel Type for Real Work
There's no universal answer, but there are decision points you should check before committing to anything. Are the endpoints on the same machine? If yes, shared memory or Unix domain sockets give you microsecond latency. If they're across a cluster, TCP or a brokered queue is your baseline. Don't reach for gRPC or GraphQL until you've solved the routing problem first. Do you need ordering guarantees? FIFO over TCP is not guaranteed unless you implement it yourself. TCP preserves order within a single connection, but if you reconnect, reorder, or load-balance across connections, your messages arrive in the order the load balancer dispatched them, not the order you sent them. I learned this the hard way when a RabbitMQ cluster in front of a Kubernetes deployment started reordering health-check payloads, and the downstream service treated stale heartbeats as failures.
Get the Full Details
What happens when one side dies? If the protocol doesn't handle disconnection gracefully, you'll have zombie connections piling up until you hit your file descriptor limit and the whole process segfaults on the next accept() call. This is more common than you'd expect in long-running Go services that spawn goroutines per connection without proper context cancellation.
Common Pitfalls That Waste Hours
The first one is silent truncation. Some serialization formats don't warn you when data gets cut off. CBOR handles this cleanly with length prefixes. JSON does not. If you're writing frames to a binary socket and one message gets split across two TCP segments, the receiver either reads garbage or hangs waiting for a close bracket that never comes in the current read. Use delimited framing — length prefix, delimiter, or both — before you ship anything to production. The second is assuming a channel is the same as a protocol. A WebSocket is a channel. The protocol on top of it — whether you define your own message format or use something like protobuf over WebSocket frames — determines reliability, versioning, and error handling. Mixing these concepts up leads to projects where every team writes their own wire format and nobody can talk to anyone else after six months. The third is ignoring backpressure entirely. I've seen async Python apps push thousands of items into an in-memory queue with no cap, then wonder why the process was using 4 gigabytes of RAM three hours after startup. Set a maxsize on your queues. Block the producer. It's cheaper to slow down the source than to OOM the consumer.
When Channels Fail Completely
Communication channels cannot solve problems that aren't about data movement. If your issue is consistency across distributed nodes, a channel won't help — you need a consensus protocol. If your issue is authentication, a secure channel alone doesn't prove identity; you need TLS with certificate validation, not just TLS because your library enables it by default without verifying the peer. Channels also break down when latency becomes the primary constraint and you need deterministic response times. Shared memory with lock-free queues can hit nanosecond-scale throughput, but only if you can guarantee single-producer-single-consumer topology. Add a second producer and you need atomics or a mutex, and you've just lost most of the advantage over a properly designed message queue.
What I Recommend Starting With
If you're building something internal and the services live in the same environment, start with Unix domain sockets for local IPC or gRPC for cross-process calls. gRPC gives you generated stubs, bidirectional streaming, and deadlines for free. It's heavy, but the alternative is writing your own framing, serialization, and retry logic, which is where most projects bleed time. If you need decoupling, use a persistent message broker — RabbitMQ for complex routing, Kafka for throughput-heavy log-style streams. Don't use a broker because it sounds architecturally mature. Use it because you have producers that must not wait for consumers, and you can't afford to lose messages between them. For simple pub-sub within a single process, asyncio.Queue with a bounded size covers 90 percent of cases without pulling in an external dependency. I used it in a data pipeline that ingested sensor readings at 10k events per second. The queue depth sat at about 500 items during steady state and spiked to 3,000 during burst windows. No crashes, no dropped messages, and the consumer workers processed at their own pace without flooding the backend database.
The Hard Part Nobody Talks About
Channel design is straightforward until you need to handle schema evolution. You ship version 1 of a message format. Six months later you need to add a field. Old consumers crash on unknown fields. New producers send data old consumers can't parse. The workaround I use is simple: every message carries a version number in the first four bytes, and consumers reject or coerce based on that. It adds two lines to every serialization path and saves you from the kind of incident where three services go down because someone added a nullable field to a JSON schema without checking the deserializer. This is what communication channels actually are in practice. Not theory. The mechanisms you choose determine everything about how your system behaves under load, how it fails, and how hard it is to change six months from now.