What Complete Randomized Design Actually Looks Like When You Run It
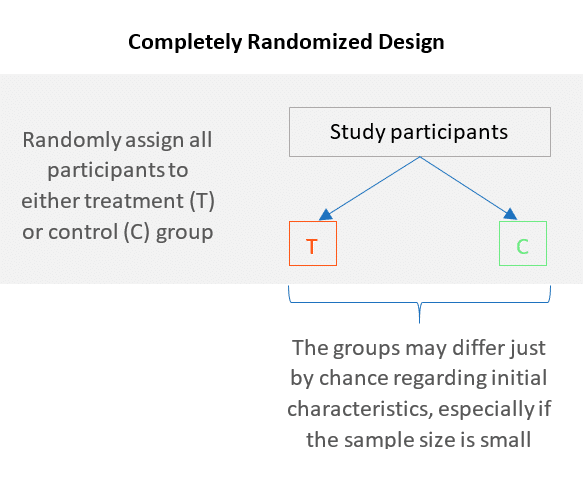
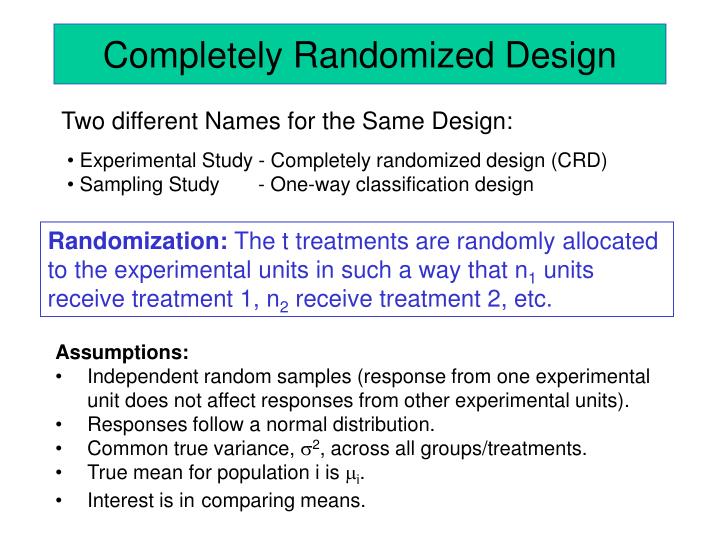
I used to think CRD was just tossing treatments into plots and calling it a day. That changed after I ran a field trial where the drainage was patchy and the "random" layout I made by hand ended up with all the high-yield fertilizer bunches on one side of the field. The statistical analysis came back with a significant treatment effect, but when I walked the rows, it was obvious the difference was water, not treatment. That's when I learned that complete randomized design isn't just a textbook definition — it's a commitment to actual randomization, not whatever your gut tells you looks balanced. At its core, CRD is the simplest experimental structure you can run. You take a homogeneous group of experimental units, assign each one to a treatment purely by chance, and measure the outcome. No blocking. No grouping. No fancy arrangement. Just treatments allocated randomly to units that are assumed to be similar enough that any remaining variation is noise. The model looks like this:
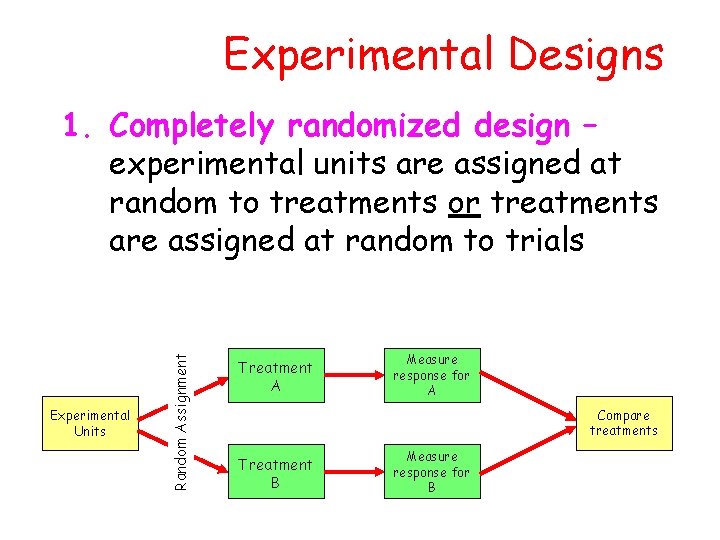
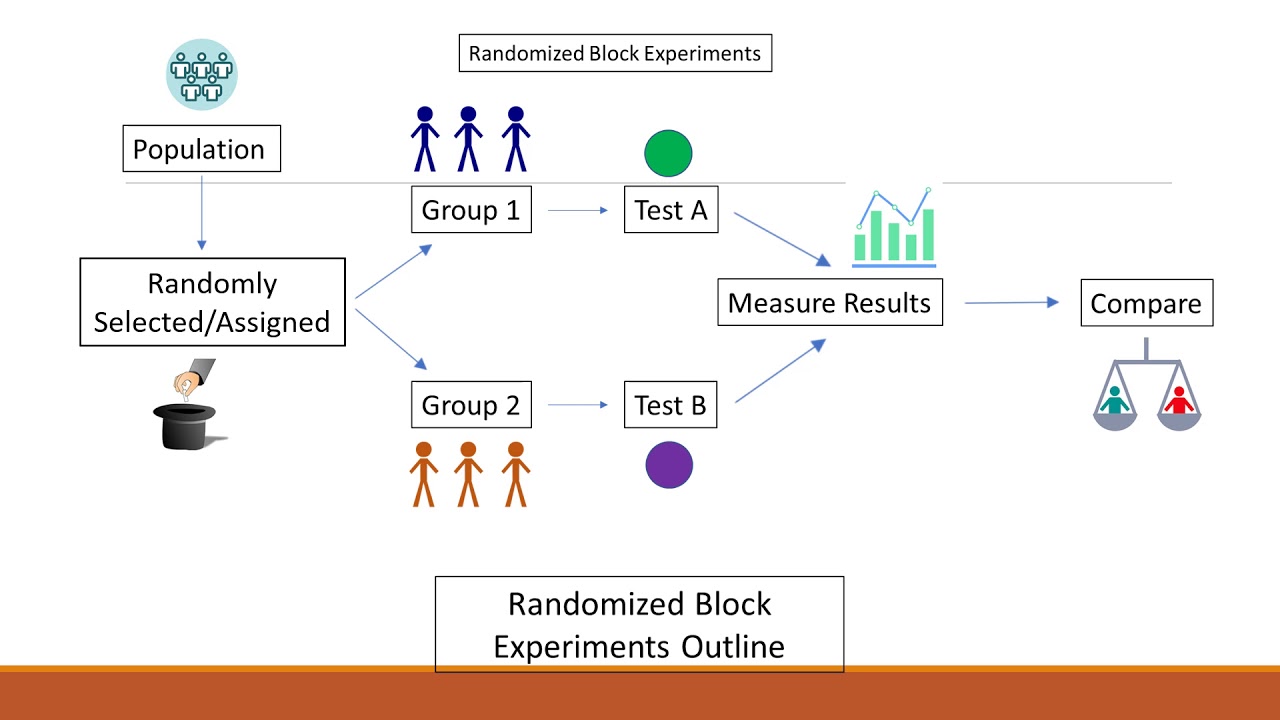
Yij = + i + ij Where is the overall mean, i is the treatment effect, and ij is the random error. The error term is what does all the heavy lifting here — it captures everything you didn't control for, which is why the assumption of homogeneity matters so much. In practice, the assignment process goes like this. Say you have 4 treatments and 20 experimental units. You write each treatment name on slips of paper, put them in a hat, and pull one out for each unit. Or you use a random number generator. The key is that every unit has an equal probability of receiving any treatment, and the assignment of one unit doesn't influence another.
How to Run It Without Messing It Up
Here's what I actually do when setting up a CRD trial. First, I figure out how many units I need per treatment. That depends on the effect size I'm trying to detect, the variance I expect, and the alpha level I'm willing to accept. A rough rule of thumb: if the coefficient of variation is below 15 percent, you can get away with fewer replications than you'd think. Above 25 percent, you need to double your sample size or you'll waste money on a trial that can't detect anything. Once I know the replication count, I generate the random allocation. I don't do this by hand anymore. I use a script that outputs something like this: Treatment | Unit
A | 3, 7, 12, 18, 20
B | 1, 5, 9, 14, 19
C | 2, 6, 11, 15, 17
D | 4, 8, 10, 13, 16
Get the Full Details

Each number is a unit, randomly assigned. The treatment letters are arbitrary — what matters is that the pattern couldn't have been predicted beforehand. Then I set up the experiment. I label each unit with its treatment code. I apply the treatments in a randomized order too, not just by plot arrangement. If I'm applying a liquid treatment by hand, I might start at plot 1 and work my way through, which introduces a time-based confound. Instead, I shuffle the application order separately from the assignment order. This is something most people skip, and it's one of the main reasons CRD trials sometimes produce misleading results. Data collection follows the same unit labels. I don't reference treatment names during collection — just unit IDs. That way I'm blind to which treatment produced which result until the analysis is done. It sounds paranoid, but I've seen publication-reable bias creep in from exactly this kind of unconscious favoritism.
The Analysis Part
After the trial runs its course, I run an ANOVA. The degrees of freedom are straightforward: treatments get t - 1 degrees of freedom where t is the number of treatments, and the error gets N - t where N is the total number of units. The F-test compares the mean square for treatments against the mean square for error. If the F-value exceeds the critical value at my chosen alpha, I reject the null hypothesis that all treatment means are equal. When the F-test is significant, I run a post-hoc test. Tukey's HSD is my default because it controls the family-wise error rate across all pairwise comparisons. If the sample sizes are equal across treatments, it's straightforward. If they're not — which happens when units are lost to mortality or contamination — I use Tukey-Kramer instead, which adjusts for the unequal n. I also check the assumptions. Residuals should be approximately normally distributed, which I verify with a Shapiro-Wilk test or a Q-Q plot. Homogeneity of variance matters too, and I run Levene's test. If the variances are clearly different across treatments, I either transform the data or switch to a Welch's ANOVA, which doesn't assume equal variances.
What People Get Wrong About CRD
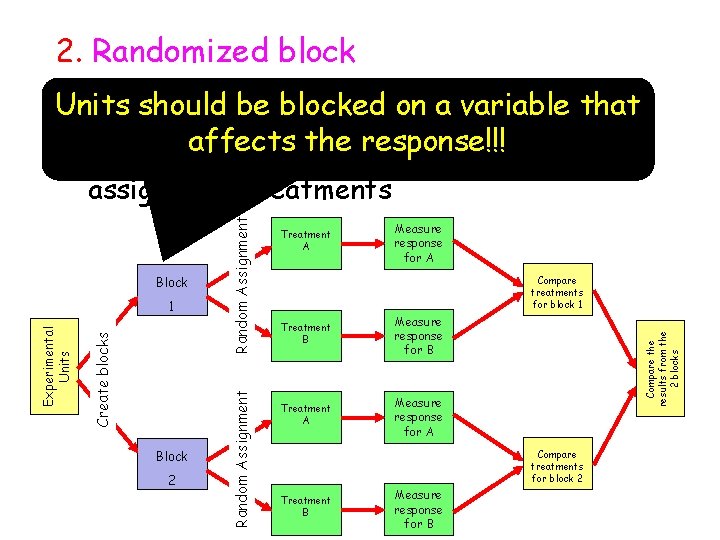
The biggest mistake I see is assuming CRD works anywhere. It doesn't. The design assumes that experimental units are homogeneous, or at least that any variation among them is random and unrelated to the treatments. If there's a gradient in the field — soil fertility sloping from one end to the other, or light intensity changing across a greenhouse bench — CRD will conflate that gradient with treatment effects. I learned this the hard way during a greenhouse experiment with seed germination. The benches had a temperature gradient of about 3 degrees Celsius from front to back. I used CRD, and the treatment that happened to land mostly on the warmer end looked significantly better. When I re-ran the experiment using a randomized complete block design with temperature as the blocking factor, the "significant" treatment effect disappeared entirely. The real takeaway from that was that the warm end just made seeds sprout faster, regardless of treatment. Another common error is under-replicating. I've seen trials with only 2 replications per treatment, which gives you almost no power to detect anything but huge effects. The error degrees of freedom are so low that even moderate treatment differences get swallowed by the noise. Four or five replications is a realistic minimum for most agricultural trials. More if the variability is high.
There's also the issue of accidental correlations. If you're measuring the same plant multiple times over a period, those repeated measures aren't independent. CRD assumes independence of observations, so repeated measures on the same unit violate that assumption. You'd need a repeated measures design or a mixed model with a random effect for unit in that case.
When CRD Actually Makes Sense
Despite its limitations, CRD is useful in specific situations. Laboratory experiments where conditions are tightly controlled — incubators, growth chambers, controlled-environment rooms — are ideal candidates. The units are naturally homogeneous because the environment is held constant. I've run dozens of CRD trials in growth chambers with microbial cultures, and they work well because the chamber maintains uniform temperature and humidity across all positions. Industrial experiments are another good fit. If you're testing different machining parameters on metal samples cut from the same batch, the material is effectively homogeneous. Randomize the order of testing, and CRD gives you clean, interpretable results. Education and training exercises also benefit from CRD because the simplicity lets students focus on understanding randomization itself rather than getting lost in complex blocking structures. It's the right starting point before moving into RCBD or Latin square designs.
My Reality Check on Sample Size
Here's something I wish I'd known earlier: power analysis for CRD is not optional if you care about the results. I ran a trial once with 3 replications per treatment across 5 treatments, which gave me 12 degrees of freedom for error. The F-test barely missed significance at alpha = 0.05. Looking back, my power was probably around 40 percent, meaning there was a 60 percent chance I'd miss a real effect even if one existed. I wasted three months of work on an underpowered design. After that, I started doing proper power calculations before running any CRD. For detecting a medium effect size (Cohen's f = 0.25) with alpha = 0.05 and power = 0.80, you typically need around 15-20 units per treatment depending on the number of treatment groups. It feels like a lot, but it's cheaper than running a trial and finding out you couldn't have detected anything meaningful.
Software Tools I Use
For randomization, I use a simple R script that generates the allocation table and saves it to a file. I never eyeball randomization — it's too easy to introduce subtle patterns without realizing it. The script ensures true randomness and creates a reproducible record of the allocation. For analysis, I use R's aov() function for the ANOVA, followed by TukeyHSD() for the post-hoc test. I also run plot(aov_model) to check residuals visually. If the residuals show a clear pattern in the residual-by-fitted plot, that's a red flag that something violated the model assumptions. For more complex situations where assumptions are violated, I switch to lm() with robust standard errors or lme4 if I need to add random effects later. CRD is simple, but real data rarely stays simple.
The Bottom Line
Complete randomized design is not complicated, but that's exactly why people underestimate it. The simplicity is both its strength and its weakness. It works beautifully when assumptions hold, and it fails silently when they don't. The design doesn't protect you from gradients, heterogeneity, or under-replication. It just gives you the simplest possible framework for evaluating treatment effects, and the responsibility for making it valid falls entirely on the experimenter. If you're designing a trial, start by asking whether your experimental units are actually homogeneous. If there's any systematic variation you can identify — soil type, light exposure, batch differences, time of day — you should consider blocking for it. If you can't identify any source of variation, or if the environment is tightly controlled, CRD is your design. Just make sure you replicate enough, randomize properly, and check your assumptions before declaring victory. The trial I mentioned at the beginning, the one where drainage created a false treatment effect — I redesigned it as a randomized complete block with drainage zones as blocks, and the results were cleaner and more reliable. The lesson wasn't that CRD was wrong. It was that I was wrong about my field being homogeneous. CRD would have been perfect if I'd recognized the gradient beforehand. That distinction matters, and it's the difference between a useful experiment and a costly mistake.