Why people build these and what they actually become
A digital journal habits tracker is simply a software-based system for recording daily behaviors, moods, and routine metrics, then visualizing the resulting patterns over time. Most people start with a flat spreadsheet or a Notion database, then layer in conditional formatting, roll-up formulas, and occasionally a simple script that nudges them to log the previous day if they missed it. The output is a dashboard that shows streaks, weekly averages, and occasional anomalies. That is the whole mechanism. I built three versions across four years. The first lived in Google Sheets, which broke every time I added more than fourteen columns and two dozen linked sheets. I migrated to Notion in 2023, then realized Notion's query engine chokes on anything beyond roughly five thousand logged rows without slowing your workspace to a crawl. I switched to a local SQLite-backed setup with a lightweight Python script, and that has been stable since. The pattern is always the same: start simple, accept that the first version will become unusable within six months, and plan the migration path before you log your first habit.
What Is Digital Journal Habits Tracker
The term itself is not a single product. It is an umbrella phrase that covers three distinct categories, and confusing them is the most common beginner mistake. The first category is a journaling-first tool where habits are secondary notes tied to dated entries. Tools like Obsidian with a daily-note plugin, day-one style apps, or even a well-structured Notion page fall here. The second category is a habits-first tracker where journaling is optional and the system is optimized for check-ins, streaks, and completion rates. Habitica, Loop Habit Tracker, and Streaks belong here. The third category is a hybrid where the journal feed and the habit grid live in the same database and share fields. This is the model most people actually want when they search for the phrase, and it is also the hardest to maintain without creating redundant data or broken relationships. If you are evaluating the category right now, your decision should come down to one constraint: do you need free-form narrative space alongside structured habit data, or do you mostly want numerical records with occasional notes. If the answer is mostly records, use a habits-first tool. If you need long-form reflection, use a journaling-first tool and add a lightweight habit table to each daily note. Trying to force a full journal into a habits-first app will make you stop logging within three weeks because the friction outweighs the reward. Under the hood, any functioning system needs a date column, a unique row per date, a set of habit fields with a consistent scale, and an optional narrative or mood column. The scale matters more than people admit. A simple yes-no toggle produces very different analytical results than a three-point scale, and switching scales halfway through a dataset makes trends almost impossible to read. I learned that the hard way when a client tried to merge a quarter of completed trackers that used different rating systems, and we spent two days writing a normalization script before anything became comparable.
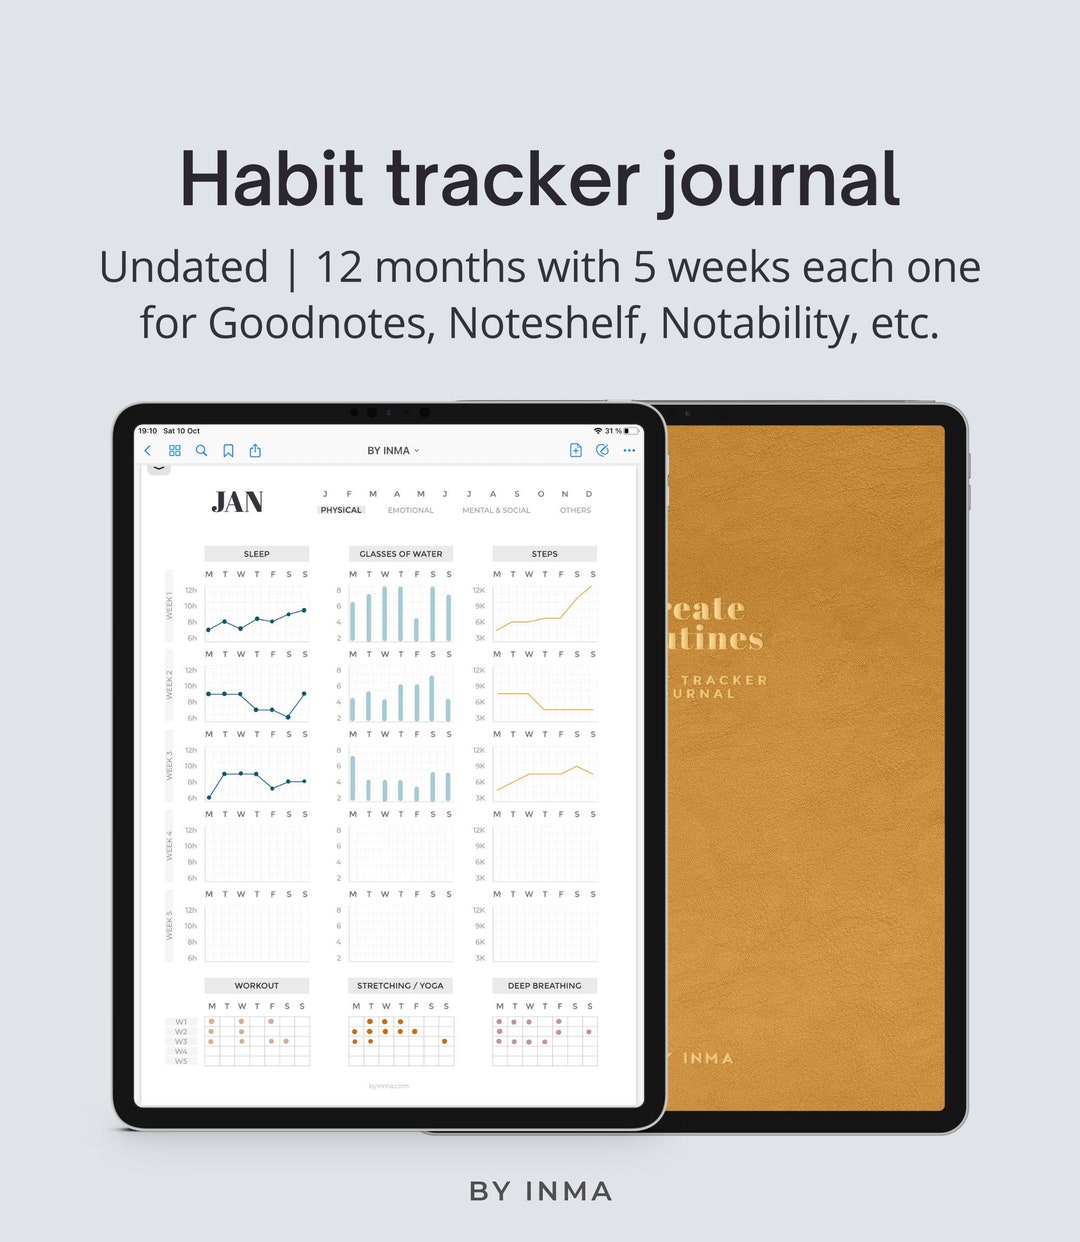
Visualization is where most people think the value lives, but it is usually the weakest point. A bar chart of weekly completion rates tells you less than a simple streak count and a monthly heat map. Heat maps work because they compress the signal into spatial memory. Red days and green days line up and the pattern becomes obvious without calculation. If your tool does not support a calendar heatmap, you are better off exporting the raw data to a spreadsheet for that view rather than fighting your app's charting engine. Automation is the second place people overspend time. A five-minute script that copies yesterday's habit values into today as defaults, marks weekends differently, or sends you a push notification at a fixed time saves about twelve minutes per week on average. That sounds small, but the benefit is not the time saved. The benefit is that you reduce the decision cost of logging. When the interface requires fewer clicks and fewer choices, you are far more likely to log on days when you feel too tired to think. This is the part that actual users underestimate. One edge case that is worth flagging explicitly: timezone drift. If you travel across zones or work late into the next calendar day, your tracker will misdate entries unless you either lock the timezone to your local zone and never change it, or you store the timestamp separately from the date field and compute the effective day in your queries. I once had a tracker that appeared to show a twenty percent drop in a habit for an entire month, and the cause was a three-hour UTC offset that made late-night entries land on the wrong day in the report queries. Relocating the date computation to a local-time function fixed it instantly.
Get the Full Details
How to build a system that does not collapse after two months
Start with a single spreadsheet or database and limit yourself to ten habits maximum. Ten is not a magic number, but it is close to the point where visual scan time begins to dominate logging time on a phone screen. Fewer than ten forces you to merge related behaviors into compound metrics, which is often exactly what you want. More than ten almost guarantees abandonment unless you are using automation to handle most of the input. Choose one storage backend and stick with it for at least ninety days. The temptation to hop platforms after the second month is real, and hopping resets your data continuity every time. If you start in Notion, stay there until the database hits four thousand rows or your queries begin timing out. If you start in a spreadsheet, stay until row-count limits or formula lag become a problem. The cost of migration is higher than most people estimate because you have to reconcile duplicate dates, re-map fields, and rebuild any custom views you created. Set a logging window that matches your actual routine, not your ideal routine. Logging at midnight sounds disciplined, but if you tend to skip nights when you are tired, a 7 p.m. to 9 p.m. window produces more consistent data because it catches the people who are actually willing to log. Consistency beats philosophical purity in habit tracking. A mediocre tracker that gets filled daily is more useful than a perfect tracker that gets filled three days a week.
Design your fields with future queries in mind. That means avoiding free-text fields where a controlled list would work, and meaningfully labeling every habit so you can still identify it six months later when the original context is fuzzy. I once renamed a habit for short-term clarity, broke every historical chart, and had to spend an afternoon rewriting the slug references across three dashboards. Use persistent identifiers from day one. Export your data weekly, even if you think you will never need it. A CSV dump takes thirty seconds and saves you from a locked-in platform or a corrupted workspace. If your tool does not support automatic export, write a simple scheduled script. I use a cron job that pulls my SQLite database into a timestamped CSV folder every Sunday night. It is background noise, and it has recovered me twice when an app update corrupted a local cache.
Pitfalls that destroy most implementations
The most common failure mode is over-tracking. People add fifteen habits, build elaborate dashboards, and then abandon the system because maintaining fifteen daily data points became a part-time job. The fix is brutal: cut the list in half and keep only the behaviors that correlate with the outcomes you care about. Sleep, movement, focused work, and hydration usually cover the high-signal core. Everything else is noise unless you have a specific reason to measure it. The second failure mode is ignoring missing data. Empty cells look clean but they corrupt averages and trend lines. Treat a blank as a non-response and exclude it from calculations, or fill it with a documented placeholder like NA. Do not let blanks propagate through your roll-up formulas silently. I ran a personal analytics pass once and got a falsely positive streak because empty cells were being treated as zero instead of missing, which made a month of inconsistent behavior look like perfect compliance in the aggregated view. The third failure mode is building complex dashboards before you have eight weeks of clean data. Dashboards look impressive in screenshots and they motivate you for about ten days, but they also create a maintenance burden that competes with actual logging. Keep your default views flat and your aggregate views simple. Add conditional formatting, pivot tables, and trend lines only after you have a baseline of complete data that you are actually using for decisions.
When a digital journal habits tracker will not work for you
This approach breaks down in a few specific scenarios, and knowing those upfront saves you from wasting weeks on a system you will discard. If you have ADHD and find repetitive data entry genuinely dysregulating, a fully manual tracker will likely collapse under its own consistency requirement. In those cases, a passive tracking layer that pulls from wearables or app usage stats, combined with a very light manual journal for context, tends to survive longer. You trade precision for sustainability, and that trade is usually worth it. If you travel across multiple time zones weekly, local-time date alignment becomes a persistent source of errors unless you invest significant effort in timezone-aware storage and reporting. Casual users rarely get this right, and the result is usually a dataset that looks reasonable at first glance but contains systematic misalignments that invalidate trend analysis. If this applies to you, consider a cloud sync solution that handles timezone normalization for you, or accept that weekly summaries will be approximate. If your goal is clinical-grade behavioral tracking, consumer tools are insufficient. The sampling frequency, validation, and data integrity requirements of clinical research exceed what most habit apps provide. In those cases, you should use a purpose-built research platform or build a custom pipeline with proper audit trails. Using a consumer tracker for that purpose will produce data that is easier to interpret than nothing, but it is not rigorous enough for serious analysis.
Here is a practical recommendation if you want to start without overcommitting. Build a single-table SQLite database with columns for date, habit identifier, value, note, and timezone. Use a simple Python script to insert daily rows and export a weekly CSV. Create one query that returns a ninety-day heatmap and one query that returns rolling seven-day averages. That is enough to see real patterns without turning the system into a side project. Anything beyond that should only exist if the extra complexity is driving a decision you actually make. The reason most people fail with these systems is not the tool. It is the mismatch between the tracking design and their actual capacity for daily maintenance. Design for the lowest consistent effort you can sustain, not for the ideal workflow you imagine having. The data you actually collect beats the data you planned to collect every time.