DNA Replication Basics for People Who Actually Need to Understand It
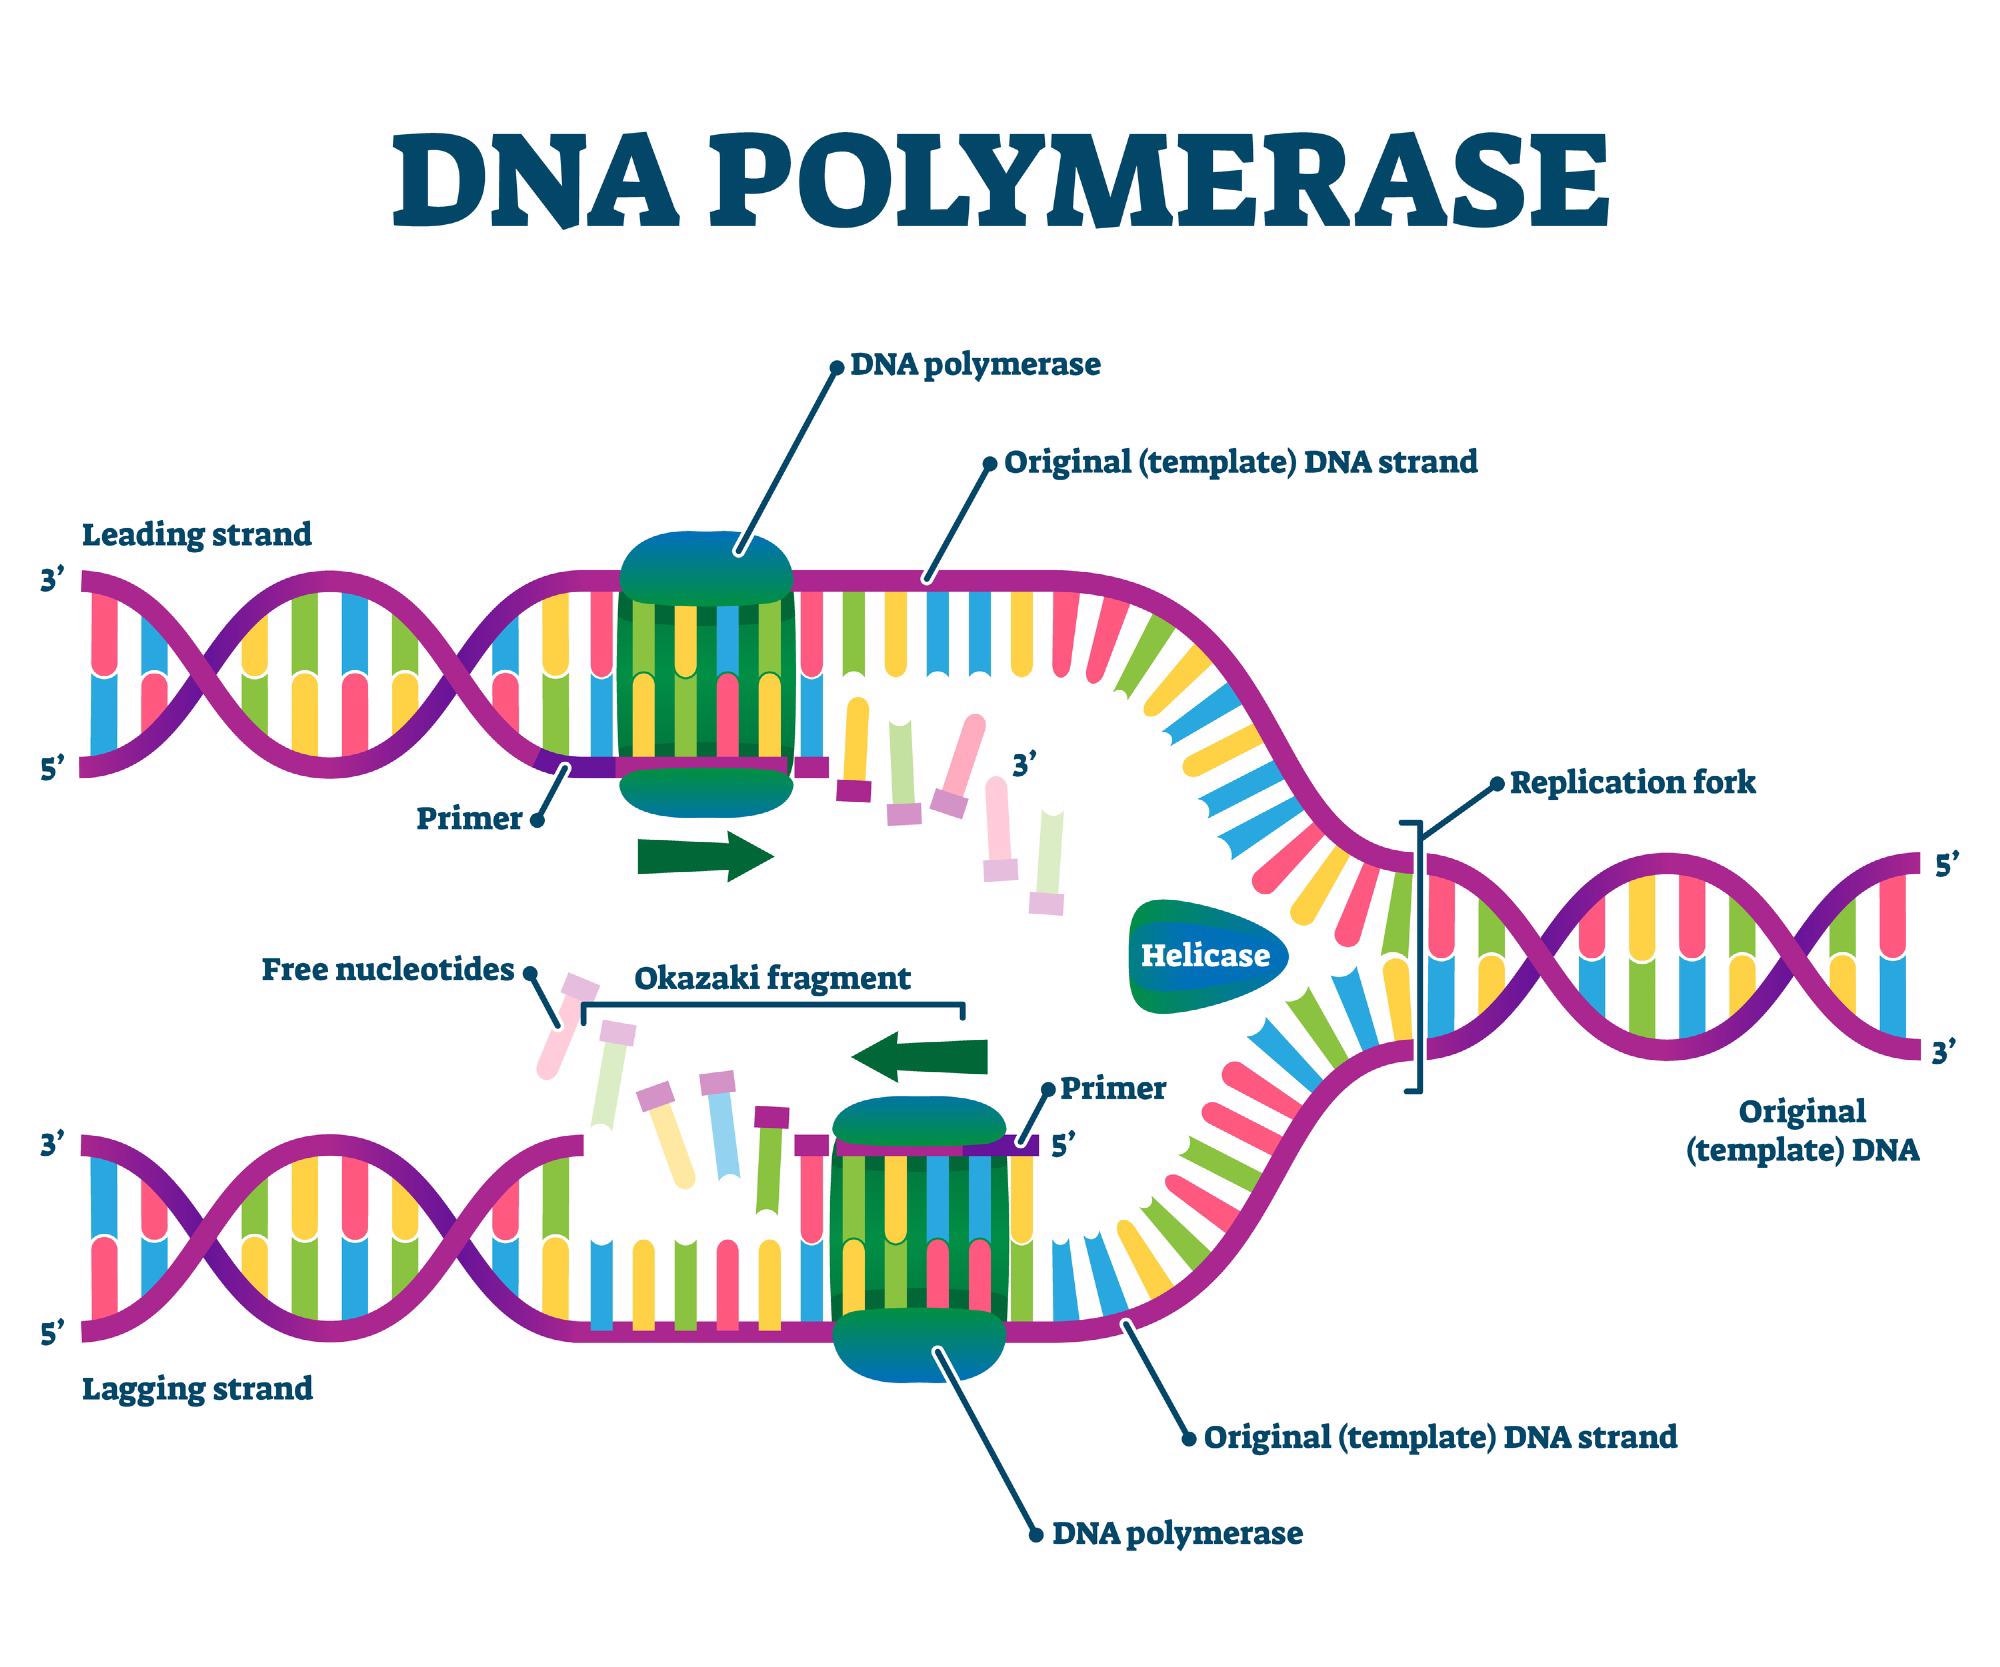
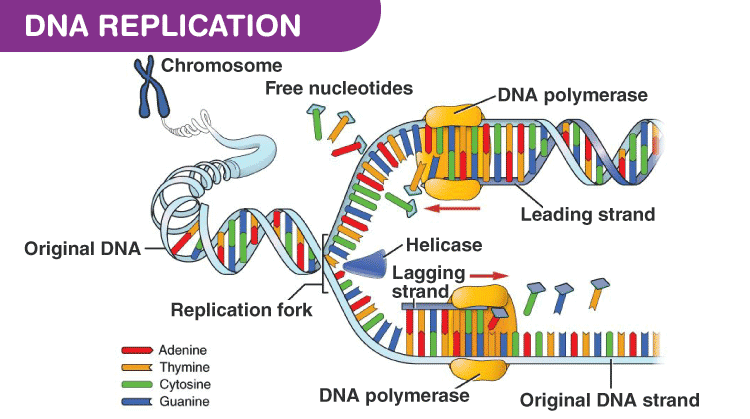
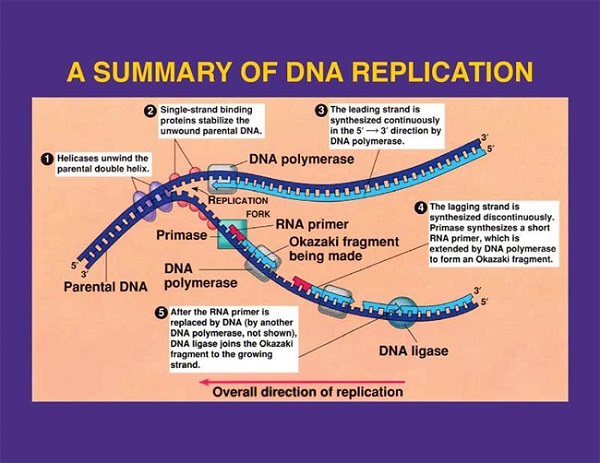
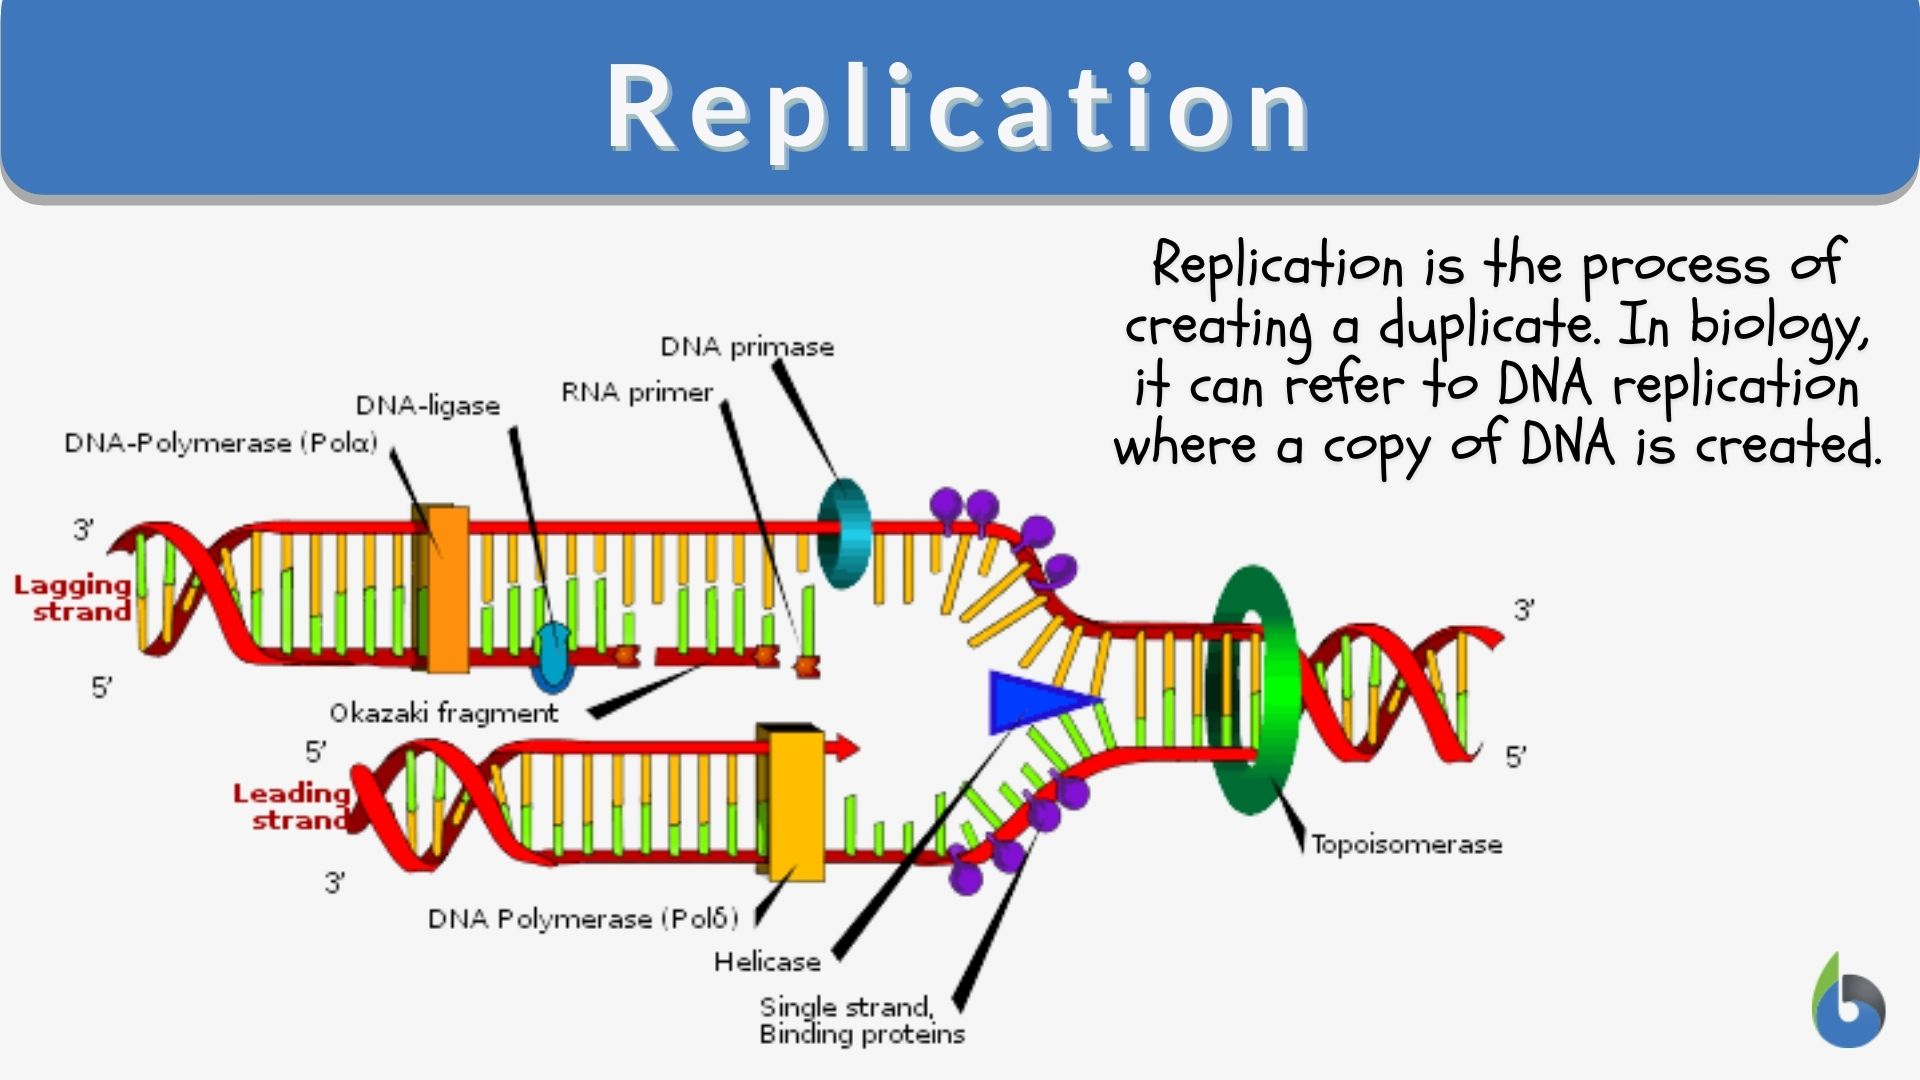
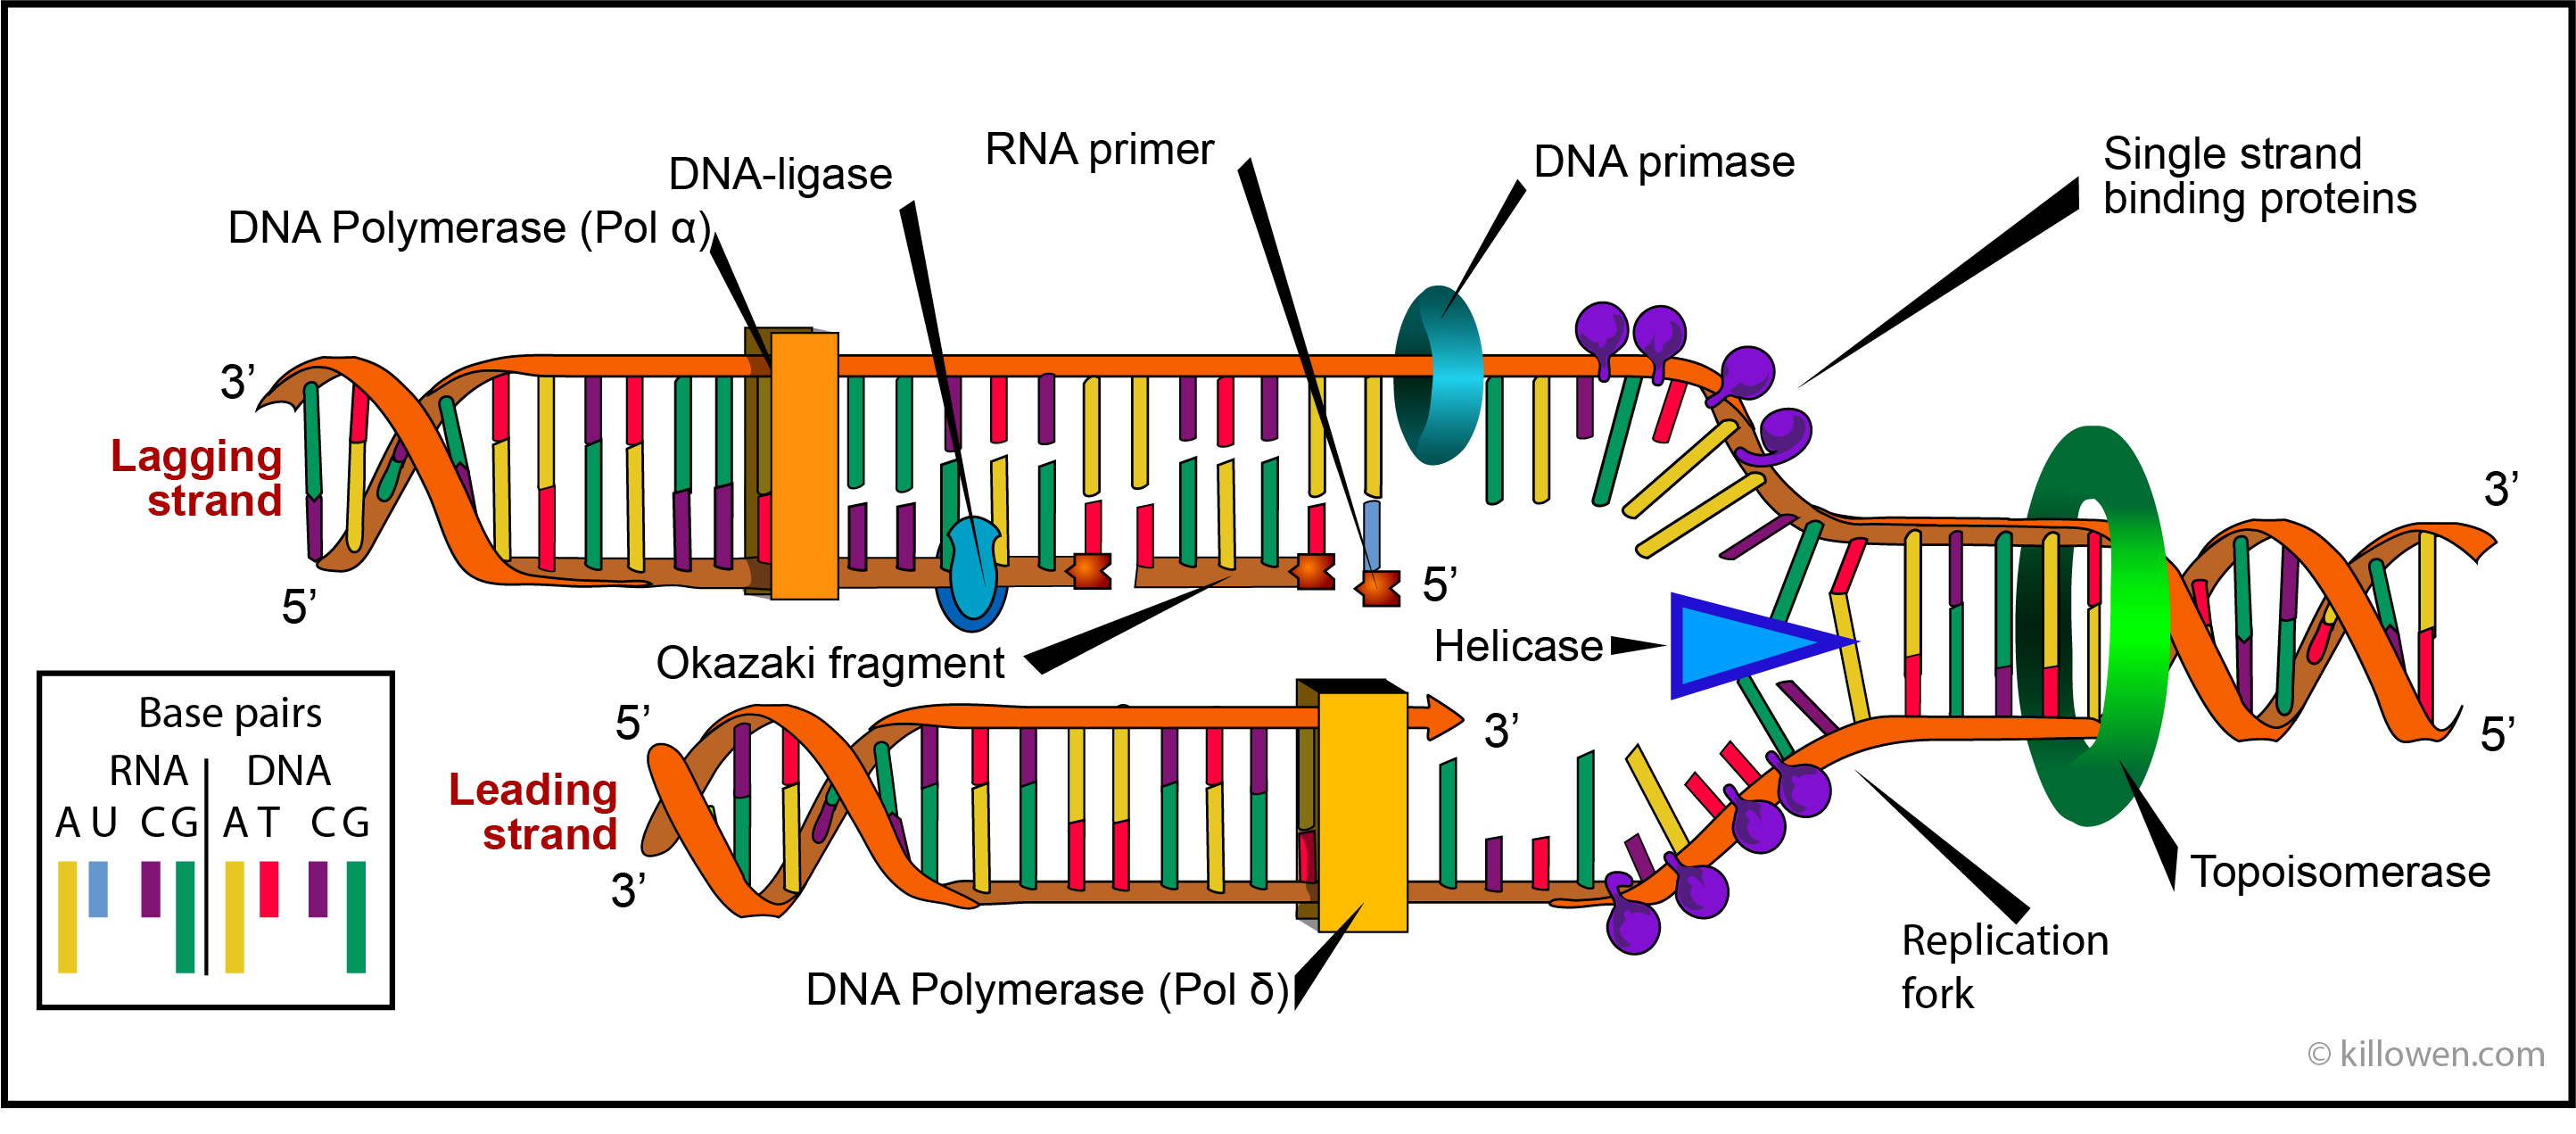
DNA replication is the process by which a cell makes an exact copy of its entire genome before dividing. The double helix unwinds, each strand serves as a template, and new complementary strands are synthesized. That is the textbook version. The reality involves a choreography of enzymes that has to stay synchronized across millions of base pairs or the whole thing falls apart. The machinery is not complicated in concept, but it is fussy. Helicase unwinds the DNA at the origin of replication. Single-strand binding proteins keep the strands from snapping back together. Topoisomerase relieves the supercoiling tension ahead of the fork, which is where things can go wrong if you are working with a plasmid prep that is nicked or overly constrained. Primase lays down an RNA primer because DNA polymerase cannot start from scratch. It can only add nucleotides to an existing 3' hydroxyl group. On the leading strand, synthesis proceeds continuously toward the replication fork. On the lagging strand, it goes the other way in short fragments called Okazaki fragments. DNA polymerase III does the heavy lifting in bacteria, and in eukaryotes it is pol delta and pol epsilon. DNA polymerase I removes the RNA primers and replaces them with DNA. Ligase seals the nicks between fragments. That is the whole pathway, stripped down to what actually matters.
I spent a lot of time troubleshooting replication timing issues when I was doing early molecular cloning work. One particular problem stood out. I was running a rolling circle amplification setup to generate single-stranded DNA templates, and the yield was consistently garbage. Turns out the source DNA had methylation patterns that were blocking the strand displacement activity of the polymerase. The workaround was straightforward: switch to a dam/dcm methylase-deficient E. coli strain for plasmid propagation and use a thermostable polymerase with strand displacement capability instead of the standard Klenow fragment. Yield jumped from nearly nothing to microgram quantities in a single afternoon. One thing people routinely miss is that replication is asymmetrical in ways that matter for sequencing and cloning. The leading and lagging strands have different error rates. In E. coli, the mismatch repair system biases toward the newly synthesized strand by detecting transient methylation at GATC sites, but this only works during a narrow window after synthesis. If you are doing high-fidelity cloning, that timing window is relevant because misincorporations near origins can persist if repair has not caught up. Another counter-intuitive point is that more origins does not always mean faster replication. Eukaryotic cells fire a subset of their thousands of potential origins each cycle, and the timing of origin firing is cell-type dependent. Stress conditions, nucleotide depletion, or checkpoint activation can silence entire clusters of origins. When I worked on replication timing profiles in mammalian cell lines, the early-firing origins were remarkably consistent across replicates, but the late-firing ones were noisy and varied by culture conditions. This matters if you are correlating replication timing with gene expression patterns, because late-replicating regions are not just late, they are also enriched for heterochromatin marks and repeat sequences that complicate assembly.
The replication fork is also a vulnerability. When it encounters a DNA lesion, it stalls. Translesion polymerases like Pol IV and Pol V in bacteria can bypass damage, but they do so error-prone. In eukaryotes, Pol eta, Pol kappa, and Pol iota serve similar roles. The tradeoff is survival versus fidelity. Bypassing a thymine dimer with Pol eta is relatively accurate, but bypassing certain bulky adducts with other translesion polymerases introduces mutations at rates that are orders of magnitude higher than the replicative polymerases. For anyone actually running replication assays, I would note that the bromodeoxyuridine incorporation method is still widely used but has significant limitations. It only tells you about S-phase entry and overall DNA synthesis rates, not fork speed or origin usage. If you need mechanistic detail, bromodeoxyuridine alone will not give it. DNA combing or smFIR (single-molecule analysis of replicated DNA) is more informative, but it requires specialized equipment and skills. The standard EdU click-chemistry approach sits somewhere in between and is usually sufficient for most lab purposes. Replication also intersects with chromosome segregation in ways that are easy to overlook. In bacteria, the origin region is actively partitioned to opposite poles during replication, a process mediated by ParABS systems. If you are engineering a synthetic origin or working with artificial minichromosomes, simply getting the sequence right for replication is not enough. You also need proper partitioning machinery, or the plasmid will be lost at a high rate even if it replicates fine. I saw this firsthand with a custom mini-F bacterial artificial chromosome that replicated well in selection but was lost within ten generations once selection pressure was removed.
Get the Full Details
The bottom line is that DNA replication is a well-characterized process, but the details that matter for any practical application depend heavily on the organism, the specific DNA substrate, and the cellular context. The textbook gives you the framework. The edge cases are where you learn what actually breaks.