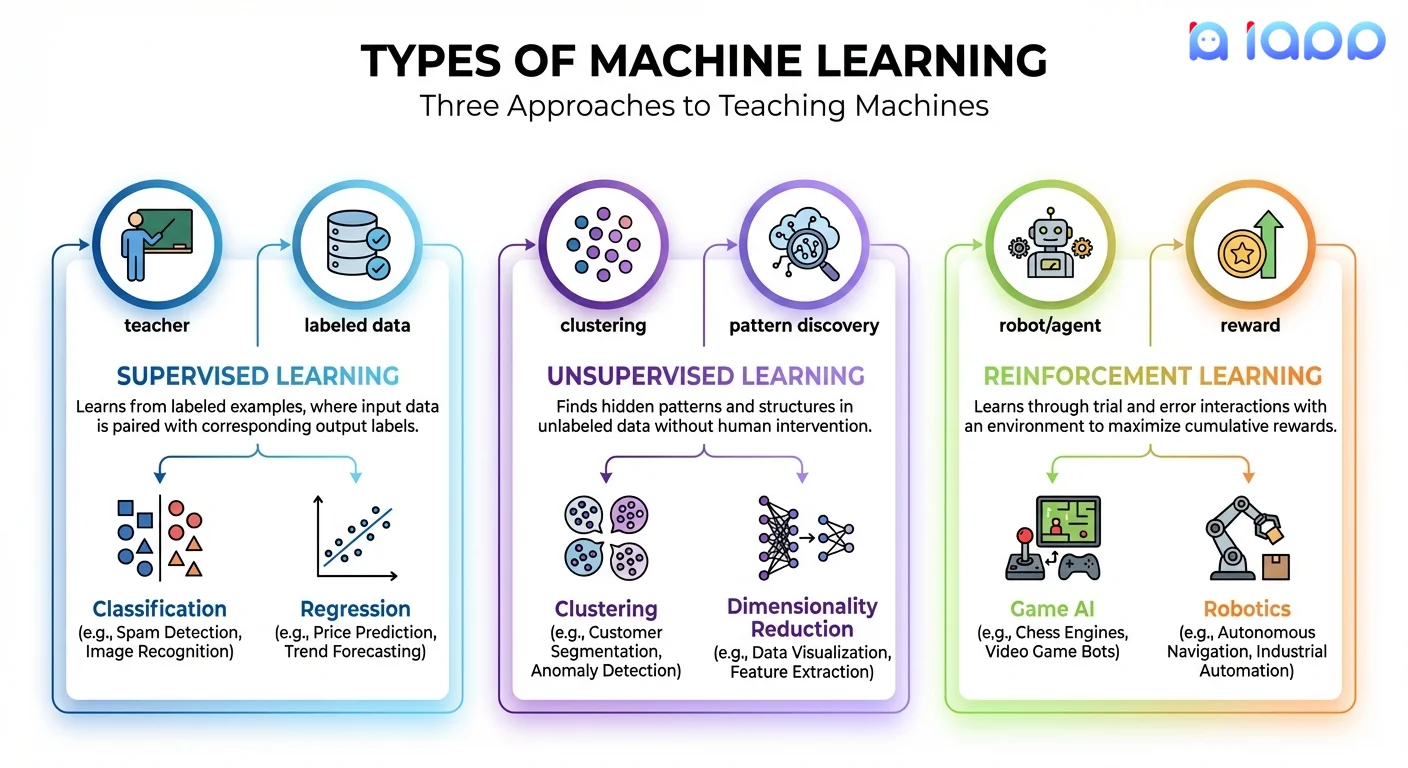
Machine Learning isn't magic. It's engineering.
Most people think ML is about writing deep neural networks and training massive models. That's a tiny slice of what actually happens. The real work is cleaning data, understanding what your features mean, and figuring out why your model keeps making the same stupid mistake on Tuesday afternoons. I've been doing this long enough that I still don't trust my own models until they've been wrong in production for at least three weeks. There's something about seeing a model fail in ways you didn't predict that teaches you more than any tutorial ever will.
What Is Guide For Machine Learning
A guide for machine learning is really just a structured path through a problem space that has no fixed solution. You start with a question, gather data that might answer it, pick a tool that might work, and then spend most of your time debugging the things that went wrong. The "guide" part is usually someone else mapping out the steps so you don't walk into every pitfall on your own. Here's the thing most guides leave out: the workflow is rarely linear. You'll fit a model, check the results, realize your features are garbage, go back and fix them, re-fit, and then spend three days tuning hyperparameters that won't actually improve your validation score by more than 0.3 percent. I learned this the hard way on a churn prediction project back in 2019. We had a XGBoost model hitting 94 percent accuracy on our test set, which we celebrated prematurely. Two months later it was performing at 61 percent in production because the training data had a time-based leak — we were accidentally including features that only existed after the event we were trying to predict. The fix wasn't complicated. It was reshuffling the feature engineering pipeline to respect chronological order and using time-series cross-validation instead of random splits. Took about four hours once I figured out what was happening.
Getting Started Without Losing Your Mind
Install Python, preferably through conda or miniconda. Don't skip the virtual environment thing — I know it feels like extra steps, but untangling dependency conflicts between pandas, numpy, and scikit-learn versions is a special kind of hell that nobody needs. Your first practical stack should be scikit-learn for classical models, pandas for data manipulation, and matplotlib or seaborn for visualization. That's it. You don't need PyTorch or TensorFlow for your first few projects. They're useful later. Starting there just adds cognitive load you don't need yet. Here's a basic workflow that actually works:
Get the Full Details
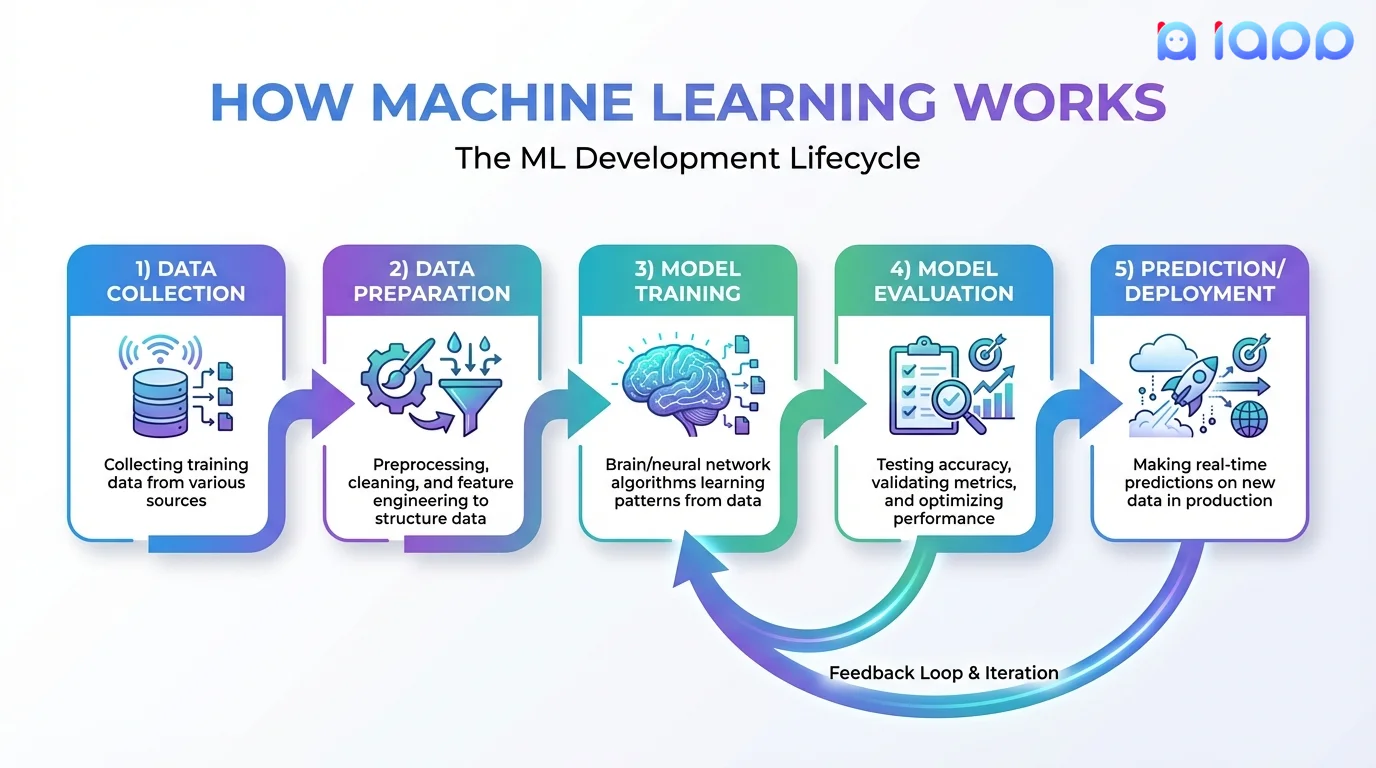
Load your data. Check for missing values. Understand what each column represents. Don't impute blindly — if 40 percent of a feature is missing, that might be information in itself. Split your data with stratification if you're doing classification. Fit a simple baseline model first, like logistic regression or a shallow decision tree. Evaluate it honestly. Then move to something more complex only if the baseline can't capture the pattern. Feature engineering is where most people stall out. It's also where the actual domain knowledge matters. A well-constructed interaction term between two mediocre features can outperform a fancy model with raw inputs every time. I once replaced a gradient boosting classifier with a logistic regression model plus three hand-crafted features and got better AUC on a fraud detection task. The engineers who built the original system couldn't believe it.
Common Pitfalls That Waste Weeks
Data leakage is the silent killer. It happens when information from the target variable indirectly gets into your features. This includes things like future data in time series, duplicate rows across train and test splits, or aggregated features computed before the split. Always split first, then fit your scalers and encoders on the training set only, then transform the test set. Never reverse that order. Overfitting to the validation set is the second most common issue. You tune hyperparameters repeatedly until your validation score looks great, but your test performance tanks. The workaround is nested cross-validation or, more practically, keeping a holdout set completely untouched until the very end. Treat it like the final exam. You don't get to study for it. Scaling matters more than people admit. Neural networks and SVMs are sensitive to feature scales. Tree-based models aren't, which is why random forests and gradient boosting can skip that step. But if you're using PCA or k-means clustering as part of your pipeline, unscaled data will produce garbage results because distance calculations become meaningless when one feature ranges from 0 to 1 and another from 0 to 1000000.
Another thing nobody warns you about: categorical features with high cardinality. Encoding a feature with 500 unique categories using one-hot will blow up your feature space. Target encoding or embedding layers help, but they introduce their own leakage risks if not done inside a cross-validation fold. I use a combination of CatBoost encoding with a regularization parameter for this, which handles high-cardinality categoricals relatively gracefully without the explosion.

When to Move Beyond Classical Methods
Deep learning becomes worth the effort when you're working with unstructured data — images, audio, raw text — or when you have enough data that the extra capacity of neural networks pays off. Tabular data, which is what most real-world business problems involve, is surprisingly well-handled by tree ensembles. LightGBM and XGBoost have been the workhorses of Kaggle competitions for years, and for good reason. The tradeoff is interpretability. A random forest with 100 trees doesn't explain itself the way a linear model does. SHAP values can approximate explanations, but they're approximations. If your stakeholders need to understand why a decision was made, a simpler model with a few meaningful features often beats a black box with higher accuracy. Especially in regulated industries where explainability isn't optional. Training times scale poorly too. A gradient boosting model on a million-row dataset might take twenty minutes. A similar-sized neural network could take hours on the same hardware. That matters when you're iterating and you need to run dozens of experiments in a day.
Practical Resources That Actually Help
Scikit-learn's documentation is genuinely excellent. Their user guide covers the math without drowning you in it, and the API is consistent enough that once you learn one model, you understand most of the others. The examples section alone is worth bookmarking. For deeper theory, Kevin Murphy's "Machine Learning: A Probabilistic Perspective" is thorough but dense. Good for reference, overwhelming for a first read. If you want something lighter, "Hands-On Machine Learning with Scikit-Learn, Keras, and TensorFlow" by Aurélien Géron is practical and covers the real workflow from data prep to deployment without skipping the messy parts. Fast.ai's course is free and starts with practical code before explaining the theory underneath. That reverse engineering approach works well for people who learn by doing, which is most of us. The catch is that without the theoretical foundation, you'll struggle when things don't go according to plan. And they never do.
The Hard Truth About Learning ML
You'll spend more time reading error messages and debugging pipelines than you will actually training models. A shape mismatch in a tensor can cost you an hour. A subtle bug in your data loader can waste a whole day. This is normal. Every single person doing this work has a folder full of half-finished notebooks and models that failed for reasons that seem obvious in hindsight. The skill that separates people who ship ML projects from those who don't isn't knowing every algorithm. It's knowing how to diagnose failure, how to read a confusion matrix and understand what's actually going wrong, and how to decide when a model is "good enough" for the problem at hand. Most production systems don't need 99 percent accuracy. They need something that's reliably better than the current process and doesn't break when the data distribution shifts slightly. Data drift will happen. Your model will degrade over time. Setting up monitoring for feature distributions and prediction stability is as important as the model itself. I've seen models deployed and then forgotten until someone noticed six months later that predictions had become effectively random because the underlying data patterns had changed. Automated retraining pipelines or at minimum scheduled performance checks prevent this.

The field moves fast. New papers come out daily. You don't need to read them all. Focus on building things, breaking them, and understanding why. That's the guide that actually works.


