The Real Composition of Nucleic Acids
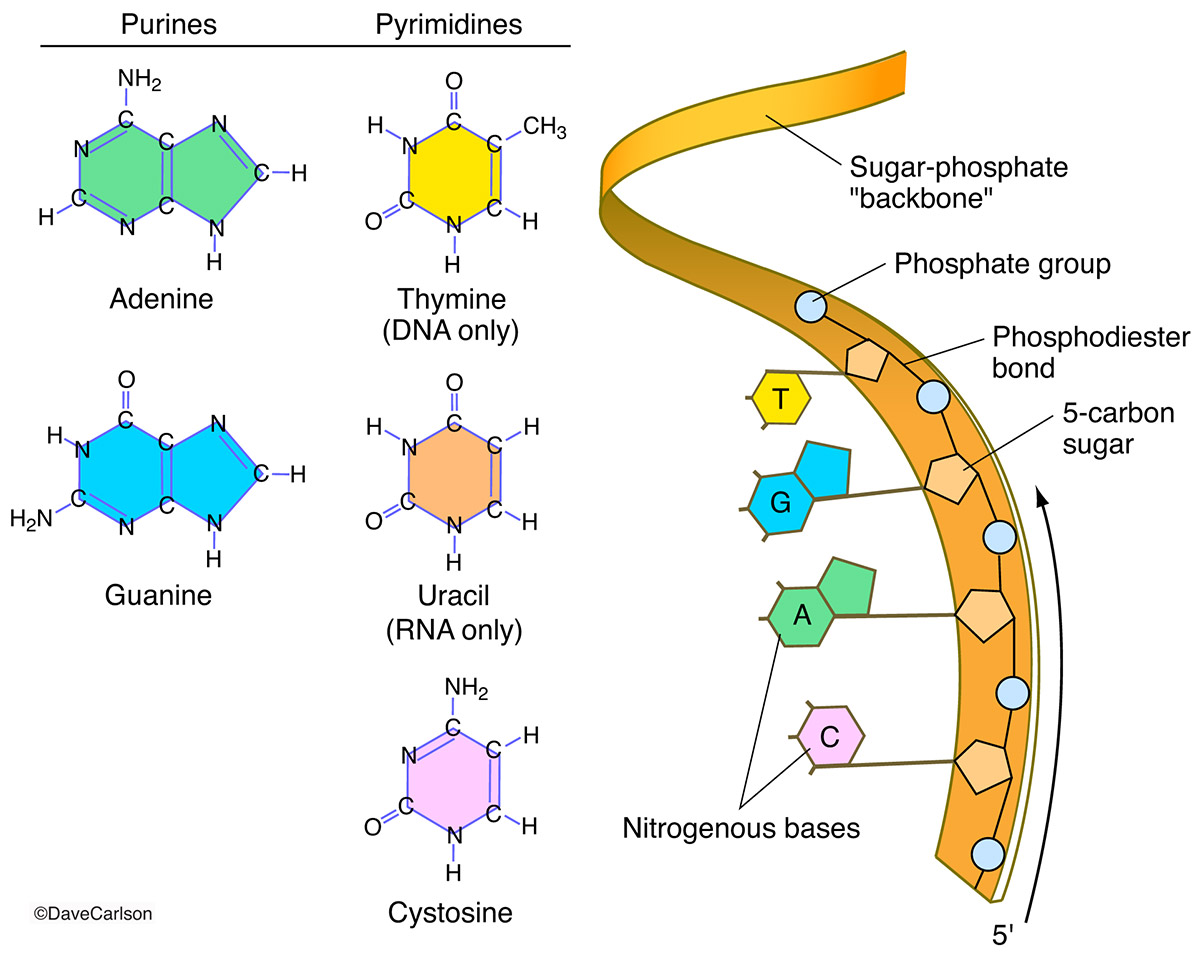
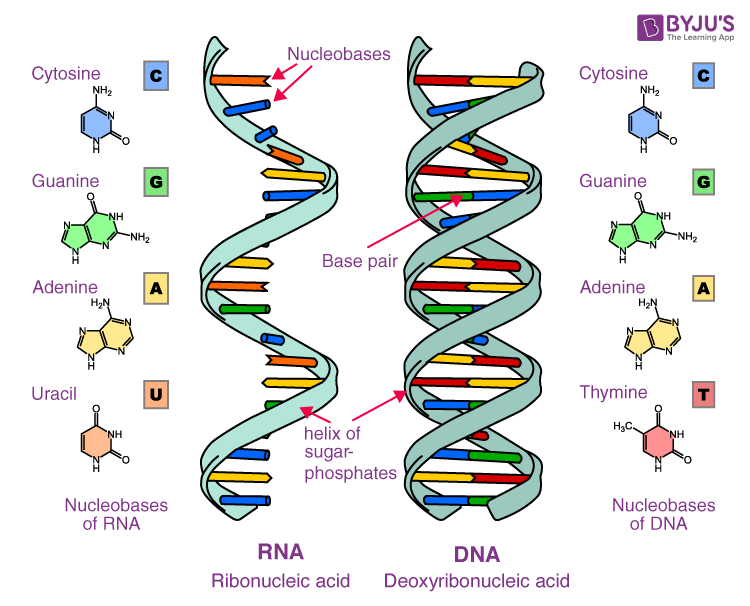
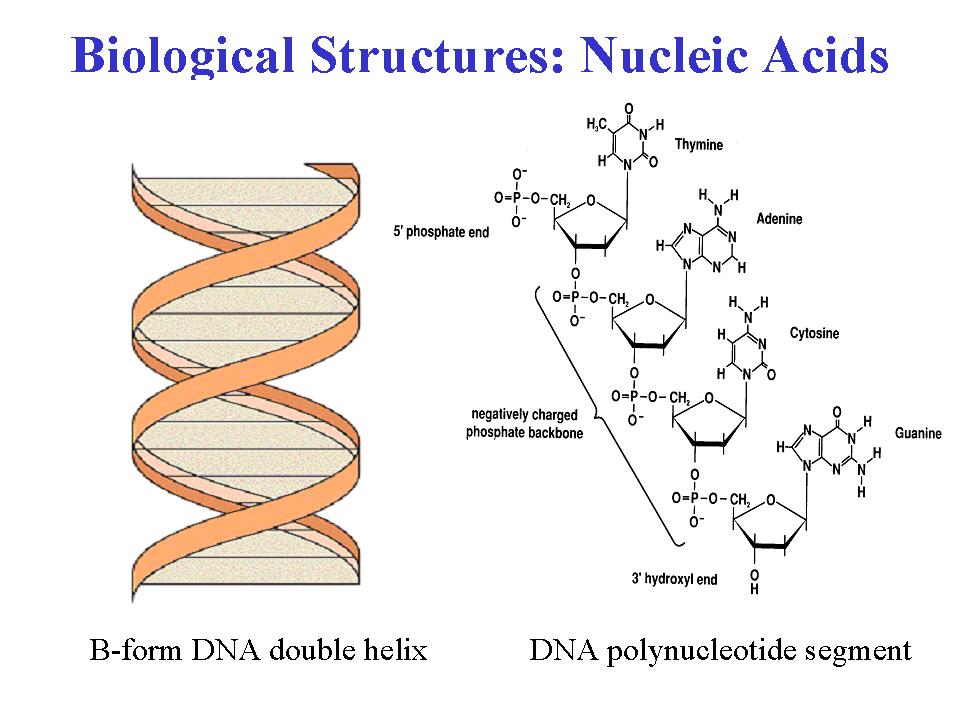
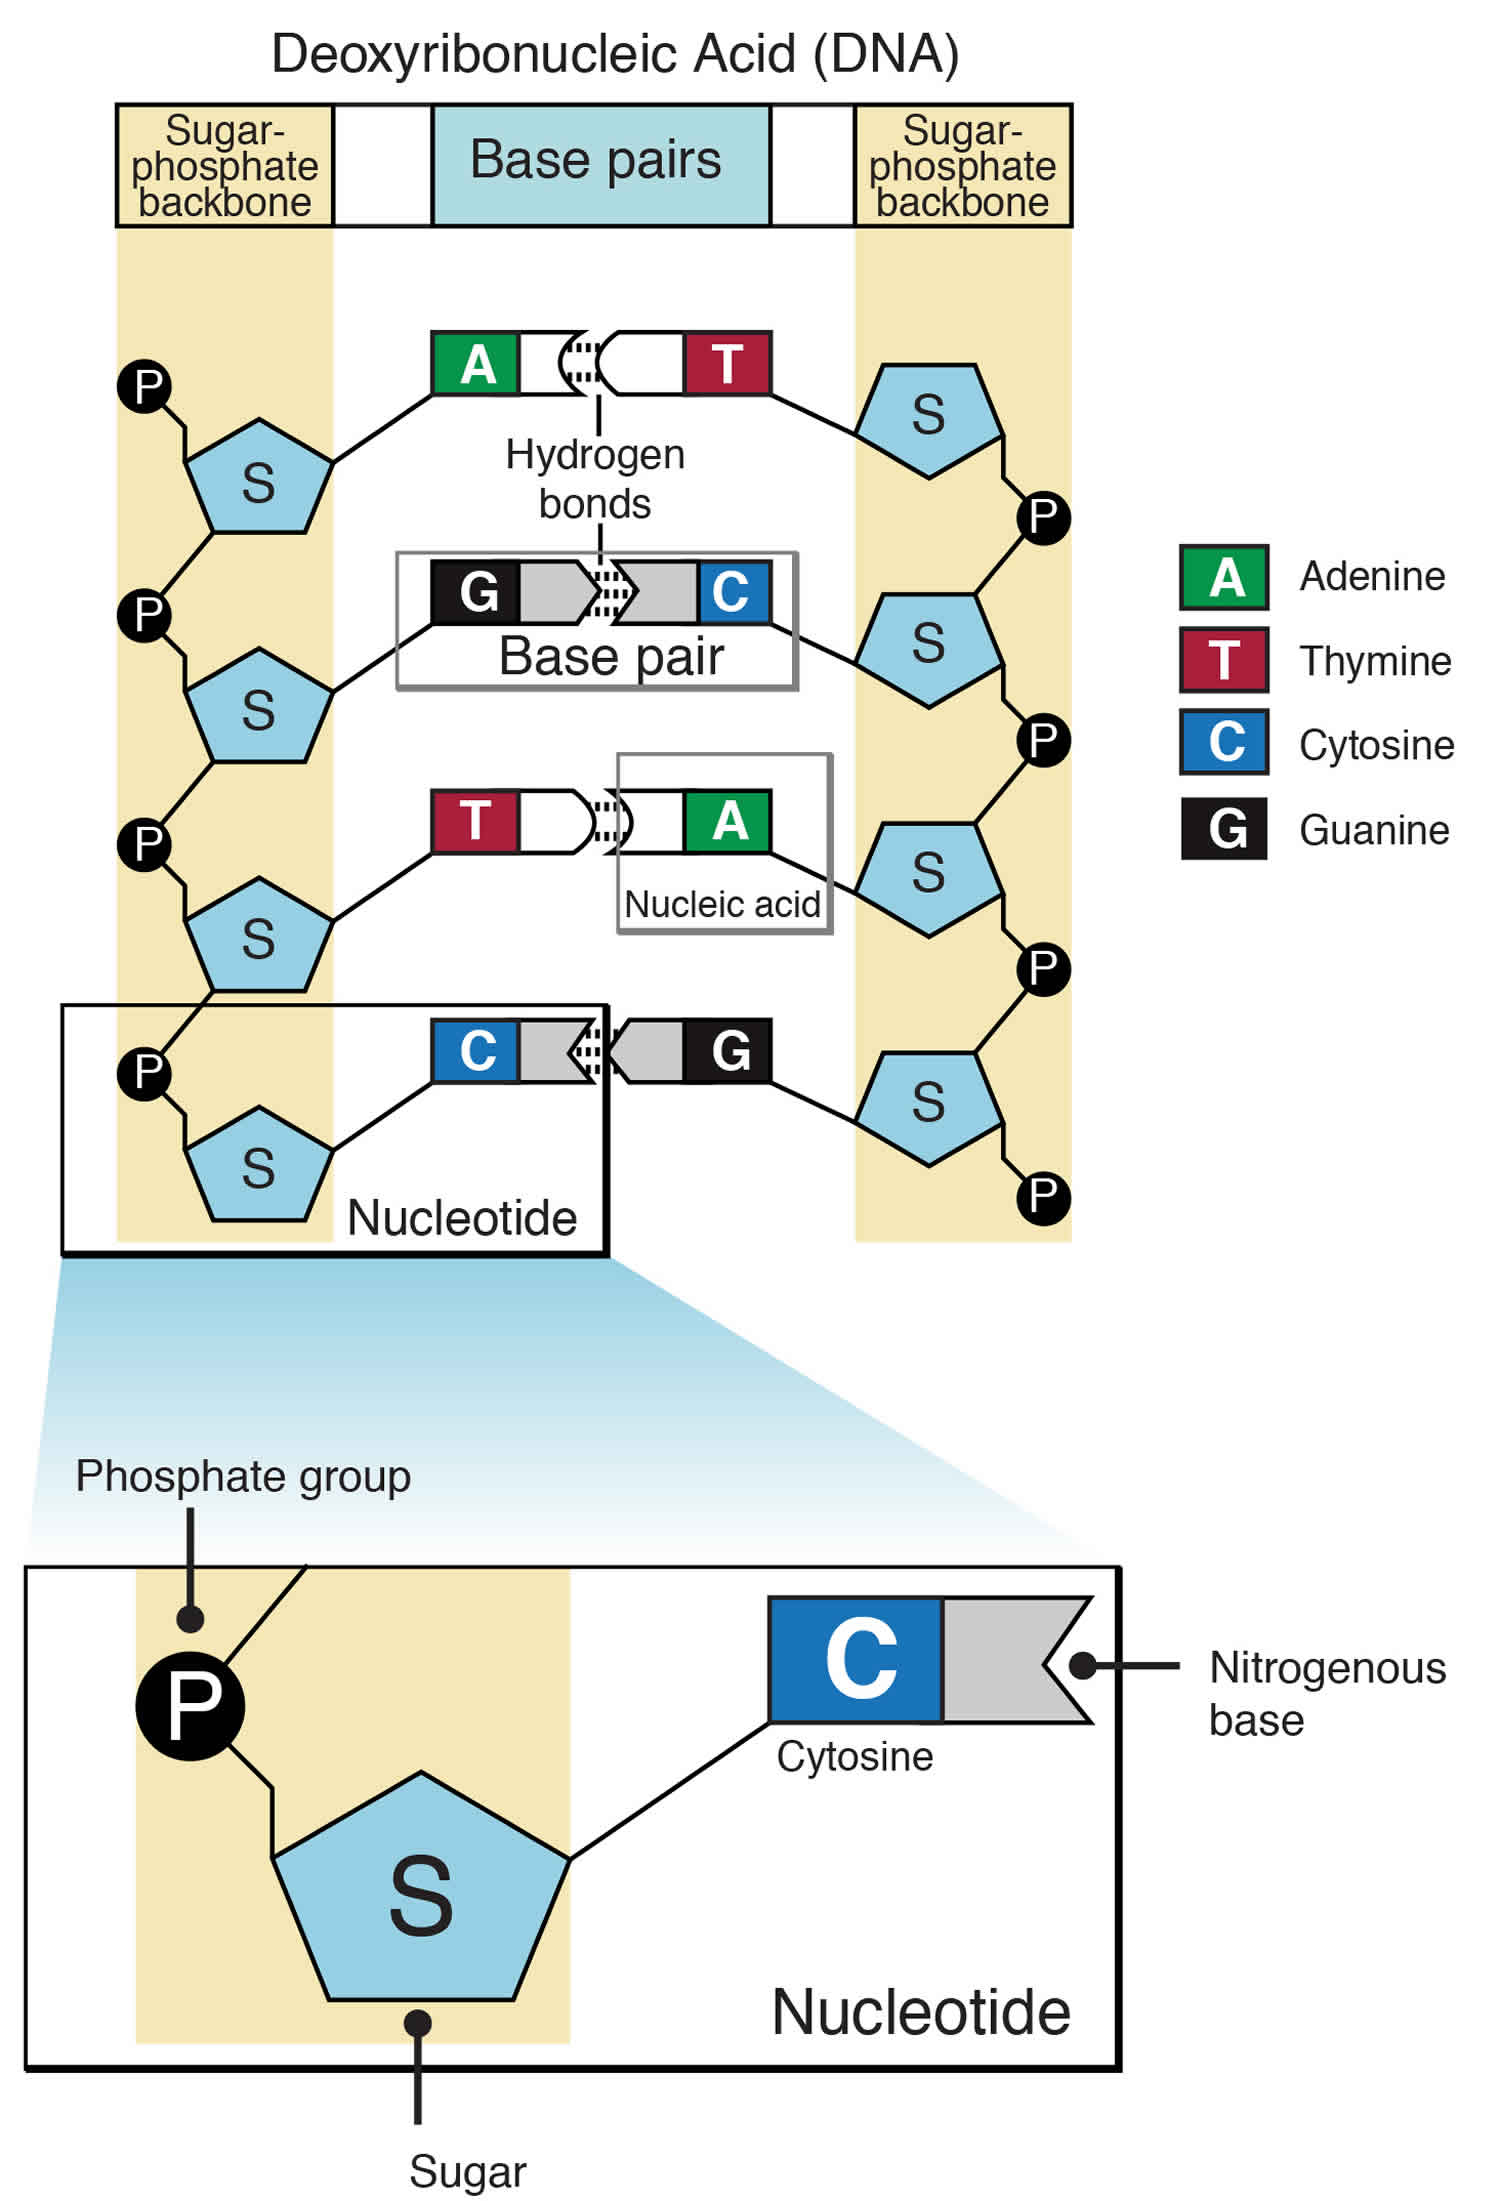
Nucleic acids are polymers made from nucleotide monomers, and when people ask what is in nucleic acids, they usually get a simplified three-part answer: a sugar, a phosphate group, and a nitrogenous base. That's correct but incomplete for anyone who actually works with them in a lab or needs to understand how they behave under real conditions. Each nucleotide contains a five-carbon pentose sugar, a phosphate group attached to the 5' carbon, and one of several nitrogenous bases attached to the 1' carbon. The difference between DNA and RNA comes down to a single oxygen atom: DNA has deoxyribose (missing an OH at the 2' position), while RNA has ribose. That missing oxygen matters more than textbooks let on. It's the reason RNA is far less stable in alkaline conditions and why RNases have been such a persistent headache in my experience. The nitrogenous bases split into two categories. Purines—adenine and guanine—are double-ringed structures. Pyrimidines—cytosine, thymine, and uracil—are single-ringed. DNA uses A, G, C, and T. RNA swaps thymine for uracil. The pairing rules (A with T/U, G with C) are foundational, but the actual geometry of those pairs in the double helix creates a major groove and a minor groove, and those grooves are where proteins actually read the sequence. If you're doing anything involving protein-DNA interaction, ignoring the groove geometry means you're flying blind.
Phosphate groups link the 3' carbon of one sugar to the 5' carbon of the next through phosphodiester bonds. That's the backbone. Directionality runs 5' to 3', and every enzymatic process that touches nucleic acids respects that orientation. Polymerases add nucleotides only to the 3' end. Reverse transcriptase does the same. Primers are always designed and read 5' to 3'. Get this wrong and your whole experiment falls apart, usually in ways that take hours to diagnose.
The Practical Reality of Working With Nucleic Acids
I spent years running extraction and purification protocols, and the first thing I learned is that nucleic acids are not stable objects. They degrade. DNA gets sheared by physical force. RNA gets chewed up by enzymes that are everywhere—on your skin, in the dust, on the surface of almost anything you touch without thinking about it. The phosphate backbone is chemically vulnerable to hydrolysis, especially at extreme pH or high temperature. One specific problem that cost me a lot of time: I was working with a template that had an unusual GC-rich region, and standard primer design software kept giving me primers that wouldn't anneal properly. The software was calculating melting temperatures based on simple nearest-neighbor models that didn't account for the secondary structure the GC clumps were forming. The workaround was running a structural prediction tool like mfold or UNAFold on the target region before designing primers, then deliberately placing primers outside the predicted hairpin zones. That cut our failed PCR attempts from about 60 percent down to roughly 10 percent. Another thing people don't always appreciate: modified bases exist. Methylation of cytosine at the 5' position (5mC) is a major epigenetic mark in eukaryotic DNA. Inosine shows up in tRNA and sometimes in RNA sequencing artifacts. Pseudouridine is the most common modified nucleotide in RNA. These modifications change hydrogen bonding properties, alter protein recognition, and can completely throw off standard sequencing protocols if you're not expecting them. Bisulfite sequencing is the standard way to detect methylation, but it degrades your DNA significantly—usually losing 50 to 90 percent of input material depending on conditions. That's a real constraint if you're working with limited samples.
Get the Full Details
What Actually Makes Up the Molecule
By elemental composition, nucleic acids contain carbon, hydrogen, oxygen, nitrogen, and phosphorus. The phosphorus content is what makes them distinguishable from proteins and carbohydrates in basic biochemical assays. The classic diphenylamine test detects DNA specifically by reacting with the deoxyribose sugar. The orcinol test targets RNA's ribose. Neither is used much in modern labs, but they illustrate that the sugar component is as important as the bases for identification purposes. The molar ratios follow Chargaff's rules in double-stranded DNA: adenine equals thymine, guanine equals cytosine. This holds for double-stranded DNA but breaks down completely in single-stranded DNA, RNA, or any non-B-form structure. I've seen people apply Chargaff's rules blindly to sequencing data and draw incorrect conclusions about genome composition. The rules are a consequence of base pairing, not a universal law of nucleic acid chemistry. Ion binding is another practical consideration. The negatively charged phosphate backbone attracts cations—sodium, potassium, magnesium. Magnesium is especially critical because it's a cofactor for nearly every nucleic acid enzyme. Polymerases, ligases, nucleases all require Mg2+. When you're running a reaction and it fails, checking the magnesium concentration is often more productive than redesigning primers. I've seen protocols fail because someone used EDTA-containing water that chelated the magnesium, or because the buffer formulation had an imbalanced salt concentration. The nucleic acid itself was fine. The chemistry around it was the problem.
Limitations and Where This Understanding Falls Short
Describing nucleic acids as just sugar-phosphate-base polymers misses the structural diversity that actually determines function. G-quadruplexes form in GC-rich regions, especially near telomeres and promoter sequences. Z-DNA exists as a left-handed alternative to the standard B-form. A-DNA appears under dehydrating conditions. These alternative conformations have real biological consequences—G-quadruplexes can block replication and transcription, and stabilizing them with small molecules is an active area of cancer research. But standard textbook treatment of nucleic acid structure rarely goes beyond the double helix. For practical work, the biggest gap in most people's understanding is how much the solution environment matters. Salt concentration, pH, temperature, and the presence of organic solvents all shift the melting temperature and structural stability of nucleic acids. A primer pair that works perfectly at 50 millimolar sodium might fail at 10 millimolar. The same DNA sample can look completely different on a gel depending on whether you run it in TAE or TBE buffer. These aren't edge cases. They're the normal conditions of working with nucleic acids, and treating them as variables rather than constants is what separates reliable results from frustrating inconsistency. The takeaway isn't that nucleic acids are complicated. It's that they're precisely complicated in ways that matter for every step from extraction to analysis. Knowing what they're made of is the starting point, not the destination.