So you want to know what independent assortment actually means in practice
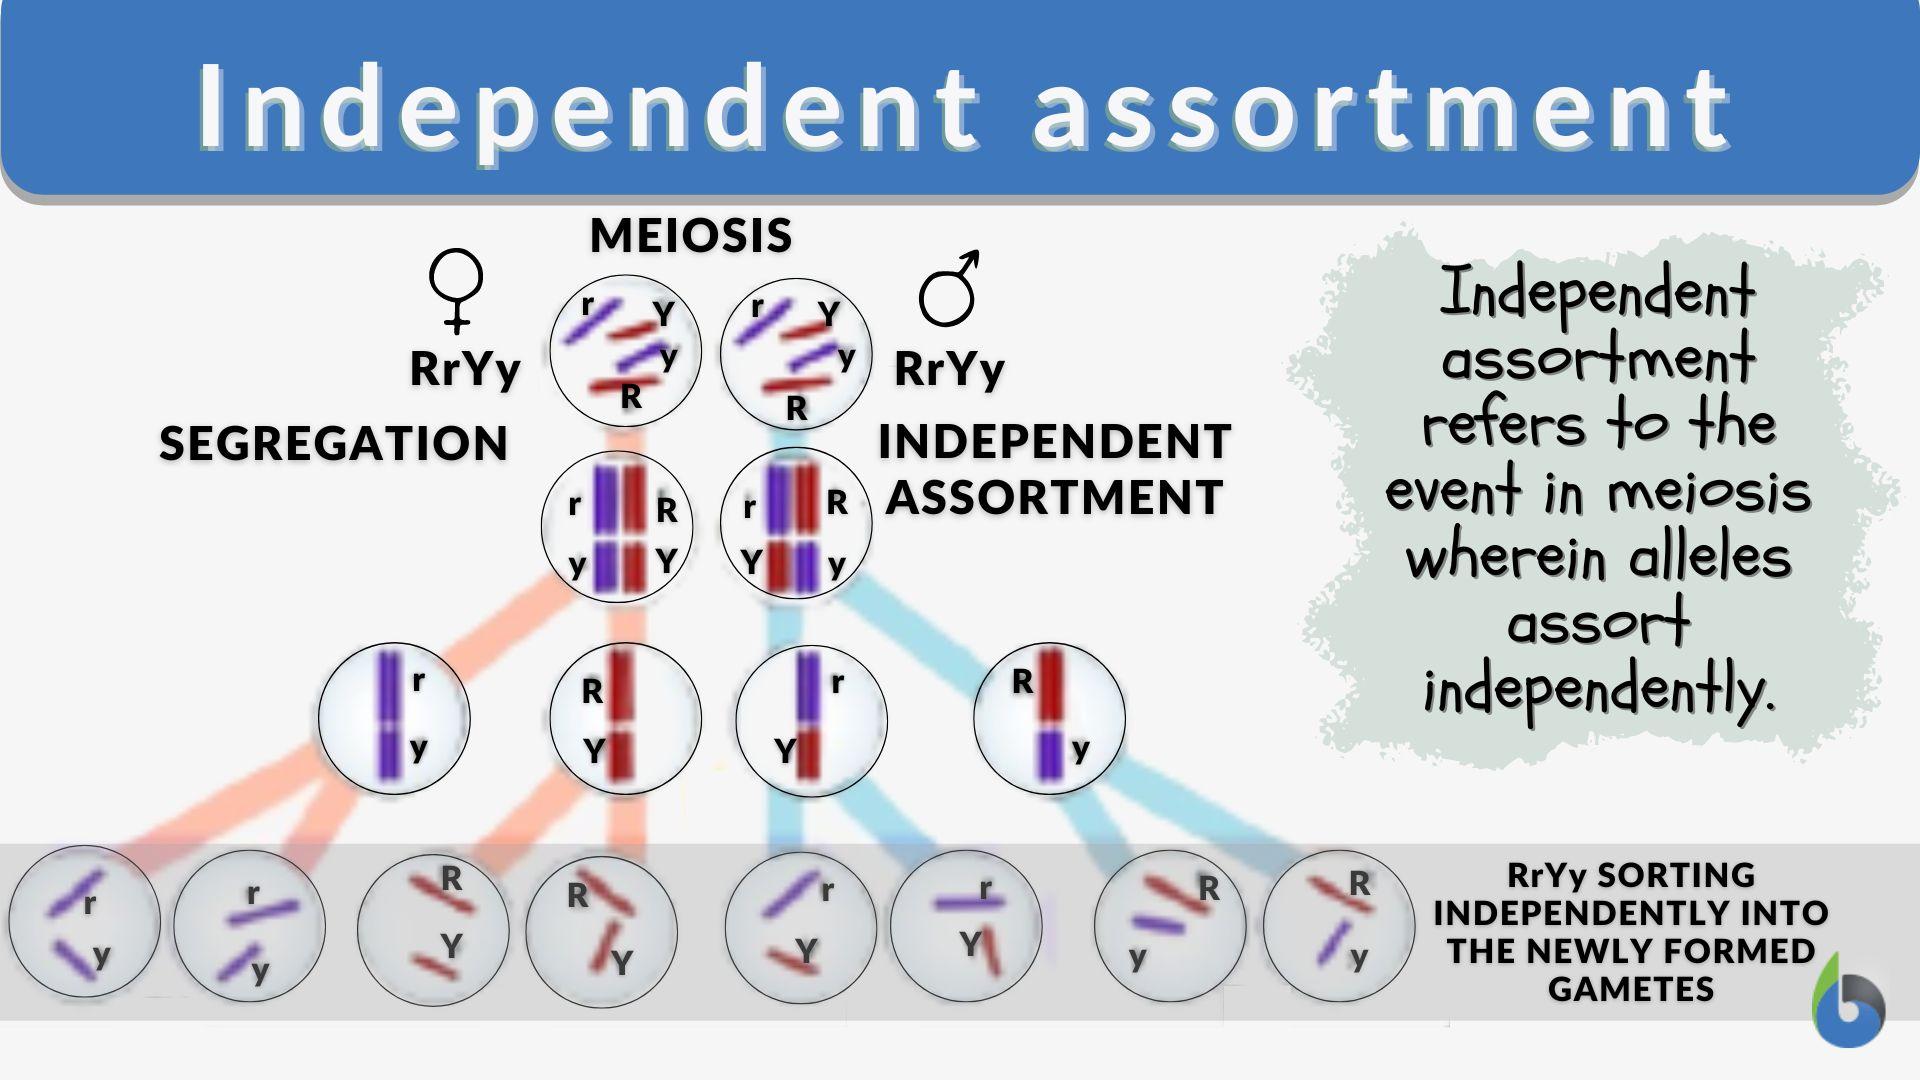
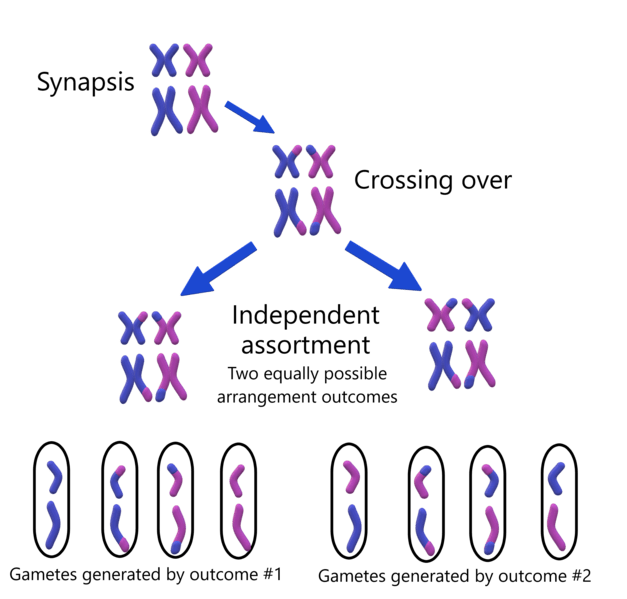
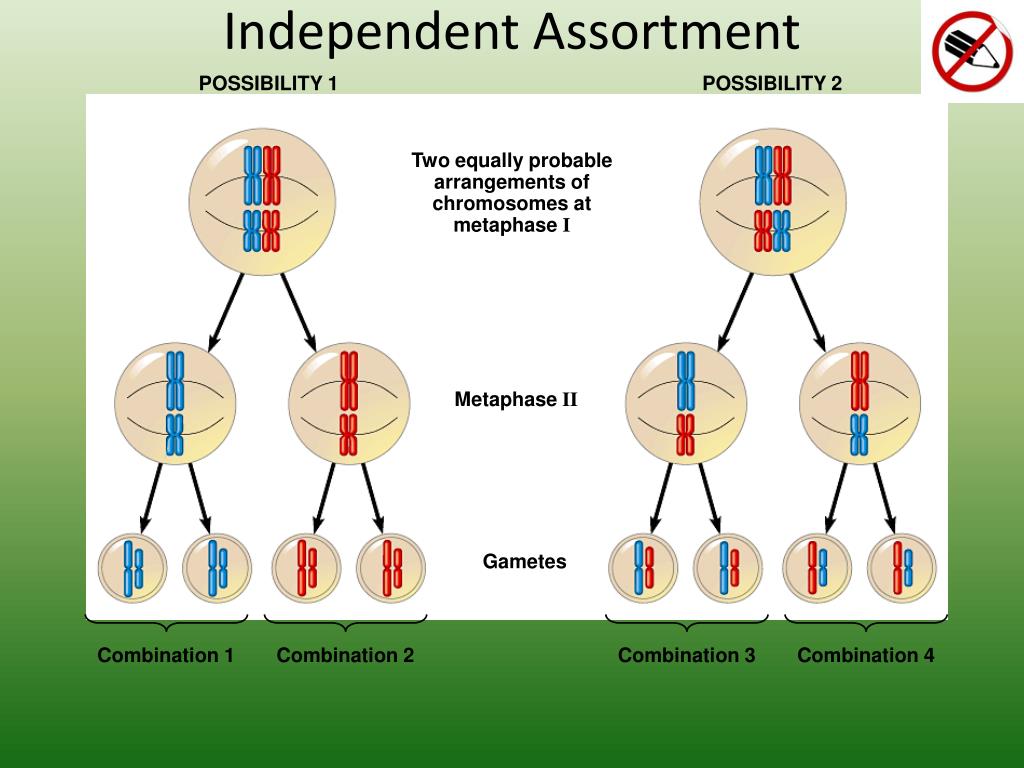
I spent about six months debugging a genetics simulation where the crossover engine was randomly mixing chromosomes instead of respecting linkage groups. It turned out someone had confused Mendel's second law with a uniform random shuffle. The data looked plausible at first glance because you get roughly equal allele frequencies either way, but the multilocus haplotype structure was completely wrong. That's usually where people trip up on this topic. Independent assortment isn't randomness. It's a specific mechanism that only applies under certain conditions, and when it doesn't apply, your results look fine until they don't. The concept comes from Mendel's pea experiments in the 1860s. He was tracking two traits at once, seed color and seed shape, and noticed that the alleles for each trait segregated into gametes independently of each other. A plant that was heterozygous for both traits could produce four types of gametes in roughly equal proportions. That's the definition most textbooks give you, but the real practical point is about chromosomal behavior during meiosis I. When homologous chromosome pairs line up at the metaphase plate, they orient randomly with respect to each other. One pair doesn't influence how another pair positions itself. The result is that alleles on different chromosomes get mixed into gametes in predictable ratios. Here's what I learned the hard way: this only works for genes on different chromosomes or genes that are far apart on the same chromosome. If two genes are close together, they're physically linked and they travel together through meiosis most of the time. The recombination frequency between them drops below 50 percent, and you start seeing deviation from the expected 9:3:3:1 dihybrid ratio. I've seen people try to use a simple Punnett square for linked genes and then wonder why their testcross results are off by 30 to 40 percent.
The mechanics are straightforward enough. During prophase I, homologous chromosomes pair up and can exchange segments through crossing over. But even without any crossing over, the random alignment of chromosome pairs at metaphase I creates new combinations of maternal and paternal chromosomes in the resulting gametes. Humans have 23 chromosome pairs, so without any recombination you'd still get 2 to the 23rd power, which is over 8 million possible gamete types from just the assortment mechanism alone. Add crossing over into the mix and the number becomes astronomically large.
The numbers behind the concept
When genes assort independently, a heterozygous individual with genotype AaBb produces four gamete types in equal frequency: AB, Ab, aB, and ab. Each one makes up 25 percent of the gamete pool. If you self-cross two double heterozygotes, you expect the classic 9:3:3:1 phenotypic ratio in the offspring. That ratio assumes complete dominance at both loci and no epistasis. Get either of those conditions wrong and the numbers shift in ways that can look like independent assortment is broken when it's actually working fine. The chi-square test is your standard tool for checking whether observed data fits the expected ratio. I usually calculate it by hand first to catch mistakes before feeding the numbers into software. You take each observed class, subtract the expected count, square the difference, and divide by the expected. Sum those values across all classes and compare to the critical value for your degrees of freedom. With a dihybrid cross you have three degrees of freedom. Anything above 7.815 and you probably have linkage or some other complication going on. One thing most introductory courses skip is that independent assortment creates linkage drag in breeding programs. When you're trying to select for a desirable trait, the genes nearby on the same chromosome tend to come along for the ride, whether you want them or not. This can introduce unwanted alleles into your lines. Plant breeders deal with this constantly and use marker-assisted selection to track which segments are actually being inherited together. The workaround I ended up using in my own work was running testcrosses with tightly linked markers flanking the target gene, then selecting for recombinants that had swapped the linked segment away from the unwanted allele.
Get the Full Details

When the rule breaks down
Independent assortment has hard limits and knowing them saves you from wasting time on crosses that will never give you clean ratios. The main exceptions are linkage, which I already mentioned, sex-linked genes that follow different inheritance patterns, mitochondrial DNA that gets inherited maternally without any meiosis involved, and structural variants like inversions that suppress recombination in heterozygotes. Inversions are particularly annoying because they create pseudo-linkage, making genes that look like they should assort independently actually behave as if they're on the same chromosome. I encountered a case where a chromosomal inversion in Drosophila made three genes on the same arm appear to assort independently in a small F2 sample. The recombination fraction looked close to 0.5 just by chance because the sample size was only about 80 flies. When I increased it to 400, the deviation became obvious and the linkage map positions snapped into place. Sample size is always a factor here. Small crosses with independent assortment expectations often fail chi-square tests for no biological reason at all, and larger crosses sometimes show tiny but statistically significant deviations that are biologically real but practically negligible. Another limitation nobody mentions enough is that independent assortment assumes normal meiosis. Polyploids complicate things because chromosome pairing gets messy. In tetraploids you can have multiple homologous chromosomes trying to pair up, and the segregation ratios diverge significantly from diploid expectations. Some organisms also have deterministic sex determination systems or meiotic drive mechanisms that bias which chromosomes end up in which gamete, breaking the assumption of random assortment.
Practical tips for working with the concept
If you're doing actual genetics work rather than just studying for an exam, here's what actually helps. Always confirm linkage phase before setting up your crosses. Knowing whether your heterozygote is in coupling or repulsion configuration changes the expected ratios entirely. I've seen people waste weeks on reciprocal crosses trying to figure out what was just a phase problem. Testcrosses are your best friend for mapping because they reveal the gamete types directly without dominance masking anything. For quick estimates without running full simulations, the multinomial probability formula gives you exact expected frequencies for any cross configuration. It's more work than a Punnett square but takes about the same time once you know the pattern, and it handles cases where independent assortment breaks down because of partial linkage. When genes are linked with a recombination fraction of r, the four gamete types from a double heterozygote in coupling phase appear at frequencies (1-r)/2, r/2, r/2, and (1-r)/2. Just plug those into your expected value calculations and you're done. The bottom line is that independent assortment is a useful null model. It tells you what to expect when there's no physical connection between loci, and deviations from it tell you something interesting is happening. That's actually more valuable than the ratio itself because the deviations are where the biology lives. Linkage maps, chromosomal rearrangements, evolutionary constraints, breeding program design, all of that comes from noticing when things don't assort independently.