Understanding the machine learning manual concept
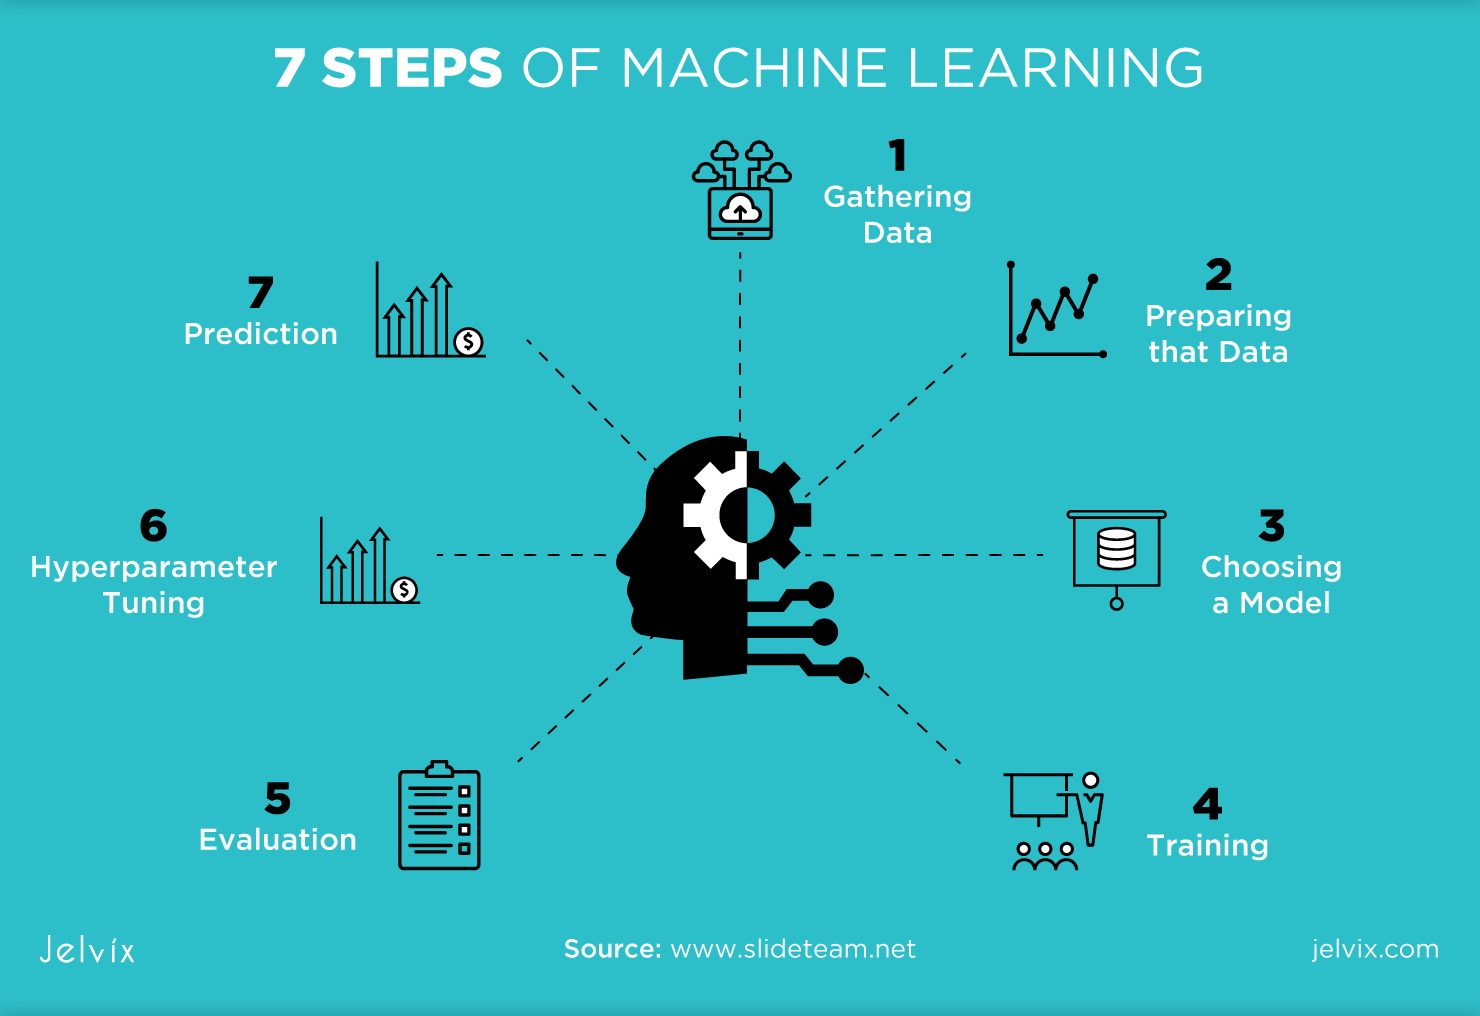
A machine learning manual is essentially a documented process for building, validating, and deploying ML models in a production environment. It covers everything from data preparation through model selection to monitoring after deployment. I've seen teams skip this because they were racing to ship a prototype, and it always came back to bite them. The manual isn't bureaucracy. It's the difference between a model that works in your notebook and one that actually runs in production without breaking at 2 AM. The term refers to a comprehensive documentation framework that standardizes how an organization develops and maintains machine learning systems. It's not a single document but a collection of guidelines, templates, checklists, and procedures. Think of it as an operational handbook that ensures consistency across projects, reduces onboarding time for new data scientists, and creates an audit trail for regulatory compliance. In practice, it typically includes sections on data governance, experiment tracking, model versioning, evaluation metrics, and deployment protocols. I spent six months trying to rebuild a churn prediction model because the original team hadn't documented which feature engineering steps they used. The code existed, but the pipeline steps were scattered across Jupyter notebooks, Slack messages, and one person's mental model. We recovered most of it by reverse-engineering the data, but we lost three weeks. That experience made me obsessive about documentation.
Building your manual: the practical structure
Start with your data lifecycle. Document where each dataset comes from, who owns it, how it's cleaned, and what transformation rules apply. This is usually the weakest part of any ML operation because data isn't static. The training data you logged last quarter looks different from today's input if someone changed the source schema without updating anything. I encountered this with a recommendation engine where the feature store had two different definitions of "active user" depending on which team wrote them. The model was producing garbage predictions for two weeks before anyone noticed the drift. Your manual should specify a single source of truth for every feature. Call it out explicitly and make it searchable. Use a feature catalog tool or at minimum a well-organized Confluence space. The rule is simple: if two people can give you the same feature definition from different documents, your manual has failed.
Model development standards
Document your experiment tracking requirements. Every model iteration should record the hyperparameters, training data snapshot, evaluation metrics, and validation approach. MLflow or Weights & Biases works for this, but the tool doesn't matter as much as the habit. I worked with a team that relied entirely on notebook cells and Git commits to track experiments. They couldn't reproduce their best model three months later. They had forty thousand lines of code but no map of which parameters produced which results. Define your evaluation criteria upfront. Accuracy alone is almost never enough for production models. Specify whether precision, recall, F1, AUC-ROC, or business-level metrics are the decision threshold. I once saw a fraud detection model approved because it hit 99 percent accuracy, which was meaningless when the positive class was only 0.3 percent of transactions. The manual should force this conversation before model building starts.
Get the Full Details
Deployment and monitoring procedures
Write down your deployment pipeline. How does a model move from development to staging to production? What gates exist? Who approves the switch? This is where most manual frameworks fall apart because the documentation sits in a PDF nobody reads. Make it actionable. Use a checklist format that engineers actually follow before deploying. Include a monitoring section that defines what success looks like post-deployment. Track data drift, prediction distribution shifts, and latency. Set up alerts. The manual should specify response protocols when metrics degrade. I had an automated pipeline that silently started outputting wrong predictions for four days because a dependency library updated and changed an API behavior. No one caught it because there was no alert configured for output distribution drift. The model was still "running," so everything looked fine on the surface.
Common pitfalls to avoid
Don't write a manual that's too long. Sixty pages gets ignored. Twenty pages with clear sections and checklists gets used. Prioritize depth over breadth. Focus on the processes your team actually struggles with, not the ones that sound good in theory. Update it quarterly. A stale manual is worse than no manual because people assume it reflects current practice when it doesn't. Avoid making it purely technical. Include decision logic. Explain why certain thresholds exist, not just what they are. A junior engineer reading this should understand the reasoning, not just follow instructions blindly. I found this out the hard way when a team member changed a threshold value without understanding the original justification, and the downstream impact took two days to trace back to that undocumented decision.
Where to find existing templates and resources
Several organizations have published open-source ML manual templates. Google's ML Ops Guide offers a solid starting framework. The MLOps Community on GitHub maintains multiple repository templates with documentation standards built in. If you're working within a cloud provider ecosystem, AWS, Azure, and GCP all publish their own ML operational guidelines that you can adapt. The key is customization. Copying someone else's manual verbatim rarely works because your data, team size, and deployment complexity differ. Use these as structural references, then fill in the gaps with your actual workflows. I maintain a basic template in my team's internal wiki that covers data sourcing, feature definitions, experiment logging, model validation criteria, deployment checklists, and monitoring thresholds. It started as twelve pages and grew to eighteen after we added a section on rollback procedures following a bad deployment. Each addition came from a real incident, not speculation. That's how the manual should evolve. React to problems as they surface, document the fix, and reference the incident as context for why that section exists.

Integration with existing tools
Your manual shouldn't live in isolation. Connect it to your CI/CD pipelines, your experiment tracking platform, and your monitoring dashboards. If the manual says "validate model performance before deployment" but your deployment pipeline has no validation step, the instruction is decorative. I prefer linking manual sections directly to the tools that enforce them. A checklist item about data validation should point to the specific Great Expectations suite that runs before every training job. A monitoring alert threshold should link to the Grafana dashboard showing that metric in real time. This approach turns the manual from a static document into an operational reference that engineers interact with daily. Reading it becomes part of doing the work rather than an extra step. It took my team about two weeks to wire everything together properly, but the maintenance overhead dropped significantly after that. People stop treating documentation as separate from execution when the execution tools themselves reference it. If you need a starting point for a What Is Machine Learning Manual framework, begin with the four pillars: data governance, experiment tracking, model deployment, and monitoring. Build out each section based on your team's actual pain points rather than theoretical completeness. A thin manual that gets followed daily is infinitely more valuable than a comprehensive one that collects digital dust.


