Understanding Molecular Solvation in Practice
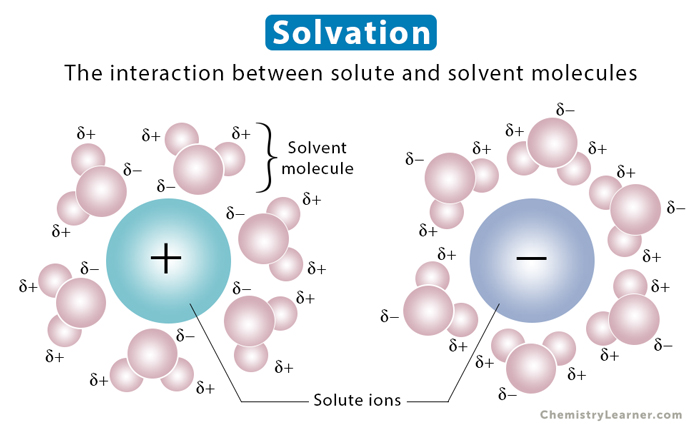
Molecular solvation describes what happens when a molecule interacts with its surrounding solvent medium. It involves breaking apart some solvent-solvent interactions, breaking apart some solute-solute interactions, and forming new solute-solvent interactions. The energy difference between these three components is what we call the solvation free energy, and it determines whether a compound dissolves, how it behaves in a reaction, or whether it precipitates out of solution entirely. In computational chemistry, you encounter this problem constantly. When I first started running DFT calculations on pharmaceutical compounds, I assumed the default gas-phase geometry optimization would carry over reasonably well into solution. It didn't. Some molecules changed their preferred conformation by nearly 20 degrees of torsion angle just because water was stabilizing a polar group that sat buried in the gas phase. The energy landscape is fundamentally different.
What Is Molecular Solvation
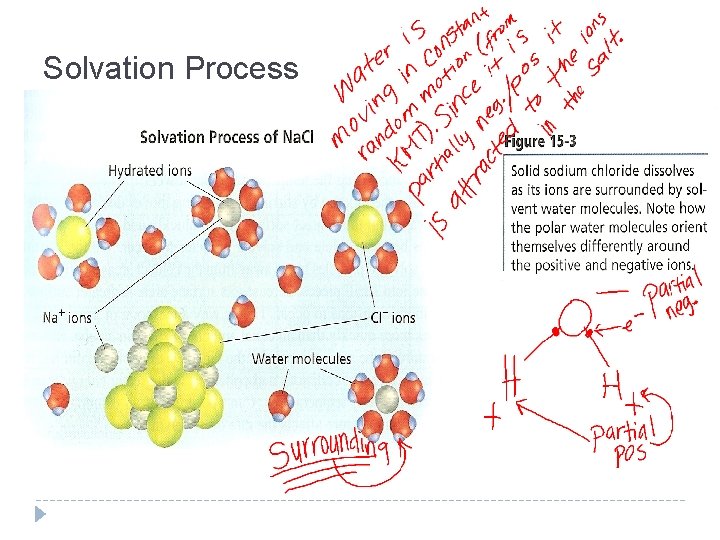
At the modeling level, there are two fundamentally different ways to handle this. Implicit solvent models treat the solvent as a continuous dielectric medium surrounding the solute. The most common implementation is the PCM family—Polarizable Continuum Model—and its variants like SMD. These solve the Poisson or Poisson-Boltzmann equation to find the electrostatic contribution to solvation free energy. They're fast. A single-point energy calculation with SMD added to a DFT job typically takes maybe 10-20% longer than the gas-phase equivalent on the same geometry. That's useful when you're screening hundreds of candidates. Explicit solvent models actually place individual water or solvent molecules around your solute and run molecular dynamics or Monte Carlo simulations. This is orders of magnitude more expensive. A typical 100-picosecond explicit solvent simulation with a reasonable force field on a modest cluster might take hours to days depending on system size. But you get things that implicit models simply cannot capture: directional hydrogen bonding, specific ion pairing, solvent bridging between functional groups, and entropy effects from the actual rearrangement of solvent structure. The counter-intuitive part that trips people up is that implicit models often overestimate solvation stabilization for charged or highly polar species. A carboxylate anion in water might show a solvation energy that's 5-10 kcal/mol more favorable than what experiments suggest. The dielectric continuum smooths over the fact that water molecules have limited orientational freedom near a charge, and the first solvation shell saturates quickly. This is why SMD includes a cavity term and a dispersion term on top of the electrostatics—because pure PCM alone misses non-electrostatic contributions that matter a lot in real systems.
I ran into a specific problem last year where I was computing pKa values for a series of heterocyclic compounds using TD-DFT with PCM. The trend was completely wrong compared to experimental data for three of the eight molecules. I traced it back to a case where one compound formed a strong intramolecular hydrogen bond in the gas phase that PCM couldn't properly describe because the hydrogen-bonded partner was also partially solvated. The implicit model treated those regions as either fully exposed to the dielectric or fully buried, with no gradient between the two states. Switching to an explicit solvent box with 200 water molecules and running a 50-ps equilibration before the single-point energy calculation fixed the discrepancy. The computation took about 40 times longer per data point, but the accuracy gain was substantial. There are also hybrid approaches. Cluster-continuum models place a few explicit solvent molecules in the first solvation shell and treat the rest with a continuum. This captures specific interactions like hydrogen bonds while keeping computational cost manageable. For proton transfer reactions in water, I've found this to be a reliable sweet spot. You need at least 3-4 explicit water molecules in the first shell for accurate pKa prediction, and adding the continuum on top accounts for bulk electrostatic effects. Another thing beginners miss is that solvation models are parametrized for equilibrium geometries. If you're doing a transition state search, the solvent response time matters. Implicit solvent assumes instantaneous electronic polarization of the dielectric, but nuclear rearrangement of solvent molecules happens on a picosecond timescale. For reactions involving significant charge redistribution in the transition state, this can shift barrier heights by several kcal/mol. The COSMO-RS method attempts to address this by treating the solvent as a surface dialog between chi and chi' potentials, but it's still an approximation and isn't available in every quantum chemistry package.
Get the Full Details
When I work with experimental collaborators, the biggest source of confusion is always the units and reference state. Most solvation free energy calculations report values in kcal/mol or kJ/mol, but the standard state matters. A 1 molar standard state shifts everything by about 1.9 kcal/mol compared to the pure liquid reference. I've seen papers report values that look wildly off because nobody specified which convention they were using. Always check this if you're comparing computed solvation energies to literature values. The practical takeaway is straightforward but easy to get wrong. Use implicit solvent for quick screening and geometry optimization in solution. Use explicit solvent when you need to resolve specific solute-solvent interactions or when your system has charged species, ions, or strong hydrogen bonding networks. Hybrid cluster-continuum is worth considering for proton transfer chemistry. And whatever you do, document your standard state and your solvation model version so someone else can reproduce your numbers.


