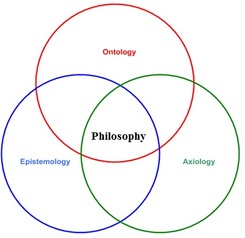
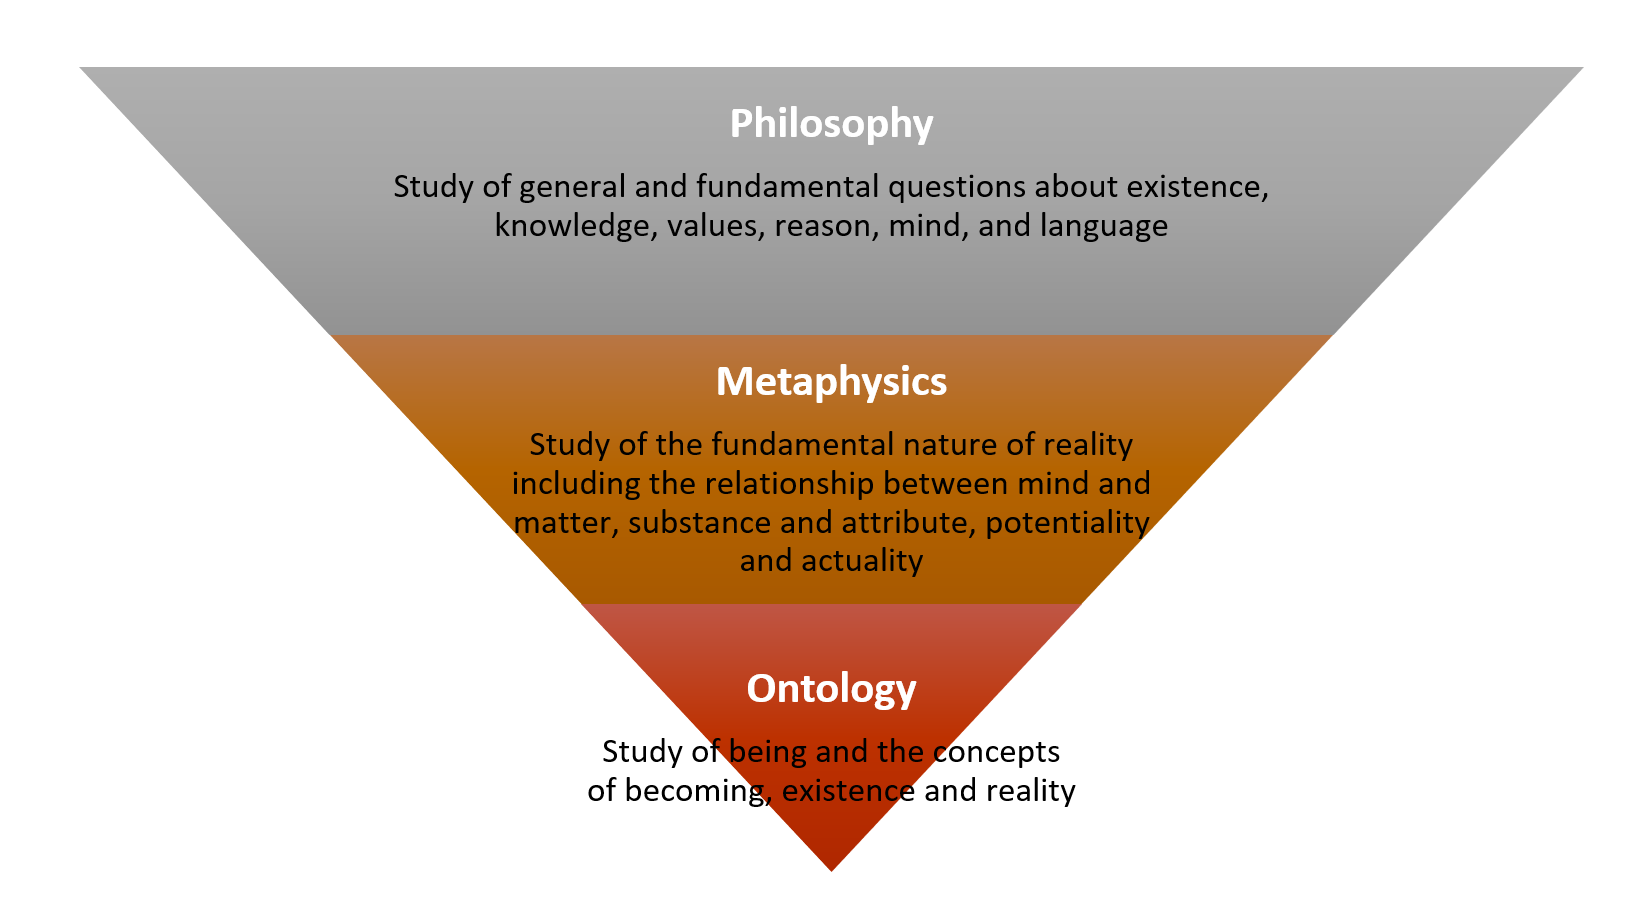
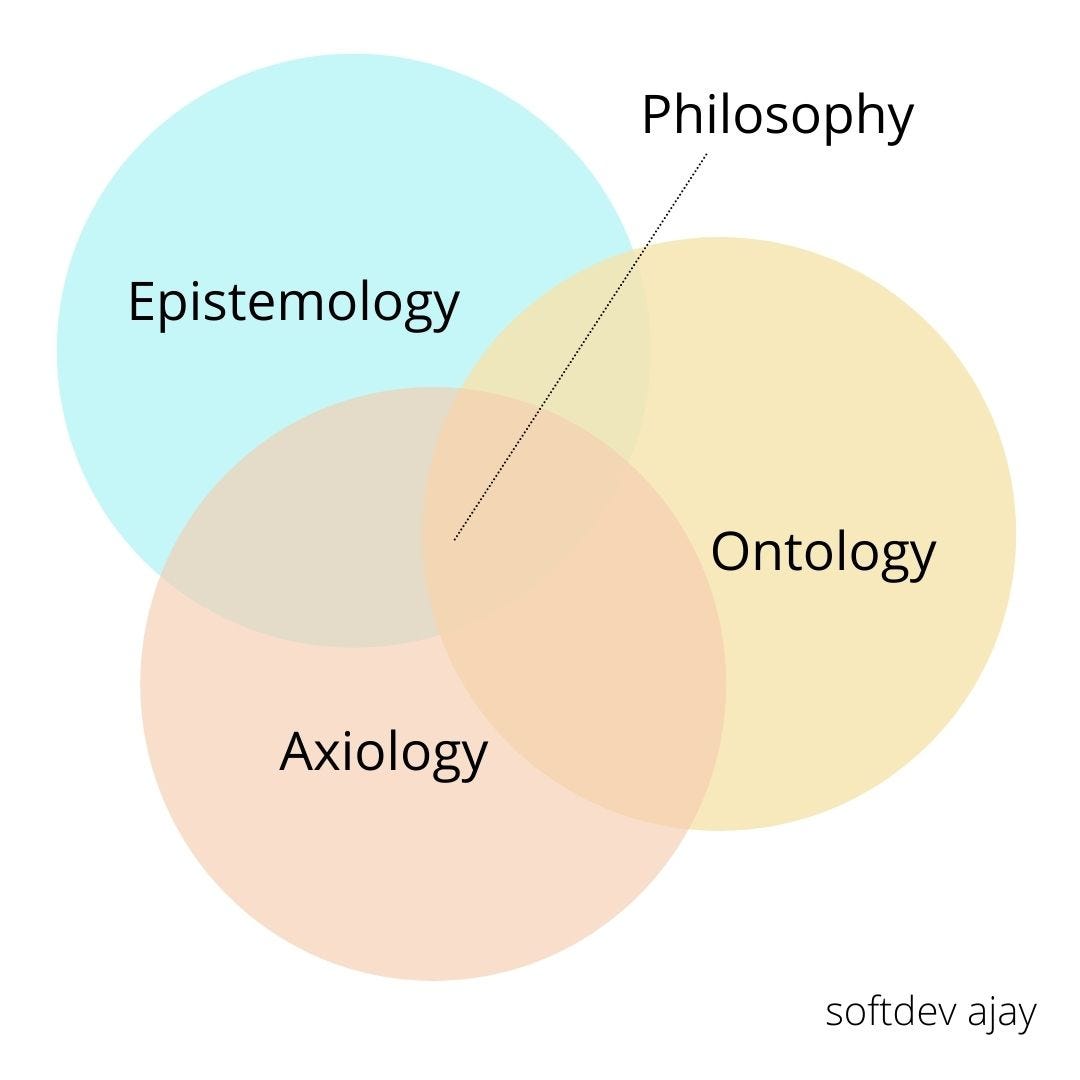
Ontology is just the study of what exists, and it is far more practical than people think
You pick up any introductory philosophy textbook and you will see the word ontology paired with categories, being, and abstract objects. That is the surface version. In practice ontology is a method for deciding what kinds of things your system recognizes as real, and then making sure every statement you make is consistent with that list. It shows up everywhere once you stop treating it as pure theory. Data modeling, legal reasoning, artificial intelligence knowledge graphs, even database schema design — all of these are exercises in applied ontology. The core question is simple: what categories of entities exist, and how do they relate to each other? Aristotle answered by drawing up a list of ten categories, including substance, quantity, quality, relation, place, time, and so on. He was not trying to be clever. He was trying to create a vocabulary that prevented people from arguing past each other when they discussed reality. If your opponent says a law exists but you treat laws as mere human conventions rather than social objects, you will never agree on anything substantive about jurisprudence. That is the practical value of ontology right there. Later philosophers shifted the focus. Quine made it famous with the phrase "to be is to be the value of a variable." His point was that whenever your best scientific theory quantifies over something, you have committed to its existence. If physics requires electrons to explain particle collisions, then electrons exist in your ontology, whether you like it or not. This shifted ontology from a speculative exercise into something tied directly to what your theories require you to believe.
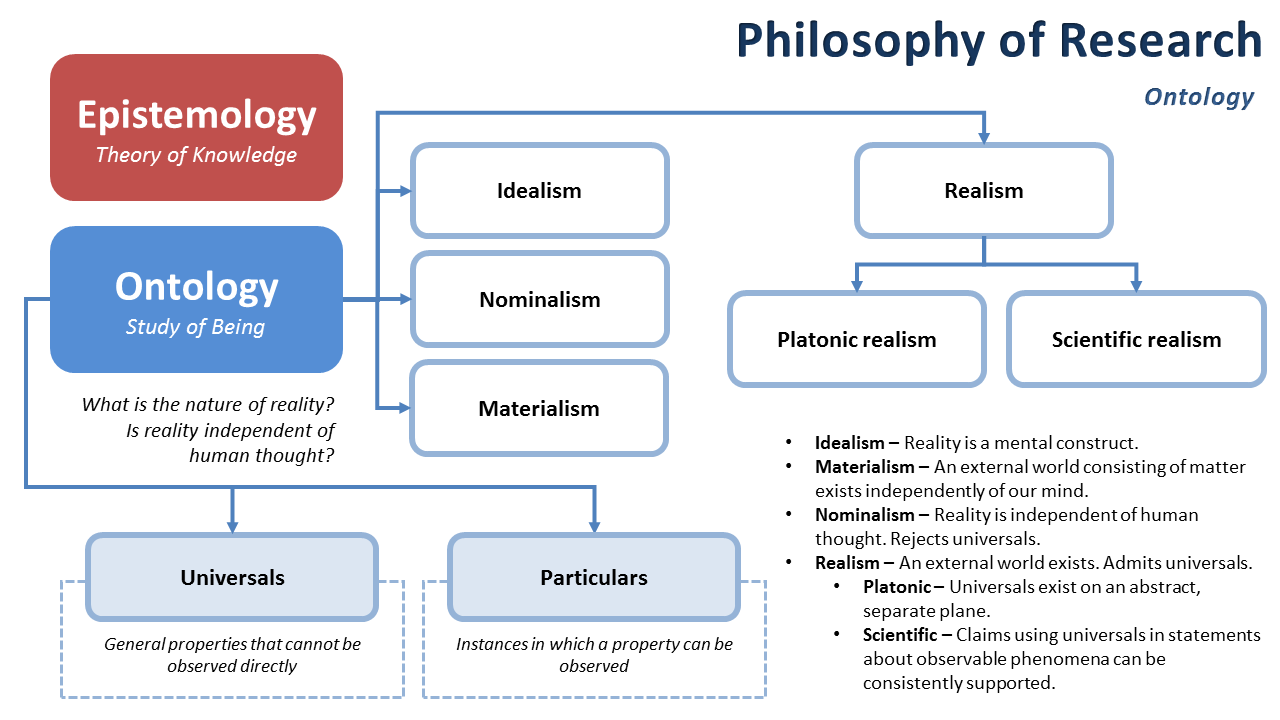
Then you have the debate over universals versus particulars, which most beginners gloss over and which causes real trouble if you ignore it. A universal is something like redness or justice that can be instantiated in many different places at once. A particular is a single thing, like this red apple or the specific act of bribery that happened in your city council last March. Realists say universals exist independently of particulars. Nominalists say they do not, and that we are just grouping similar things together with labels. This distinction matters enormously when you build knowledge representations. If you model redness as a real entity that multiple objects share, you get a very different data structure than if you model it as a property attached to each object individually. Both approaches work. They just produce different results under stress. I spent about three years building ontological frameworks for a health data interoperability project, and the moment I learned the hard way why formal ontology matters was when we tried to merge two clinical systems that used the same term for completely different concepts. The term was "adverse event." System A meant any harmful reaction to a treatment, including expected side effects that crossed a severity threshold. System B meant only unexpected harmful reactions, excluding anything known from the prescribing information. We caught the mismatch during integration testing, not after deployment, which saved us roughly six weeks of rework. But catching it required us to write out the exact ontological commitments of each term, not just compare glossaries. That process alone took about a week because we had to trace each term back to its underlying definitions, map the relationships between categories, and identify where the hierarchies diverged. The most useful tool I found for this work was the topological approach to ontology, derived from the work of theorists like Barbara Smith and the General Reference Ontology work at the Institute for formal Ontology and Medical Information Science. The idea is straightforward. You treat an ontology as a directed graph where nodes represent entities and edges represent relationships like is_a, part_of, and relates_to. The key insight is that some relationships are transitive while others are not, and mixing them up breaks your inference engine. For example, if A is_a B and B is_a C, then A is_a C. That works for class hierarchies. But part_of is also transitive in most cases, while located_in is not. Getting those rules wrong means your automated reasoning produces incorrect conclusions silently, which is worse than producing no conclusions at all because you have no way of knowing your answers are wrong.
How to actually build or analyze an ontology without getting lost
Start by listing the domain and the intended users. An ontology for a pharmaceutical company has different requirements than an ontology for a museum collection or a municipal government. Write down the core questions your users need the ontology to answer. If you skip this step you will build something technically impressive that nobody can use. Next, identify the top-level categories. Do not start by listing specific entities like patients or medications. Start with the highest level distinctions that your domain requires. The basic top-level split is usually between continuants, which are things that persist through time like objects and substances, and occurrents, which are events and processes that unfold over time. Most modeling errors come from mixing these two levels. You cannot say a heart attack is_a heart because one is an event and the other is an object. They are related, but the relationship is part_of or occurs_during, not is_a. Then define your relations carefully. Each relation should have a clear definition, a domain, and a range. The domain is the set of classes that can occupy the subject position of the relation. The range is the set of classes that can occupy the object position. If you define part_of without specifying its domain and range, you will end up with statements like "Tuesday part_of pain," which is syntactically valid and semantically meaningless. OWL and RDF let you express these constraints, and enforcing them at the schema level prevents this category of error entirely.
Get the Full Details
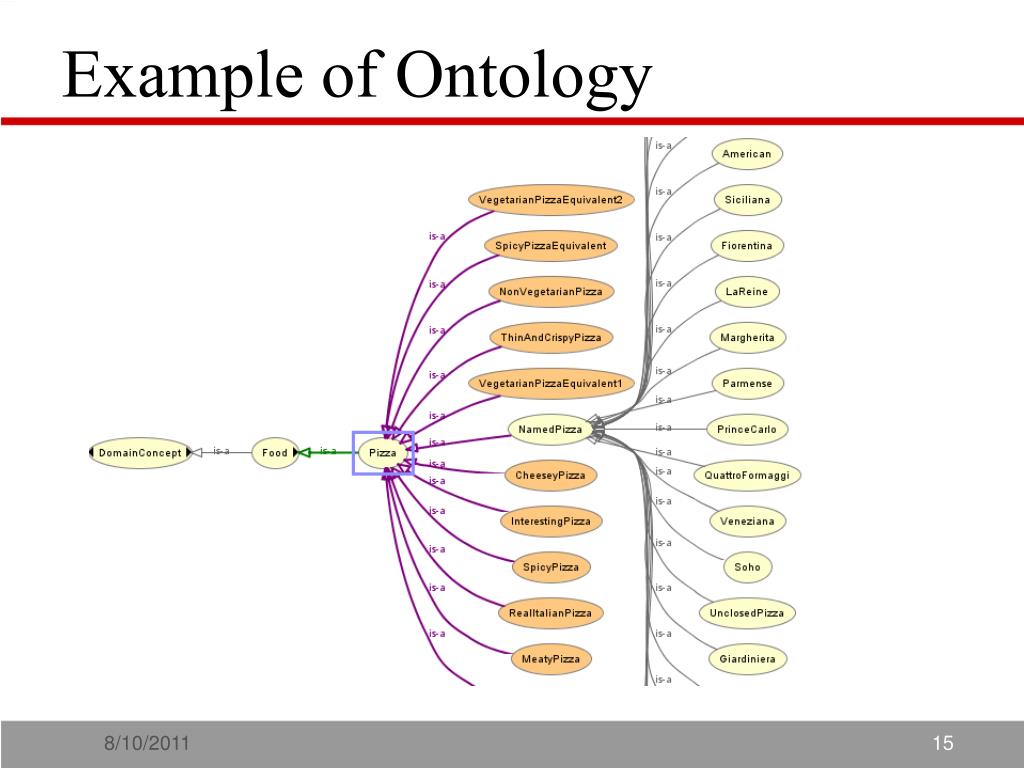
A common pitfall is assuming that every concept needs a parent. Some ontologists create deep hierarchies for the sake of hierarchy, producing structures with six or seven levels of abstraction before they reach any concrete category. This makes querying harder and slows down inference engines. A shallow but well-connected ontology usually outperforms a deep sparsely connected one. I learned this when a client insisted on a seven-level hierarchy for their medication ontology. Query response times increased by roughly forty percent compared to a flatter structure with explicit cross-references, and the maintenance burden tripled because every new medication type required changes across multiple levels. Another pitfall is ignoring the difference between instance-level and class-level statements. When you write "Patient_123 has_diagnosis Diabetes_Mellitus_Type_2," that is an instance-level fact. When you write "Diabetes_Mellitus_Type_2 subclass_of Diabetes_Mellitus," that is a class-level axiom. Mixing these up in your knowledge base creates ambiguity for reasoners. Separate your TBox, which contains the schema and class definitions, from your ABox, which contains the assertions about individual instances. Keep them in separate files or at least clearly labeled sections. It takes marginally more setup time but prevents a whole class of reasoning errors.
When ontology breaks down and what to do instead
Formal ontologies assume that your domain can be cleanly categorized and that relationships between categories are stable enough to encode as axioms. This assumption fails in domains dominated by vague boundaries, contested definitions, or rapid change. Medical terminology changes constantly as new diseases are recognized and old classifications are revised. Legal terms shift with new legislation and court interpretations. Social categories evolve with cultural change. In these domains, a rigid ontology becomes a liability because it encodes decisions that later turn out to be wrong or incomplete. The workaround is to use a modular ontology design, where each module covers a specific aspect of the domain and modules can be updated independently. You also need versioning and provenance tracking. Every axiom should be annotated with who asserted it, when, and on what authority. When new evidence contradicts an existing axiom, you do not delete it. You mark it as superseded and keep the old version available for historical reasoning. This adds complexity but it is the only honest way to handle domains where the ground shifts. Sometimes formal ontology is simply the wrong tool. If your domain is highly contextual and interpretation-dependent, a narrative or argumentative framework may serve you better. Legal reasoning, for instance, often depends on precedent and policy considerations that resist clean categorization. An ontology can capture the taxonomy of legal concepts, but it cannot resolve the substantive disputes that arise when two competing interpretations both fit the categories. In those cases, you need an argumentation framework alongside your ontology, not instead of it, but clearly distinguished from it.
The field of applied ontology has expanded significantly since the early 2000s, and the tools have improved. OWL 2, the Web Ontology Language, provides a formal specification with different profiles suited to different use cases. OWL EL is designed for large biomedical ontologies where reasoning speed matters more than expressive power. OWL DL provides full decidability at the cost of restricting some modeling features. OWL Full allows maximum expressiveness but sacrifices automated reasoning guarantees. Choosing the right profile is a technical decision with real consequences for performance and correctness. If you want to explore the philosophical foundations, the Stanford Encyclopedia of Philosophy entry on ontology is the standard reference, though it assumes some familiarity with analytic philosophy. For the practical side, the book Building Ontologies with Formal Ontology by Thomas Bittner and Barry Smith covers the methodological foundations more rigorously than most introductory texts. The Basic Formal Ontology reference model is also worth studying because it demonstrates how abstract philosophical distinctions translate into implementable axioms. Most beginners treat ontology as something you study rather than something you do. The mistake is thinking that reading about the history of the debate gives you the skills to build a useful ontology. It does not. You need hands-on experience with an ontology editor like Protégé, you need to write real axioms and test them with a reasoner like HermiT or Pellet, and you need to discover through failure that the boundaries you thought were clear are not. That process is tedious and unrewarding in the short term but it is the only way to develop actual competence.
The philosophical questions remain genuinely open. There is no consensus on whether abstract objects exist, whether fictional entities have any kind of being, or whether time is fundamentally composed of instants or durations. These debates matter because they shape how you build your top-level ontology, but they also mean that every ontology you create is provisional. The best ontologists know this and design accordingly, leaving room for revision without collapsing the entire structure when a single axiom changes.