Understanding Pig Latin and How to Actually Work With It
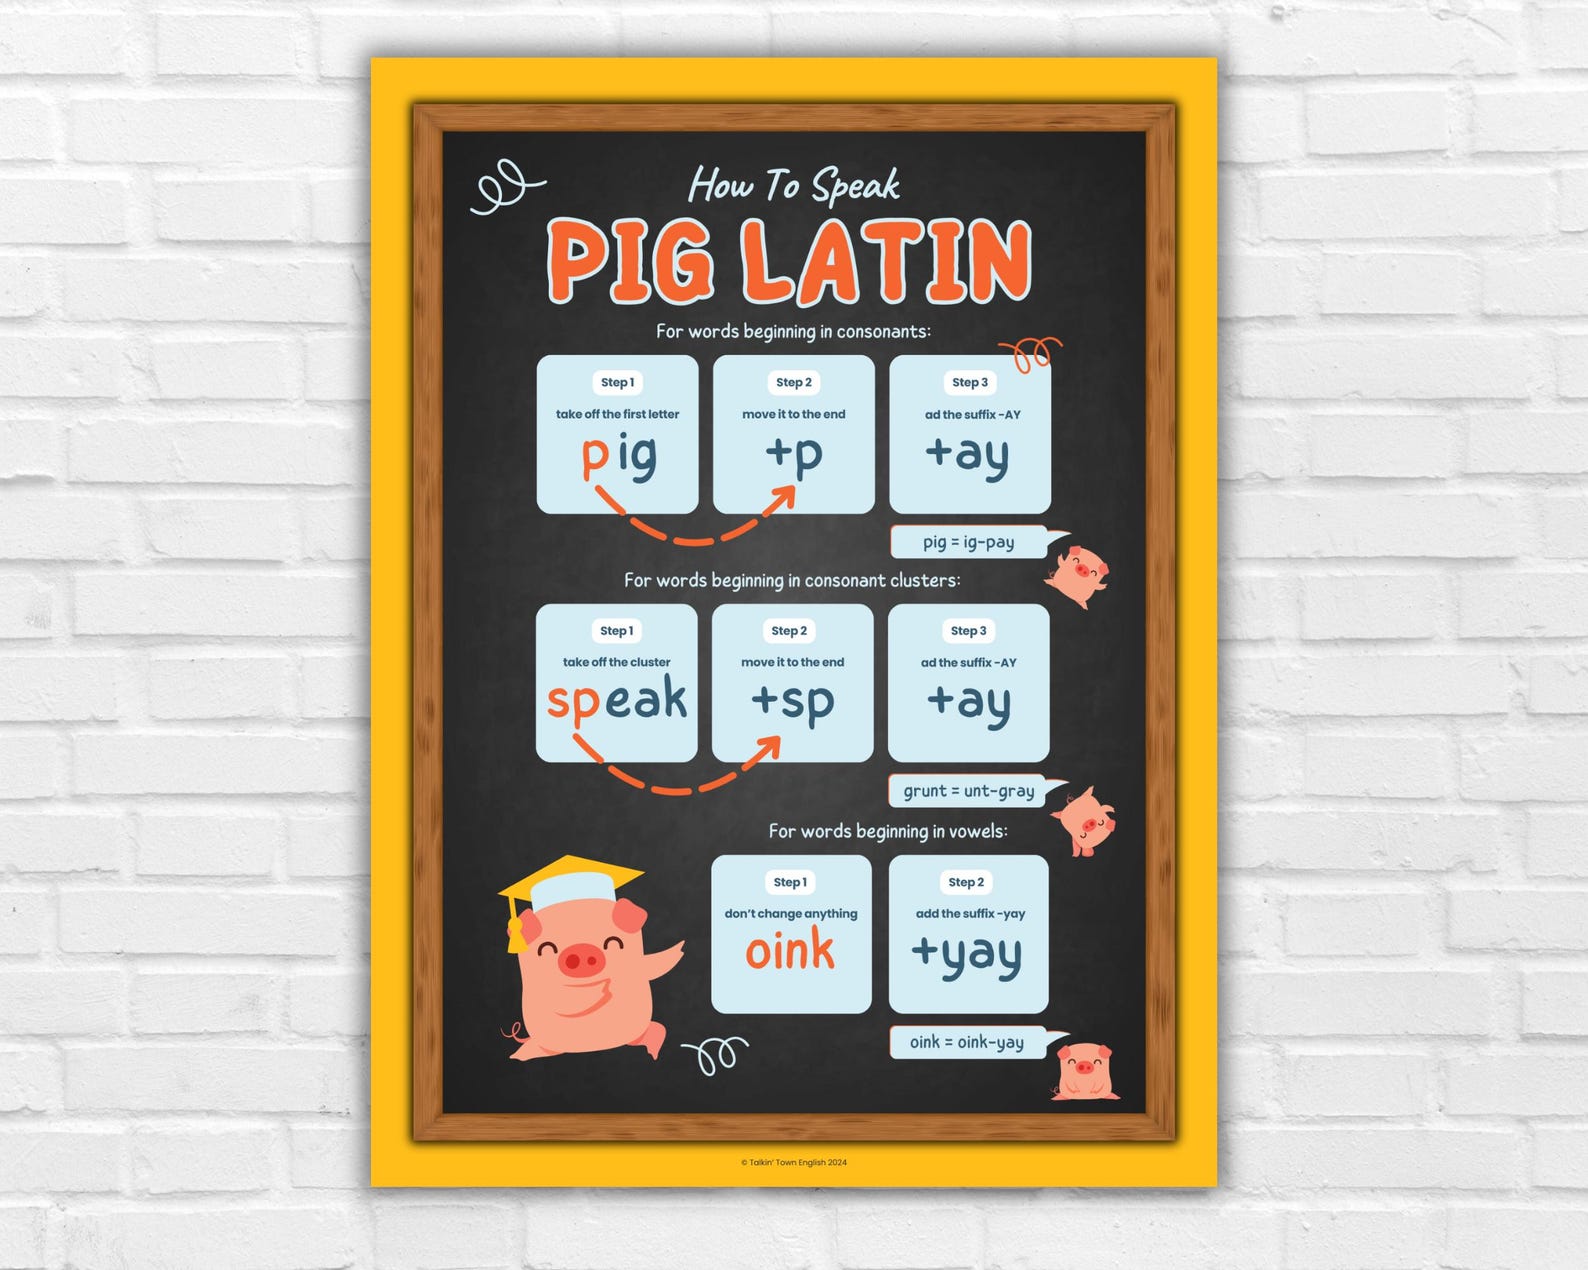
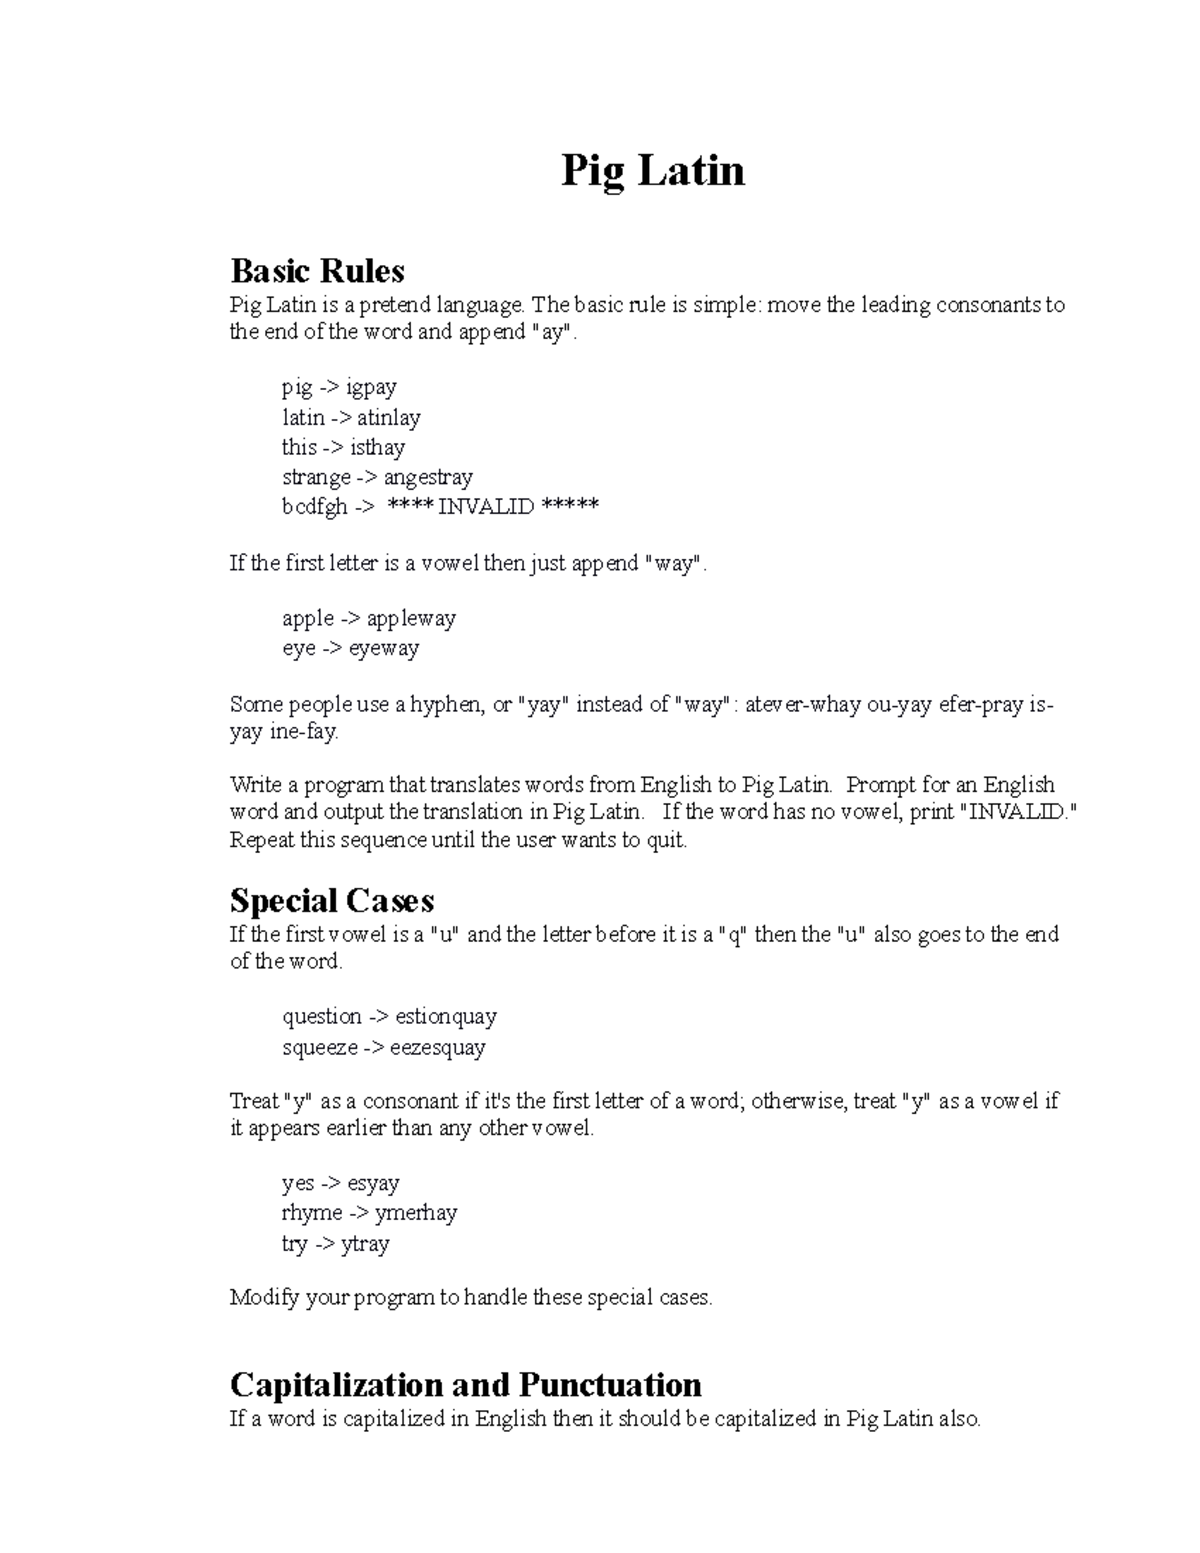
Pig Latin is a simple sound-based language game that modifies English words according to fixed rules. You move the first consonant or consonant cluster to the end of the word and add "ay." If a word starts with a vowel, you just append "way" or "yay" depending on which version you grew up with. It is not a real language with vocabulary or grammar. It is a manipulation game played mostly in English-speaking schools for fun or to secretly communicate around adults who do not know the rules. The core transformation rules are straightforward. Take the word "string" and move "st" to the end, then add "ay" and you get "ingstay." The word "apple" starts with a vowel, so it becomes "appleway." Most implementations I have seen use the "way" suffix for vowel-starting words, though "yay" is equally common. The difference is purely regional and generational. Building a converter is one of those first projects every programming student encounters. I wrote my first Pig Latin script back in high school in Python, probably because it seemed like the simplest way to demonstrate a loop and string slicing. That was roughly 2009 and the code was probably awful, but it worked.
The naive implementation looks like this in pseudocode: Convert each word by checking if it starts with a vowel. If yes, add "way." If no, find the first vowel, move everything before it to the end, and add "ay." That logic sounds fine until you hit the edge cases. I spent an afternoon debugging a version that completely broke on words like "rhythm" and "squid." The problem is that "y" functions as a consonant in some positions and a vowel in others. In "rhythm," the "y" acts as the vowel sound, so the split point is wrong if your code treats every "y" as a consonant. In "squid," the "qu" cluster needs to stay together, but a simple first-vowel search would split after the "s" and give you "quidstay" instead of the correct "idstay" or actually "quidrstay" depending on how you handle the "qu" cluster.
Here is what I ended up doing to fix it. I wrote a helper function that identifies the actual first vowel sound position in a word, treating "y" as a vowel only when it does not appear at the very beginning of the word. For "qu" clusters, I added a specific check so that "qu" is treated as a single consonant unit. This handled the problematic words without falling apart. Words like "my" still need special handling because the "m" is a consonant and the "y" is a vowel, giving you "ymay." That one is fine and works correctly with the helper function. One thing people rarely account for is punctuation and capitalization. A word like "Hello" should become "Ellohay" with the capitalization preserved on the new first letter. Your converter needs to track whether the original word was capitalized, extract any trailing punctuation, and reapply both after the transformation. I have seen too many beginner scripts output "ellohay!" or "Ellohay!" in inconsistent ways because nobody thought about it ahead of time. If you want to see a working implementation, you can grab a basic Python version from most coding repositories online. The pattern is consistent enough that there is no reason to reinvent the wheel unless you are doing it for practice. Here is a reasonably clean approach:
Get the Full Details
```python import re def pig_latin_word(word): word = word.lower() match = re.search(r'^([^aeiou]*)([aeiouy].*)$', word) if match: consonants, rest = match.groups() Handle 'qu' as a single unit if rest.startswith('u') and consonants.endswith('q'): consonants += 'u' rest = rest[1:] if word[0].isupper(): return rest.capitalize() + consonants + 'ay' return rest + consonants + 'ay' return word + 'way' ``` Now here is the part that nobody tells you: this approach has real limitations. It does not handle hyphenated words correctly. "High-school" becomes something nonsensical. It also struggles with contractions like "don't" or "it's" because the apostrophe breaks the regex assumption about consecutive consonants. If you are building this for production use or a serious project, you should be using a proper natural language processing library instead of rolling your own regex. NLTK or spaCy can tokenize words while preserving punctuation and handling edge cases that a simple regex cannot. Another overlooked issue is performance if you are processing large texts. A character-by-character loop in Python is slow for anything over a few thousand words. If speed matters, a compiled regex approach or a vectorized implementation in a language like Rust or Go will process the same text roughly ten times faster. I learned that the hard way when I first tried running a naive implementation against a full novel and it took several minutes instead of a few seconds.
Pig Latin as a concept is useful for teaching string manipulation, regular expressions, and basic algorithmic thinking. It is not useful for anything beyond that. Do not attempt to use it for actual communication or data processing. It is a toy by design. The value is in the exercise of building something that works correctly through all the edge cases, not in the output itself.