The thing nobody tells you about platform product management
You ship internal tooling, other teams build on top of it, and somewhere around month six your API contracts start fracturing because engineering leadership decided to merge two services without warning your consumers. This is the day-to-day reality of What Is Platform Product Management — it's not about building the next shiny dashboard. It's about maintaining infrastructure that hundreds of engineers depend on while barely having any direct stakeholder alignment. I spent three years running the internal developer platform for a mid-size SaaS company. We had eight frontend teams, five data pipelines, and a mobile app that all consumed the same set of microservices. The platform team was four people. Half the time we were putting out fires from incidents we didn't cause. The other half we were negotiating with engineering managers about API versioning policies they had no intention of following.
What Is Platform Product Management
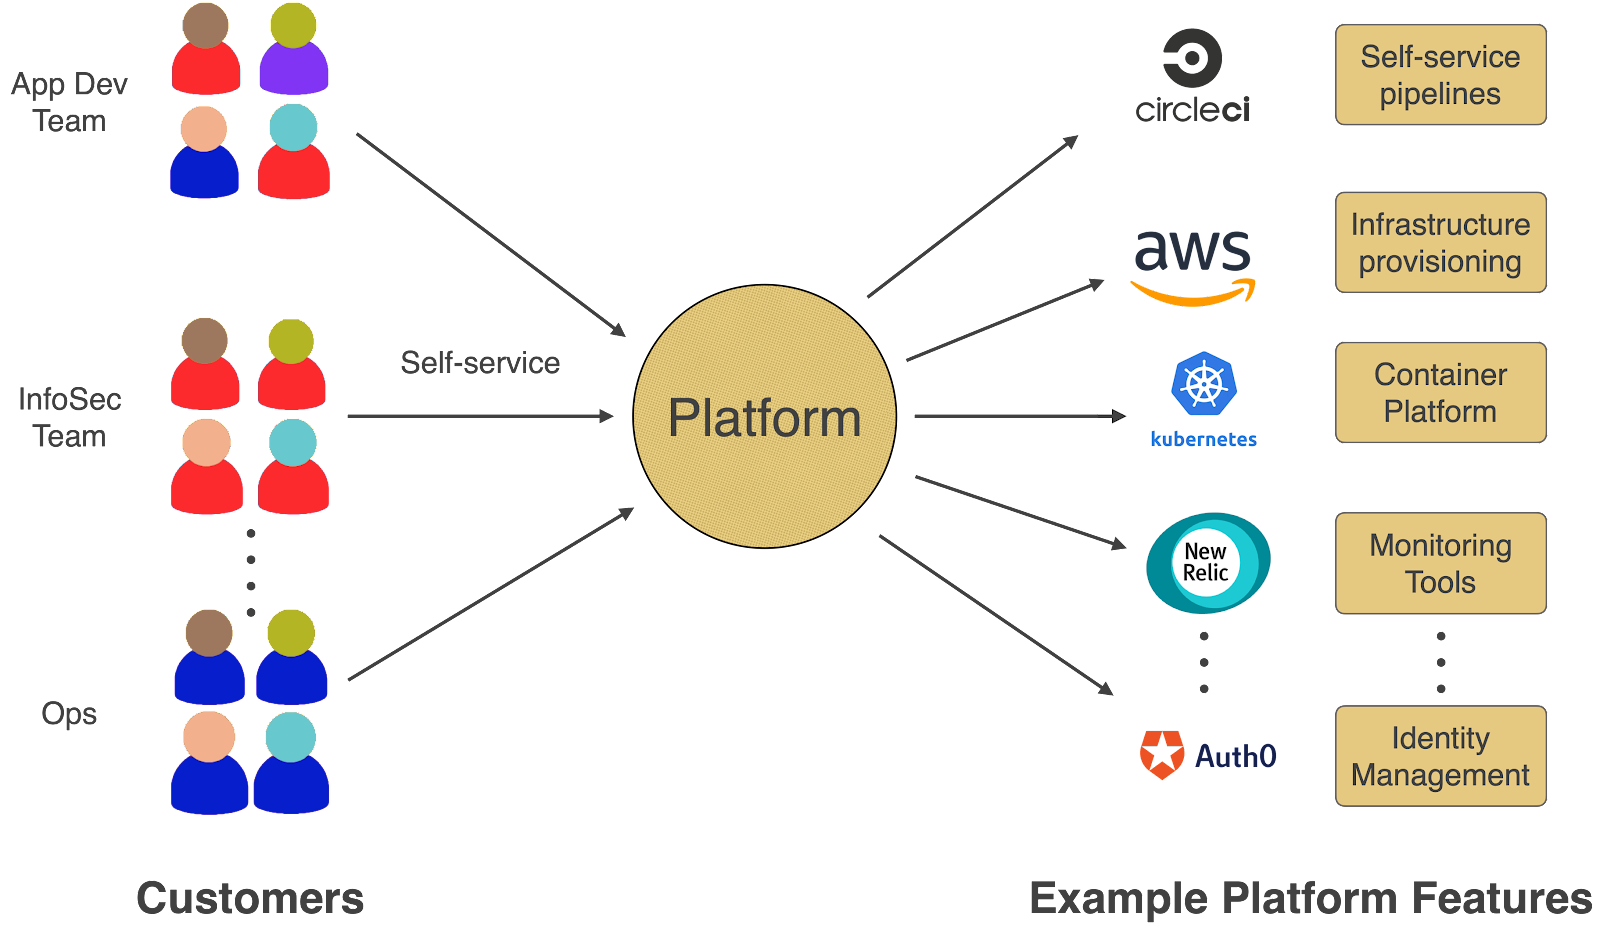
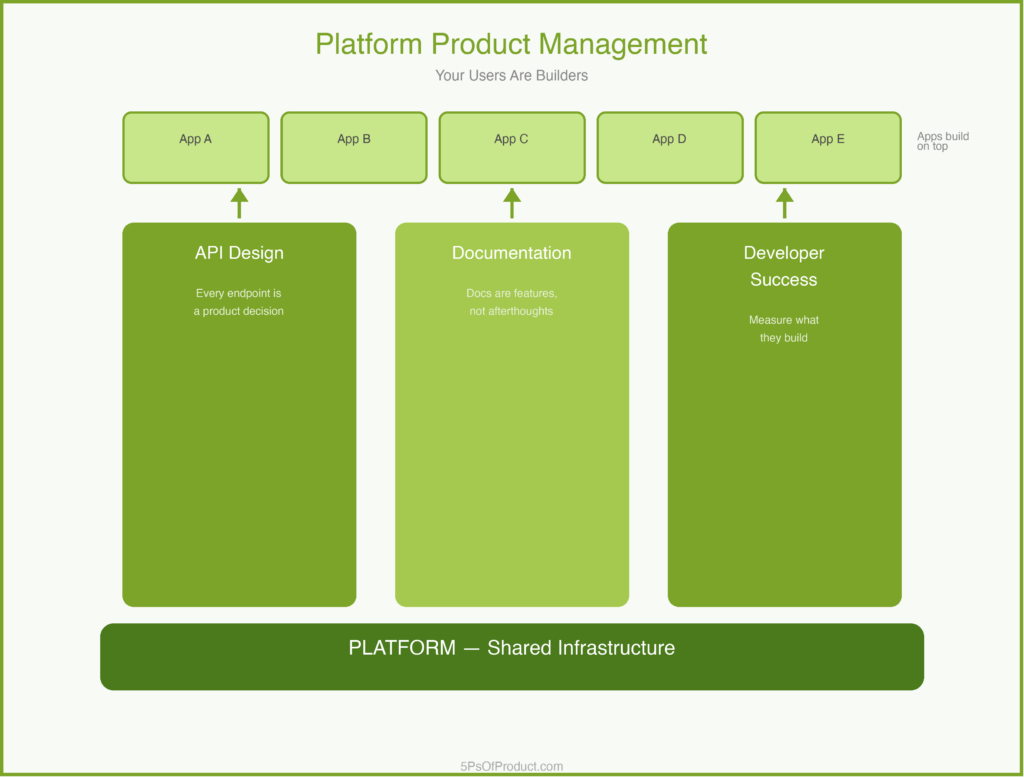
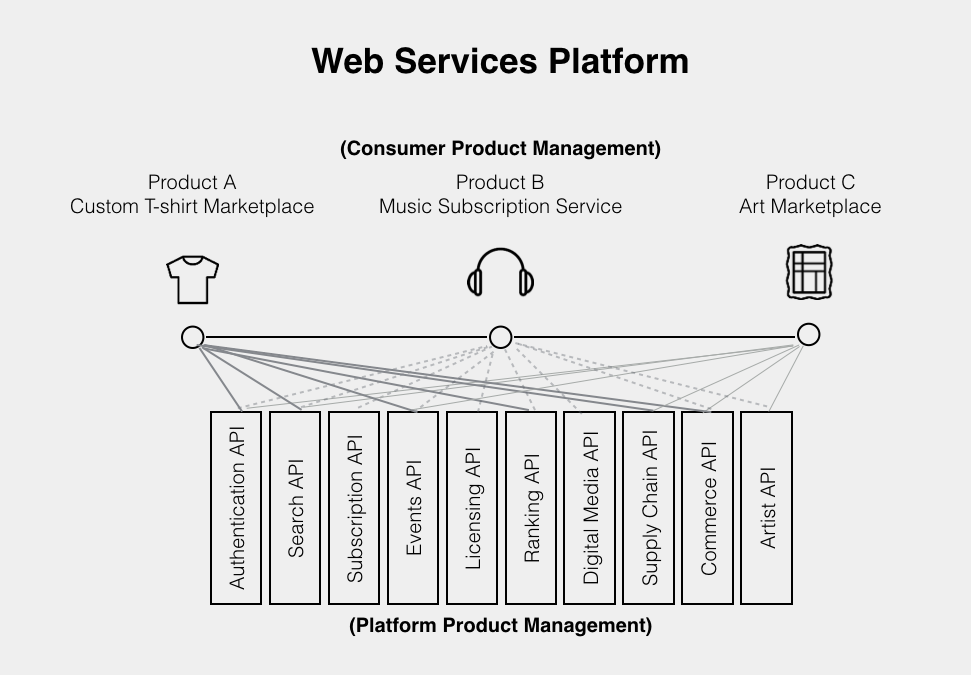
At its core, platform product management is the discipline of treating internal infrastructure as a product. That means the developers, data scientists, and ops engineers who consume your APIs, SDKs, or deployment pipelines are your users. They have roadmaps, requirements, and complaints just like external customers. The difference is you can't fire them when they're unhappy. They're your coworkers. Here's the part most job postings skip: platform PM work splits roughly into three buckets. First is the consumer experience layer — understanding what your internal teams actually need and translating that into product specifications for your platform. Second is the governance and policy layer — deciding versioning strategies, deprecation timelines, and what happens when someone breaks backward compatibility. Third is the platform economics layer — figuring out cost allocation, usage metrics, and whether your platform is actually cheaper than the alternatives your teams could build themselves. The real job is keeping all three from colliding. I once watched a platform PM get promoted because she shipped a new auth service that eliminated 40% of our login-related support tickets. Six months later, the same service became the bottleneck for our onboarding flow because the team that owned it had optimized for security checks over latency. The product hadn't changed. The context had.
How the actual work looks day to day
Most platform PM roles require you to maintain a platform roadmap that operates on completely different timelines than feature teams. Feature teams work in two-week sprints. Platform work tends to move in quarters because you're dealing with systems that other systems depend on. You can't hot-swap a database connector the way you can change a button color. I kept a running priority matrix that tracked three things: dependency risk (how many teams would break if this shipped late), debt exposure (what legacy systems we were carrying and when they'd become unmanageable), and consumer demand signal (what teams were actually asking for versus what leadership assumed they needed). The matrix lived in a shared spreadsheet that nobody checked after the first quarter. But I used it to justify saying no to about sixty percent of incoming requests, which is the actual core competency of the role. One specific edge case that still keeps me up at night: we had a situation where a data engineering team needed to extend an API we maintained for their pipeline, but doing so would have required changes that broke three other teams' integrations. The engineering director wanted to push forward anyway. What I did was run a cost-benefit analysis that quantified the exact engineering hours at risk — approximately 120 hours across three teams — versus the estimated 40 hours the data team would save. I presented it with hard numbers instead of opinions. They killed the extension and built a workaround. It took them twice as long but nobody's deployment pipeline broke.
Get the Full Details
The frameworks that actually matter
InnerSource is the practice of applying open-source principles internally — teams can fork, modify, and contribute back to platform code rather than working through a central team. This works when your platform is mature and well-documented. It fails spectacularly when your platform is unstable or your documentation is three versions behind the actual codebase. Platform as a Product (capital P) frameworks from companies like Spotify and Netflix emphasize treating internal platforms with the same rigor as external products. This means dedicated product owners, clear SLAs, consumer advisory boards, and formal deprecation policies. The Spotify model specifically recommends platform teams having their own roadmap and not being allocated to feature work. In practice, most organizations try to implement this framework while simultaneously underfunding platform teams by 40% compared to feature teams. Don't let the case studies fool you. API-first development is another framework that matters, but it's less about the technology and more about the contract. When you define your API surface before writing implementation code, you create a stable contract that consumers can depend on. The problem is most platform teams start with the implementation first because leadership wants quick results. Then they retrofit API contracts afterward, which creates a gap period where consumers are building against undocumented behavior that changes unexpectedly.
Where this approach breaks down completely
Platform product management assumes you have enough organizational maturity to support it. If your company is under fifty engineers, you probably don't need a dedicated platform PM. The roles collapse into your senior engineering manager or CTO anyway. If your platform has fewer than three consumer teams, you're better off being hands-on engineering rather than product management. The biggest failure mode I've seen is when platform teams start optimizing for platform metrics instead of consumer outcomes. You'll see this when a team measures success by number of APIs served or platform uptime rather than by whether their consumers are shipping faster. High platform uptime means nothing if your consumers are spending two weeks waiting for your release cycles. I watched one platform team celebrate a 99.99% uptime quarter while their average consumer deployment time had increased by 300% because the platform added four new mandatory validation steps. Another failure pattern: platform teams that become bottlenecked gatekeepers instead of enablers. When every change requires a ticket to your platform team and you have a four-week backlog, you're not providing governance. You're providing friction. The teams that get around it build shadow platforms. Then you lose visibility entirely and have to deal with the technical debt later.
What to measure that isn't bullshit
Avoid measuring platform success by internal ticket volume. That just measures how many problems your platform generates. Instead, track time to first deployment — how long it takes a new team to get their service onto your platform and deploy their first change. I've seen this number vary from four hours for well-documented platforms to six weeks for poorly supported ones. The variance tells you more than any satisfaction survey. Consumer retention rate is another metric that matters. What percentage of teams that adopt your platform continue using it after their first project? If it's below eighty percent, your platform has a product-market fit problem even though you're not selling to external customers. Teams will vote with their feet by building custom solutions or using competing internal platforms. The metric I recommend most strongly is incident attribution rate. When something breaks, what percentage of incidents can be traced back to platform issues versus consumer implementation issues? A healthy platform team should aim for below twenty percent. If it's above thirty, your platform has fundamental stability problems that no amount of documentation will fix.
Alternatives when platform PM isn't the answer
If your organization is small or rapidly changing, consider whether a central engineering team model might serve you better. One team owns all infrastructure and you don't bother with platform product management at all. It scales poorly but it's faster to implement and requires fewer coordination overheads. Most startups I've worked with operated this way until they hit about two hundred engineers, at which point the coordination costs become painful enough that platform structures become necessary whether anyone likes them or not. Another alternative is the you build it, you run it model where individual teams own their entire stack. This eliminates platform PM work entirely but requires teams to have strong senior engineering presence and tends to produce inconsistent infrastructure quality. I've seen it work well at well-funded companies with experienced engineering leadership. I've also seen it create a maintenance nightmare at companies where junior engineers were left to figure out observability and deployment tooling on their own. There's also the buy over build strategy where you purchase platform solutions instead of building internal ones. This removes most of the platform PM responsibilities but introduces vendor lock-in and limits customization. The tradeoff is usually worth it if you're not in a business where your platform technology is a competitive differentiator.
What I wish someone had told me on day one
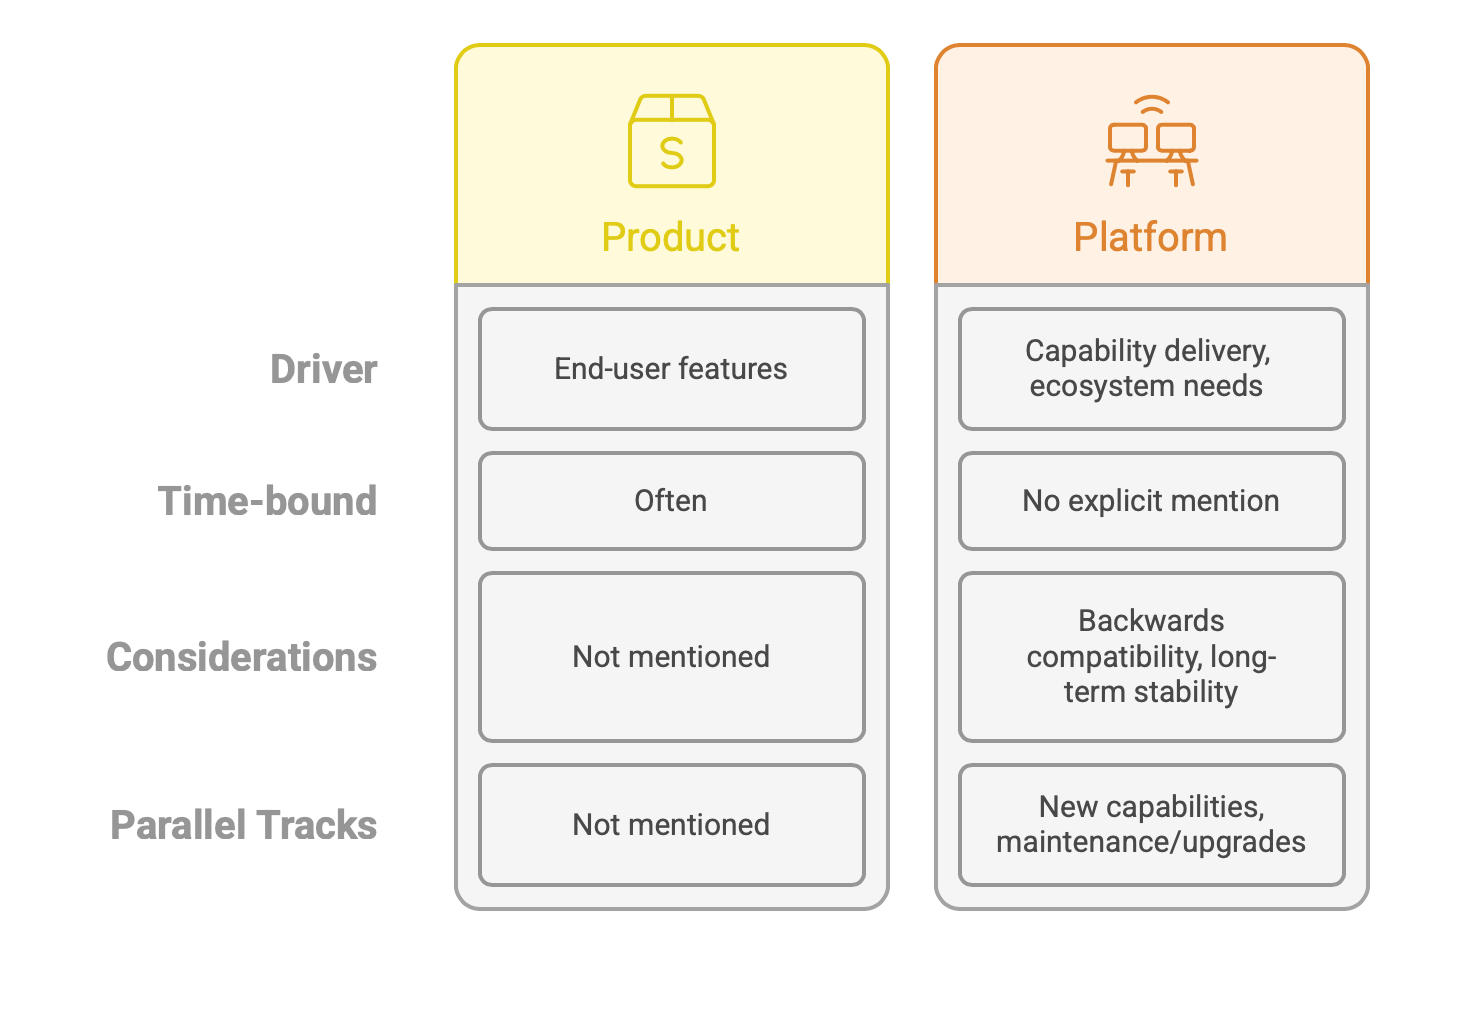
Your success as a platform PM is inversely proportional to how visible your work is. When you're doing it right, other teams deploy faster, incident rates drop, and nobody mentions your platform because everything just works. The moment your platform becomes a talking point in leadership meetings, something has gone wrong. I spent my first year trying to get recognition for platform improvements. By year three I'd learned that the best platform work is invisible work. The second thing: learn to say no with data instead of opinion. Platform PM is mostly a diplomacy role dressed up as product management. You're constantly negotiating between teams that want different things. Your currency is evidence — usage data, incident reports, performance benchmarks. Without that, you're just another person saying no for no reason, and nobody will listen to you for long. Finally, understand that platform product management is fundamentally different from feature product management because your consumers can't leave. This changes the incentive structure in ways most PMs don't anticipate. With external products, you have market discipline forcing you to deliver value. With internal platforms, the discipline comes from keeping your consumers from building workarounds. The threat of churn exists, but it's quiet churn — engineers quietly building side tools, using different services, or finding workarounds that bypass your platform entirely. Your job is to detect that churn before it becomes organized opposition.
I still get questions about this from people starting out. The honest answer is that there's no perfect framework or handbook. Every platform organization has different constraints, different cultures, and different technical debt. What works at a nine-hundred-person company with mature engineering practices falls apart at a two-hundred-person company that's still figuring out what its product strategy is. Pay attention to your specific context more than any advice you read online.