The Method Behind the Madness
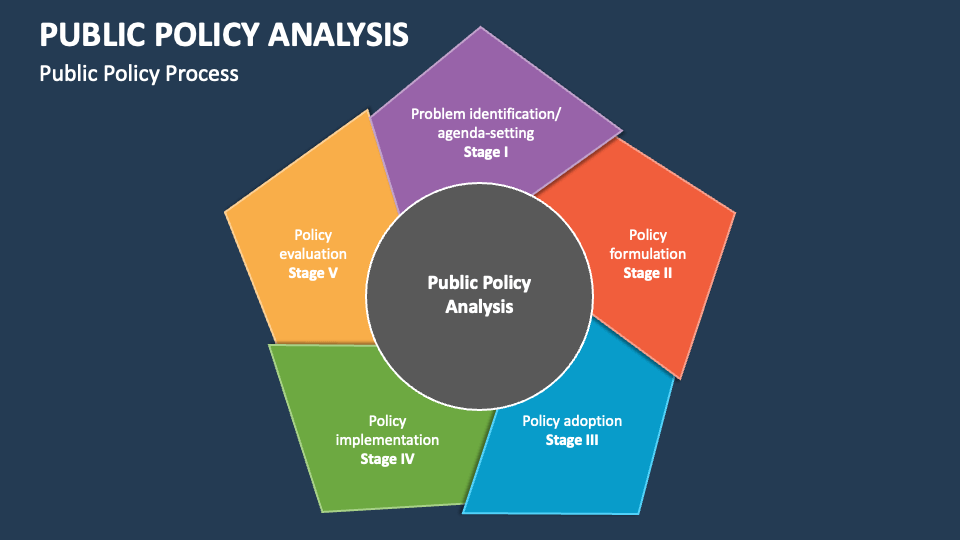
Policy analysis is basically the structured process of examining a public problem, identifying possible solutions, and evaluating which one actually makes sense when you factor in politics, money, and implementation constraints. That sounds like a textbook definition because most textbooks treat it like a four-step recipe. It isn't. The reality is messier, slower, and usually involves far more spreadsheet work than anyone admits in an academic program. I spent about six years doing this for state-level transportation and public health initiatives. What I learned quickly is that the analytical framework matters less than understanding who has incentives to distort the data. A cost-benefit analysis can be technically flawless and still lead to the wrong recommendation if you ignore the political economy around the policy. That's not a criticism of the method. That's just how it works in practice.
What Is Policy Analysis and Why People Get It Wrong
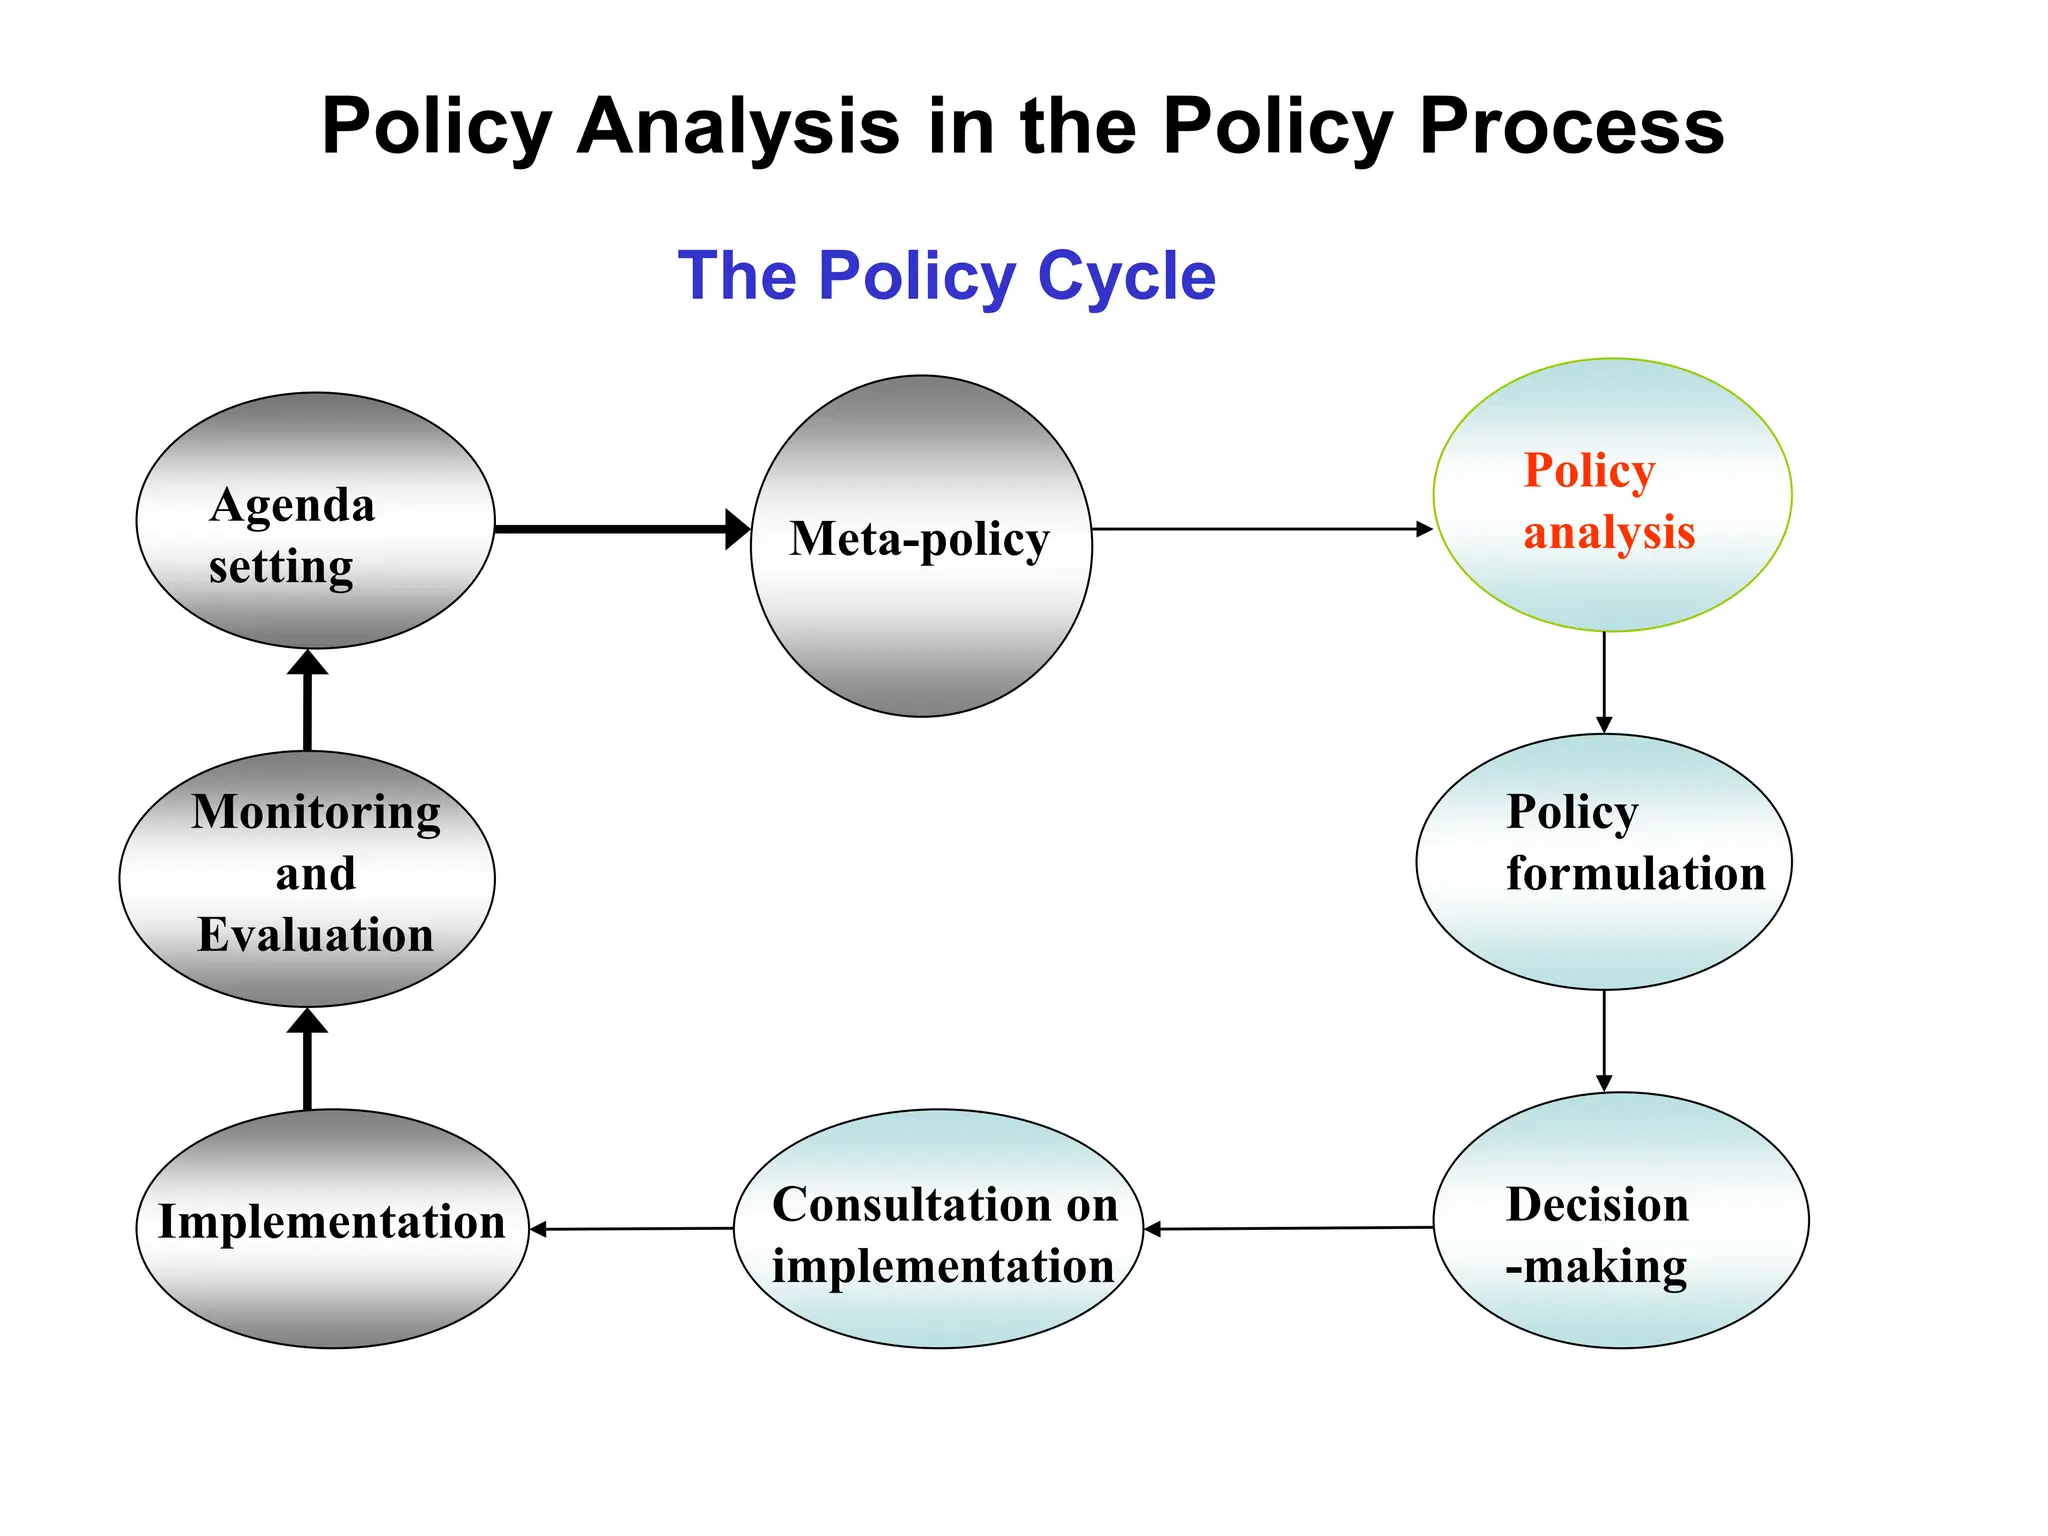
At its core, What Is Policy Analysis breaks down into examining a problem statement, collecting and cleaning relevant data, modeling outcomes under different scenarios, and presenting findings in a way that decision-makers can actually act on. The tricky part is that most people conflate the evaluation with the advocacy. You produce an analysis. Someone else uses it to push a position. Your job is to keep those two things separate, which sounds easy until you're being asked by a legislator's office to "verify" a number that doesn't exist in your dataset. The most common mistake I see from beginners is treating policy analysis as purely quantitative. It's not. Qualitative factors—stakeholder preferences, administrative capacity, public acceptance—are often the difference between a policy that passes on paper and one that gets quietly shelved after the election cycle turns. I once spent three weeks building a regression model to evaluate a housing subsidy program, only to find out the local housing authority couldn't process more than fifty applications per month regardless of what the funding said. The math was irrelevant. The bottleneck was administrative throughput.
How It Actually Works in Practice
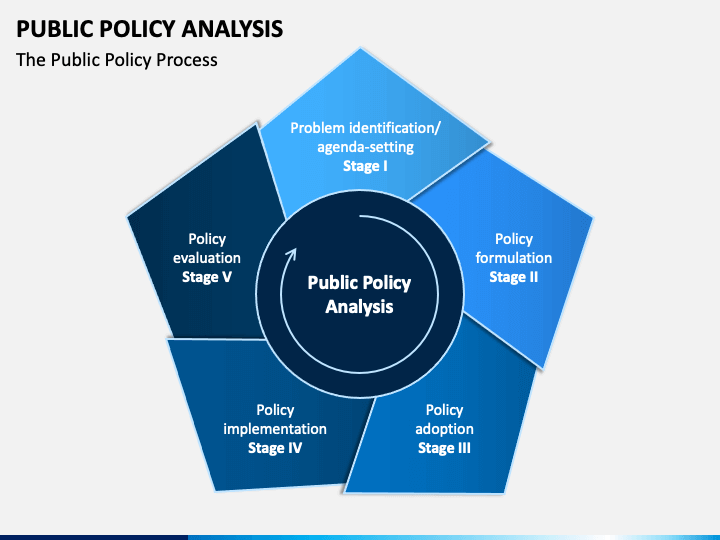
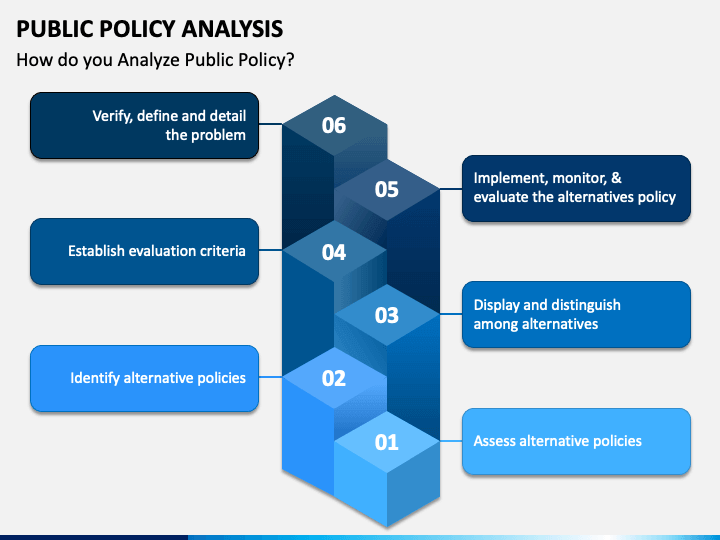
Start with the problem definition. This is where most analyses quietly fail. If you can't articulate the problem in one or two sentences that a non-expert would understand, you don't have a problem. You have a vague concern. A well-defined problem includes the affected population, the current baseline, and the measurable gap between where things are and where they should be. "Too many people are driving drunk" is not a problem statement. "In county X, impaired driving crashes cost $14 million annually in emergency services and property damage, with a 22 percent recidivism rate among cited offenders" is something you can actually analyze. From there you identify policy options. Not just the obvious ones. The interesting work is in the second and third-tier alternatives that stakeholders aren't already fighting over. Standard approaches like regulatory mandates, tax incentives, and informational campaigns are table stakes. The options that usually survive initial screening are the ones that redistribute costs in ways that don't trigger organized opposition. That's not cynical. That's just how budget cycles and interest groups function. When you get to evaluation criteria, pick them before you know the answers. I learned this the hard way during a public safety initiative where we were evaluating reduced sentencing protocols. Our original criteria emphasized recidivism rates and courtroom processing time. About halfway through the analysis, a prominent advocacy group pushed us to add "community trust metrics" and "victim satisfaction scores" as evaluation criteria. Both are legitimate concerns, but introducing them after the fact skewed the entire weighting framework. If you're going to add criteria mid-process, document exactly when and why, and re-run the sensitivity analysis. Otherwise you've just introduced confirmation bias dressed as rigor.
Get the Full Details
A Specific Case That Changed How I Work
A few years back I was analyzing a workforce development grant program for a mid-sized city. The program promised to reduce unemployment among displaced manufacturing workers by linking training slots to employer hiring commitments. The data looked clean on the surface. Participation rates were high, completion rates exceeded eighty percent, and wage gains at twelve months showed a statistically significant increase of roughly seven percent over the control group. But when I dug into the employer-side data, I found something that made the whole evaluation collapse. The "hiring commitments" were defined loosely enough that employers could count seasonal or temporary positions as fulfillment. The actual long-term employment retention at eighteen months was barely above the control group. The program wasn't failing to produce short-term gains. It was failing to distinguish between jobs that lasted and jobs that existed on paper for payroll reporting. I had to rewrite the evaluation framework to track eighteen-month retention as a primary outcome instead of a secondary footnote, which shifted the conclusion from "moderately effective" to "structurally flawed." That rewrite took about a week and forced a complete reconsideration of the grant's renewal. The grant got restructured. Not eliminated, but changed in ways that actually addressed the attrition problem instead of burying it.
Advanced Nuances Beginners Miss
One thing that rarely gets taught in introductory courses is the concept of policy feedback loops. Policies don't just solve problems. They create new political coalitions and institutional interests around themselves. A welfare program that starts as a safety net will eventually develop an administrative apparatus with its own budget, staffing incentives, and constituent base. That apparatus will resist evaluation findings that suggest restructuring or downsizing, not because the data is wrong, but because the institution's survival depends on the program's continuation in its current form. Understanding feedback loops means you stop asking "does this policy work" and start asking "who benefits from this policy continuing to exist regardless of whether it works." Another counter-intuitive point: robustness often matters more than accuracy in policy analysis. A slightly less precise estimate that holds up under reasonable changes in assumptions is more useful than a sharply precise estimate that collapses when you adjust the discount rate by two percentage points. I've seen analysts get burned by this repeatedly. Decision-makers don't need the single best number. They need to understand the range of plausible outcomes and which variables matter most. A tornado diagram showing sensitivity to five key parameters is worth more than a Monte Carlo simulation with thirty inputs that everyone ignores because it produces an intimidating output nobody can interpret.
Where It Falls Apart
Policy analysis has real limitations that people in the field don't always want to discuss publicly. The first is data availability. You will almost never have the data you want. You'll have the data that someone collected for a different purpose, in a different format, with different definitions. Cleaning that data usually consumes forty to sixty percent of a project's timeline. I've seen well-designed evaluations derailed entirely because the source agency changed its reporting categories halfway through the study period, making before-and-after comparisons statistically invalid. The second limitation is temporal mismatch. Policy problems operate on election cycles and budget years. Academic-style analysis operates on six-to-eighteen-month research timelines. By the time your evaluation is complete, the political context has usually shifted enough that the recommendations are either too late or irrelevant. This isn't a failure of the analysis. It's a structural feature of how governance works. The workaround is to build phased deliverables into your project plan. An initial scoping brief within three weeks, a preliminary findings memo at four months, and the full analysis at eight. Decision-makers will read the brief. They won't read the monograph. The third limitation, and the one that drives the most frustration, is that policy analysis can identify what's effective but rarely determines what will be chosen. The political selection mechanism is opaque and driven by factors—fundraising needs, coalition management, media cycles—that are largely immune to analytical persuasion. I've produced analyses where the data overwhelmingly supported option A, the legislative committee heard the testimony, reviewed the evidence, and chose option C because it had a cooler acronym and a champion with better relationships on the appropriations committee. That's not a reason to stop doing analysis. It's a reason to calibrate your expectations.
Practical Approaches That Actually Help
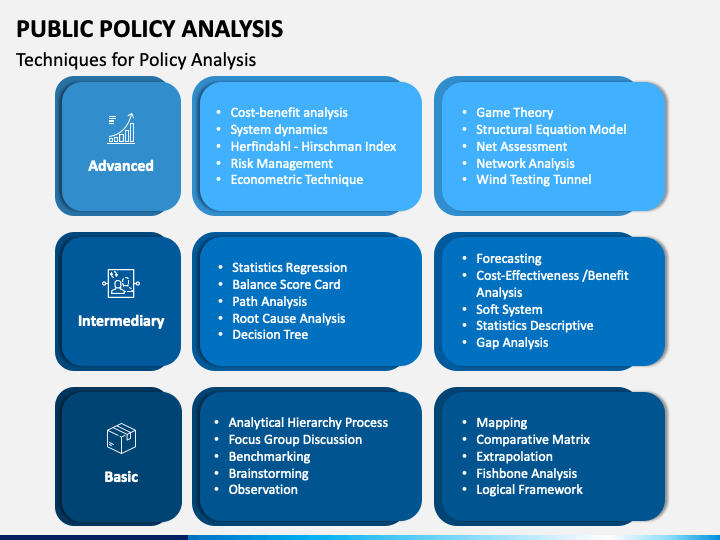
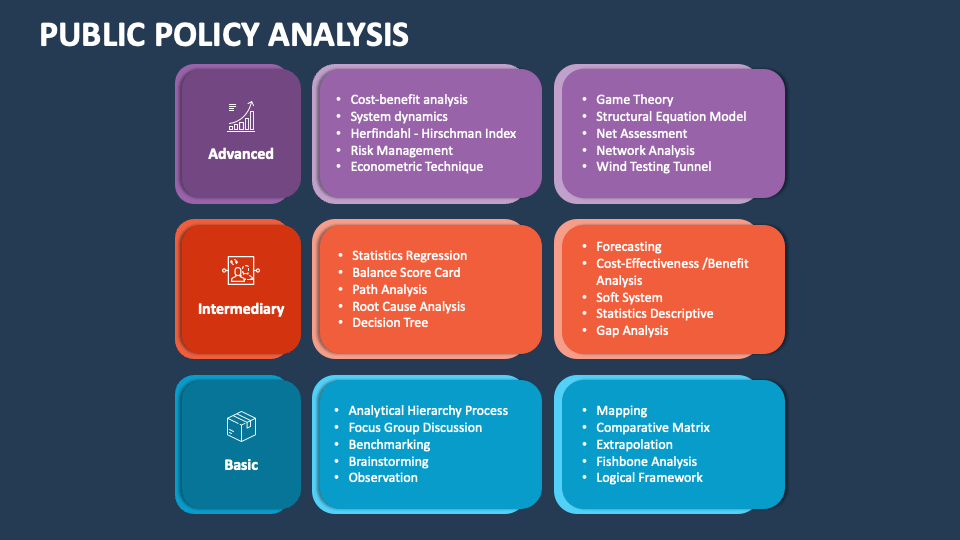
If you're getting started, don't try to master every evaluation method. Learn to recognize which question requires which tool. A question about distributional effects needs incidence analysis. A question about long-term returns needs cost-benefit analysis with appropriate discounting. A question about stakeholder feasibility needs qualitative methods like structured interviews or Delphi techniques. The mistake most people make is applying a single framework to every problem. That's like using a hammer for every task because you're good with a hammer. Build a personal toolkit rather than memorizing textbooks. I keep a running folder of actual evaluation reports I've encountered, both good and bad, organized by policy domain and methodology. When a new project comes up, I review three or four similar past analyses before writing a single line of my own protocol. This usually saves two or three days of reinventing frameworks that already exist. You'll also start noticing patterns in how different agencies report data, which helps you anticipate cleanup work before it bites you. Learn to write for the audience that will actually read your work, not the audience that will cite it. Legislative staff members skim. Agency directors scan. Elected officials read the executive summary if they read anything at all. Put your main finding in the first paragraph. Support it in the second. Methodology details go in an appendix unless they're directly relevant to interpreting the result. A twenty-page analysis with a one-page executive summary that accurately captures the key findings and uncertainties will have more real-world impact than a hundred-page monograph that gets filed and forgotten.