Polynomials are just sums of variables and coefficients
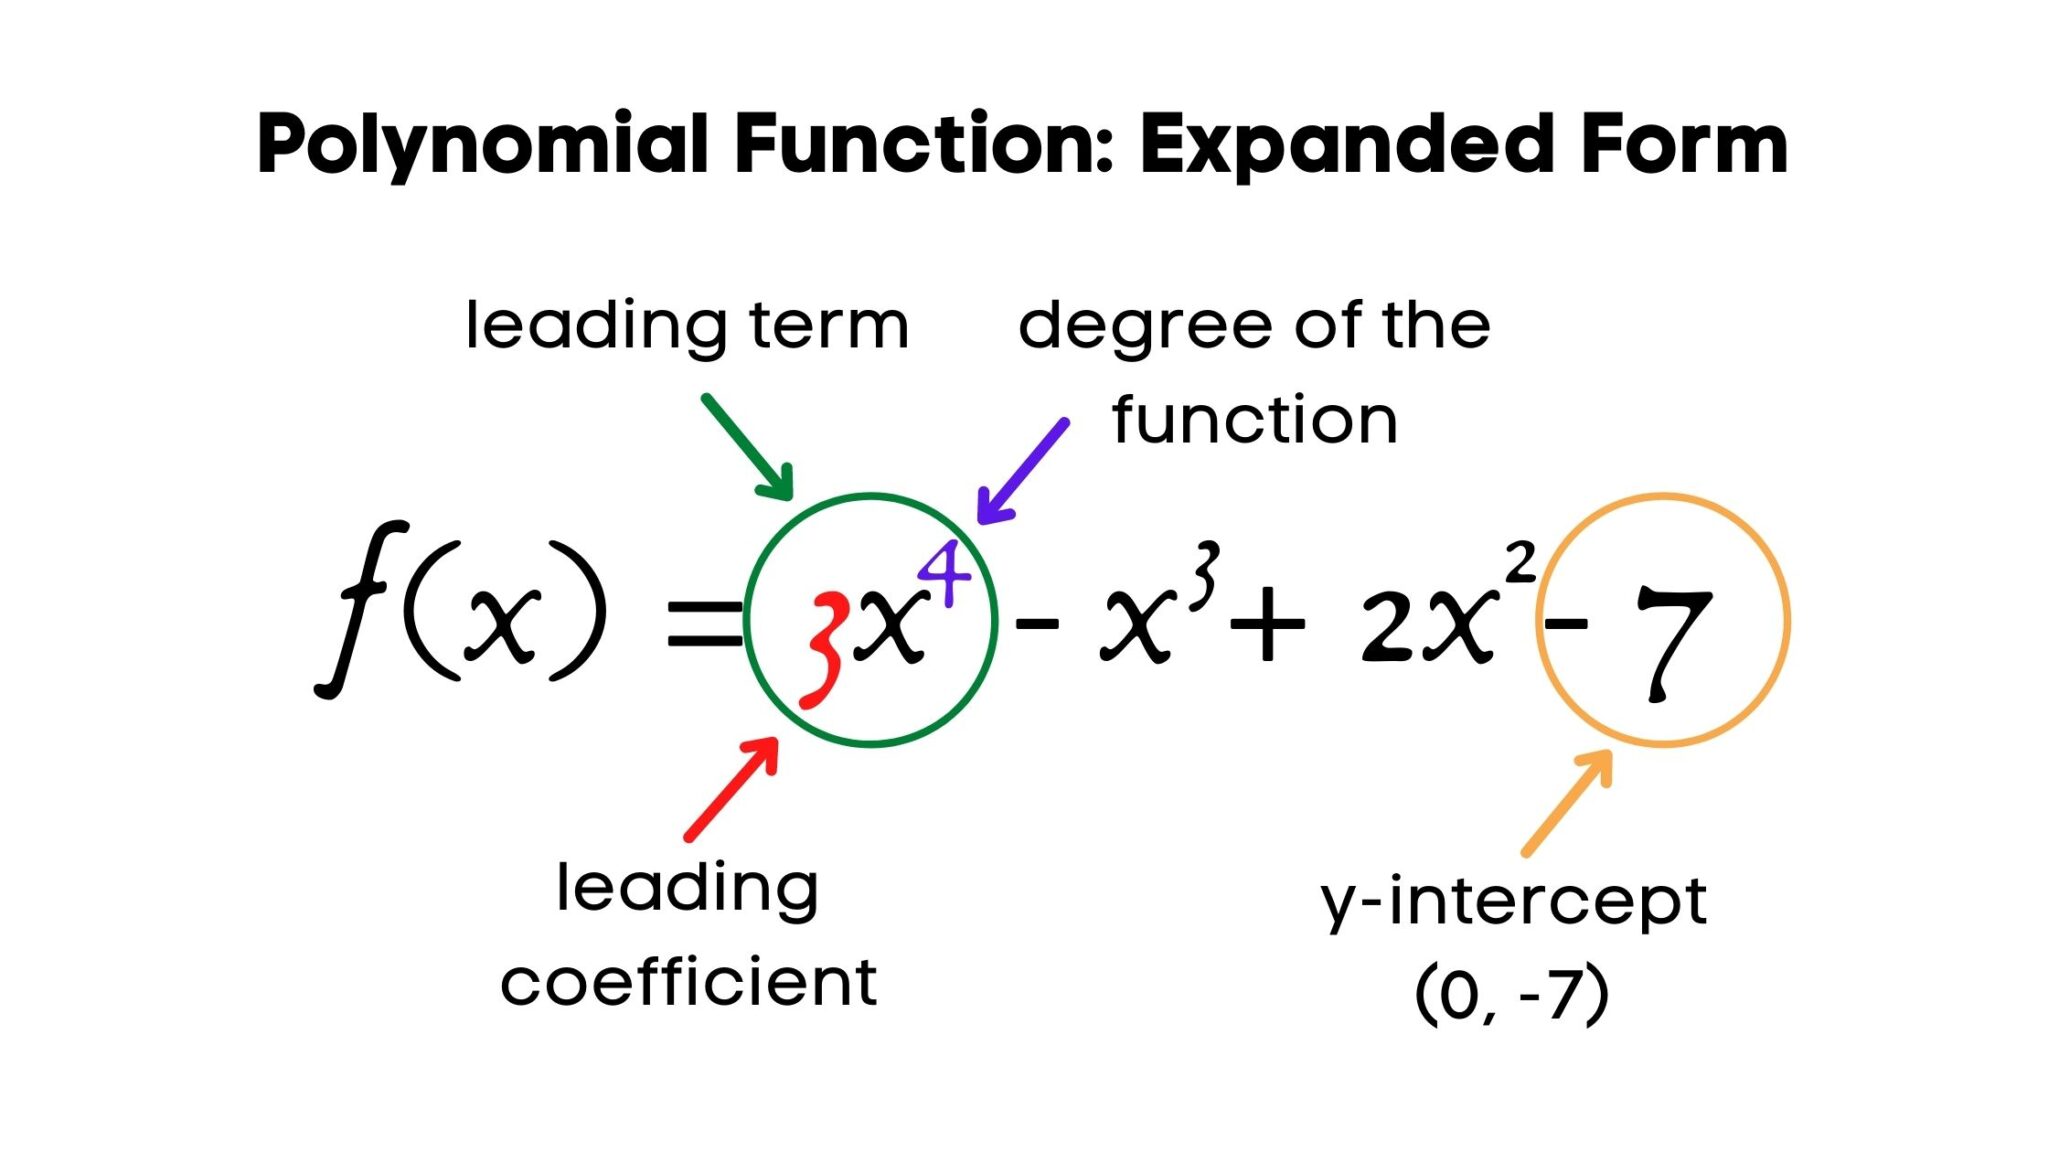
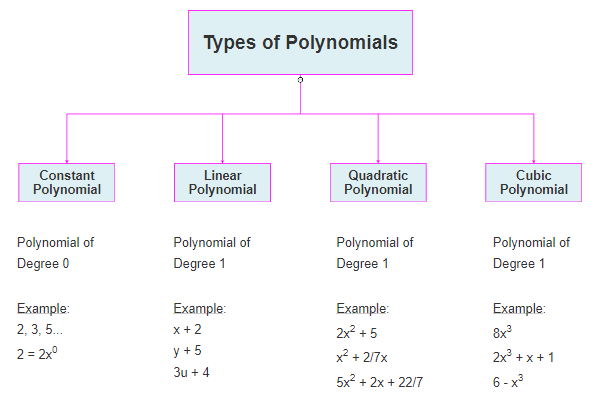
You've probably seen them in algebra class. Something like 3x² + 2x - 5. That's it. That's the whole thing. A polynomial is an expression made by adding together terms where each term is a constant multiplied by a variable raised to a non-negative integer power. There's not much more to say about the definition. The confusion usually comes from what people assume polynomials can and can't do, which is where most students hit walls later on. I spent years debugging numerical simulations where polynomial approximations were the primary tool. You'd think this is basic stuff from a first-year course, but the gap between knowing what a polynomial is and actually using one without introducing subtle errors is wider than most people expect. Let me walk through how this actually works in practice. A polynomial in one variable has the general form ax + ax¹ + ... + ax + a where n is a non-negative integer and each a is a coefficient. The degree of the polynomial is the highest power with a nonzero coefficient. A constant like 7 is technically a degree-0 polynomial. A linear expression like 4x + 1 is degree 1. The degree matters because it determines the shape of the graph and, more importantly, how many roots the polynomial can have.
Polynomials in multiple variables work the same way. Take 2x²y + 3xy³ - y + 1. The degree of each term is the sum of the exponents in that term. The term 3xy³ has degree 4 (1 + 3). The whole polynomial's degree is 4. That's straightforward. What's not straightforward is what happens when you try to fit one to real data.
Building and Fitting Polynomials
The most common practical use of polynomials is curve fitting. You have a set of data points and you want a smooth function that approximates the trend. Least squares regression is the standard approach. Given n data points, you can fit a polynomial of degree at most n-1 that passes exactly through every point. That's polynomial interpolation, and it sounds great until you try it with more than about 10 points. Here's the thing that almost no introductory course emphasizes: high-degree polynomial interpolation is numerically unstable. As the degree increases, the interpolating polynomial starts oscillating wildly between your data points, especially near the edges. This is called the Runge phenomenon and it's not a theoretical curiosity. I encountered it directly while fitting a spectroscopic calibration curve. I had 15 wavelength-intensity data points and decided a degree-14 interpolating polynomial would give me perfect accuracy. Instead, the polynomial oscillated by over 40% between the endpoints and the center of the range. The fit was worse than a simple linear regression at the edges. The workaround is not to fight it with higher degrees. It's to use lower-degree polynomials with regularization or switch to piecewise polynomials like splines. For my calibration problem, a cubic spline with natural boundary conditions reduced the maximum error from about 40% down to roughly 2%. That's the difference between a usable instrument and garbage data. The cubic spline approach is more work to set up but it's dramatically more reliable.
Get the Full Details

Roots and Factoring
Finding the roots of a polynomial means solving p(x) = 0. For degree-1 polynomials, it's trivial. For degree-2, the quadratic formula works. Degree-3 and degree-4 have closed-form solutions too, though they're messy enough that nobody uses them by hand anymore. Starting at degree 5, there is no general algebraic solution. This was proved by Abel and Galois in the early 1800s and it still surprises people who think math has neat answers for everything. In practice, you use numerical methods. Newton's method converges quickly if you start close to a root. The Durand-Kerner method finds all roots simultaneously and is what most numerical libraries use under the hood. I learned this the hard way when a colleague was trying to factor a degree-8 polynomial by hand for a control systems project. He spent three days going down dead ends with rational root theorem attempts before I showed him that a companion matrix eigenvalue approach would give all the roots in about ten minutes on a laptop. The rational root theorem is worth knowing because it tells you where to look first. If your polynomial has integer coefficients and the constant term is 12 and the leading coefficient is 2, then any rational root must be a divisor of 12 divided by a divisor of 2. That gives you a finite list to test: ±1, ±2, ±3, ±4, ±6, ±12, ±1/2, ±3/2, ±5/2, etc. You test them, and if one works, you factor it out and reduce the degree. It's a legitimate technique for textbook problems and sometimes for engineering problems where the coefficients are clean integers. It fails fast when the roots are irrational or complex.
Evaluation and Computation
Evaluating a polynomial at a specific value seems like it should be trivial, but the naive approach of computing each power separately is inefficient and prone to floating-point error. Horner's method is the standard. It rewrites the polynomial as a nested expression: ax + ax¹ + ... + a becomes (...((ax + a)x + a)x + ... )x + a. This reduces the number of multiplications from O(n²) to O(n) and generally improves numerical stability. I've seen production code that evaluated polynomials term by term and got wildly wrong results for high-degree polynomials at large x values. A degree-10 polynomial evaluated at x = 100 with coefficients on the order of 10 produced results that differed from Horner's method by several orders of magnitude. The issue wasn't the math, it was that computing x¹ separately and then scaling by the coefficient amplified floating-point rounding errors at each step. Switching to Horner's method fixed it completely. This is the kind of thing that doesn't show up in lectures but costs people hours of debugging.
Common Pitfalls and Where Polynomials Break Down
Polynomials are powerful but they have well-defined limitations. Here's what you need to know before you reach for one. They can't model asymptotic behavior. A polynomial always goes to positive or negative infinity as x goes to positive or negative infinity. If your data has a horizontal asymptote, a polynomial will eventually diverge from it no matter how high the degree. I worked on a project modeling reaction kinetics where the concentration approached a steady state. Someone tried a degree-6 polynomial fit and it blew up outside the calibration range, predicting negative concentrations. A rational function or exponential model would have been appropriate from the start. Overfitting is a real risk with limited data. A degree-n polynomial through n+1 points is an exact interpolant, not an approximation. Every measurement error gets baked into the coefficients. If your data has noise, which it always does, a high-degree polynomial will chase the noise instead of the signal. The rule of thumb is to keep the degree below roughly one-fifth of your data points for fitting, not interpolation. There are statistical tests for this, but in practice you just check the residuals and see if they look random or structured. Structured residuals mean your model is wrong.
Polynomials struggle with discontinuities and sharp turns. If your function has a jump discontinuity or a very sharp peak, polynomials will smear it out. You'd need a very high degree to approximate a step function, and even then you'd get Gibbs-like oscillations near the discontinuity. Wavelets or piecewise constants are better choices there. I ran into this when trying to approximate a digital signal's step response with a single polynomial. The result was a sluggish curve that missed the transition entirely. Switching to a piecewise quadratic spline captured the step in about three segments. Taylor series are polynomials but they have a limited range. A Taylor polynomial approximates a function locally around a point. The approximation gets worse as you move away from that point. People often forget this and apply a Taylor polynomial globally. A fifth-degree Taylor expansion of sin(x) around 0 is accurate to about 0.001 for |x|
1 but the error grows to about 0.15 at x = 2 and becomes meaningless beyond that. Chebyshev approximation minimizes the worst-case error over an interval and is preferable when you need uniform accuracy across a range rather than just near a single point.
When Polynomials Are the Right Tool
Despite all the limitations, polynomials are still the default choice in many situations and for good reason. They're easy to differentiate and integrate analytically. They're computationally efficient to evaluate. Most numerical libraries have optimized polynomial routines. If your function is smooth and your range is moderate, a low-to-moderate degree polynomial will give you good results with minimal setup. The key is matching the degree to the problem. Linear models for trends that look straight. Quadratic or cubic for smooth curves with one or two turning points. Splines when you have a wider range or need to capture local features without global oscillation. Reserve high-degree single-polynomial fits for interpolation problems where you know the function is truly polynomial and your data is essentially noise-free. That combination is rarer than you'd think. If you need a quick implementation, numpy.polyfit and numpy.polyval in Python handle least-squares fitting and evaluation. scipy.optimize.root can find roots numerically. For interpolation, scipy.interpolate offers both polynomial and spline options, and the spline versions are almost always the safer choice for real data. On the C side, GNU Scientific Library has polynomial routines, and MATLAB's built-in polyfit is still one of the more straightforward options if you have a license.
What Is Polynomial In Mathematics From a Practical Standpoint
At the end of the day, a polynomial is just a flexible function approximator with well-understood properties and well-known failure modes. The mathematics behind it is clean. The application is where you earn your keep. Know the degree limits, watch for oscillation, prefer lower degrees when possible, and don't pretend a fitted polynomial knows your data better than your data actually does.