QTL mapping is one of those techniques everyone learns about in grad school and then quietly curses at for the next two years.
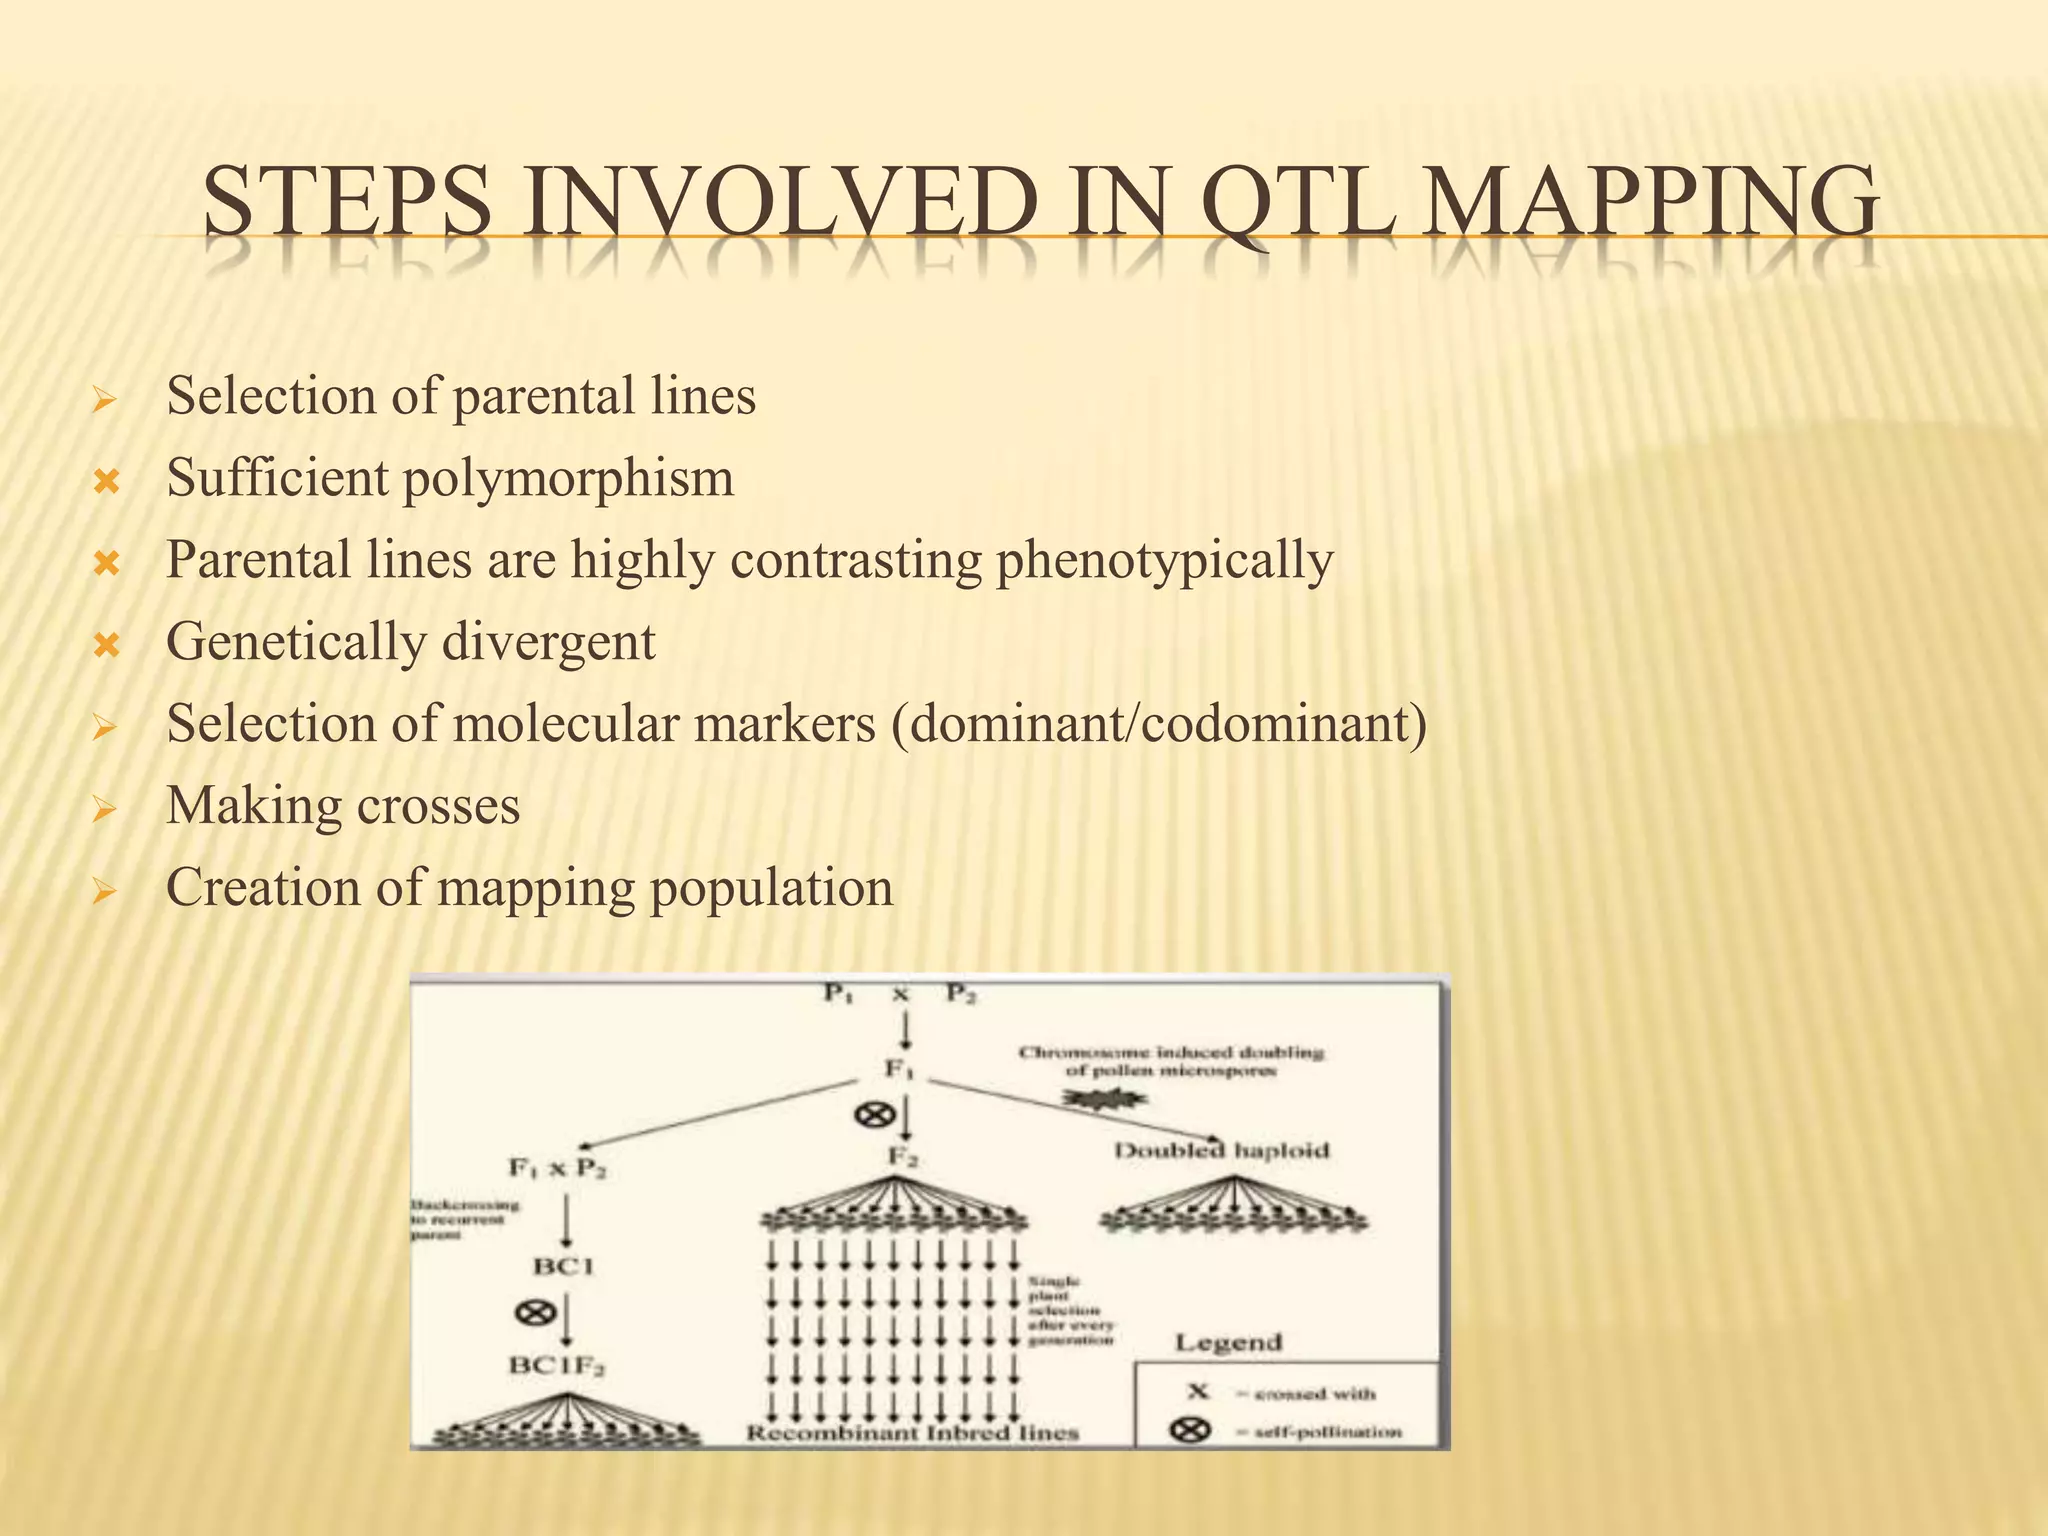
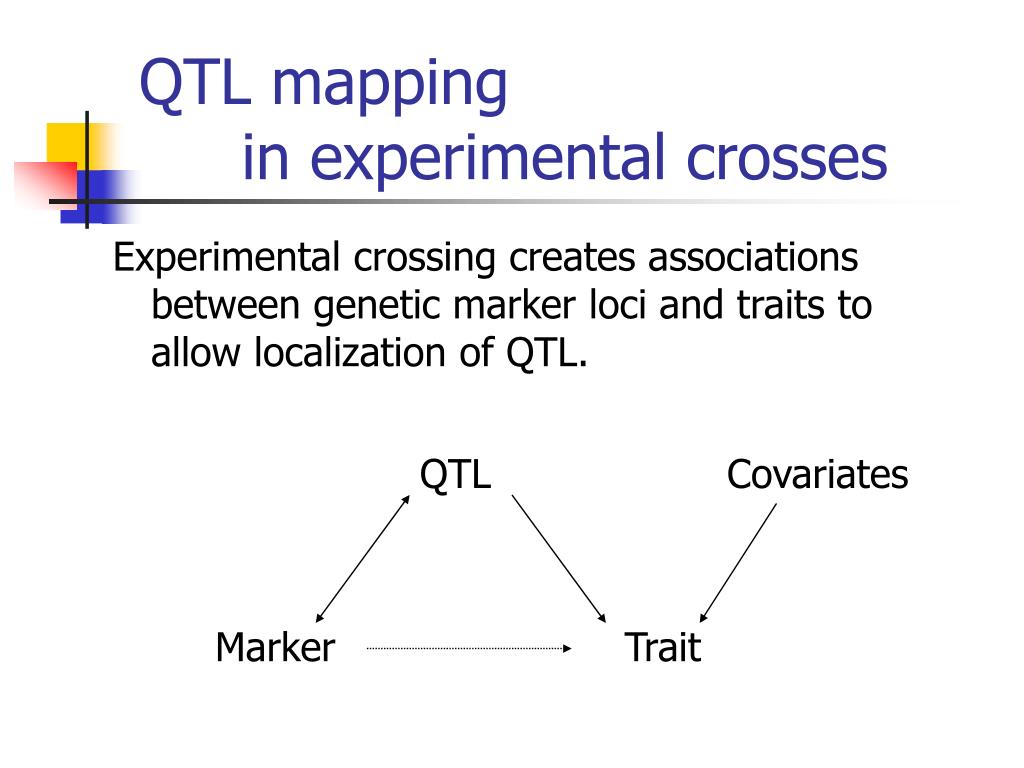
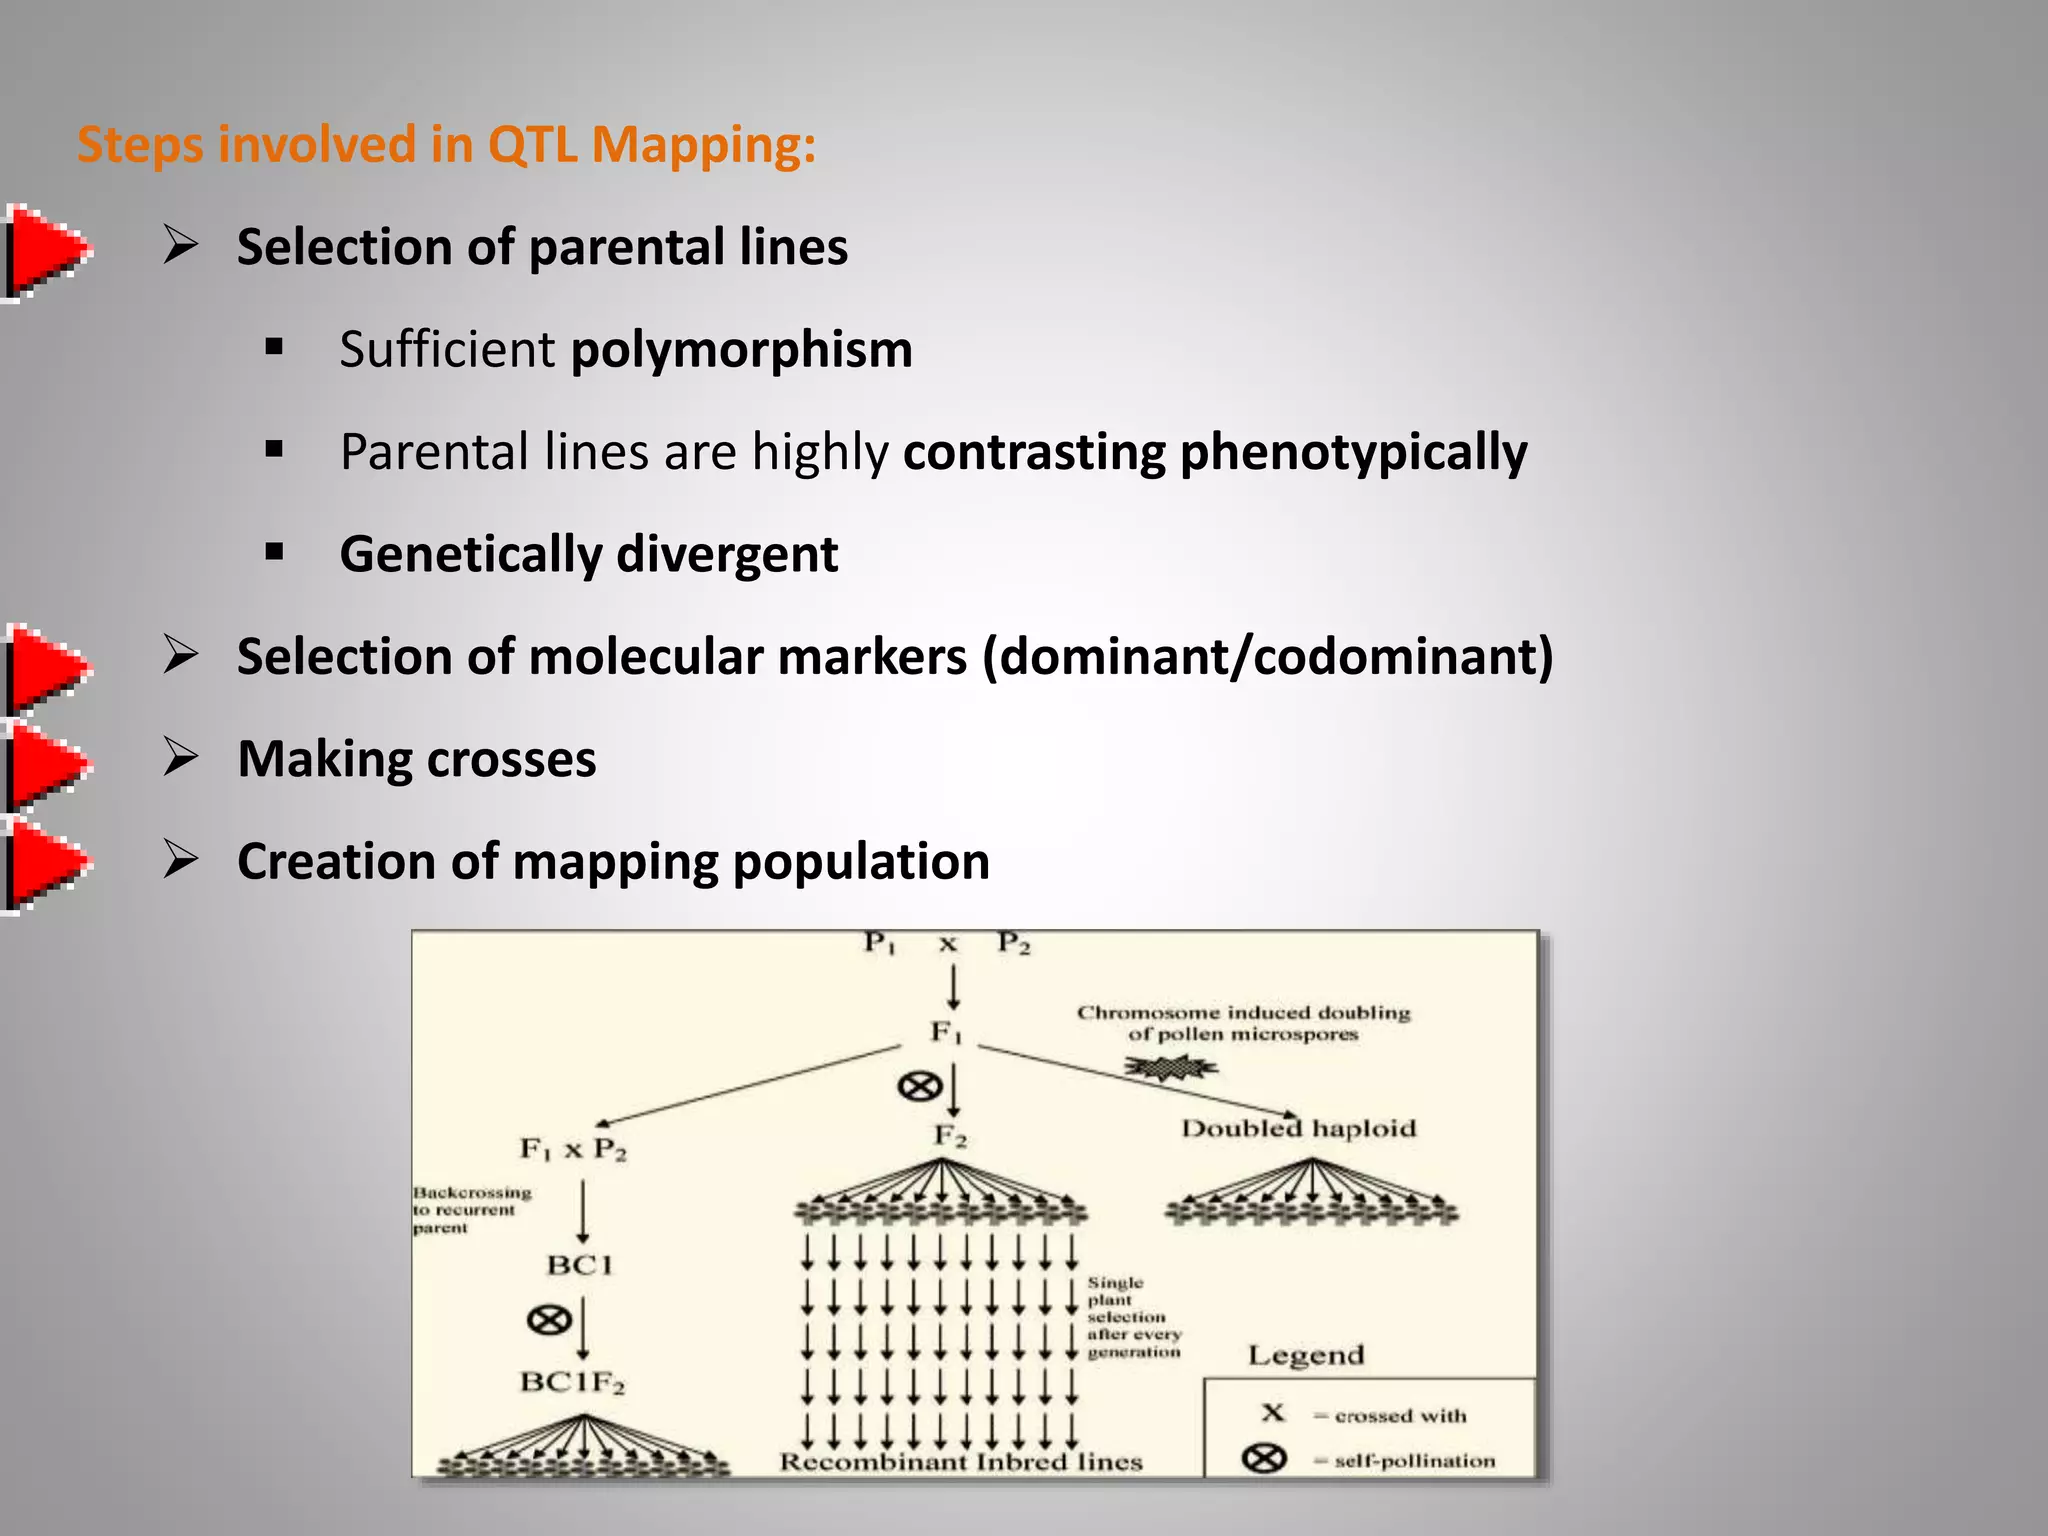
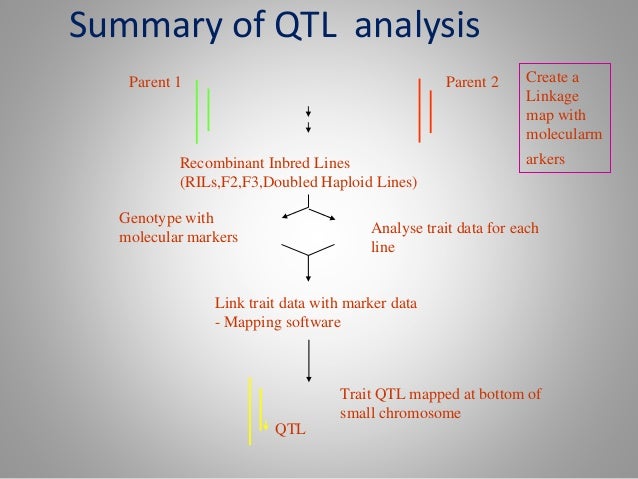
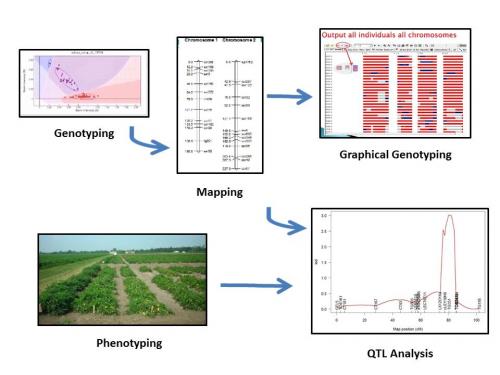
You set up a cross between two parental lines that differ for some trait—say, drought tolerance or yield—and you genotype the resulting progeny using molecular markers spread across the genome. Then you phenotype the same individuals and run a statistical association between marker genotypes and trait values. Any marker that shows a significant link gets flagged as being near a locus that influences the trait. That's the rough outline, but the actual execution is where things get annoying. At its core, QTL mapping is about locating regions of the genome that contribute to quantitative traits—traits that don't follow simple Mendelian inheritance patterns but instead show continuous variation. Unlike a gene that's either present or absent, a quantitative trait like plant height or milk production is shaped by multiple loci, each contributing a small effect, plus environmental noise. The goal of QTL mapping is to separate signal from that noise using statistical models. The most common design uses an F2 population or a backcross, though recombinant inbred lines and doubled haploids are more popular now because they let you phenotype the same genotype repeatedly. The basic workflow runs like this: cross your parents, generate segregating progeny, genotype them with markers (SNP arrays used to be the standard, but RAD-seq and GBS have largely taken over), phenotype them under controlled conditions, and then run interval mapping or composite interval mapping using software like Windows QTL Cartographer, R/qtl, or TASSEL.
I spent a summer trying to map a QTL for disease resistance in a maize cross and kept getting false positives everywhere. The problem turned out to be population structure—my experimental lines weren't randomly mating, they had subtle subpopulation structure that the basic model wasn't accounting for. I ended up adding principal components from the genotype matrix as covariates in the model, which cleaned up the noise significantly. It's one of those things that standard tutorials don't really emphasize enough.
How to Actually Do It Without Losing Your Mind
Here's the practical sequence. First, you need a well-designed population. The power of your QTL detection depends heavily on population size and the number of recombination events. A rule of thumb that actually holds up is that you need at least 100 to 200 individuals for a basic detection, but if you're looking for small-effect QTLs, you're realistically in the 500-plus range. More markers help too, but there's a point of diminishing returns—once your marker density gives you adequate coverage of the genome, adding more doesn't improve detection power much. Genotyping is the fast part nowadays. You send your DNA to a service or run it on an Illumina platform, and you're back with a matrix of genotypes in a few weeks. Phenotyping is where projects die. Get it right, and your QTL mapping will be solid. Mess it up, and no amount of statistical horsepower will save you. I learned this the hard way when we phenotyped a wheat trial during an unseasonably wet year and the disease pressure was so uneven across the field that our QTL peaks looked like random scatter. We had to replant and rerun the trial the following season, which cost us almost a full year. For the analysis itself, start with simple interval mapping to get a broad view of where effects might lie. Then move to composite interval mapping, which controls for background genetic variation by including cofactor markers. This reduces false positives from linked QTLs. The LOD score threshold is critical—you need to determine it through permutation testing, not just guess at 3.0. Running 1,000 permutations typically takes 10 to 30 minutes on a decent machine depending on population size, and it gives you an empirical threshold that's actually valid for your data.
Get the Full Details
One thing people routinely miss is that a detected QTL peak doesn't mean you've found the gene. It means you've found a region. In outcrossing species with large genomes, a single QTL interval can span tens of megabases containing hundreds of candidate genes. Fine mapping requires developing near-isogenic lines or doing sequential backcrossing with marker selection, which adds years to the project. If your goal is gene discovery rather than just marker-assisted selection, you should budget accordingly or consider alternatives like GWAS, which leverages historical recombination events to achieve much finer resolution.
Pitfalls That Will Waste Your Time
The biggest issue is epistasis. Most basic QTL mapping pipelines test one locus at a time and ignore interactions between loci. But quantitative traits are often shaped by gene-gene interactions, and missing those means you're underestimating the genetic architecture. Two-locus interaction scans are computationally expensive, though. With a population of 300 individuals and 10,000 markers, you're looking at roughly 50 million pairwise tests. Even with modern hardware, that can take hours or days, and the multiple testing burden is brutal. Another sneaky problem is genotype-by-environment interaction. A QTL that's significant in one environment might be invisible in another. I had a tomato QTL for fruit weight that showed up clearly in greenhouse conditions but disappeared entirely in field trials. The locus was real, but its effect was environment-dependent. The workaround is to phenotype across multiple environments and run a multi-environment QTL analysis, which partitions the genetic effect into stable and environment-specific components. It adds complexity but it's essential if you want results that translate beyond the controlled setting. Also worth noting: QTL mapping has a resolution limit that's fundamentally tied to the number of recombination events in your population. In a typical F2 population with a few hundred individuals, you're looking at maybe 20 to 40 historical recombination events per meiosis across the whole genome. That limits your mapping resolution to roughly 10 to 30 centimorgans per QTL interval. If you need finer resolution, you either need a much larger population, a special mapping population like a NAM or MAGIC population, or you move to association mapping, which exploits thousands of historical recombination events but comes with its own set of confounding factors like population stratification and allele frequency spectra.
When QTL Mapping Isn't the Right Call
There are situations where other approaches are simply better. If you're working with a species that has a high-quality reference genome and you have access to diverse germplasm, genome-wide association studies will give you finer resolution without the need to develop a specialized cross. If your trait is controlled by a single major gene, you don't need QTL mapping at all—just follow segregation and map it as a Mendelian locus. And if you're in the era of genomic selection, where the goal is prediction rather than dissection, you might be better off fitting a whole-genome regression model and moving on. The software landscape is decent. R/qtl and R/qtl2 are free and well-maintained. TASSEL is good if you're also running GWAS. MapQTL is commercial but polished. For basic interval mapping, any of these will work. The bottleneck has rarely been the software—it's been the biology, the phenotyping, and the statistical modeling decisions that separate a publishable result from a pile of noise.