The actual problem with quantum chemistry
Most people approach this subject backwards. They start by trying to understand the Schrödinger equation before they've ever seen why it matters for anything real. I spent years watching students (and junior colleagues) get stuck on the math because nobody bothered explaining what the math was actually solving. Here is the sequence that works, based on trial and error over more than a decade of running these calculations and debugging other people's results.What Is Quantum Mechanics In Chemistry
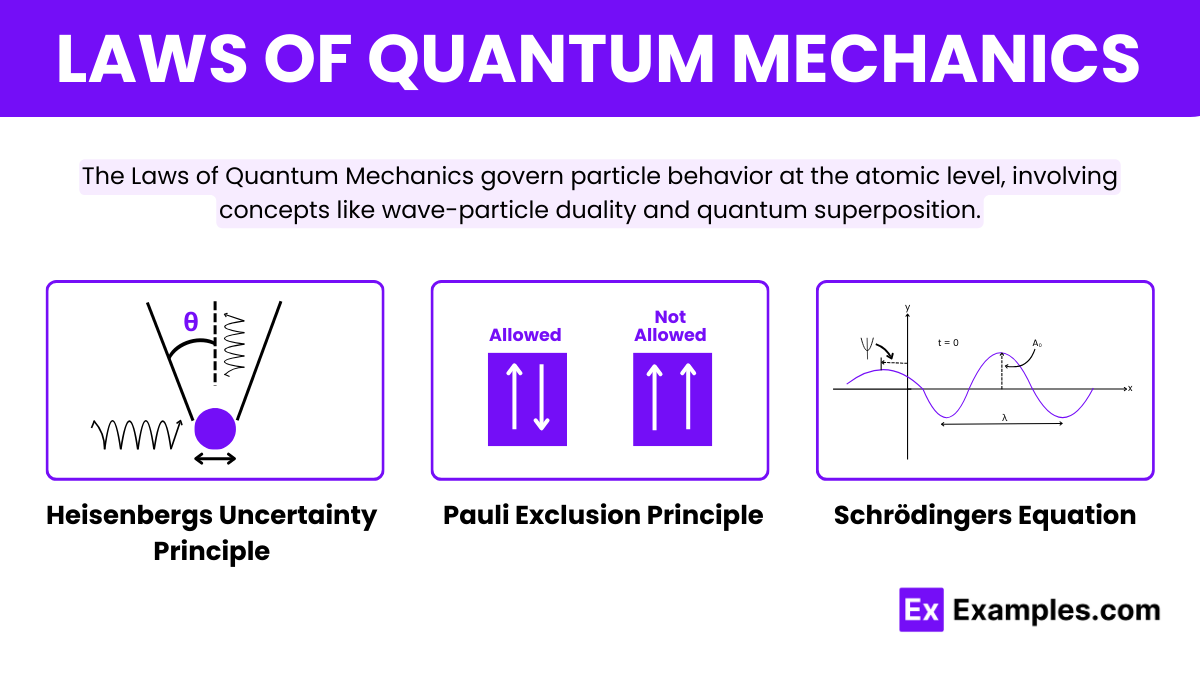
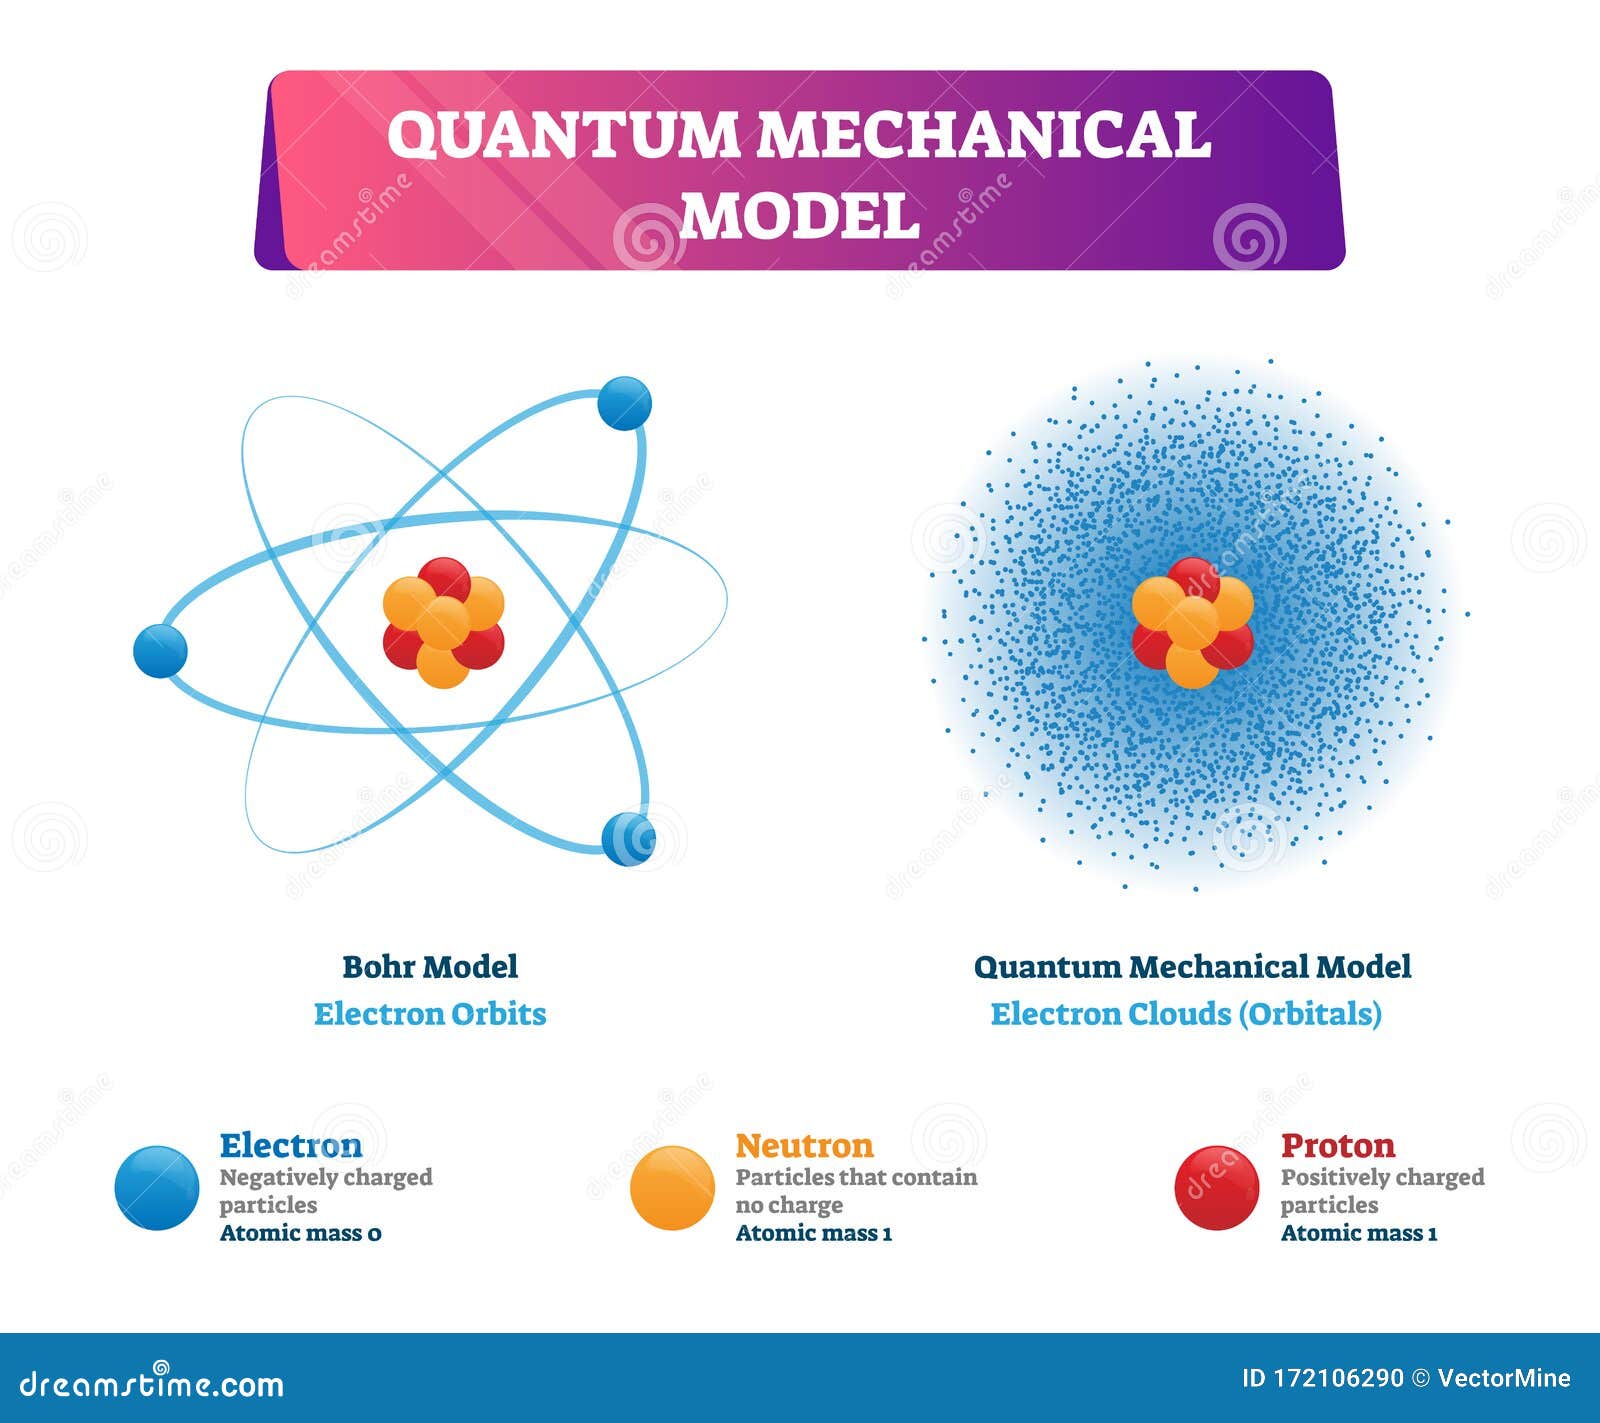
At its core, quantum mechanics in chemistry is just applying the rules of quantum physics to figure out how electrons behave inside molecules. The Schrödinger equation describes electron wavefunctions, and from those wavefunctions you derive things like molecular geometry, bond strengths, reaction barriers, and spectroscopic properties. That is the short version. The long version involves approximations, approximations of approximations, and the constant tension between getting an answer that is physically correct versus one that is computationally feasible. I used to think the hardest part was the theory. It isn't. The hardest part is knowing which approximation is safe for your specific system and which one will quietly produce garbage results that look plausible on the surface.
Start with the method, not the definition
Before you touch any software or try to derive equations, understand that there are really two camps in computational quantum chemistry: wavefunction-based methods and density functional theory. Wavefunction methods, like Hartree-Fock and post-Hartree-Fock approaches such as MP2, CCSD(T), and CI, explicitly model electron correlation through increasingly expensive corrections. DFT, which includes functionals like B3LYP, PBE0, and wB97X-D, takes a different route by focusing on electron density rather than the full many-electron wavefunction. The practical tradeoff is steep. MP2 calculations on a modest organic molecule might take an hour on a decent workstation. CCSD(T) on the same system could take days or weeks, depending on basis set size. The counter-intuitive thing nobody tells beginners is that DFT is not inherently more accurate than Hartree-Fock. For certain systems, especially those with significant static correlation or transition metals, DFT can perform worse than the simpler Hartree-Fock method. This is not a hypothetical edge case. I ran a set of organometallic complexes a few years ago where B3LYP predicted completely wrong geometries for high-spin states, while HF actually got the bond lengths closer to experiment. It was embarrassing. I had to redo three months of work.
Practical workflow for a standard calculation
Here is what the actual process looks like when you are doing routine work. You pick a Gaussian-type basis set, usually something like 6-31G* for initial geometry optimization or def2-SVP as a starting point. You run a geometry optimization to find the nearest local minimum. Then you do a frequency calculation to verify it is a true minimum and not a transition state. After that comes the single-point energy calculation with a larger basis set if you need accuracy. The whole thing, from input file to final energy, typically takes anywhere from 20 minutes to four hours on standard hardware, depending on molecule size and method. The most common pitfall is skipping the frequency check. I have seen people publish geometries that turned out to be saddle points because they never verified the Hessian had no imaginary frequencies. It sounds basic but it happens constantly, even in peer-reviewed work. A single imaginary frequency means your structure is sitting at a transition state, not a minimum, and any energy you compute from it is meaningless for thermodynamic comparisons.
Get the Full Details

The specific problem I ran into
About two years ago I was studying a series of conjugated organic systems and needed accurate vertical excitation energies using time-dependent DFT. I chose TD-B3LYP with the 6-31+G(d) basis set because it is the standard default everyone uses. The first set of results looked fine for the smaller molecules, but once I hit compounds with extended pi systems over twelve conjugated atoms, the errors jumped to 0.4 to 0.8 eV compared to experimental values. That is a huge deviation for any kind of quantitative work. The workaround was switching to TD-wB97X-D with a def2-TZVP basis set and applying an empirical dispersion correction. This cut the mean absolute error down to roughly 0.12 eV for the same test set. The calculation time increased by about 40 percent due to the larger basis set and the range-separated functional, but the accuracy gain was worth it. For long-range charge-transfer excited states specifically, standard hybrid functionals like B3LYP systematically underestimate excitation energies because they lack proper asymptotic behavior. Range-separated hybrids fix this by mixing in exact exchange at long interelectronic distances. This is not obvious unless you have spent time debugging exactly this kind of failure mode.
When quantum chemistry simply fails
It is important to be honest about the limitations. These methods break down in several well-defined scenarios. Strongly correlated systems, such as bond-breaking processes and certain transition metal oxides, are notoriously difficult because the single-determinant assumption underlying most DFT and Hartree-Fock calculations becomes invalid. Multi-reference methods like CASSCF exist for these cases but they require manual orbital selection and scale factorially with active space size, making them impractical for anything beyond ten or twelve active orbitals. You also run into problems with non-covalent interactions if your functional does not include dispersion corrections. Standard B3LYP without a dispersion term can underbind pi-stacking interactions by 30 to 50 percent. Another hard limit is system size. Beyond roughly three hundred to five hundred atoms, even DFT becomes computationally expensive for routine use. Linear-scaling methods and semi-empirical approaches like DFTB or PM7 exist as alternatives, but their accuracy drops significantly and they are not suitable for quantitative predictions unless you have carefully validated them against higher-level calculations for your specific chemical space.
Software options
The main packages people use are Gaussian, ORCA, GAMESS, Q-Chem, and Psi4. ORCA is free for academic use and is genuinely good value. It handles DFT, wavefunction methods, and TD-DFT competently with a reasonable learning curve. Gaussian remains the industry standard in many labs but requires a commercial license that can cost thousands annually. Q-Chem is excellent for excited state calculations but also carries a license fee. Psi4 is open source and written in C++ with a Python interface, which makes it easy to script complex workflows. I use ORCA for most of my routine work and fall back to Q-Chem when I need high-quality TD-DFT results. If you need a starting point for learning, ORCA's documentation is thorough and their tutorial collection covers everything from basic geometry optimization to advanced spectroscopy simulations. The community forums are active and responses tend to come within a day. Gaussian has equally good documentation but less transparent licensing for students trying to learn independently.
How to actually learn this without wasting six months
Start small. Pick a molecule like water or formaldehyde, run a geometry optimization with B3LYP/6-31G*, and examine the output file carefully. Read the printed orbitals, check the vibrational frequencies, compare your calculated bond lengths to literature values. This takes about fifteen minutes and teaches you more than a week of reading textbooks. Once you are comfortable with that, move to a slightly larger system and introduce a dispersion-corrected functional. Then try a frequency calculation on a transition state to see what an imaginary mode looks like visually. Each step builds intuition about what the numbers actually represent. The field moves fast too. New functionals and basis sets appear regularly, and what was considered best practice three years ago may already be outdated for certain applications. Keeping up with recent benchmarking studies in journals like the Journal of Chemical Theory and Computation and the Journal of Chemical Physics will save you from blindly applying methods that have known failures for specific classes of compounds.