The Short Answer
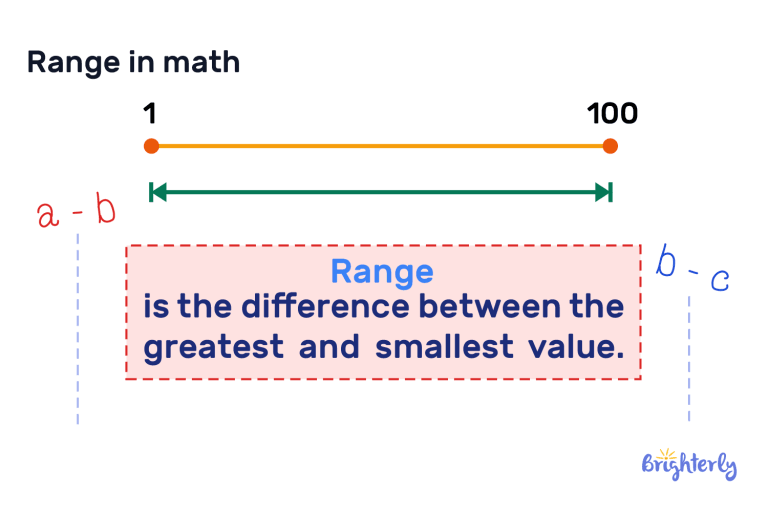
Range in math describes the spread of values in a dataset. You calculate it by subtracting the smallest number from the largest. It is one of the simplest statistical measures, but people constantly misuse it or treat it as sufficient on its own. That is the question I see most often on forums and in office emails. The definition fits on a sticky note. The practice is messier. I learned this the hard way during a quality control project at a manufacturing plant. We were tracking bolt diameters across three production shifts. The range looked fine—0.02 millimeters spread across thousands of bolts. Then I noticed the data had a bimodal distribution because two different machines were running on the night shift. The range didn't flag that. Standard deviation would have been higher, but still wouldn't show the split. I had to pull individual machine logs to see what was happening.
That's the thing about range. It tells you the distance between extremes. Nothing else. It ignores everything in between.
How To Calculate It
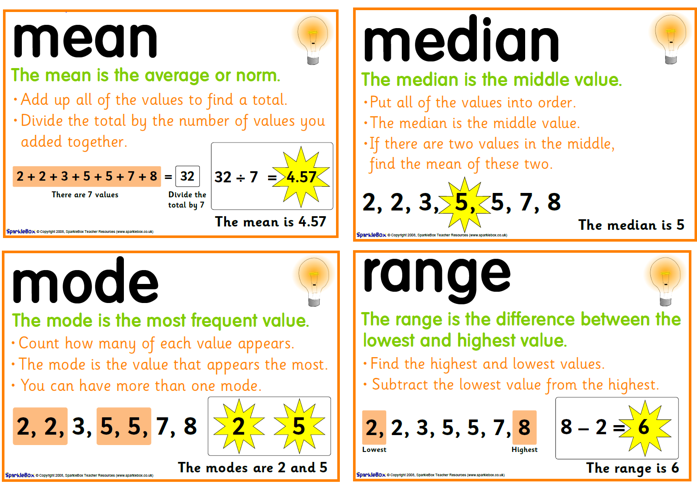
Find the minimum value. Find the maximum value. Subtract min from max. That is literally all there is to the calculation. A dataset of 4, 7, 2, 9, 1 gives you a range of 9 minus 2, which equals 7. Done. The method works for any numeric dataset. It works for negative numbers. It works for decimals. It does not work for categorical data. You cannot calculate the range of colors or brands or names. The numbers have to mean something quantitatively.
Get the Full Details
When Range Actually Helps
Range is useful for quick sanity checks. I use it when reviewing data exports from databases. If a column labeled age shows a range of 0 to 200, I know someone entered test data without validation. A range of 18 to 120 would pass my initial scan. That takes about 30 seconds to compute in any spreadsheet. It is also useful for describing tolerance bands in engineering. When a specification says a part must be 10 millimeters plus or minus 0.5, the allowable range is 0.5 millimeters. Manufacturers use this language constantly.
Where Range Fails You
Range is extremely sensitive to outliers. A single data entry error can inflate the range dramatically. I worked with a survey dataset once where one respondent entered their age as 150 instead of 50. The range jumped from 18 to 89 years old to 18 to 150. That single typo made the entire dataset look more variable than it actually was. The workaround I use is to calculate the interquartile range alongside the regular range. The IQR looks at the middle 50 percent of data and ignores extremes. In Excel or Google Sheets, you can compute it with QUARTILE functions. In Python, numpy has percentile functions. The IQR takes a few extra seconds to calculate and gives you a much more stable picture of spread. Range also fails when your dataset is small. With only five data points, a single new value changes the range completely. A dataset of 10, 12, 11, 13, 12 has a range of 3. Add 100 and the range becomes 90. That is not a gradual increase in variability. That is one outlier destroying the metric.
Interpreting Range Correctly
A small range does not mean data is tightly clustered. It only means the extremes are close. The middle could be wildly dispersed. I saw a dataset once where values bounced between 1 and 99 in the middle but the minimum was 0 and the maximum was 100. The range was 100, which looked large, but 90 percent of the data fell between 45 and 55. The range completely masked that concentration. A large range does not mean data is uniformly spread. It could be clustered at both ends with nothing in the middle. My bolt diameter example from earlier fits this pattern. Two machines produced slightly different sizes, creating clusters at each end of the range with a gap in between. The practical advice is to never rely on range alone. Pair it with standard deviation, variance, or IQR. Even just looking at a histogram or box plot takes a minute and reveals structure that range hides.
Common Mistakes
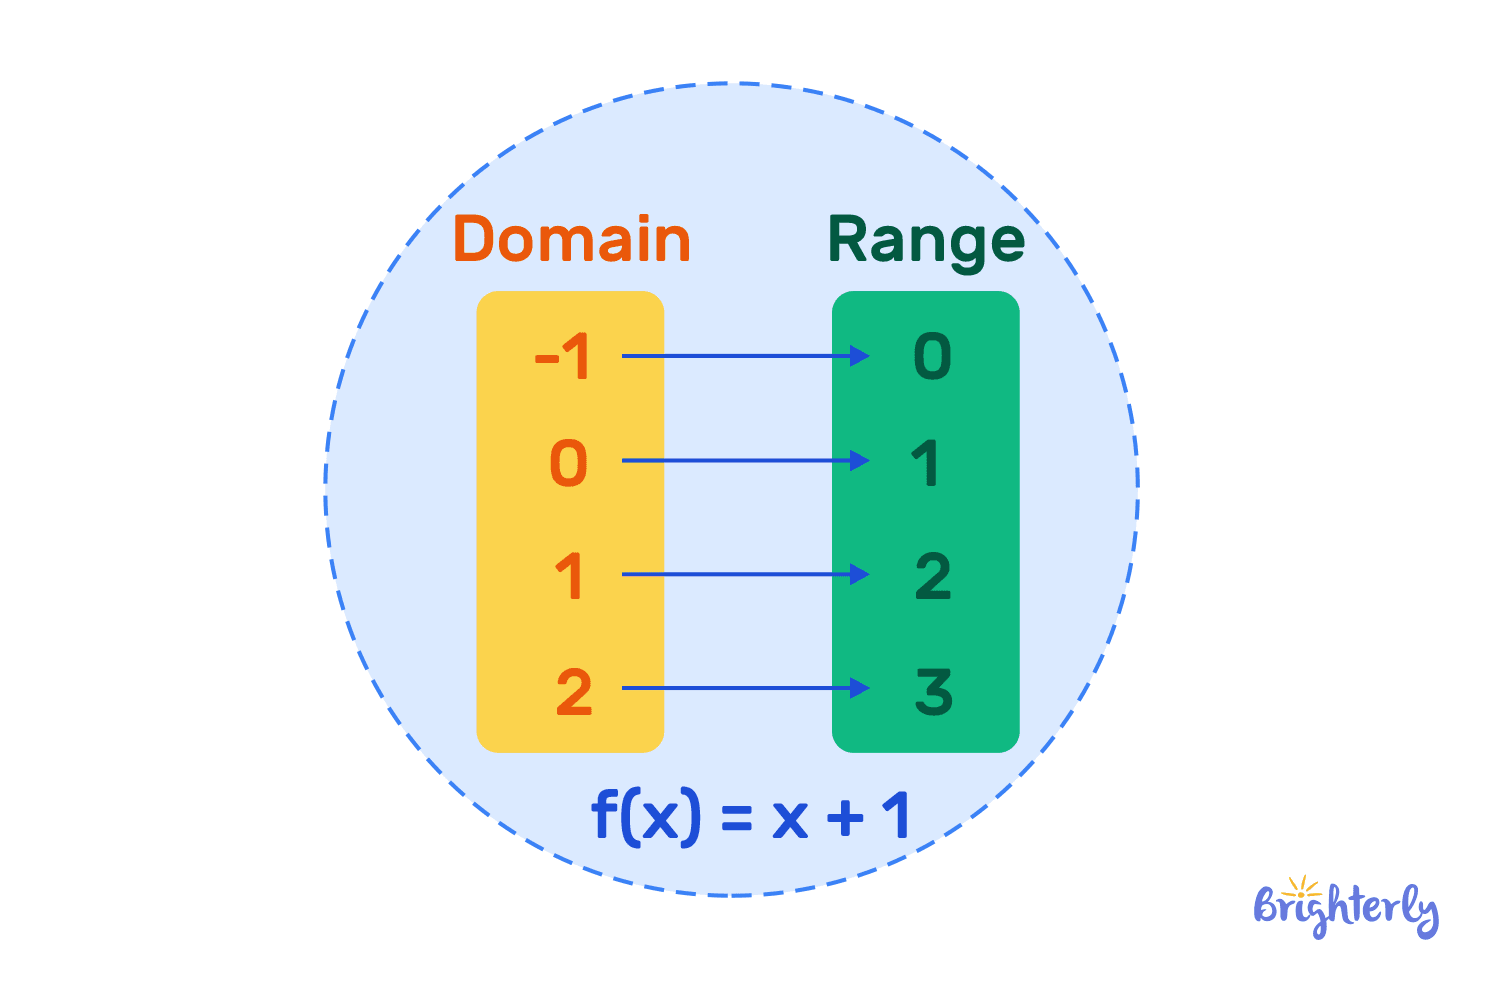
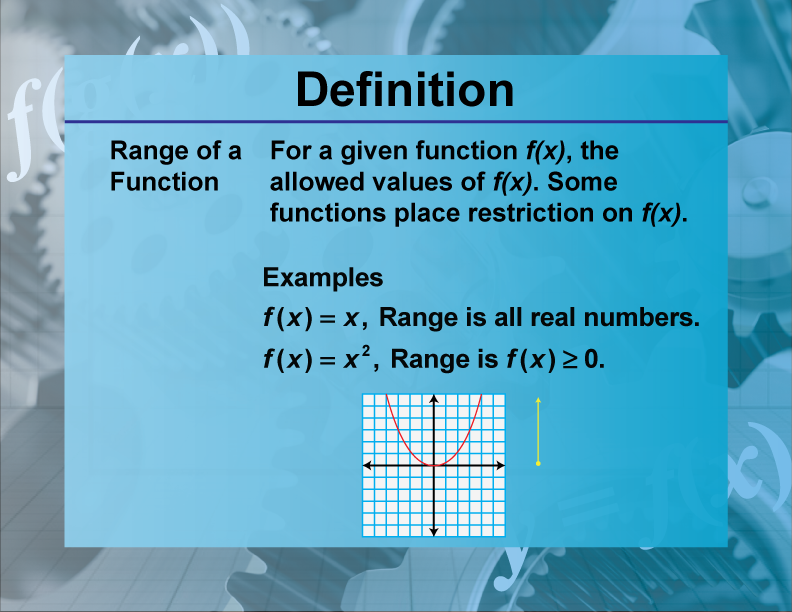
People confuse range with domain. Domain is the set of input values a function can accept. Range is the set of output values it produces. In introductory algebra classes, students mix these up constantly. When I tutor, I have them label the axes first. Input goes on x. Output goes on y. Range relates to y. Domain relates to x. That visual anchor usually sticks. Another mistake is treating range as a measure of central tendency. It is not. It is a measure of dispersion. Mean, median, and mode describe center. Range, variance, and standard deviation describe spread. They answer different questions.
Edge Cases That Trip People Up
Range is undefined for empty datasets. You cannot subtract min from max if there are no values. Some software returns null. Others return errors. Be aware of this when writing scripts that process variable-length data. Range is also problematic with infinite values. If your dataset contains positive or negative infinity, the range becomes infinite. I encountered this in sensor data where a reading failed and returned a special flag value that looked like a number to basic scripts. The fix was adding a validation step to filter out known error codes before calculating statistics. Comparing ranges across datasets with different scales is meaningless. A range of 10 degrees Celsius and a range of 10 degrees Fahrenheit describe completely different spreads. Convert to the same scale first. This sounds obvious until you see it in published research papers.
Practical Workflow
Here is how I approach range calculations in practice. First, I load the data and check for missing values or obvious errors. Second, I compute the range. Third, I compute the IQR and standard deviation. Fourth, I plot a histogram or box plot. This sequence takes about two minutes in most tools and catches issues that range alone would miss. If you are doing this manually, range is fast enough to compute on paper. For anything beyond a handful of values, use a calculator or spreadsheet. The time savings are marginal for small datasets but essential when you are processing thousands of rows. Range is a starting point, not a destination. It gives you one number that summarizes spread in the crudest possible way. Use it for quick checks and initial scans. Do not build conclusions on it alone. The math community has better tools for describing variability, and they are almost as easy to compute once you know where to find them.