Starting With the Math Before the Definition
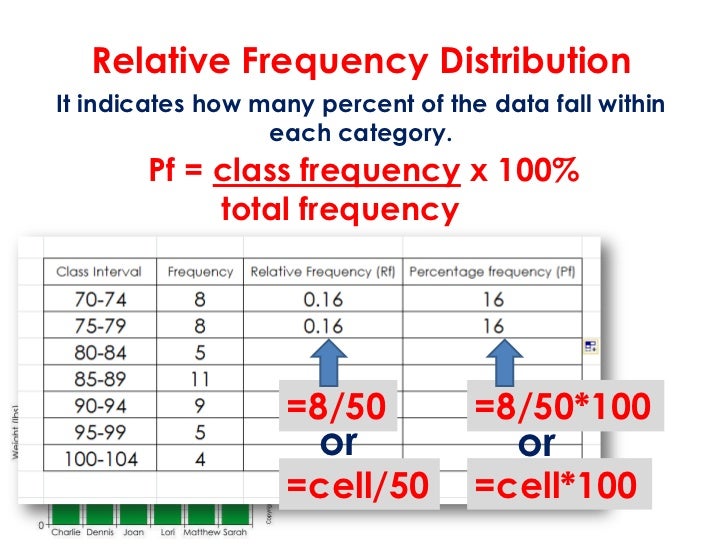
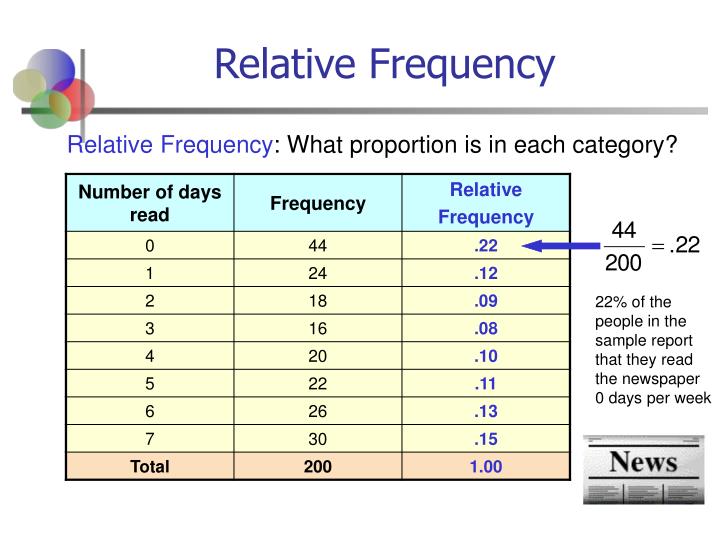
The formula itself is trivial: divide the count of a specific outcome by the total number of observations. If you surveyed 200 people and 45 said they prefer tea over coffee, the relative frequency of tea preference is 45 divided by 200, which gives you 0.225 or 22.5%. That is it. The entire concept boils down to that single division operation repeated across whatever categories your data contains. Most textbooks bury the definition under pages of preamble, but the actual mechanism takes about three seconds to explain and longer to apply correctly in messy real-world scenarios. I remember working on a healthcare compliance audit a few years back where we needed relative frequency distributions across patient age brackets. The dataset had over 14,000 records, and roughly 3% of the entries had missing age values. If you just blindly divide category counts by the grand total, your relative frequencies will be slightly distorted because those missing records are still inflating the denominator. The workaround I ended up using was calculating the relative frequency against the count of non-missing observations instead, then flagging the missing-data rate as a separate footnote in the report. This shifted the relative frequencies by about 3% across every category, which actually mattered when the compliance auditors were checking for statistically significant demographic patterns.
What Is Relative Frequency In Statistics
Relative frequency is the proportion or percentage of times a particular value or category appears within a dataset relative to the total number of observations. It transforms raw counts into a standardized measure that allows comparison across datasets of different sizes. A raw count of 50 defects means very little on its own. A relative frequency of 0.04 tells you that defects occur in 4% of inspected units, which becomes meaningful when you are benchmarking against industry standards or tracking changes over time. One thing beginners consistently miss is that relative frequency and probability are not interchangeable, even though they share the same numerical range between zero and one. Relative frequency is an empirical observation drawn from actual data. Probability is a theoretical construct that describes what should happen under idealized conditions. When you roll a fair six-sided die 600 times and get 102 ones, the relative frequency of rolling a one is 0.17, which is close to the theoretical probability of 0.167, but they are distinct concepts. Conflating them becomes problematic when sample sizes are small. With only 30 observations, relative frequencies can swing wildly and still be perfectly valid descriptions of your data. Treating those swings as if they represent underlying probabilities leads to overconfident conclusions. Another nuance that does not get enough attention is how relative frequency behaves with continuous data. You cannot simply count occurrences of exact values in a continuous distribution because nearly every value will appear zero or one times. You have to bin the data into intervals first, then calculate relative frequencies within each bin. The choice of bin width dramatically affects the resulting distribution shape. I spent an afternoon last year trying to reproduce a published quality control chart and realized the original authors had used half the bin width I was using. Our relative frequency distributions looked completely different, even though they were describing the same underlying measurements. There is no universally correct bin size, which is why methods like the Freedman-Diaconis rule or Scott's rule exist, but they are approximations, not solutions.
Building a Relative Frequency Distribution Step by Step
Take your raw dataset and identify the variable you want to analyze. If it is categorical, list each unique category. If it is continuous, create bins using a rule-based approach rather than arbitrary cutoffs. Count the number of observations falling into each category or bin. Sum all the counts to verify the total matches your dataset size, accounting for any missing values. Divide each individual count by the total. Multiply by 100 if you want percentages. Verify that all relative frequencies sum to exactly 1.0 or 100%, allowing for minor rounding differences. Here is a practical example using a manufacturing defect log. A production run produced 500 units. The quality team recorded 12 surface scratches, 8 dents, 5 wrong-color units, and 3 missing components. The remaining 472 units passed inspection with no recorded defects. The relative frequency for surface scratches is 12 divided by 500, equaling 0.024. Dents come to 0.016. Wrong color is 0.01. Missing components is 0.006. No defects is 0.944. The sum of all these relative frequencies is exactly 1.0. This distribution immediately shows that surface scratches are the dominant defect type at 2.4% of total output, which would be difficult to see from raw counts alone if you were comparing this line to another line producing 2,000 units per run.
Get the Full Details

Where This Breaks Down and What to Do Instead
Relative frequency analysis assumes your sample is representative of the population you are making claims about. If your sampling method is biased, the relative frequencies will be precise but wrong. I encountered this repeatedly in customer satisfaction surveys where online respondents skew significantly younger than the actual customer base. The relative frequencies of satisfaction scores were mathematically correct but completely misleading for product decisions. The fix is weighting your data to match known population demographics before calculating relative frequencies, or acknowledging the sampling bias explicitly in your methodology section. Another failure mode appears with sparse categorical data. When you have a category with only one or two observations out of thousands, the relative frequency might look stable numerically but carries enormous uncertainty. A relative frequency of 0.0002 based on a single occurrence in a 5,000-record dataset gives you zero confidence that the true population parameter is anywhere near that value. In those cases, Bayesian approaches with appropriate priors or exact binomial confidence intervals are more honest than reporting the point estimate alone. Relative frequency also struggles when comparing distributions across groups with very different total sizes. A category representing 10% of a small group of 50 observations carries far less statistical weight than 10% of a group with 5,000 observations. Reporting raw relative frequencies without sample sizes invites misinterpretation. Always include the underlying counts alongside your relative frequencies in any table or visualization.
The computational side is straightforward in any modern tool. In Python, you can use pandas value_counts with normalize=True to get relative frequencies directly. In R, prop.table applied to a table object produces the same result in a single line. Excel requires a simple COUNTIF divided by COUNT or COUNTA, depending on whether you have missing values. None of these approaches handle the edge cases I described above automatically, so you still need to think about what the numbers actually mean rather than treating the calculation as the analysis itself. Relative frequency remains useful precisely because it is simple. The simplicity is also its limitation. It describes your data, nothing more. It does not test hypotheses, it does not infer populations, and it does not account for sampling variability. When you need to go beyond description, you move into confidence intervals, hypothesis testing, or regression modeling. But for getting a clear picture of how your data is distributed across categories, relative frequency is usually the right first step and often the right last step as well.