The Scientific Method Is Overworked and Understood Wrong
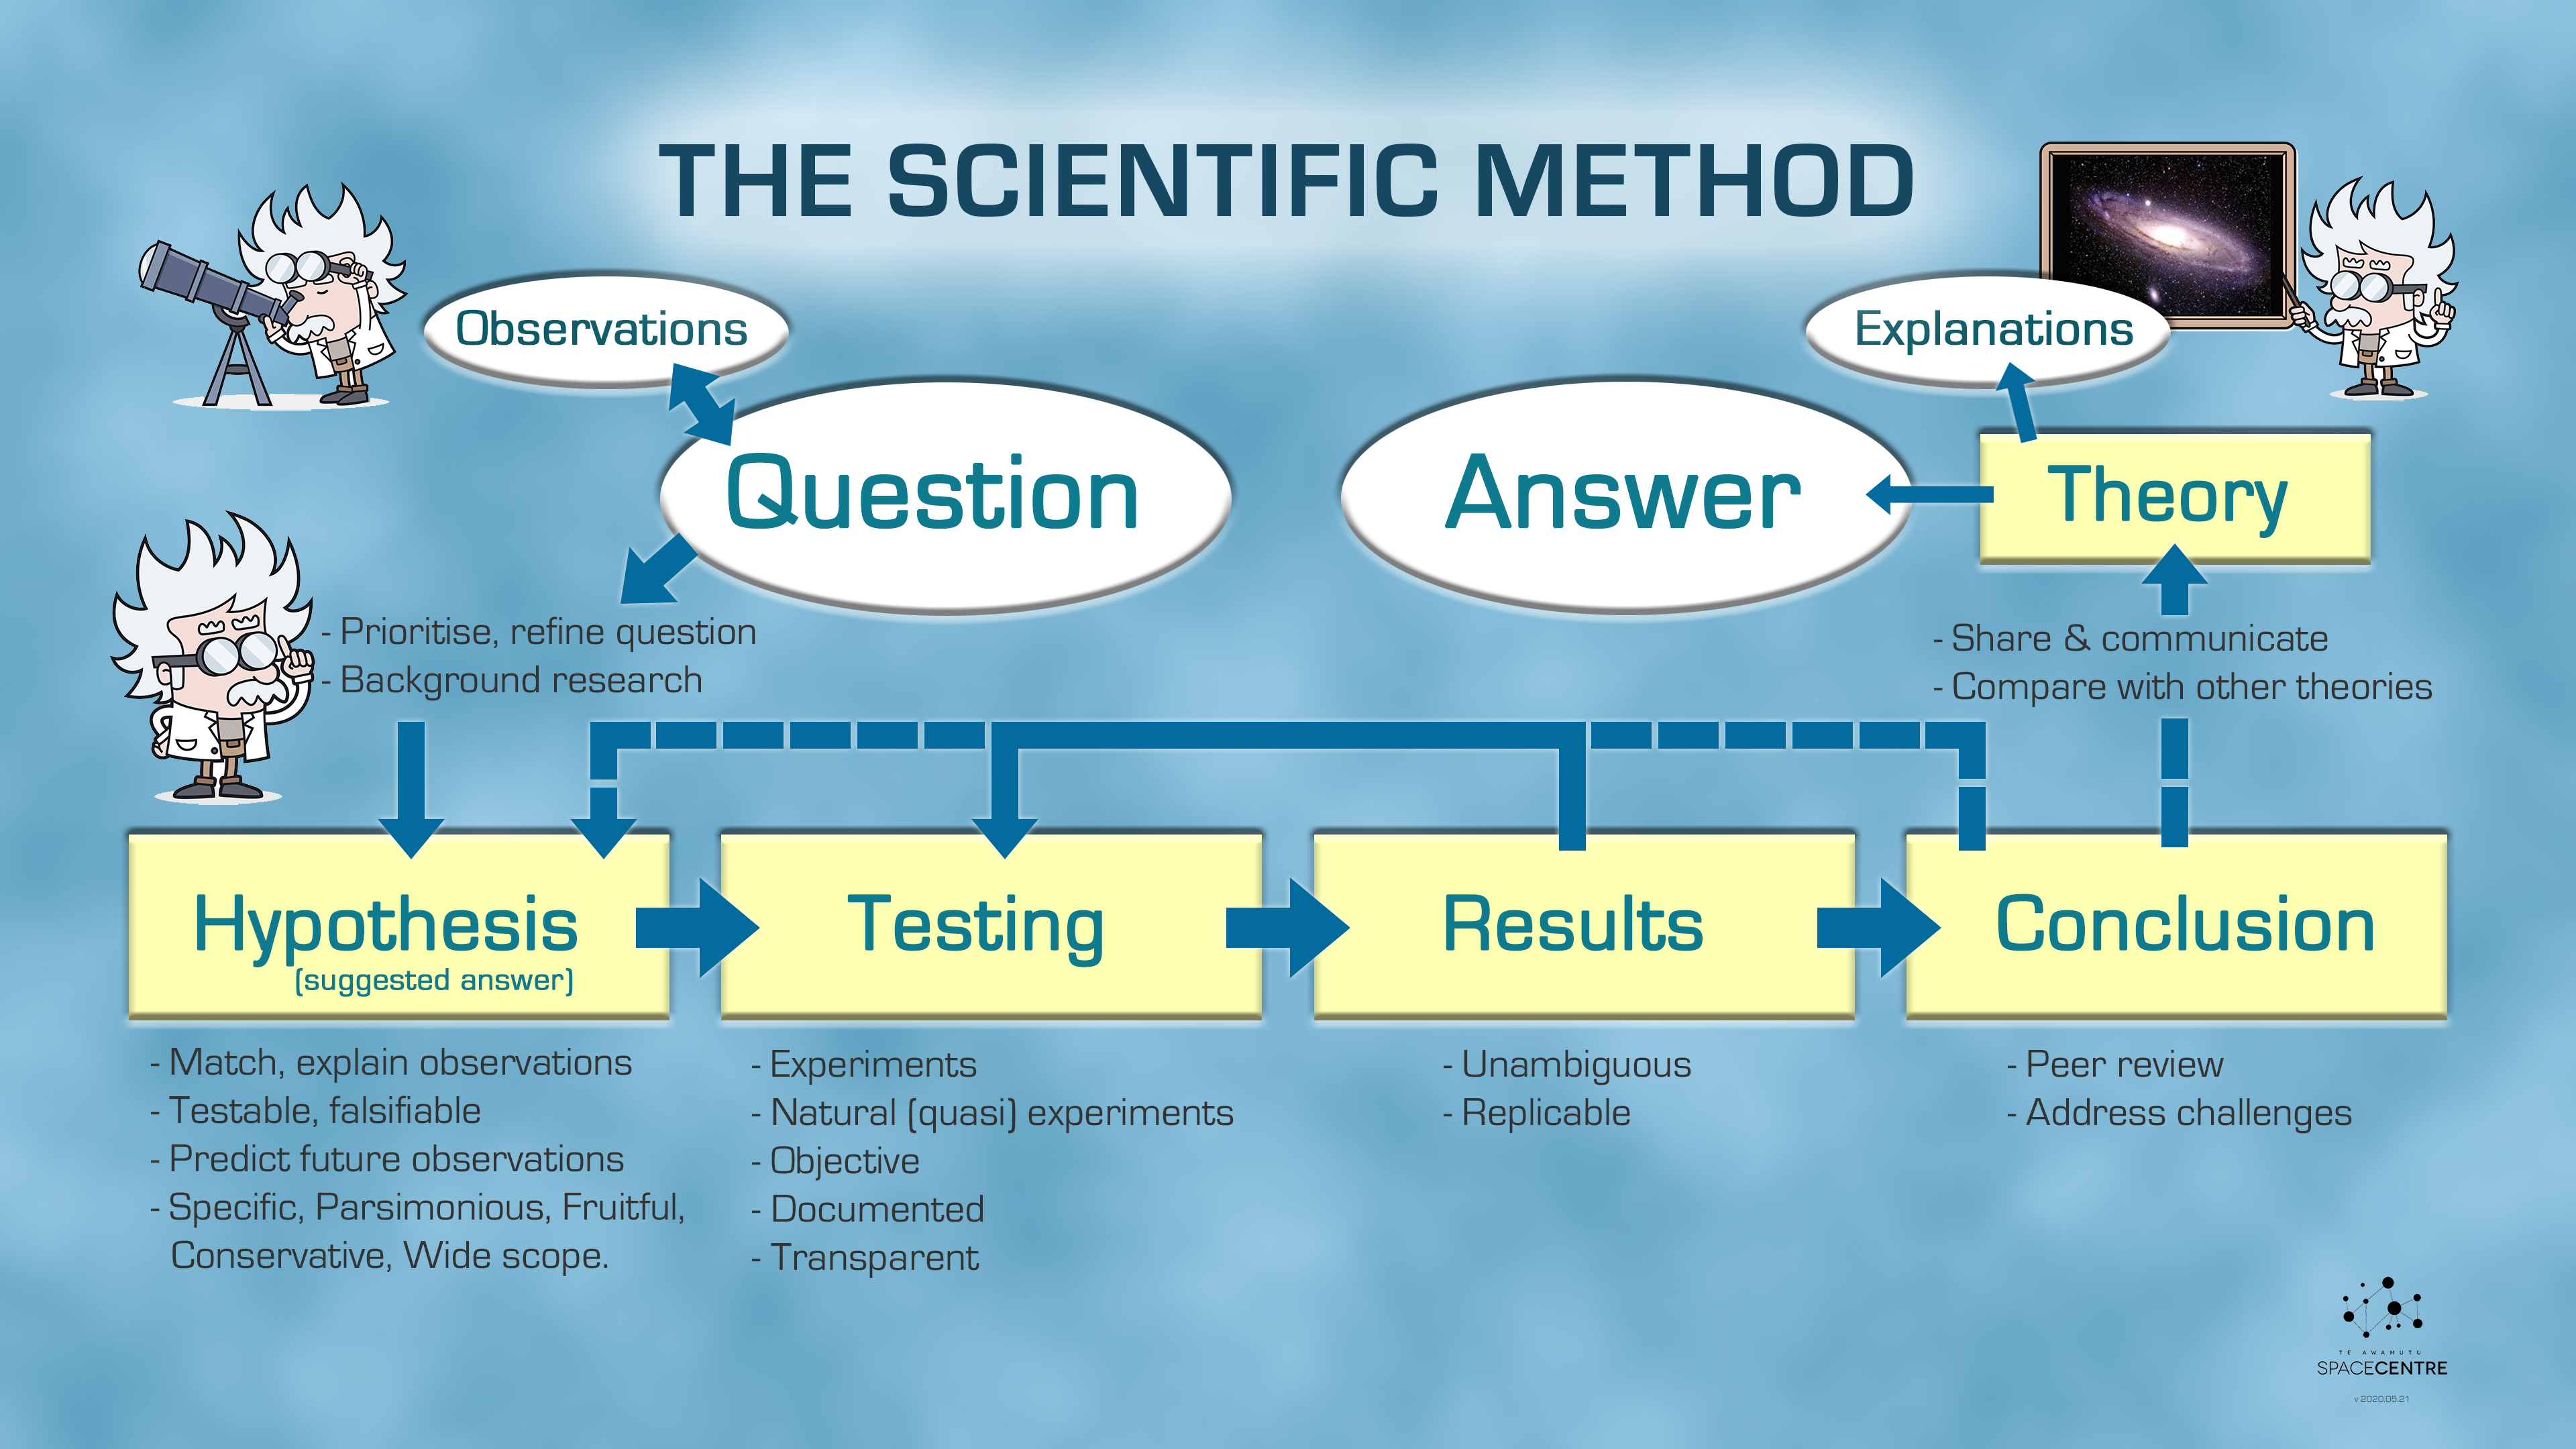
Most people learn it as a five-step checklist from elementary school. Observe, question, hypothesis, experiment, conclude. That version exists to get kids through a science fair, not to describe how actual research happens. The scientific method is really a framework for reducing uncertainty through systematic testing, and it rarely follows a neat linear path. I have spent years watching both published papers and internal projects fall apart because teams treated it like a recipe instead of a reasoning process. At its core, the scientific method is a structured approach to building reliable knowledge. You make observations, formulate a testable explanation, make predictions from that explanation, run controlled tests, and then revise your explanation based on the results. The key word is revise. Confirmation is not the goal. Falsification is. Karl Popper nailed this decades ago, yet most lab meetings and project retrospectives I sit through sound like people trying to prove their favorite idea right rather than actually stress-testing it. Let me explain how this works in practice rather than theory. A hypothesis must be falsifiable. That means there has to be some possible outcome that would prove it wrong. "All swans are white" is a proper hypothesis because finding a black swan kills it. "This code runs fast enough" is garbage because you never defined fast enough. Vague hypotheses waste weeks of data collection that cannot actually resolve anything.
Here is the part most beginners skip. Controls matter more than your experimental group. When I was troubleshooting a deployment pipeline issue that caused intermittent latency spikes, I spent three days measuring the "affected" servers before I bothered setting up a proper control. We had identical hardware, same network segment, but one group received the updated package and the other did not. Once I had that baseline, the real variable became obvious within hours. Without controls, you are just collecting noise and calling it evidence.
How It Actually Plays Out
Research is messy. The textbook version presents science as a straight line, but in reality you loop through steps constantly. You observe something, form a quick hypothesis, test it informally, observe the result, and then either refine or scrap the hypothesis and start again. The formal experiments come later, after you have already eliminated the obvious wrong answers through rapid iteration. Statistical literacy separates people who use the scientific method from people who just do science-y things. A p-value below 0.05 does not mean your hypothesis is true. It means the observed data would be unusual if the null hypothesis were correct. That is a subtlety that gets glossed over constantly. I worked on a project where the team celebrated a statistically significant result that turned out to be a classic multiple comparisons problem. We ran twenty-seven tests and found one that "passed" significance by chance alone. Replication killed it immediately. Replication is non-negotiable. Single experiments are anecdotes with better formatting. I cannot stress this enough. In my experience, any finding that has not been reproduced at least once independently should be treated as preliminary, regardless of how clean the data looks or how impressive the statistical tests are. Published replication failure rates in certain fields are brutal, and even in well-funded environments, the pressure to produce novel results often crowds out the boring work of confirming earlier findings.
Get the Full Details
Another counter-intuitive point. Sometimes your hypothesis should fail, and that is a good outcome. Negative results are information. I once spent six months disproving a theory about user behavior patterns that everyone in the organization believed was true. The initial funding and political support for that hypothesis were enormous. When the data consistently contradicted it, I had to present those findings to stakeholders who had built decisions on the opposite assumption. It was uncomfortable, but the scientific method works precisely because it does not care about your feelings or your budget. It cares about whether your model predicts reality.
Where It Breaks Down
The scientific method is not a universal problem solver. It requires phenomena that can be observed, measured, and tested under controlled conditions. Questions about ethics, aesthetics, meaning, and values do not yield to empirical testing. You cannot design an experiment that proves something is beautiful or just. The method is powerful within its domain, and that domain is narrower than many people claim. Observer bias is a persistent threat that no single control eliminates. When you know what you expect to find, you notice confirming evidence more readily than disconfirming evidence. This is not a character flaw. It is a cognitive limitation. Double-blind protocols reduce this in clinical research, but most domains lack the resources or feasibility for that level of blinding. The workaround is peer review and transparent methodology. You lay out exactly what you did so others can check your work, not because peer review is perfect, but because it is the best institutional tool we have for catching sloppy reasoning. Another limitation worth stating plainly. The scientific method assumes the universe is comprehensible and consistent enough that patterns will repeat. That assumption works remarkably well for physics and chemistry. It works less reliably for complex adaptive systems like human societies or ecosystem dynamics, where initial conditions are impossible to fully control and where the act of observation can change the system itself. In those domains, you still use the method, but you temper your conclusions accordingly. The models are approximations, not truths.
Practical Steps That Actually Work
Start with a precise question. "Why do users churn?" is not a question you can test. "Does adding a progress indicator to the checkout flow reduce abandonment rate by more than two percentage points within thirty days?" is a question you can test. The tighter the question, the easier the design. A loose question produces loose data and loose conclusions that convince nobody. Write your hypothesis before you collect data. If you collect data first and then look for patterns, you are doing data mining, not hypothesis testing. Data dredging produces spurious correlations every time. I have seen it happen repeatedly. Someone looks at a dataset, finds an interesting pattern, and then frames a hypothesis around it. The pattern was noise. They published it anyway because the narrative was appealing. Define your success criteria in advance. Not "we will see if it improves things." Define the metric, the threshold, and the time window. "Conversion rate increases by at least 1.5 percentage points with 95% confidence over a fourteen-day test period." Write it down. Do not move the goalposts when the data comes in. Goalpost moving is the most common way good processes go bad, and it happens constantly in industry settings where business pressure outweighs methodological rigor.
Document everything. Raw data, code, configuration, timestamps, environmental conditions. If you cannot reproduce your own experiment from your notes, you do not actually understand what you did. I keep detailed lab notebooks and version-controlled scripts for every project. The cost is maybe an extra twenty minutes per session. The payoff is that when something goes wrong six months later and you need to debug it, you are not starting from scratch. I lost a project once because I had not documented the exact build flags used during initial testing, and we could not replicate the conditions that produced the original results. Three weeks of lost time over a detail I should have recorded immediately.
Common Pitfalls to Avoid
Confusing correlation with causation. This is the oldest mistake in the book and people still make it daily. Two variables move together. That does not mean one causes the other. A third variable might drive both. Or it might be pure coincidence. Controlled experiments isolate causation by holding other variables constant. Observational studies can only suggest relationships, and even then, only with appropriate statistical controls. Sample size too small. Small samples produce unstable estimates. A test with ten participants might show a dramatic effect that vanishes with a hundred. I have seen startup teams make product decisions based on five user interviews and then treat those findings as definitive. They are not definitive. They are directional. Treat small samples as generating hypotheses, not confirming them. Survivorship bias. Studying only the cases that made it through a selection process while ignoring those that did not. During a project analyzing successful product launches, we initially missed a critical factor because we only looked at products that reached market. The ones that failed during development had different characteristics entirely. Including the failures changed our model substantially. Always ask what data is missing, not just what data you have.
The scientific method is a tool, not a religion. It produces better answers than intuition or authority or committee consensus, but it requires discipline to use correctly. The discipline is in the details: falsifiable hypotheses, proper controls, pre-registered criteria, replication, and honest reporting of negative results. Skip any of those and you are not practicing the scientific method. You are just going through the motions. I recommend reading "The Science of Science Fiction" by Adam Rutherford or "Bad Science" by Ben Goldacre if you want to understand how the method gets corrupted in practice. Both are accessible and both are necessary reading for anyone who makes decisions based on data. The gap between knowing the scientific method and applying it correctly is wider than most people expect. Closing that gap takes conscious effort and a willingness to change your mind when the evidence demands it.