What Social Inequality Actually Looks Like When You Study It
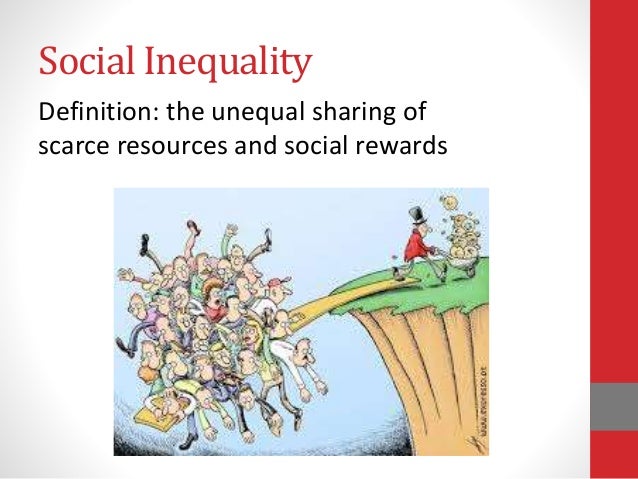
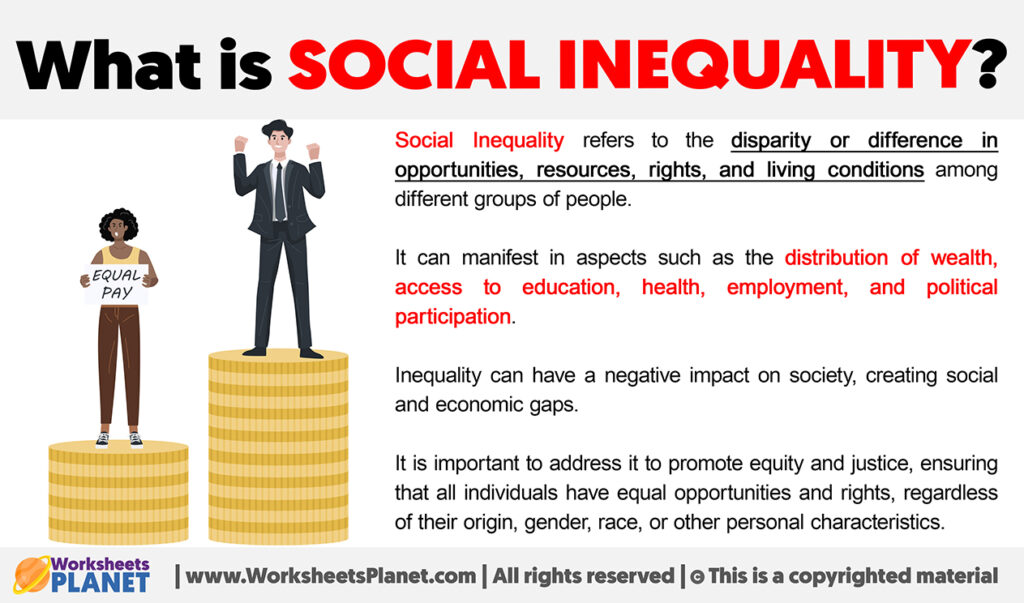
Social inequality is the systematic distribution of advantages and disadvantages across groups in a society. That's the textbook version. The practical version involves dealing with overlapping categories of wealth, education, race, gender, geography, and institutional access that rarely line up neatly. When you try to measure it, you quickly find that each variable shifts depending on how you define it. I spent years working with census tract data and survey samples trying to map inequality patterns in mid-sized American cities. The first thing you learn is that your choice of measurement completely changes your conclusions. If you use income quintiles, you get one picture. Switch to wealth percentiles and the spatial distribution looks different. Add in mobility data and it looks entirely different again.
What Is Social Inequality In Sociology
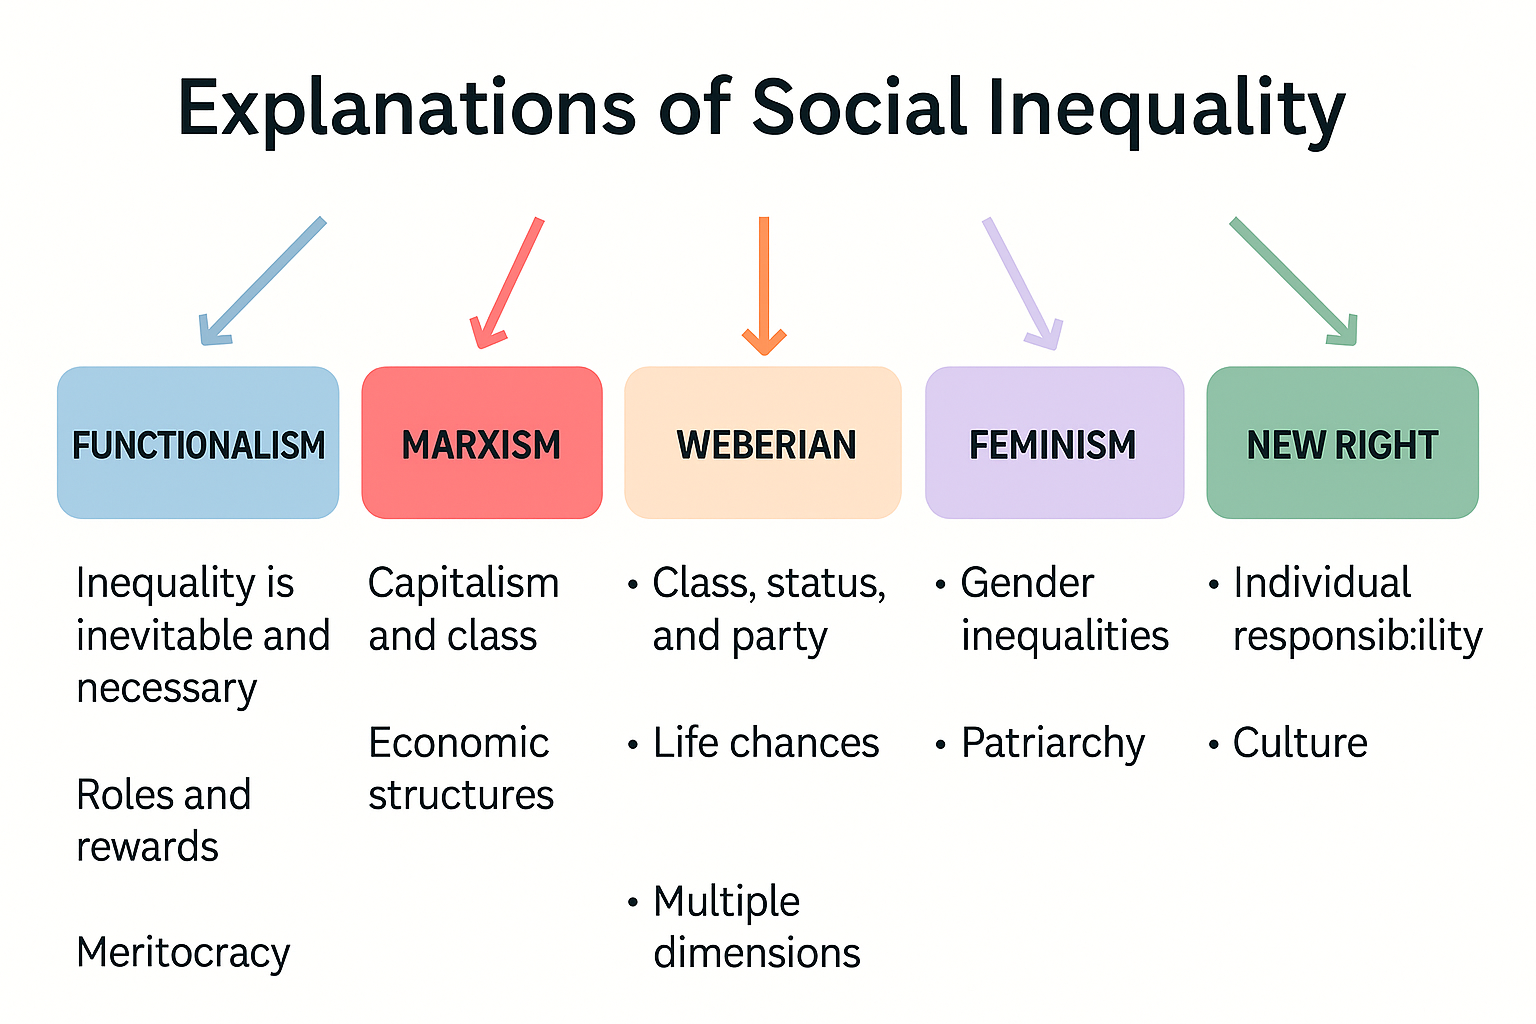
At its core, the concept refers to how resources, opportunities, and power are distributed unevenly across social groups. But the interesting part isn't the definition. It's what happens when you actually try to operationalize it. Most introductory courses cover the big three frameworks: functionalism, conflict theory, and symbolic interactionism. You'll also encounter Weber's multidimensional approach, which treats class, status, and party as separate but related axes. Bourdieu added cultural capital to that mix, which turns out to be one of the most useful tools for explaining things that pure economic models miss. Here's what nobody tells you about applying these frameworks: they often contradict each other in practice. A functionalist reading of educational inequality will emphasize sorting and merit allocation. A conflict theorist looking at the same data will see reproduction of advantage. Both can be right. They're just answering different questions. I learned this the hard way when reviewing grant proposals for a regional education equity study. Two reviewers from different theoretical backgrounds rejected the same methodology for opposite reasons. The workaround was straightforward: explicitly state which level of analysis you were prioritizing and acknowledge where the alternative framework would draw different conclusions. That saved the proposal. The deeper issue is that social inequality isn't a single phenomenon. It's a cluster of related processes that reinforce each other. Economic inequality creates political inequality. Political inequality shapes educational access. Educational access affects health outcomes. Health outcomes feed back into economic position. The feedback loops matter more than any single measure.
One counter-intuitive finding from the literature is that relative inequality often matters more for social outcomes than absolute inequality. A society can become wealthier across the board while inequality increases, and the social effects tracked with the inequality trajectory, not the absolute poverty line. This shows up consistently in life expectancy data, crime statistics, and social mobility metrics. The Gini coefficient tells you something, but it doesn't tell you everything. Pair it with median-to-mean income ratios and you get a much clearer picture of what's actually happening. Another thing beginners routinely miss is the difference between structural and interpersonal inequality. Structural inequality refers to the patterns embedded in institutions and systems. Interpersonal inequality is what people experience in daily interactions. Both are real. Both produce measurable outcomes. But they require different analytical tools. Measuring discrimination in hiring requires regression discontinuity designs or audit studies. Measuring structural inequality in housing requires spatial analysis and policy tracking. Mixing up the two leads to messy, uninterpretable results. I ran into a specific problem a few years back while analyzing school funding data across a state's districts. The obvious approach was to correlate property tax bases with per-pupil spending. But that missed the largest source of inequality in the system: categorical grants and earmarked funds that flowed through completely separate channels. Property tax disparities explained about 35 percent of the spending variation. The categorical grant system accounted for another 40 percent, in the opposite direction, partially offsetting the property tax effect. The remaining variation came from federal programs and private donations. If I had stopped at the first correlation, I would have produced a clean but misleading story about local funding inequality. The real story was messier and involved state-level policy decisions that no simple bivariate analysis would reveal.
Get the Full Details
The workaround was to build a hierarchical linear model with districts nested within regions, regions nested within state funding formula categories, and to include every grant stream as a separate variable. It took three times longer to code and required cleaning data from seven different state agency formats. The output was worth it. The model showed that the state's funding formula was actually progressive at the property tax level but regressive at the categorical grant level, and that the net effect varied dramatically by region. That nuance is exactly what policy changes respond to. Intersectionality is another concept that gets taught poorly in intro courses. It's not just "add diversity and stir." It's a specific analytical framework for understanding how multiple axes of disadvantage interact in ways that aren't additive. A Black woman's experience isn't the sum of Black experience plus woman experience. The interaction produces qualitatively different outcomes in employment, healthcare, and criminal justice systems. Categorical variables in regression won't capture this properly. You need interaction terms, or better yet, qualitative methods that can track the mechanism. The main bottleneck with inequality research is data quality. Administrative datasets are fragmented across agencies with different definitions and reporting periods. Survey data suffers from nonresponse bias that skews toward higher-income and higher-educated respondents. Linking datasets across sources introduces match errors. None of this is unique to inequality research, but inequality research is especially vulnerable because the populations you're studying are the ones least likely to appear in official data. I've seen researchers accidentally exclude the most disadvantaged communities simply because those communities had the highest rates of institutional residency, mobile housing, and informal employment, all of which are undercounted in standard surveys.
There's no perfect solution to the data problem. The best approach I've found is triangulation: combine whatever administrative data you can get, supplement with targeted survey work in the missing populations, and use qualitative interviews to validate that the numbers are measuring what you think they're measuring. It's slower and more expensive than running a single regression on existing data. It's also the only way to avoid producing confident but wrong conclusions. Policy implications are where this gets uncomfortable. Inequality research rarely produces clear policy recommendations because the relationships are contingent and context-dependent. A universal basic income intervention in one city produced different mobility effects than the same intervention in another city, even when the baseline inequality measures were similar. The difference came down to local labor market structure and existing social service networks. There's no portable inequality fix. Any intervention has to be designed for the specific mechanism it's targeting. The field also struggles with causality. Cross-sectional data dominates the literature because it's cheaper and faster. Longitudinal studies are better but expensive. Natural experiments are rare and often too context-specific to generalize. Causal inference methods like instrumental variables and difference-in-differences help, but they require assumptions that are rarely stated clearly enough. I've reviewed papers where the identified "causal effect" of a policy on inequality depended entirely on a parallel trends assumption that didn't hold in the pre-treatment period. The authors didn't notice because they never checked.
If you're getting into this work, start with clear definitions of what type of inequality you're studying. Economic inequality is not the same as social inequality. Social inequality is not the same as political inequality. They overlap. They're not identical. Pick your lane, justify your measure, and be honest about what your method can and can't show. The field has enough confident nonsense already.