Understanding Biodiversity Beyond the Textbook Definition
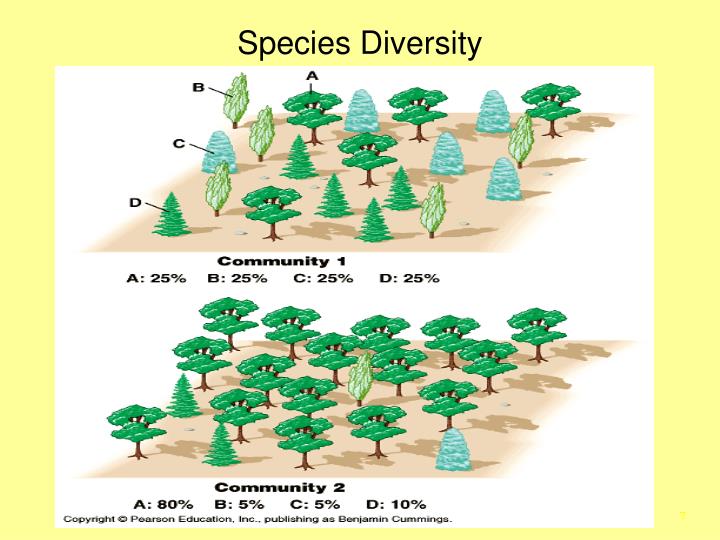
When people talk about species diversity, they usually mean how many different kinds of organisms exist in a given area and how evenly those populations are distributed. That's the basic idea, but it's also where most introductions to the topic stop, and that gap between the simplified version and what you actually deal with in the field is significant. Species diversity combines two separate metrics: species richness, which is simply the count of different species present, and species evenness, which measures whether those species have relatively similar population sizes or if one or two dominate completely. A forest with 50 tree species where each has roughly the same number of individuals is far more diverse than a forest with 50 species where one species makes up 90 percent of all individuals, even though the richness numbers are identical. The difference matters because ecosystems with higher evenness tend to be more resilient to disturbance, disease, and climate stress. I spent three years monitoring plant communities across fragmented habitats in the Pacific Northwest, and the standard diversity indices we relied on kept giving us misleading pictures. Shannon-Wiener and Simpson's indices are the workhorses here, and they handle the richness-plus-evenness calculation differently. Shannon weighs rare species more heavily, while Simpson emphasizes dominance. In practice, I found that using both together caught cases where one index would paint a stable ecosystem while the other flagged a quiet collapse happening underneath.
The real trouble started when I tried applying these indices to a wetland site that looked healthy on the surface. Richness was high, around 42 vascular plant species across our quadrats, and evenness looked reasonable at first glance. But when I ran the data through a rank-abundance curve, I spotted something the aggregate numbers hid. Seven species accounted for over 60 percent of all individual stems, and four of those were invasive reed canary grass and knotweed. The native diversity was functionally diminished even though the raw species count never dropped. That's the kind of thing standard diversity reports routinely miss because they compress everything into a single number.
Why Raw Counts Lie to You
One of the more counter-intuitive things about measuring diversity is that adding more species to a dataset doesn't always mean the diversity index goes up the way you'd expect. In highly productive environments where a few fast-growing species monopolize resources, you can have high richness numbers but low functional diversity because the ecological roles are redundant. Two sites might both register 30 bird species, but if one site's birds fill six distinct feeding niches and the other site's birds all eat the same insects from the same canopy layer, the first site is far more diverse in any meaningful sense. Functional diversity is what bridges that gap, and it requires looking past species lists entirely. You need trait data: beak morphology, root depth, flowering phenology, foraging height. I learned this the hard way when a funding reviewer asked why our site with fewer species was designated as higher priority for conservation. The answer came from our trait analysis showing that the rarer species occupied unique positions in the resource-use space, meaning their loss would compress the functional range more than losing one of several redundant common species. Another pitfall beginners run into is sampling effort bias. If you survey a tropical plot for two days and a temperate plot for two weeks, the temperate plot will appear artificially diverse simply because you gave it more time to accumulate rare species. Rarefaction curves solve this by standardizing samples to equal effort, but even that has limits. It assumes your sampling method catches every species with equal probability, which is never true in practice. Invertebrate diversity especially suffers from this because your sweep net, pitfall trap, and hand-sorting protocol each catch different subsets of the community, and no single curve reconciles them.
Get the Full Details

Getting Practical With Field Methods
The fastest reliable approach for a quick diversity assessment is a stratified random quadrat design combined with a standardized count protocol. For plants, a 1-meter square quadrat works well in most herbaceous communities, and you record every individual within that frame. For larger or more spaced-out vegetation, a 10-by-10-meter plot gives you better resolution on tree and shrub layers. The key is consistency: if you change quadrat size halfway through your sampling, your evenness calculations become garbage because the detectability threshold shifts. I usually run about 20 to 30 quadrats per site depending on habitat heterogeneity. That number catches the dominant species reliably and starts approaching asymptote on the species accumulation curve for medium-complexity communities. Simple grassland might need fewer. Old-growth forest understory definitely needs more. If your accumulation curve hasn't flattened by your 20th quadrat, you're under-sampling and your richness estimate is a floor, not a ceiling. For mobile fauna like birds or insects, point counts and transect sweeps are the standard, but the diversity problem shifts from detection probability to behavioral variation. A male warbler singing at dawn is trivially detectable. A female of the same species foraging silently in the mid-canopy might go entirely unrecorded during a short window. I ended up running separate dawn and midday surveys for a season just to quantify how much the Shannon index changed between those periods, and the difference was roughly 0.3 to 0.5 bits, which sounds small but is ecologically substantial when you're comparing management treatments.
Calculating Diversity Without Overcomplicating It
You don't need specialized software to compute basic diversity indices. A spreadsheet handles it fine if you have your rank-abundance data organized correctly. Enter species names in column A, individual counts in column B, then sort descending by count. The Shannon index formula is H = minus the sum of p_i times ln of p_i for each species, where p_i is the proportion of individuals that belong to species i. Simpson's index is D = the sum of n_i times n_i minus 1 divided by N times N minus 1, where n_i is the count for species i and N is the total count across all species. Both are straightforward enough to implement manually. The evenness component comes from dividing your observed Shannon value by the maximum possible Shannon value, which is ln of S where S is total species richness. That gives you Pielou's J, ranging from zero to one, with one meaning perfect evenness. If you get a J value below 0.3 in a natural system, something unusual is going on, usually dominance by an invasive or a severe environmental filter squeezing out weaker competitors. Here's where my wetland example becomes relevant again. When I recalculated diversity after removing the invasive canopy species and reclassifying their counts, the Shannon index jumped from about 2.1 to 2.8 and Pielou's evenness went from 0.52 to 0.71. The species richness stayed at 42 because the invasives were already counted as species. This is the exact scenario where the headline number looks stable while the ecosystem is quietly losing structure, and it's why I now always report evenness alongside richness rather than letting a single diversity number do all the heavy lifting.
When Standard Diversity Metrics Break Down
There are scenarios where species diversity as a concept hits a wall, and being honest about those boundaries is more useful than pretending the metrics work universally. Microbial communities are the most obvious example. You can sequence thousands of operational taxonomic units from a single gram of soil, but your definition of what counts as a species shifts entirely depending on the gene region you amplify and the similarity threshold you set, usually 97 percent for 16S rRNA. The resulting diversity numbers are internally consistent within a study but meaningless when comparing across studies that used different primers or clustering algorithms. Fungal diversity faces a similar problem with an added wrinkle. Most fungal species haven't been cultured, so identification relies on environmental sequencing, and the taxonomic databases for fungi are incomplete compared to plants or animals. A diversity study in a temperate forest might confidently identify 80 percent of its vascular plants to species level but only reach genus or family level for fungi, inflating the apparent gap in diversity between those groups. The organisms aren't necessarily less diverse, your ability to resolve them is just worse. Another boundary case is disturbed or transient communities where species composition changes faster than your sampling interval captures. A recently cleared agricultural field might show a diversity spike in year one because pioneer species from multiple dispersal routes colonize simultaneously, then crash as competitive exclusion kicks in. If you sample once per year, you'll see that oscillation clearly. If you sample once every three years, you'll miss the peak entirely and conclude the system is depauperate when it actually passed through a high-diversity phase.

Choosing the Right Index for Your Question
The index you pick should match the ecological question, not the other way around. If you're assessing habitat quality for a regulatory permit, richness is usually what the framework expects, even though it's the crudest metric available. If you're studying ecosystem stability or resilience, Shannon or Fisher's alpha gives you better signal. If you're concerned about dominance and competitive exclusion, Simpson's index or the evenness component derived from it is your best bet. Fisher's alpha is worth mentioning because it's less commonly taught in introductory courses but performs well when you have long tail distributions with many rare species. It derives from a logarithmic series model and is relatively insensitive to sample size compared to raw richness, which makes it handy when comparing sites with inherently different sampling intensities. I used it extensively in my work with old-growth versus second-growth forests because the old-growth sites had dramatically more rare understory species that richness alone couldn't contextualize properly. Phylogenetic diversity is another layer that most basic studies skip, and it's increasingly important as sequencing costs drop. Two communities might share the same species count but differ radically in evolutionary history. A community composed of five closely related oak species represents far less phylogenetic diversity than a community with five species spanning different families and orders. Conservation decisions based solely on species counts can accidentally prioritize areas that look diverse superficially but are phylogenetically clustered, which means the functional and evolutionary insurance value is lower than the numbers suggest.
A Reality Check on What Diversity Numbers Tell You
Species diversity is a useful shorthand, but it's a shorthand, not a complete diagnosis. It tells you something about complexity, not about health, function, or trajectory. A degraded estuary can maintain high diversity for years through generalist species cycling in while the specialists disappear, creating a diversity debt that eventually comes due when environmental conditions tip past a threshold. The numbers look fine right up until they don't. The most practical takeaway is to measure diversity as part of a broader monitoring package that includes abundance trends, trait composition, and spatial distribution patterns. If you only track a single diversity index, you're watching one dimension of a multidimensional system and assuming it captures the rest. It doesn't. I've seen too many restoration projects declared successful because the target diversity number was met, only to watch the site flatten out functionally because the wrong species assembled to fill the space. Recording your methods transparently matters more than the precision of your final index value. Report quadrat size, sampling duration, identification resolution, and which indices you calculated. That lets anyone evaluating your work understand what the numbers actually represent instead of treating them as objective truth. The difference between a useful diversity assessment and a misleading one is rarely the math, it's usually what got left out of the report.