Understanding the Concept Before Getting Into the Details
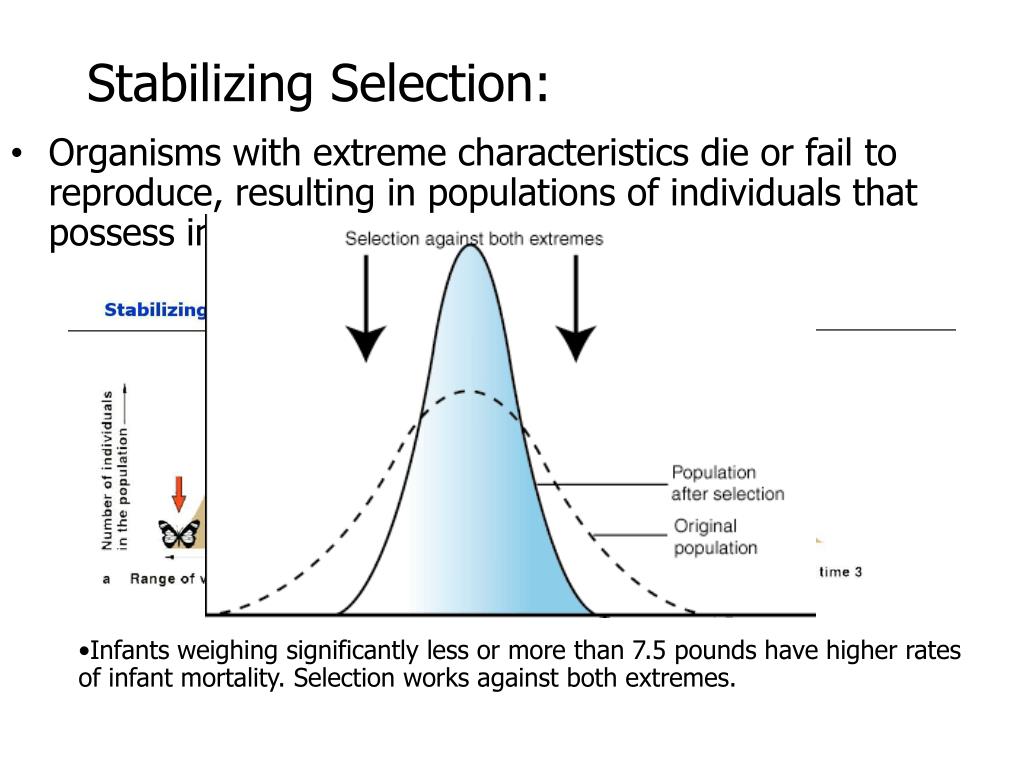
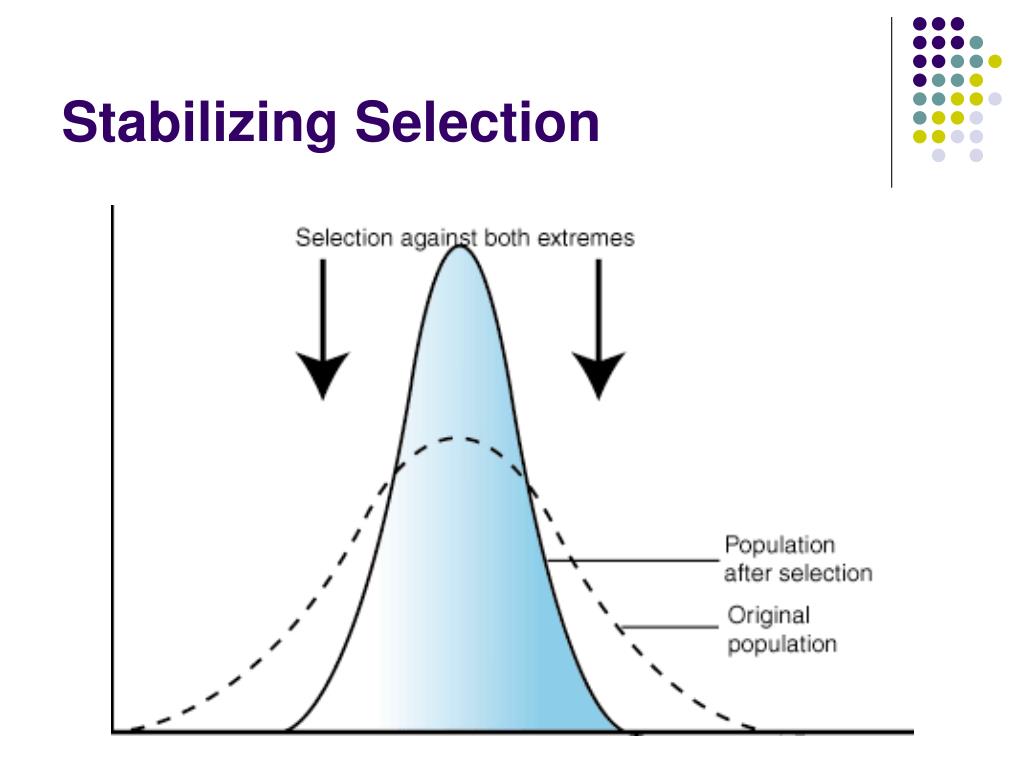
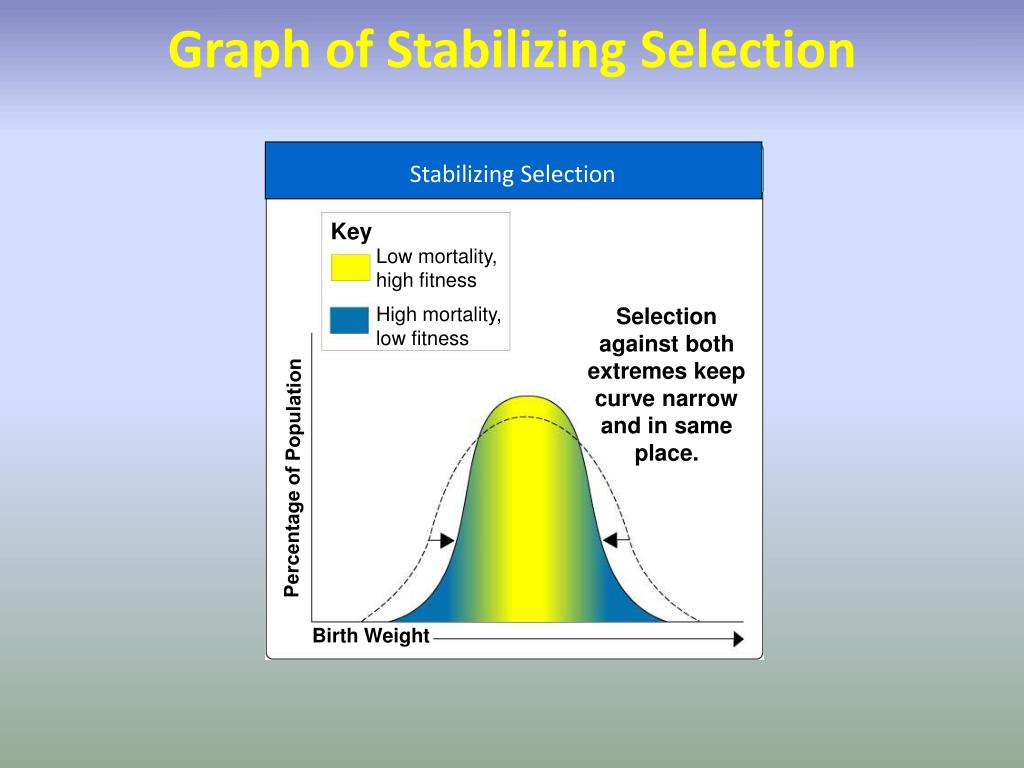
The idea is straightforward enough, but people routinely mess it up when they try to apply it. What Is Stabilizing Selection really comes down to this: natural selection favors intermediate phenotypes and selects against extreme variants. That's it. The bell curve gets narrower over generations because the people at the tails are less likely to survive and reproduce. Nothing poetic about it. I ran into this when I was working on a dataset involving birth weights in human populations. The classic textbook example. Babies born too small had high mortality rates. Babies born too large also had high mortality due to birthing complications. The optimum was right around 7.5 pounds, give or take a pound. Over decades, you see the distribution tighten around that mean. It's not dramatic. It's just math playing out across generations.
What Is Stabilizing Selection and How It Actually Works
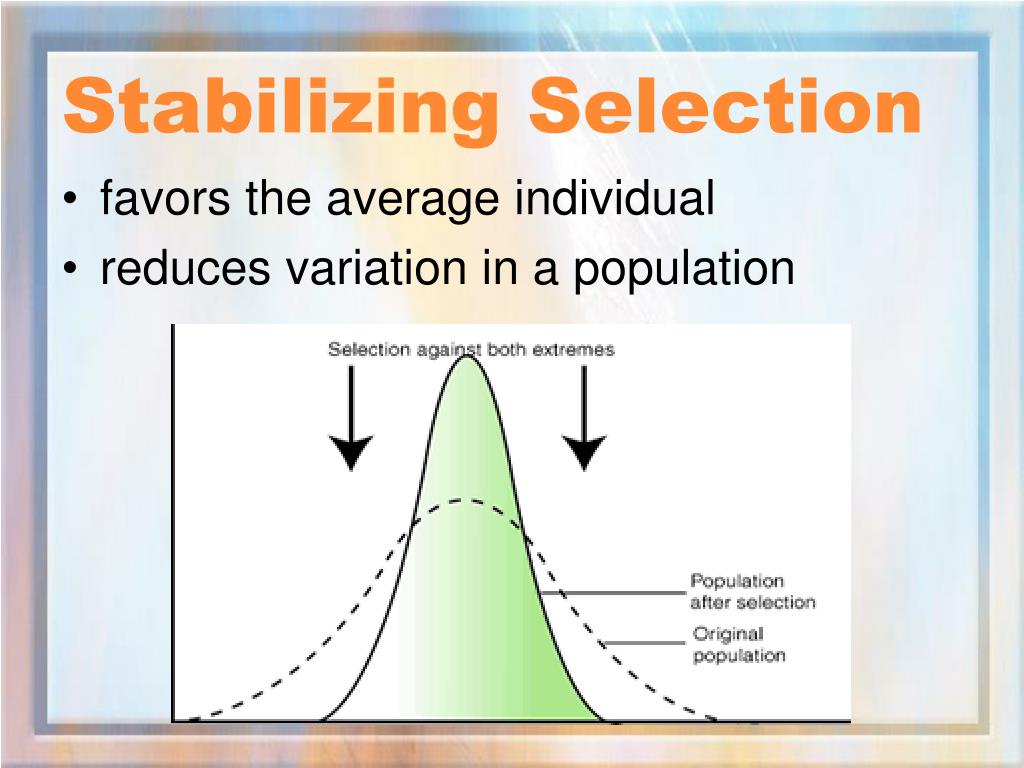
You need to understand the mechanism before you try to spot it in real data. The key is that selection pressure comes from both ends simultaneously. This distinguishes it from directional selection, where pressure only comes from one side pushing the curve in a single direction. Directional selection is what you get when a population is adapting to a changing environment. Stabilizing selection is what happens when the environment is already well-matched to the current population and any deviation is costly. The fitness landscape matters here. In a stabilizing scenario, the fitness function looks like an inverted U-shape. The peak is at the mean phenotype. As you move away from that peak in either direction, fitness drops. It doesn't matter if you're above or below. Both extremes get penalized. This is why the genetic variance in the population shrinks over time. Not because variation is disappearing entirely, but because the individuals carrying extreme alleles are leaving fewer descendants. One thing beginners miss is that stabilizing selection doesn't require the phenotype to be fixed. The optimum can drift. If environmental conditions shift even slightly, the fitness peak moves, and what was once an intermediate trait suddenly becomes extreme. This is a common source of confusion in the field. People see a narrowing distribution and assume selection is stabilizing, but they haven't checked whether the optimum itself has been moving.
In practice, I've found that you can detect this pattern by looking at variance trends across generations more than mean trends. If the mean stays roughly constant while the variance is clearly compressing, that's your signal. The opposite pattern—mean shifting with relatively stable variance—would point to directional selection instead. I once spent two weeks trying to figure out why a bird population wasn't responding to what I thought was stabilizing selection on beak size. Turns out the real selective pressure was on flight feather length, which was correlated but not identical. The beak data looked perfectly stable while the actual selection was happening elsewhere. Measuring the wrong trait is probably the most common error I see.
Get the Full Details
Where This Gets Complicated
Stabilizing selection is rare in its pure form. Most real populations experience a mix of selection types simultaneously, and disentangling them is not trivial. You might have stabilizing selection on body size while also having directional selection on disease resistance, for instance. The net effect on the population depends on how these pressures interact and which traits are genetically correlated. Another complication is that stabilizing selection can maintain genetic variation through mechanisms like heterozygote advantage or frequency-dependent selection. The classic example is sickle cell anemia in malaria-prone regions. The heterozygotes have an advantage, which maintains both alleles in the population despite selection against the homozygous extremes. This means the population can show signs of stabilizing selection on a phenotype while still harboring significant genetic diversity at the underlying loci. If you're looking at phenotypic data alone, you'd miss the hidden variation entirely. Quantitative genetics gives you tools to estimate selection gradients, but these estimates come with real assumptions. The Lande-Arnold framework assumes a linear or quadratic relationship between fitness and phenotype, which is often a rough approximation. In practice, the relationship can be more complex. Threshold effects, synergistic interactions, and environmental heterogeneity all mess with the clean quadratic model. I've seen selection gradients estimated from field data that looked solid on paper, but when the researchers actually tracked the next generation, the predicted response was off by a factor of three. The issue was usually unmeasured covariates—environmental factors that correlated with the trait and created spurious selection signals.
Here's another counter-intuitive point that surprises people: stabilizing selection can actually slow adaptation. By continuously pruning extreme phenotypes, it reduces the raw material that directional selection would otherwise act on. If the environment changes rapidly, a population under strong stabilizing selection may lag behind the new optimum because it's actively removing the variation that could help it catch up. This is relevant to conservation biology. Populations with historically low variance due to long-term stabilizing selection might be more vulnerable to rapid environmental change than you'd expect from their current mean phenotype alone. I worked with a group managing a declining amphibian population where this turned out to be exactly the problem. The frogs were well-adapted to stable conditions, but their genetic variance had been eroded over centuries of stabilizing selection. When the wetland habitat started drying out, they had nowhere to go genetically.
Practical Considerations and Limitations
If you're trying to identify stabilizing selection in your own work, start by checking whether your trait actually shows a fitness cost at both extremes. This sounds obvious but it's easy to skip if you're focused on the mean. Also verify that the trait is heritable. If the phenotypic variation you're observing is mostly environmental, selection acting on it won't produce an evolutionary response. You can estimate heritability through breeding studies or sibling correlations, though these approaches each have their own weaknesses. The main limitation of relying on stabilizing selection as an explanatory framework is that it's often a default assumption rather than a tested hypothesis. People see a stable trait and assume stabilizing selection is maintaining it. But trait stability can also result from genetic drift in small populations, pleiotropic constraints, or simply the absence of any meaningful fitness variation associated with the trait. Before settling on stabilizing selection, consider whether you've actually ruled out these alternatives. A common practical workaround when direct fitness measurements are impossible is to look at trait distributions across multiple environments. If a trait shows consistently low variance across different conditions, that's more suggestive of stabilizing selection than if the variance fluctuates wildly. Though even this isn't conclusive. Some traits are developmentally canalized, which produces similar patterns without any selection involved.
When the data is ambiguous, which is most of the time, I usually fall back on comparing multiple selection models rather than trying to confirm one specific mechanism. AIC or BIC comparisons between directional, stabilizing, and disruptive selection models can tell you which pattern fits best, but the confidence intervals on those estimates are often wide. Don't treat the results as definitive. They're useful for narrowing possibilities, not proving anything.