Understanding the Process Before You Touch a Tool
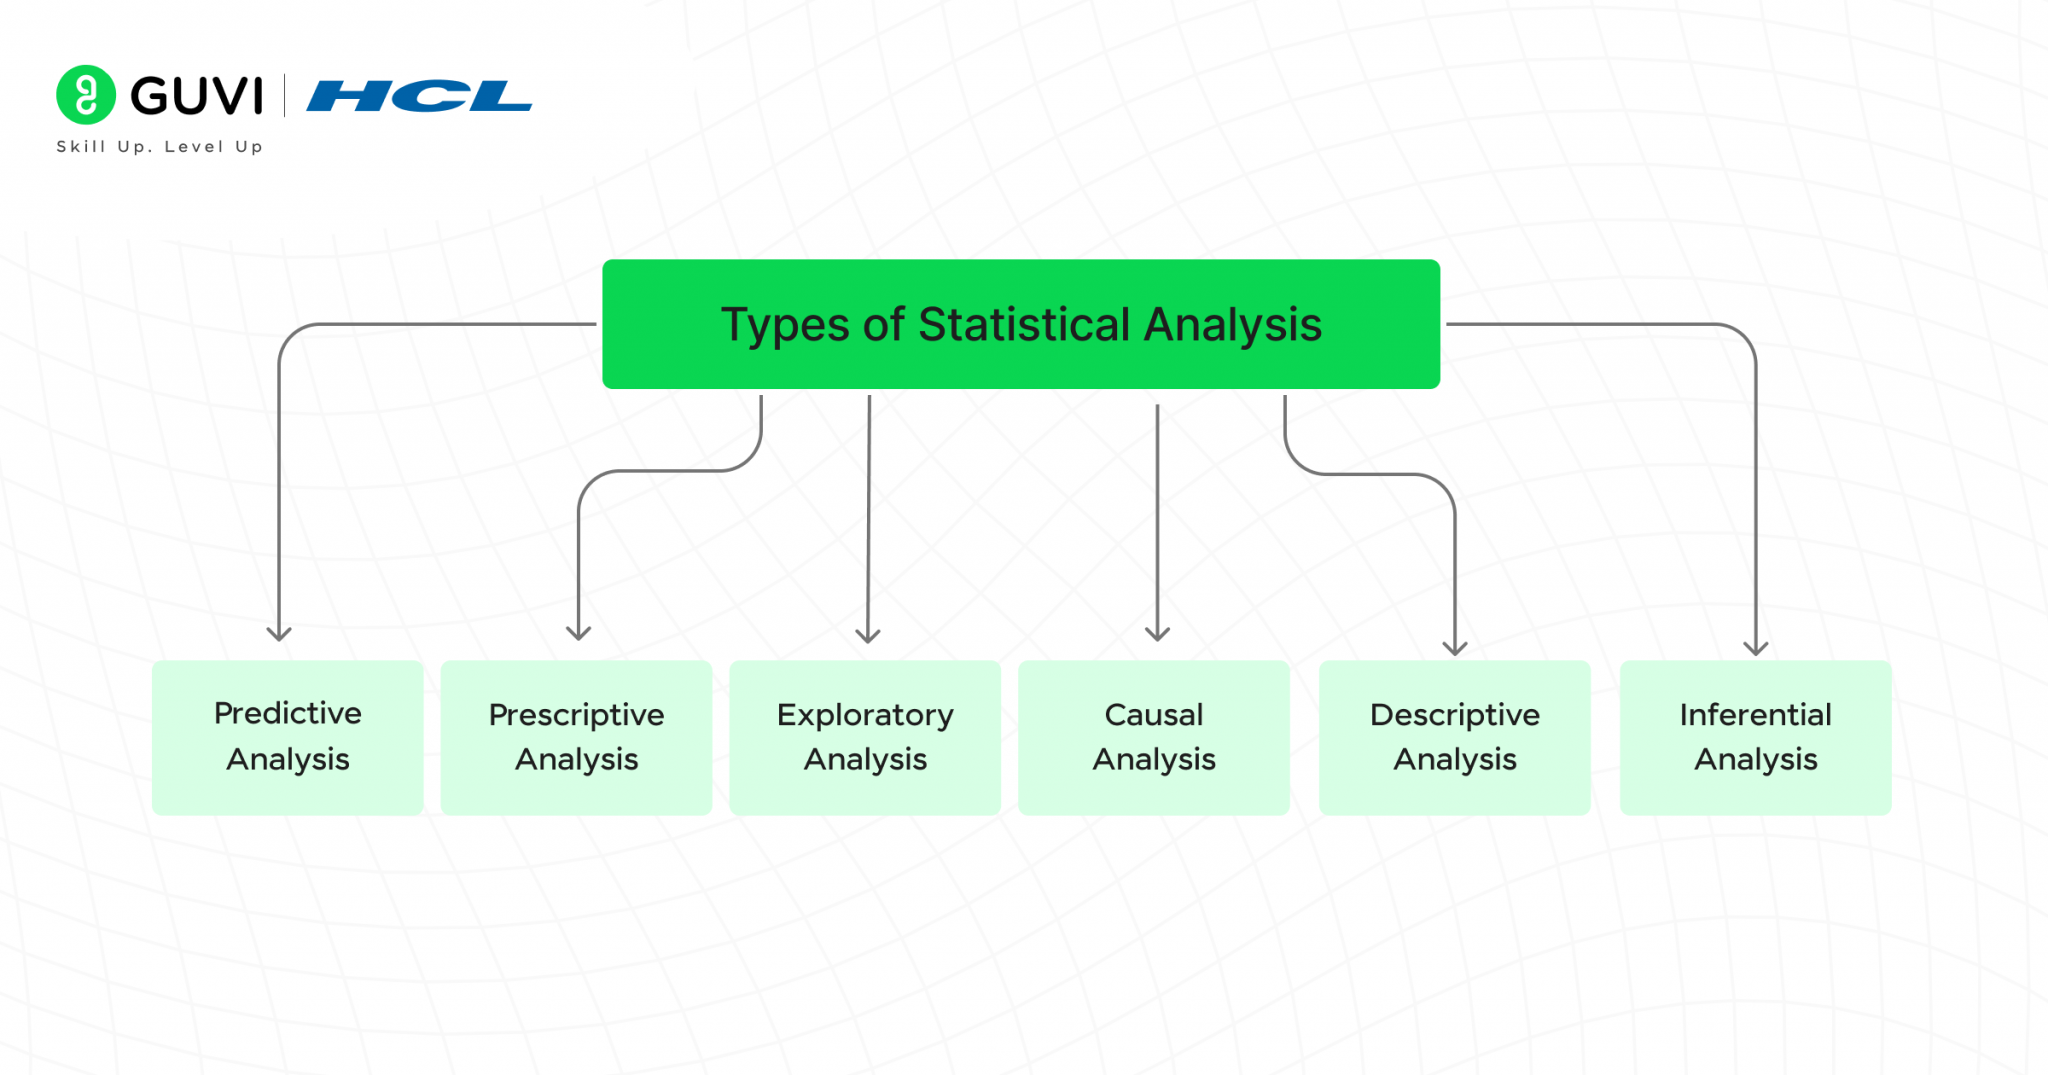
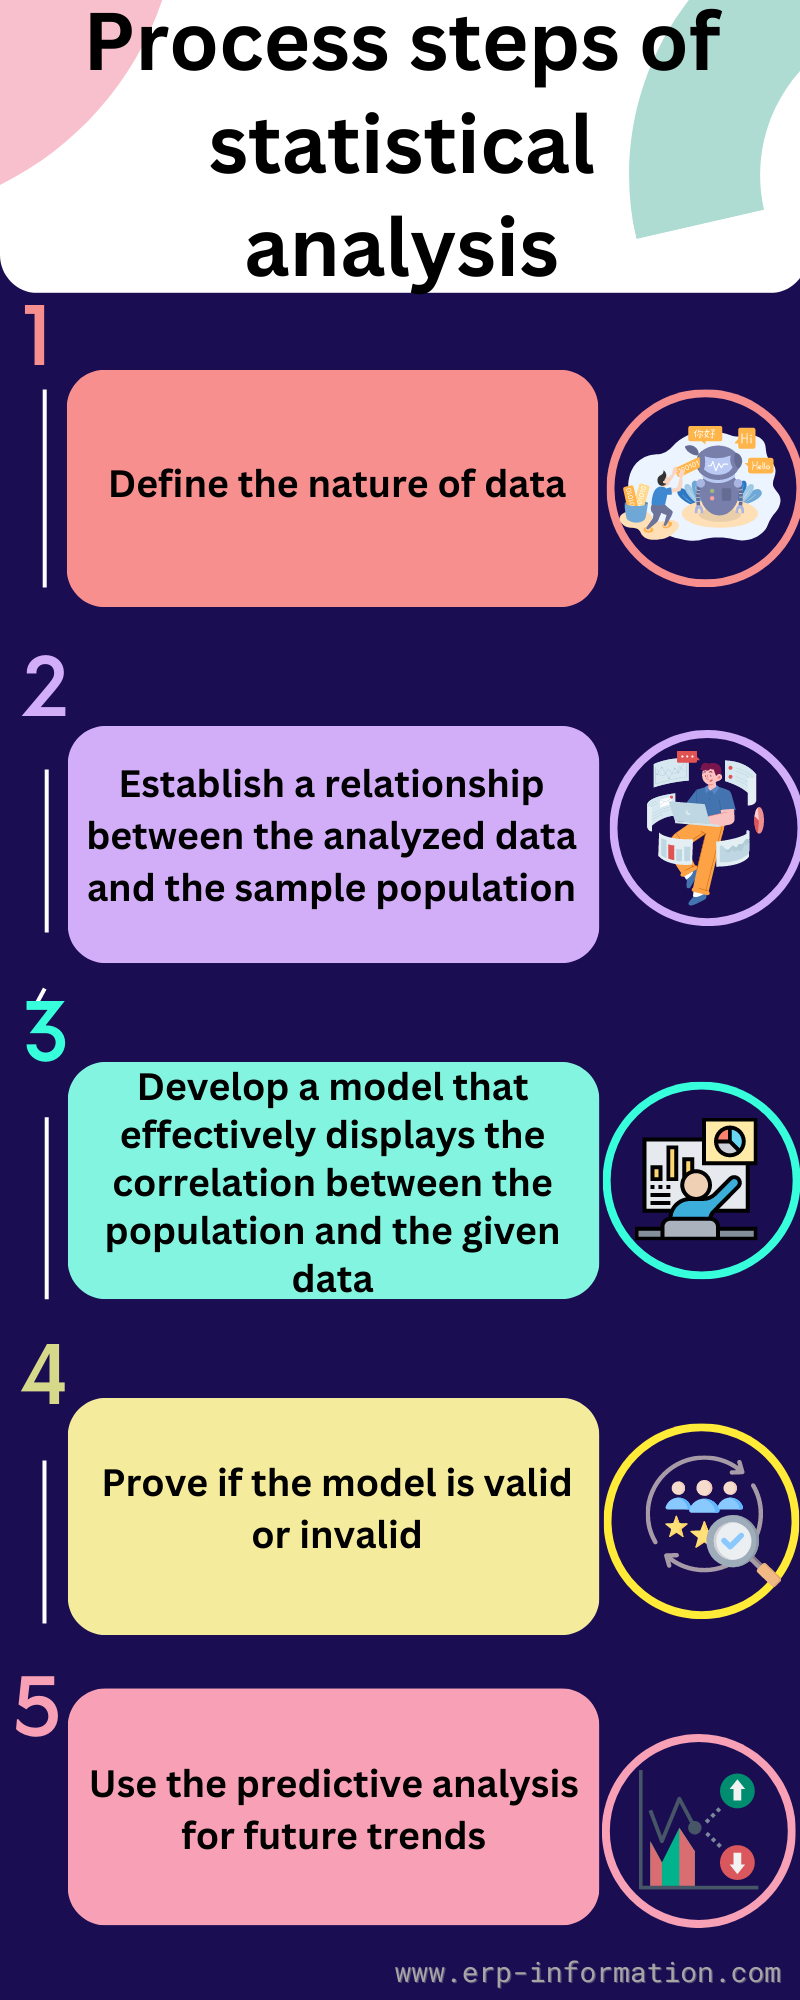
I still remember running a regression on survey data back in 2016 and spending three days trying to debug why the p-values looked wrong. Turns out the dataset had 400 rows of duplicate entries from a bad merge, and every coefficient was inflated because the model was treating them as independent observations. That kind of thing doesn't show up in any textbook introduction. It just happens. Statistical data analysis is the practice of using mathematical methods to extract patterns, test hypotheses, and draw conclusions from quantitative information. It's not a single technique. It's a workflow that moves from raw numbers to interpreted results, and every step between those two points matters just as much as the final number you report. Most people think of it as picking a test and running it. The reality is messier. You start with a question, find or collect data, clean it, explore it, choose the right method, run it, check your assumptions, and then interpret what came out. The interpretation step is where most analyses go off track. People skip it or treat it as an afterthought, and then they publish a result that technically "passed" every statistical gate but actually means nothing for the problem they set out to solve.
Here's the part beginners don't expect: the analysis you pick depends almost entirely on your data structure and your research question, not the other way around. I've seen analysts load data into a tool, see it was a time series, and immediately default to ARIMA models. The data turned out to have missing months due to a reporting gap, so the ARIMA fit was garbage. They spent a week on a model that was fundamentally inappropriate. Switching to a simpler interpolated linear trend with proper confidence bands gave a better answer in two hours. Descriptive statistics come first in almost every project. You calculate means, medians, standard deviations, ranges, and look at distributions. This step usually takes longer than people anticipate. I once cleaned a dataset that looked normal at a glance — until I plotted the actual histogram and found a long right tail driven by a handful of extreme values. The mean was misleading. The median told the real story.
Common Methods and When They Actually Work
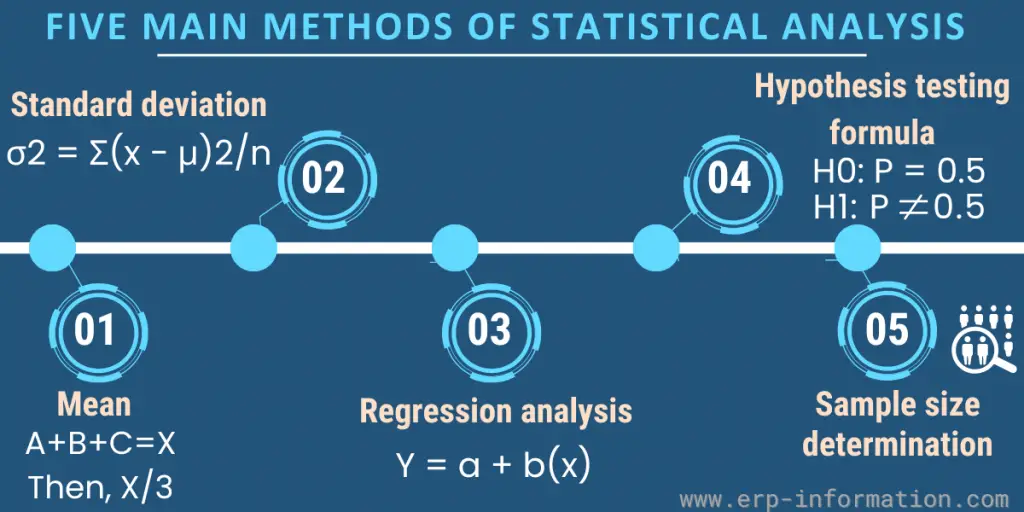
Regression analysis is the workhorse. Linear regression assumes a straight-line relationship between your variables. You check residuals for normality and homoscedasticity. If those assumptions break, you either transform your variables or switch to a generalized linear model. Logistic regression handles binary outcomes. Polinomial and interaction terms let you model curvature and combined effects. The key is knowing when to add complexity and when to stop. Hypothesis testing covers t-tests, chi-square tests, ANOVA, and non-parametric alternatives like the Mann-Whitney U test. You use a t-test when comparing two group means with roughly normal distributions and similar variances. You switch to a Welch's t-test when variances differ. You use ANOVA for three or more groups. If your data is ordinal or heavily skewed, Kruskal-Wallis is usually safer than forcing a parametric test. Time series analysis requires its own section because it behaves differently from cross-sectional data. Autocorrelation means observations aren't independent, which breaks standard regression assumptions. You need to check the autocorrelation function and partial autocorrelation function before modeling. Seasonal decomposition, exponential smoothing, and ARIMA-family models are the main tools. Forecast accuracy matters more than model elegance here.
Get the Full Details
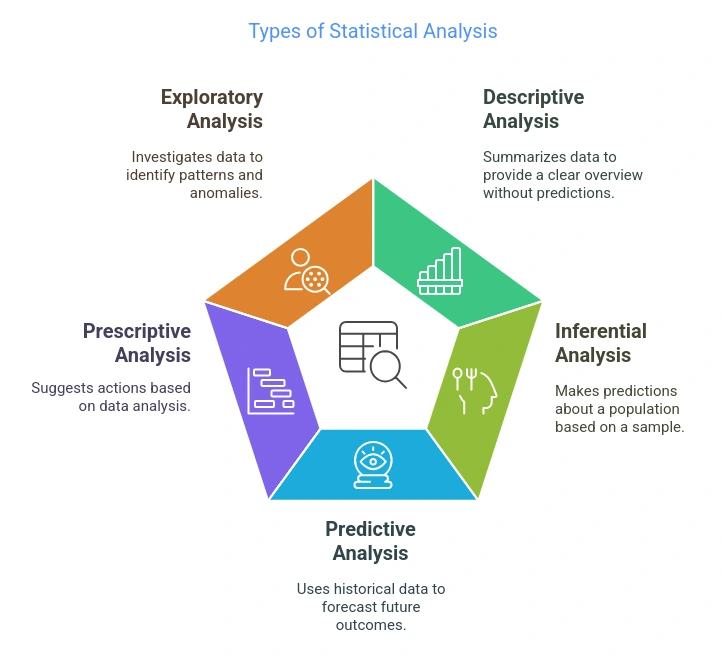
Multivariate techniques like factor analysis, principal component analysis, and cluster analysis reduce dimensionality or find groupings in your data. PCA rotates your variables into uncorrelated components that explain maximum variance. Factor analysis identifies latent constructs behind observed variables. Cluster analysis groups similar observations without predefined categories. Each has common failure modes. PCA can produce uninterpretable components if you don't rotate. K-means clustering assumes spherical clusters and fixed k. Hierarchical clustering can produce misleading dendrograms with the wrong linkage method.
The Cleanup Step That Determines Everything
Data cleaning is not a chore you rush through. It's the step that makes or breaks your analysis. Missing values need attention. Outliers need investigation, not automatic deletion. Inconsistent formatting happens constantly. I once merged two customer datasets where one stored dates as MM/DD/YYYY and the other as DD-MM-YYYY. Half the records got scrambled, and the resulting time trend analysis was completely inverted. I caught it only because I plotted a sample of the dates before running the full model. Types of missing data matter. Missing completely at random (MCAR) means the gaps are random noise. Missing at random (MAR) means the gaps correlate with other observed variables. Missing not at random (MNAR) means the gaps correlate with the unobserved values themselves. Each type requires a different handling strategy. Listwise deletion works fine for MCAR with small gaps. Multiple imputation handles MAR better. MNAR is genuinely hard and usually requires sensitivity analysis to acknowledge the uncertainty. Outliers are another area where people make mistakes. A single extreme value can skew means and inflate standard deviations. But removing outliers without justification is worse. I worked on a project where an analyst deleted every point beyond three standard deviations. The remaining data looked clean, but the original outliers were actually legitimate high-value customers. Removing them biased the revenue projection downward by nearly 20 percent. The right move is to test with and without outliers, document the difference, and let the domain context decide.
Choosing and Running the Right Method
Software choices depend on your workflow. R is powerful and free but has a steeper learning curve. Python with pandas, NumPy, and SciPy covers most needs and integrates well with production systems. SPSS and SAS are common in regulated industries where audit trails matter. Excel gets used everywhere despite its limitations with anything beyond basic operations. The tool doesn't matter as much as understanding what the tool is doing under the hood. Model selection should be driven by your question, not by what sounds impressive. A well-justified simple model beats an overcomplicated one every time. Overfitting is the most common error. It happens when a model learns noise instead of signal, performing well on training data but poorly on new data. Cross-validation catches this. Split your data into training and validation sets, or use k-fold cross-validation, and compare performance across folds. If the gap between training and validation performance is large, your model is too complex. Assumption checking is non-negotiable. Every statistical method rests on assumptions. Violating them doesn't always break everything, but it changes what your results mean. For regression, check linearity, independence, homoscedasticity, and normality of residuals. For ANOVA, check normality and equal variances across groups. For correlation, check for linearity and outliers. A quick diagnostic plot often reveals problems faster than a formal test.
Interpreting Results Without tricking Yourself
P-values get misused constantly. A p-value below 0.05 does not mean your hypothesis is true. It means the observed data would be unlikely if the null hypothesis were true. It says nothing about effect size or practical significance. I've seen published studies where statistically significant results had effects so small they were meaningless in practice. Always report confidence intervals alongside p-values. They give you the range of plausible values, not just a binary pass-fail judgment. Effect size tells you whether a finding matters. Cohen's d for mean differences, R-squared for regression, odds ratios for logistic models. These metrics ground your results in reality. A study might find a statistically significant difference between two treatments with a p-value of 0.03, but if the effect size is 0.08, the clinical or business relevance is negligible. Statistical significance and practical significance are different concepts, and conflating them is a persistent problem in the field. Correlation does not imply causation. This is the most repeated piece of advice in statistics, and also the most ignored. Two variables moving together doesn't mean one causes the other. There could be a third variable driving both, or the relationship could be coincidental. Causal inference requires specific study designs like randomized controlled trials, or specialized techniques like instrumental variables, difference-in-differences, or propensity score matching when experiments aren't feasible.
Where Standard Approaches Break Down
Statistical analysis has hard limits. Small sample sizes produce unstable estimates. With fewer than 20 observations per group, even basic t-tests lose reliability. Extreme skew or heavy tails distort means and standard deviations. Categorical data with sparse cells breaks chi-square assumptions. Survey data with complex sampling designs requires weighted analysis, and ignoring those weights produces biased estimates. Multiple testing is another hidden trap. Run enough comparisons and you will find "significant" results by chance alone. If you test 20 unrelated hypotheses at alpha 0.05, you expect one false positive on average. Bonferroni correction, Holm-Bonferroni, and false discovery rate control address this, but each has trade-offs. Bonferroni is conservative and can miss real effects. False discovery rate is less strict but allows some false positives. Choose based on whether you prioritize avoiding false alarms or avoiding missed signals. Some problems resist traditional statistical methods entirely. Highly nonlinear relationships with many interacting variables may need machine learning approaches. Time series with structural breaks require regime-switching models. Network data violates independence assumptions built into most standard tests. Recognizing these boundaries early saves time and prevents wasted effort on methods that were never going to fit.
A Practical Walkthrough
Let me walk through a recent project to show how these pieces connect in practice. I analyzed customer churn for a subscription service with about 12,000 accounts and 18 months of usage data. The question was straightforward: what predicts whether a customer leaves within the next 90 days? First, I defined the target variable. Churn was binary: churned or not within the window. I checked the class balance. Only 8 percent churned, which meant the model would face significant imbalance. I decided on SMOTE oversampling for training data, not for validation data, to avoid leakage. I cleaned the data and found that usage logs had gaps for about 5 percent of accounts due to tracking errors. Rather than deleting them, I imputed missing usage values using group means based on account tier and tenure. I tested sensitivity by running the model with and without imputation and found minimal difference in results.
For feature engineering, I created metrics like average daily usage, usage trend over the prior 30 days, support ticket count, and payment history. I avoided creating too many features relative to the event count. With only 960 churn cases, more than 30 features risked overfitting. I used LASSO regularization to select variables automatically, which kept the model to about 12 features. I compared logistic regression, random forest, and gradient boosting. Logistic regression performed best on out-of-sample validation with an AUC of 0.84. The tree-based models scored higher on training data but dropped to around 0.76 on validation, showing clear overfitting. I stuck with logistic regression and reported coefficients with odds ratios for interpretability. The business team wanted a simple rule: flag customers with usage dropping below a threshold. The model identified usage trend as the strongest predictor, but the relationship was nonlinear. Usage above 80 percent of baseline carried very low risk. Usage between 40 and 80 percent had moderate risk that increased steeply below 40 percent. A single threshold would have missed half the at-risk accounts. I presented the full probability curve instead and the team adopted a tiered intervention system based on predicted churn probability ranges.
This project took about three weeks from raw data to final presentation. Two weeks were spent on cleaning and exploratory analysis. Four days on modeling. Two days on validation and documentation. The analysis itself was straightforward, but the preparation work dominated the timeline, which is typical for real-world projects.
Tools Worth Knowing
R remains the standard for rigorous statistical work. Packages like tidyverse handle data manipulation, broom summarizes model outputs, and caret streamlines modeling workflows. Python covers the same ground with pandas, scikit-learn, and statsmodels. Jupyter notebooks make exploration and documentation seamless. For large datasets, SQL databases with analytical functions or distributed frameworks like Spark become necessary. Excel works for quick checks but fails reliably beyond moderate complexity. Visualization tools complete the pipeline. Matplotlib and seaborn in Python, ggplot2 in R. Good visualizations communicate results faster than tables of numbers. A well-labeled plot with confidence intervals often replaces a paragraph of explanation. Bad visualizations do the opposite. I've reviewed reports where stacked bar charts made trends impossible to read and 3D pie charts conveyed almost nothing.
The Honest Bottom Line
Statistical data analysis is a disciplined way of turning messy numbers into answers you can act on. It requires technical skill, but more importantly it requires honesty about what the data can and cannot tell you. The methods are well established. The hard part is applying them correctly to your specific situation, catching your own biases, and communicating results without overclaiming. Most projects succeed or fail based on the quality of the data and the clarity of the question, not the sophistication of the model. If you're learning this, start with small datasets and work through complete projects from start to finish. Clean the data, explore it, choose a method, run it, check assumptions, interpret results, and write up what you found. Repeat until the process feels routine. Then move to harder problems. The framework stays the same regardless of domain.