What Everyone Gets Wrong About The Central Dogma
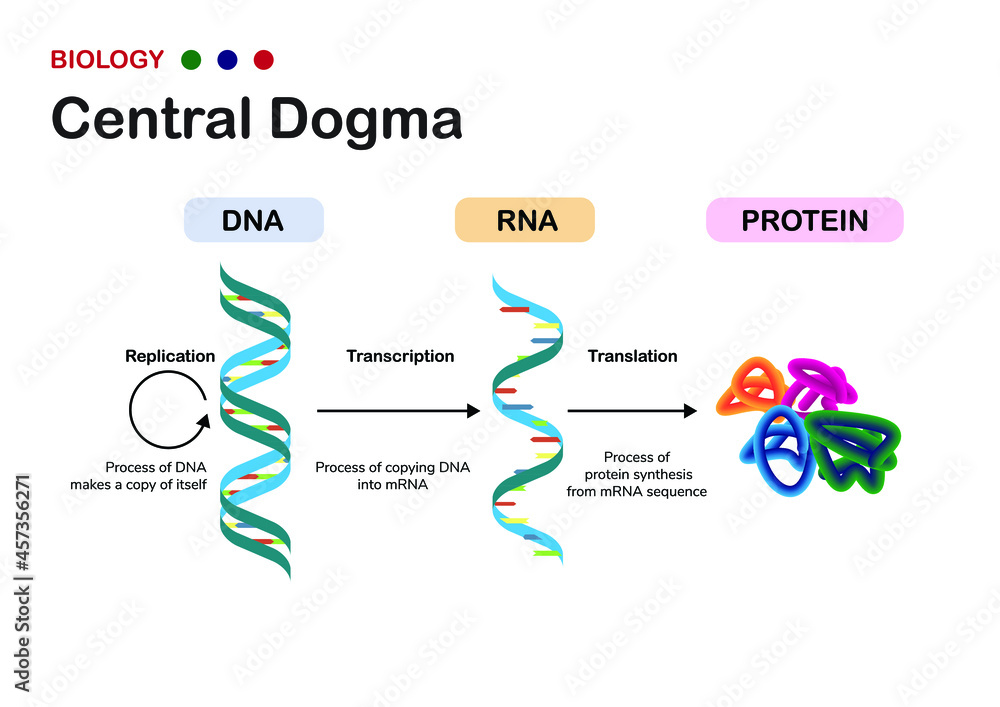
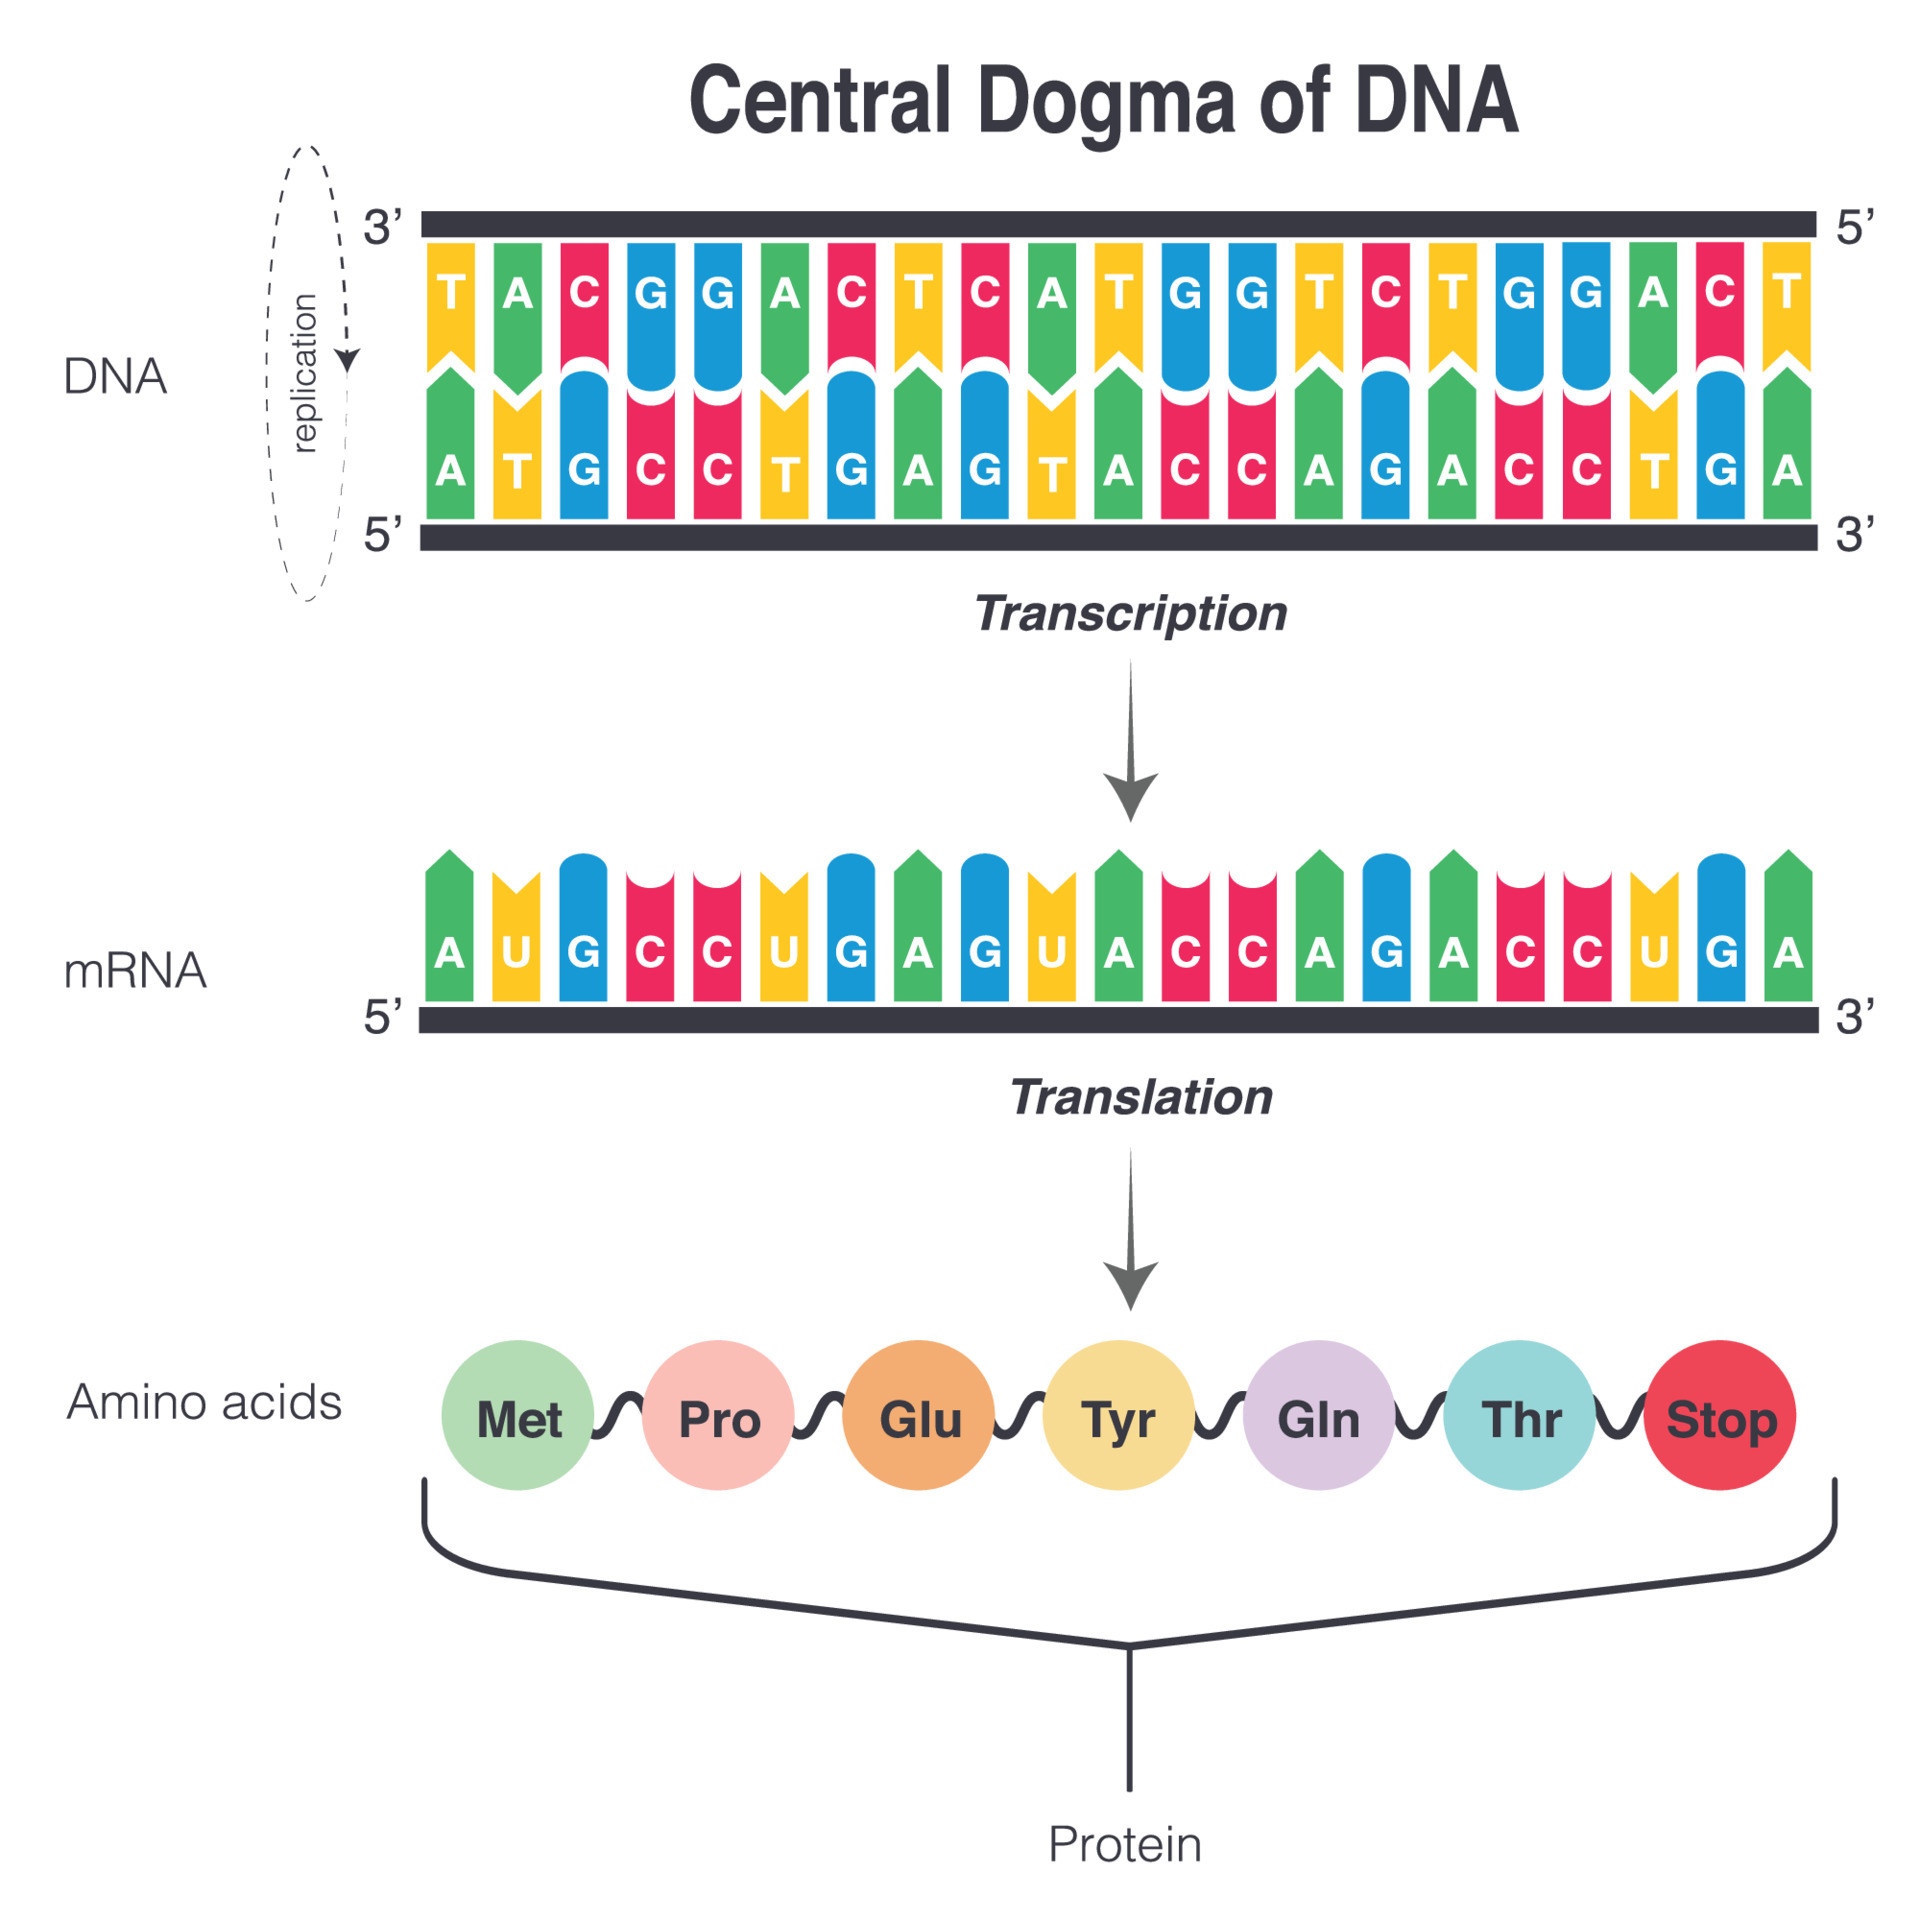
The central dogma of molecular biology is the principle that genetic information flows from DNA to RNA to protein. Francis Crick proposed it in 1958. It explains two processes: transcription, where a DNA sequence is copied into messenger RNA, and translation, where that mRNA is read by ribosomes to build a protein. That is the basic outline. The reality in the lab is messier. You learn this in your first biology class and then you rarely think about it again until something goes wrong. Most people treat it as a set of rules. It is more useful as a mental model for troubleshooting molecular work. When you are designing an experiment and the results do not match your expectations, going back to the flow of information usually reveals what you missed. The standard flow is:
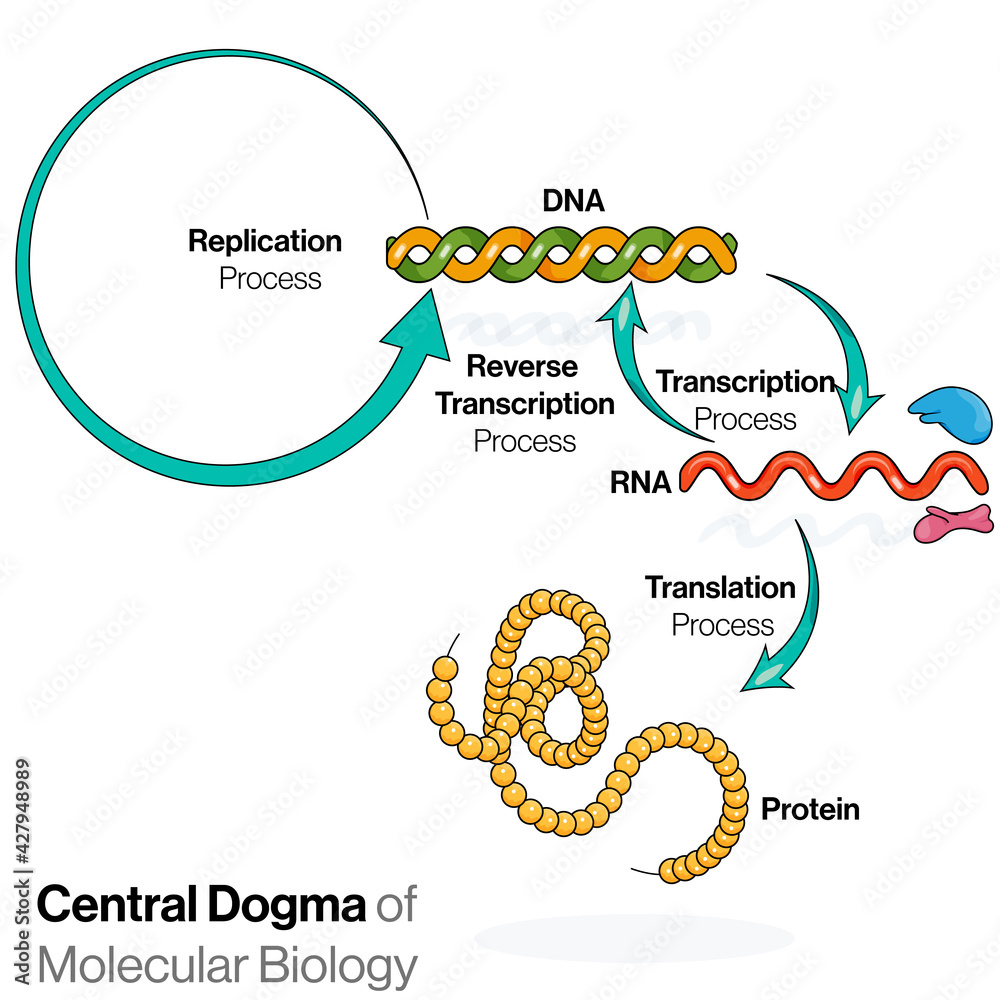
DNA RNA Protein Transcription converts DNA into RNA. Translation converts RNA into protein. That is it for the textbook version. But the actual behavior of cells does not follow a straight line.
The Practical Reality
Reverse transcription is real. RNA viruses carry RNA genomes and use reverse transcriptase to make DNA from that RNA. HIV is one example. Certain mobile genetic elements in your own genome, like LINE-1 retrotransposons, also do this. So the flow goes RNA back to DNA in those cases. Crick himself acknowledged this possibility within a year of proposing the dogma. He called it "special cases." Non-coding RNA is another exception that students often overlook. Some RNAs never become proteins. Transfer RNA, ribosomal RNA, microRNA, and long non-coding RNA all perform functions as RNA molecules. They are produced from DNA but they do not enter the translation step. This means a significant portion of the transcriptome operates outside the classic DNA RNA protein pipeline.
Get the Full Details
A Problem I Actually Had In The Lab
I was trying to amplify a gene region from genomic DNA using standard PCR. The primers were designed from the published sequence. The annealing temperature was correct. The polymerase was fresh. Nothing amplified. I ran the gel three times to rule out reagent failure. I remade the primer stocks. Same result. Zero product. The issue turned out to be that I was looking at a processed pseudogene. The sequence I wanted existed only as cDNA copies made from reverse-transcribed mRNA, not as an intact genomic locus. Standard PCR on genomic DNA would never work. I switched to using reverse transcriptase to make cDNA from total RNA, then ran the PCR on that template. The product appeared on the first attempt. It took me two weeks to figure that out. This is the kind of situation where knowing the central dogma helps. You have to ask whether the template you are working with has gone through transcription and reverse transcription steps that standard DNA extraction misses. If you only look at the DNA, you will miss the RNA-derived copies entirely.
Common Pitfalls
One thing beginners consistently get wrong is assuming that all RNA comes from the gene they are studying. In RNA-seq experiments, you will detect reads from pseudogenes, antisense transcripts, and overlapping genes. If you map those reads to a single gene model, your quantification will be inflated. You need to filter for uniquely mappable regions or use a transcript-level assembler. This is not a minor detail. It can shift your expression values by tens of percent depending on how much pseudogene overlap your target has. Another pitfall is ignoring RNA stability. mRNA half-lives vary enormously. Some transcripts last minutes. Others last hours. If you are doing qPCR and your reference gene degrades faster than your target, your normalization will be wrong. Check the stability of your housekeeping genes under your experimental conditions rather than assuming GAPDH or ACTB are always reliable. I have seen papers retracted because the reference gene was itself regulated by the treatment being tested. That is avoidable if you validate the reference first.
Where The Model Breaks Down Completely
Prioritization of RNA makes the standard model even less useful for some workflows. Eukaryotic cells process pre-mRNA by splicing out introns before export. The primary transcript is not the same molecule that gets translated. If you design primers that span an intron-exon boundary, you might amplify genomic DNA but not cDNA, or vice versa, depending on where the primers sit. This matters for clone construction and for diagnostic PCR. Always check whether your primers will discriminate between DNA and RNA templates if that distinction is important to your experiment. Prion-based inheritance is another edge case where information flows from protein structure without nucleic acids. Prions are misfolded proteins that induce other copies of the same protein to misfold. There is no DNA or RNA involved in transmitting that information. This does not overturn the central dogma for normal cellular function, but it shows the model is not universal.

What To Do Instead When The Standard Approach Fails
If you are working with a sequence that gives inconsistent PCR results, try these steps in order. First, check whether the target might be a pseudogene or reside in a repetitive region. BLAST your primers against the genome and look for multiple hits. Second, test both genomic DNA and cDNA templates. If you get product only from cDNA, the target is likely RNA-derived or the genomic copy is disrupted. Third, redesign primers in conserved exonic regions away from pseudogene homology. This usually resolves the issue within a day of work. For RNA work, always include a no-reverse-transcriptase control. Without it, you cannot tell whether your signal comes from RNA or contaminating DNA. This is basic practice but it is surprising how many protocols omit it. A single DNase treatment step during RNA isolation is usually sufficient to prevent false positives, but the control tells you definitively whether any remained. The central dogma is still the right framework for thinking about molecular biology. It is just not the whole framework. The exceptions are not rare in practice. They are the reason experiments fail when you least expect them to. Understanding both the rule and the exceptions is what separates someone who can run a protocol from someone who can troubleshoot it when the protocol does not work.