
Understanding Controls in Experimental Design
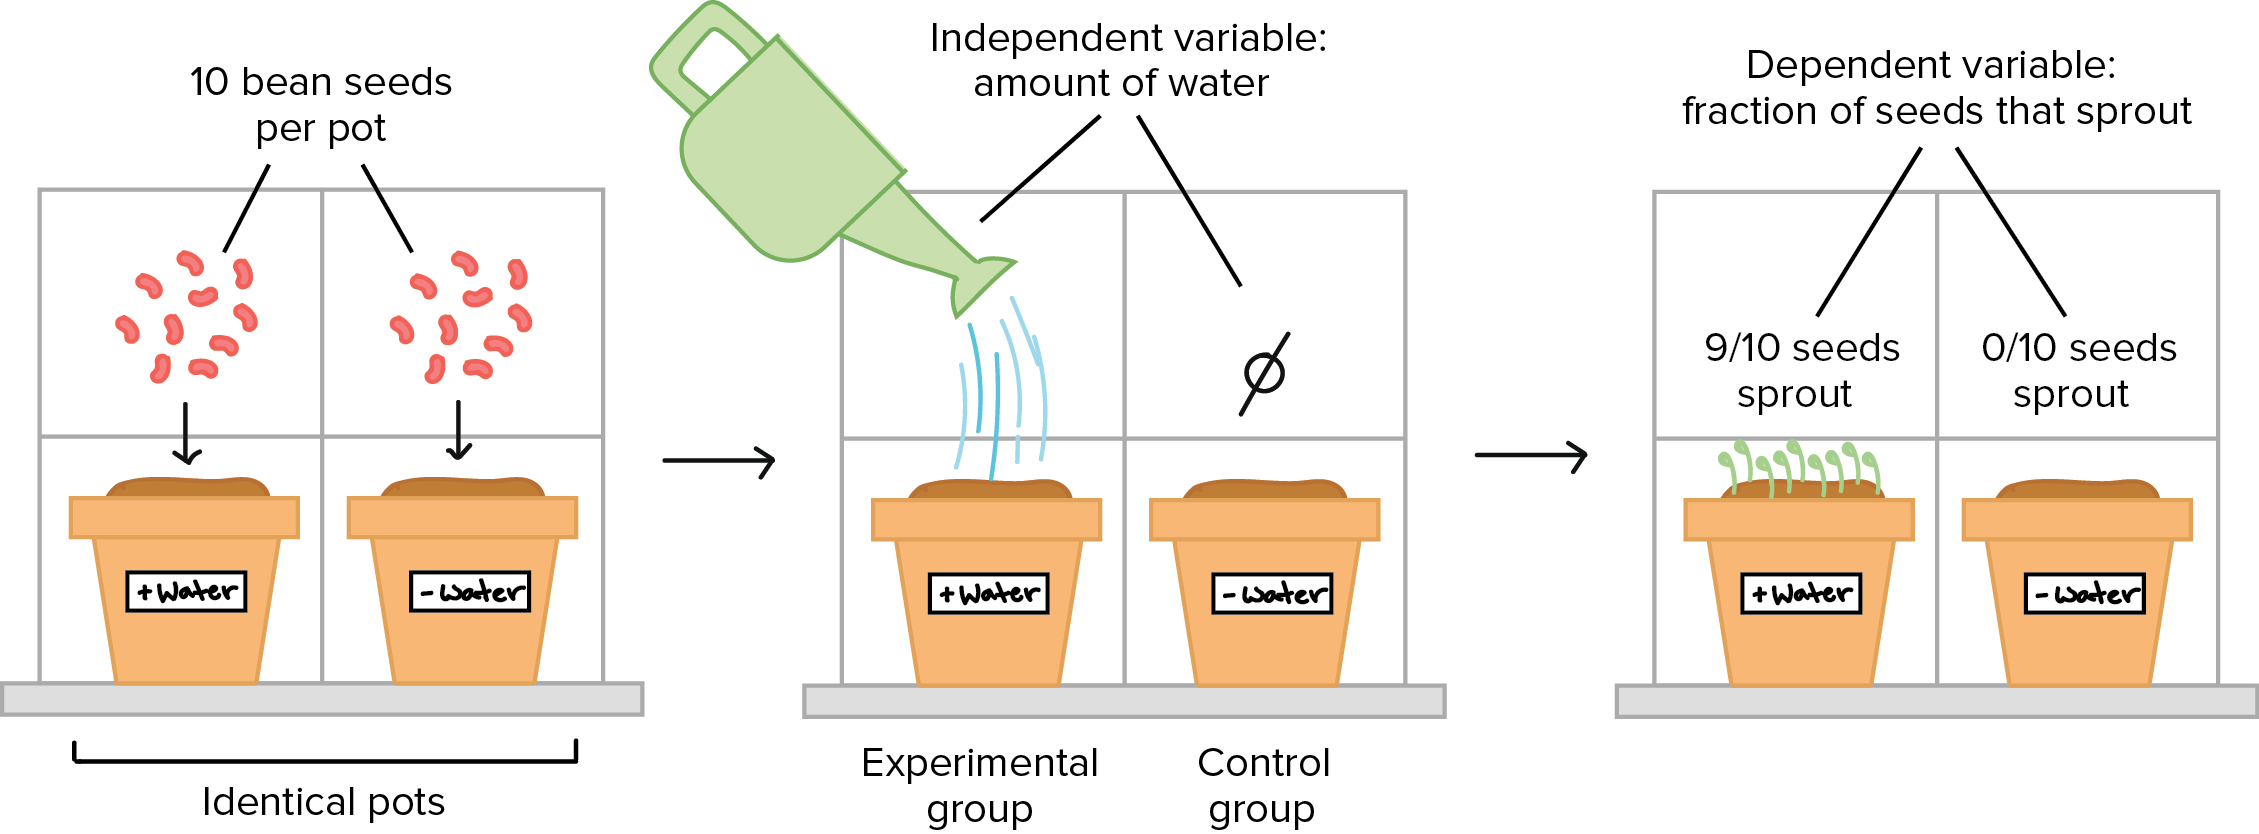
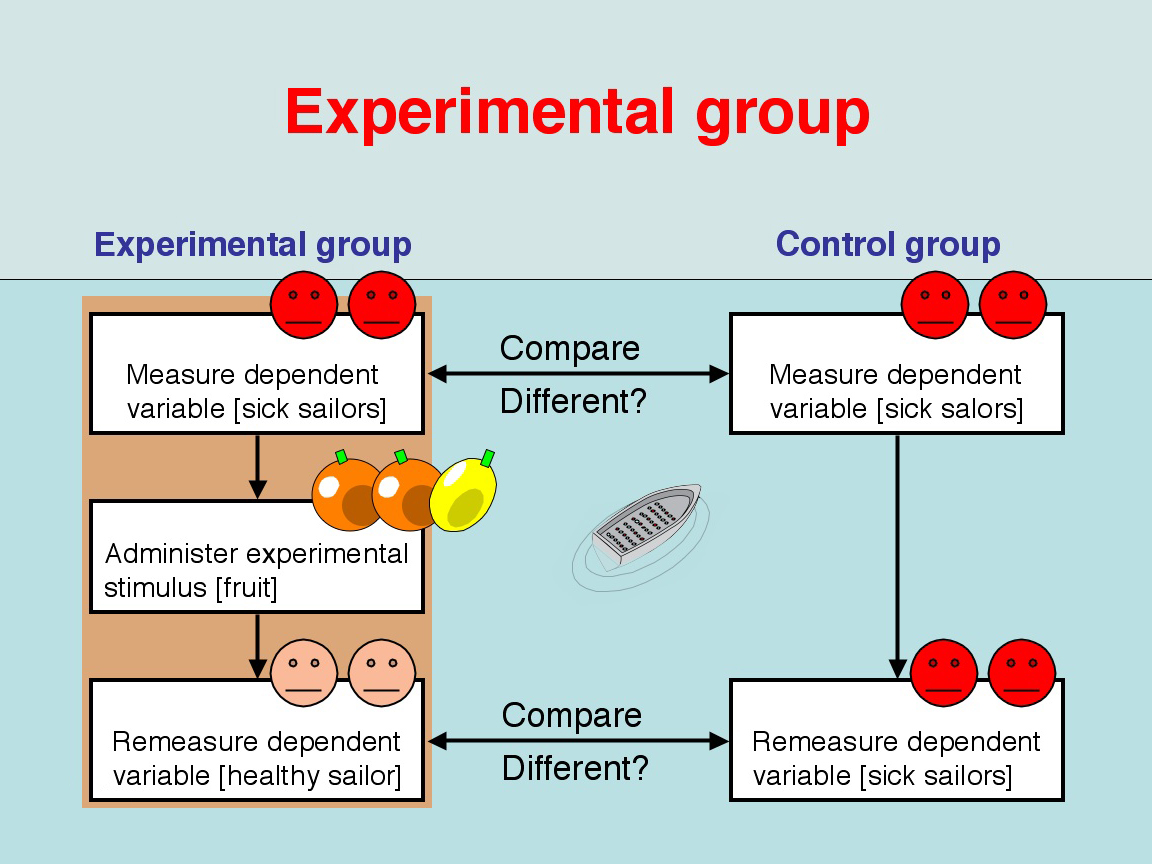
The control in an experiment is the baseline condition that everything else gets measured against. It's not a fancy term or a special setup—it's whatever you keep exactly the same while you change one variable to see what happens. Without a control, you're just collecting noise and pretending it means something. When someone asks what the control is in a given experiment, they're asking which group or condition serves as the reference point. Let me walk through how this actually works in practice rather than giving you a textbook definition. Take a basic plant growth study. You're testing whether a new fertilizer makes plants grow taller. Your experimental group gets the fertilizer. Your control group gets nothing—just water and the same soil, same light, same pot size. The control isn't failing to receive treatment because the researcher forgot; it's intentionally receiving no treatment so you can isolate the fertilizer's effect from every other variable in the system.
Here's where people mess this up constantly. I worked on a project testing a new coating formulation for industrial piping. We had three experimental batches with different additive percentages and a control batch with zero additives. Simple enough. But we used two different mixing drums for the control versus the experimental batches—one was older, had slight residue buildup from previous runs. The control showed marginally different viscosity readings even before we applied anything. Our experimental results were essentially useless because we couldn't tell whether differences came from the additives or from the drum contamination. We had to start over with a cleaned and validated single mixing system.
Common Types of Controls
Positive controls confirm your experimental setup can actually detect the effect you're looking for. If you're testing a drug that should lower blood pressure, you include a group treated with a known antihypertensive medication. If that group doesn't show reduced pressure, your entire assay is broken and you need to figure out why before trusting any results from your experimental treatment. Negative controls show what happens when absolutely nothing active is introduced. In molecular biology, this might mean running PCR without adding any template DNA. If you still get amplification bands on your gel, you've got contamination and your data is compromised. This is the most commonly skipped control and also the most important one for catching errors.
Get the Full Details
Placebo Controls and Their Complications
In clinical trials, the control group receives a placebo—an inert substance that looks identical to the actual treatment. The purpose is to separate the pharmacological effect from the psychological effect of receiving any treatment at all. Patients who believe they're getting medication often show improvement regardless of what they actually received. I once reviewed trial data where the placebo group showed a 40% improvement rate on the primary endpoint. That wasn't a fluke. It was a legitimate demonstration that the conditioning effect of treatment administration is substantial and must be accounted for. The experimental drug only showed a 52% improvement rate, which meant the actual pharmacological effect was modest—maybe 12 percentage points above placebo, not the 40% raw difference between groups that superficial readers would report.
Internal vs. External Controls
Internal controls are built into the experiment itself. External controls come from separate, parallel measurements. In a manufacturing process validation, you might run control samples alongside each production batch—that's an internal control. You might also periodically send samples to an independent laboratory for verification—that's an external control. Both serve different purposes and neither replaces the other. The problem with relying solely on external controls is timing. Independent lab results come back days or weeks later. By the time you see them, you've already produced hundreds of units that might be out of specification. Internal controls give you immediate feedback. The tradeoff is that internal controls can drift or develop systematic bias over time without anyone noticing. You need both systems working in parallel to catch different categories of error.
Sham Controls in Surgical and Device Studies
When testing a surgical procedure, you can't give patients a placebo pill. Instead, researchers sometimes use sham controls where the control group undergoes a simulated procedure—same anesthesia, same incisions, same positioning—without the actual therapeutic intervention. This is ethically contentious but sometimes necessary when the alternative is accepting results driven entirely by procedural expectations rather than physiological mechanisms. I evaluated a study comparing arthroscopic knee surgery to sham surgery for osteoarthritis. The sham procedure involved small skin incisions and instrumentation near the joint without entering the joint space itself. Results showed no statistically significant difference between the surgical and sham groups. The conclusion was that the structural intervention provided no additional benefit over the procedural ritual itself. This finding contradicted years of surgical practice and would have been missed entirely without the sham control.

Vehicle Controls Often Overlooked
When your treatment is delivered in a solvent, detergent, or carrier solution, you need a vehicle control that receives the same delivery medium without the active ingredient. I've seen papers where the experimental group got a compound dissolved in DMSO and the control group got nothing. Any observed effects could have been caused by the DMSO itself rather than the compound. The journal should have rejected it on those grounds, but peer reviewers missed it. This is particularly relevant in cell culture work where solvents can affect membrane permeability, protein expression, or cell viability at certain concentrations. A proper vehicle control uses the same concentration of solvent as the highest-dose experimental group, because the solvent effect might be dose-dependent too.
Historical Controls and Their Pitfalls
Sometimes you don't run a concurrent control group. Instead, you compare your experimental results against historical data from previous studies conducted under similar conditions. This is common in oncology drug development where randomizing patients to placebo is considered unethical when effective standard treatments exist. The fundamental problem with historical controls is that conditions are never truly identical across time periods. Patient populations shift. Diagnostic criteria change. Laboratory equipment degrades and gets recalibrated. Seasonal variations affect outcomes. I worked on a project where we compared our experimental results to published literature values from five years earlier. Our results looked dramatically worse, but when we re-ran a proper concurrent control using the same protocols, the difference disappeared. The historical data had been collected on older equipment with different calibration standards.
Blank Controls in Analytical Chemistry
A blank is a control containing everything except the analyte you're trying to measure. In spectrophotometry, this might be a cuvette with pure solvent instead of your sample. The blank establishes the zero point for your instrument. If your blank reads 0.02 absorbance when it should read zero, that's your background signal, and every sample reading needs to be adjusted by subtracting that baseline. Blanks can also reveal contamination in your reagents. I spent two weeks troubleshooting unexpected signals in a mass spectrometry assay before realizing the HPLC-grade acetonitrile I was using contained trace impurities that co-eluted with my analyte. Switching to a different supplier's batch resolved the issue completely. A properly run blank would have caught this on day one instead of wasting two weeks.

Calibration Controls in Quantitative Work
Calibration controls are reference samples with known concentrations used to establish the relationship between instrument response and the quantity being measured. They're typically run at the beginning and end of each batch, and sometimes at regular intervals throughout. Quality control samples with predetermined target values are interspersed to verify the instrument stayed within acceptable performance parameters during the run. Instrument drift is the most common failure mode. Temperature fluctuations, lamp aging, column degradation, and electronic noise all cause calibration curves to shift over time. A control that started within acceptable limits at the beginning of a run might fall outside them by the end. This is why controls need to be run throughout, not just at the start. Running controls only at the beginning and then assuming the instrument remained stable is one of the most preventable sources of bad data I encounter.
Replicate Controls and Variability Estimation
Controls aren't useful if you only run them once. You need replicate controls to estimate the natural variability in your system. A single control measurement tells you nothing about whether a difference between your control and experimental groups is real or just random fluctuation. Three replicates minimum. Five or more if your method has high inherent variability. I reviewed an assay validation where someone ran control samples in triplicate but the coefficient of variation between replicates was 18%. That's unacceptably high for a quantitative method, yet the validation report presented the mean values without mentioning the variability. The conclusion that the method was "accurate and precise" was completely unsupported by the actual data.
System Suitability Controls in Regulatory Contexts
In regulated environments like pharmaceutical testing, system suitability controls verify that the entire analytical system—instrument, reagents, operator, method—performs adequately before any sample results are accepted. These controls typically include checks for resolution, tailing factors, plate count, and reproducibility of standard injections. If system suitability fails, the entire batch of sample results is invalidated regardless of whether any individual sample result looks reasonable. This is a hard rule in most pharmacopeial methods. I've seen laboratories try to proceed with sample analysis after a failed system suitability check by adjusting the results manually. That's not just poor science—it's a compliance violation that regulatory agencies take seriously during inspections.

Choosing the Right Control for Your Situation
The control you need depends entirely on what question you're trying to answer. If you want to know whether a treatment causes an effect, you need a concurrent negative control that matches everything about the experimental condition except the treatment itself. If you want to know whether your detection method works, you need a positive control that definitely produces the expected signal. If you want to know whether your solvent is interfering, you need a vehicle control. Multiple questions require multiple controls, and there's no shortcut around that. Adding controls takes time and resources. More controls mean more samples, more preparations, more runs, more data to manage and analyze. In resource-constrained settings, researchers sometimes skip controls to save money or meet deadlines. This is almost always a false economy. The cost of discovering that your experiment lacked proper controls after you've invested weeks of work is far greater than the cost of including them from the start.
Control Collapse and Confounding
A control can fail silently if it becomes indistinguishable from your experimental condition—that's control collapse. If your negative control group accidentally receives the active treatment due to a labeling error or cross-contamination, you won't know it happened unless you've also run system suitability checks and documentation trails that verify every sample went where it was supposed to go. Confounding occurs when your control group differs from your experimental group in ways unrelated to your treatment variable. Age, sex, genetic background, environmental conditions, and timing all can introduce confounding if they're distributed unevenly between groups. Randomization helps, but it doesn't eliminate the problem entirely, especially with small sample sizes where chance imbalances are more likely. Blocking—grouping subjects by a known source of variability before randomizing within blocks—is a practical workaround when you know what variables might confound your results ahead of time.
Documentation and Traceability
Every control needs clear documentation. What is it? What does it contain? What outcome does it produce under normal conditions? What range of outcomes is acceptable? When was it last verified? Who performed the verification? This documentation should be available before the experiment starts, not reconstructed afterward when someone asks why your results look suspicious. In my experience, the quality of a laboratory's control documentation correlates strongly with the reliability of its published results. Labs that maintain detailed control logs, version-controlled protocols, and audit trails consistently produce data that holds up under scrutiny. Labs that treat controls as optional or document them retroactively tend to have problems that surface during peer review, regulatory inspection, or reproducibility attempts.
When Controls Suggest Something Is Wrong
A well-designed experiment should produce predictable control outcomes. When controls behave unexpectedly, that's not a data point to discard—it's information. A positive control that fails to produce its expected effect means your assay conditions are wrong. A negative control that shows signal means your system has contamination or carryover. A vehicle control that differs from your untreated control means your delivery method is affecting your outcome independently of the treatment. I once encountered a situation where the positive control in a cell viability assay showed only 60% of the expected signal. Rather than ignoring it and proceeding with the experimental groups, we stopped and investigated. We found that the serum batch in our cell culture medium had been compromised—proteins had denatured during storage. Using fresh serum restored the positive control to 95% of expected values and revealed that several of our experimental treatments had appeared cytotoxic when they actually weren't. The compromised serum had lowered the overall health of the cells, making everything look worse than it was. Controls exist to tell you when your experiment is lying to you. Pay attention to them.
