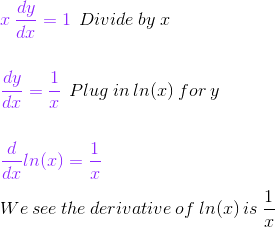
The quick answer
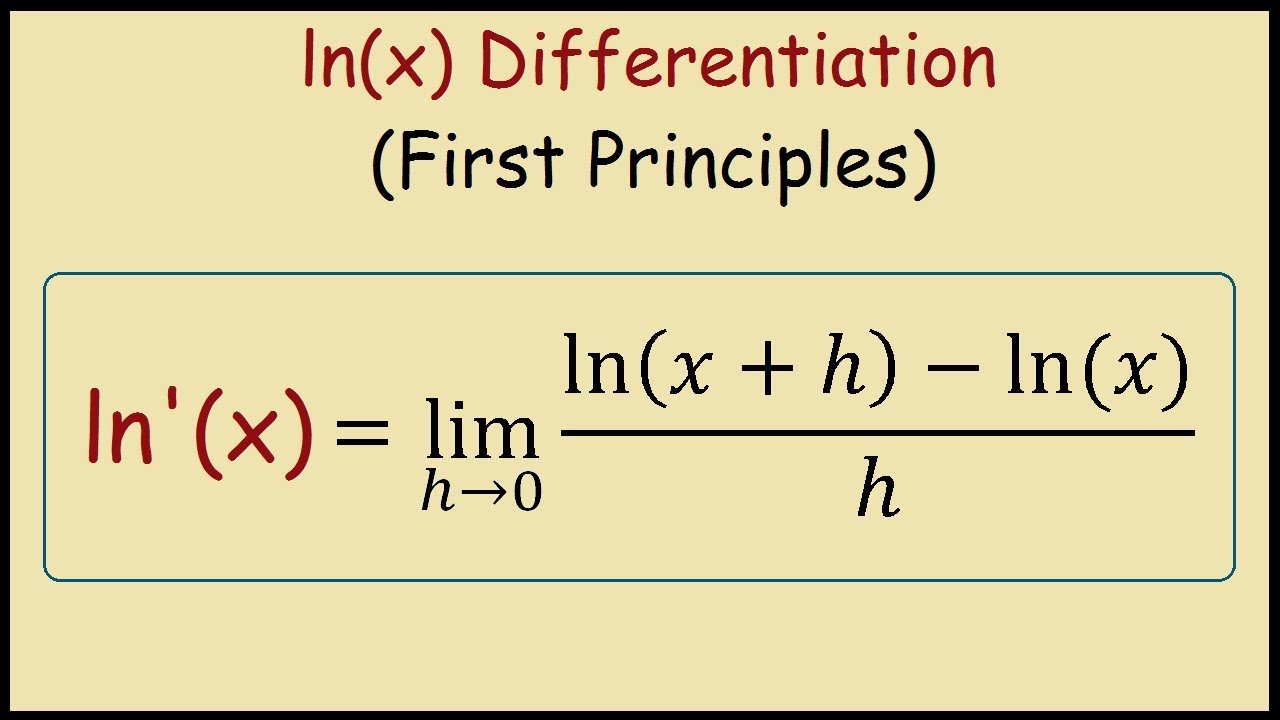
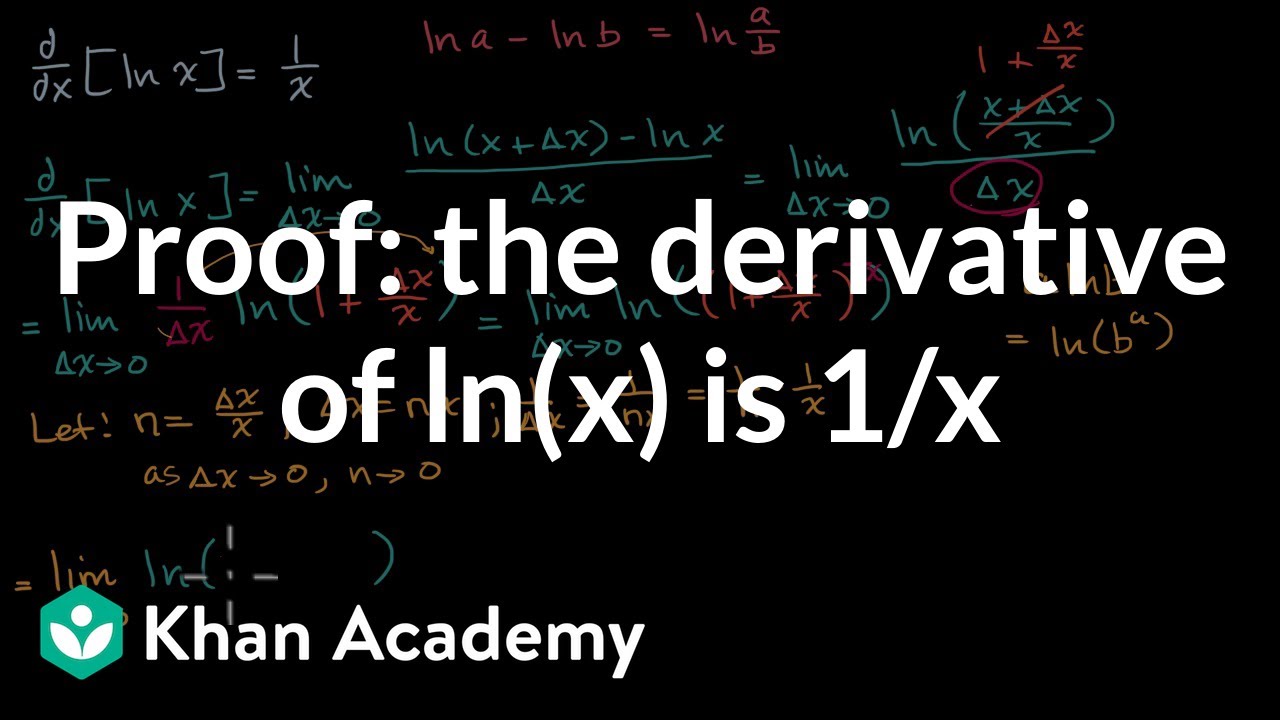
The derivative of ln x is 1/x. That is it. If you have been grinding through calculus homework for three hours and your brain is fried, that is the entire takeaway. Now let us get into why that matters in practice. The derivative of ln x with respect to x is 1/x, defined for x greater than zero. In Leibniz notation: d/dx [ln x] = 1/x. In Lagrange notation: (ln x)' = 1/x. Different notations, same result. The proof comes from the definition of the natural logarithm. If y = ln x, then x = e^y. Taking the derivative of both sides implicitly gives dx/dy = e^y = x. Then by the reciprocal rule, dy/dx = 1/x. This is standard single-variable calculus. Nothing mysterious about it once you stop treating it like magic.
How to actually use this outside homework
The raw result is simple, but most people encounter it in a chain rule context, and that is where things get sloppy. If your function is ln of something complicated, you do not just write 1 over the argument and call it a day. You multiply by the derivative of the inside function. This is the chain rule version, and it is what shows up everywhere in real work. For instance, if you have f(x) = ln(3x^2 + 2x), then f'(x) = (6x + 2) / (3x^2 + 2x). You take the derivative of the inside, which is 6x + 2, and divide by the inside expression itself. That is the pattern. Every time. I spent a few years doing numerical modeling work, and I ran into a situation where I was computing partial derivatives for a log-likelihood function. The objective function contained terms like ln(f(x, y)) where both x and y were variables feeding into a coupled system. A junior analyst on my team kept dropping the chain rule factor and treating each term as if it were just 1 over the argument. It threw off the Newton-Raphson iterations in a way that was hard to spot because the residuals looked plausible at first glance. The fix was straightforward: every ln term needed the full Jacobian applied to its argument, and I had the team switch to symbolic differentiation via a small Python script using SymPy before running any numerical solver. That single change cut debugging time from roughly two days to about an afternoon.
Common pitfalls that beginners miss
The domain issue is the first thing people skip. ln x is only defined for positive real numbers, and its derivative 1/x shares that restriction. You cannot evaluate the derivative at x = 0 or for negative x without leaving the reals. This seems obvious until you are working with a model and someone plugs in a boundary value of zero, and the solver blows up. The derivative goes to infinity there, and numerical methods around x = 0 are unstable unless you handle it explicitly. Another thing: people often confuse ln(x^2) with 2 ln x. They are equivalent when x is positive, but not when x is negative. The derivative of ln(x^2) is 2/x everywhere except zero, while 2 ln x is undefined for negative x. Using the simplified form 2 ln x without checking the domain can silently introduce errors in optimization routines that operate over the full real line. There is also the absolute value variant. Some textbooks write the antiderivative of 1/x as ln|x| + C. The derivative relationship works cleanly in the positive domain, but if you are working with expressions that cross zero, the absolute value matters for the integral side, even though the derivative of ln x itself stays 1/x on its domain.
Get the Full Details
When this approach breaks down
The 1/x result assumes you are working with the standard real-valued natural logarithm. If you move into complex analysis, ln z becomes multi-valued and you have to pick a branch cut, usually along the negative real axis. The derivative is still 1/z within a chosen branch, but discontinuities appear at the cut, and numerical routines that ignore branch cuts will produce garbage results near the negative real line. I have seen this bite people working on signal processing pipelines where the logarithm is applied to a complex spectrum. If your implementation does not handle the branch properly, gradients near the cut direction are wrong, and downstream filtering steps inherit the error. Another practical limitation: computing 1/x numerically for very small x causes overflow or loss of precision depending on your floating point format. If you are writing code that evaluates the derivative repeatedly near zero, consider working in a transformed space or using arbitrary precision libraries. It adds overhead, but it prevents silent underflow.
Worked examples
Example one: f(x) = ln(5x). Using the chain rule, the derivative of the inside is 5, so f'(x) = 5/(5x) = 1/x. The constant inside the log cancels out, which is why some people remember that the derivative of ln(cx) is the same as the derivative of ln x. It is not a coincidence. Example two: g(x) = ln(sin x). The inside derivative is cos x, so g'(x) = cos x / sin x = cot x. This one shows up in integration problems frequently, and recognizing the result as cotangent saves time compared to leaving it as a fraction. Example three: h(x) = ln(x^2 + 1). The inside derivative is 2x, so h'(x) = 2x / (x^2 + 1). This form appears in gradient-based optimization of loss functions involving Gaussian-like terms, and the denominator never hits zero, which makes it numerically stable across the real line.
Why this result matters beyond the calculus class
The derivative 1/x shows up in maximum likelihood estimation whenever the log-likelihood contains linear log terms. It is also fundamental to entropy calculations in information theory, where the natural log is the standard base. In engineering, log-compressed signal representations use this derivative when computing sensitivity or error propagation through the log transform. It is a basic building block more than it is an isolated fact. If you want a reference for verification, any standard calculus textbook covers this in the section on exponential and logarithmic derivatives. The Wikipedia page for the natural logarithm also has the derivative derivation, though it skips the domain subtleties that matter in implementation.