Breaking Down Vector Multiplication Without the Fluff
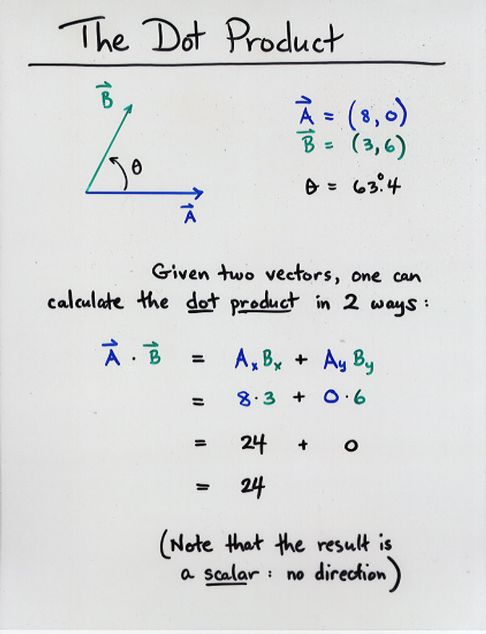
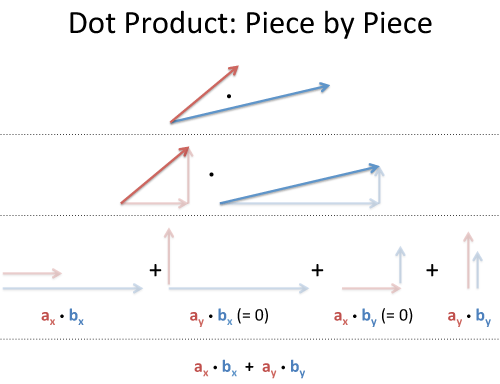
The dot product is one of those operations you see everywhere in machine learning, physics, and computer graphics, but most people learn it as a dry formula and never actually understand what it does or when it falls apart. Here is what it is, how to compute it, and a few things that usually trip people up in practice. It is a way to multiply two vectors together and produce a single scalar value. If you have vector a with components (a1, a2, a3) and vector b with components (b1, b2, b3), the dot product is a1*b1 + a2*b2 + a3*b3. That is the calculation. You multiply corresponding elements and sum them up. The geometric interpretation is a*b*cos(theta), where a and b are the magnitudes of the vectors and theta is the angle between them. This second form is more useful conceptually. When theta is zero, the result is the product of the magnitudes. When theta is 90 degrees, the result is zero. When theta is 180 degrees, the result is negative. Everything in between maps linearly to the cosine curve.
I remember working on a reinforcement learning project where I needed to measure directional similarity between policy gradient vectors across network layers. I was comparing gradients from layer three against layer six to check whether updates were pushing in conflicting directions. The dot product gave me an immediate read on that, and it saved me from running a full covariance analysis that would have taken significantly longer to implement and debug. Here is the method in practice. Take two vectors of equal length. Multiply each pair of matching elements. Add all those products together. Done. For example, vector u = (2, -1, 3) and vector v = (4, 5, -2). The dot product is (2*4) + (-1*5) + (3*-2) = 8 - 5 - 6 = -3. Negative result tells you the angle between them is greater than 90 degrees. The vectors are pointing generally away from each other.
Where It Gets Useful and Where It Breaks Down
One thing beginners consistently miss is that the dot product measures alignment, not magnitude of individual components. Two vectors can have wildly different lengths but still produce a high dot product if they point in the same direction. Conversely, two unit vectors pointing at 89 degrees will produce a near-zero dot product even though both vectors are technically in the same hemisphere. Context matters a lot here. In practice, I use the dot product for projection calculations constantly. If you want to project vector a onto vector b, you take the dot product of a and b, divide by the squared magnitude of b, and multiply that scalar by vector b. That gives you the component of a that runs parallel to b. This comes up in collision detection, lighting calculations, and force decomposition. Another counter-intuitive point: the dot product assumes your vectors are in the same coordinate space. I ran into a problem once where I was computing dot products between feature vectors extracted from two different preprocessing pipelines. One was normalized to unit length, the other was L2-normalized but then shifted by a mean subtraction step. The results looked reasonable at first glance, but the mean shift meant the angles were systematically biased, and my similarity rankings were off by a measurable margin. I fixed it by re-normalizing both sets after mean centering, but it cost me half a day of debugging.
Get the Full Details

The dot product also has real limitations. It only works when vectors have the same dimensionality. If you are working with sparse high-dimensional data like word embeddings in a 10,000-dimensional space, most of those dimensions will be zero anyway, which means you are effectively multiplying zeros together most of the time. In those cases, the dot product can still work, but it becomes sensitive to the sparsity pattern rather than the actual signal. Cosine similarity is often a better choice for sparse data because it normalizes out the magnitude issue and focuses purely on angular similarity. Another edge case: the dot product is not robust to outliers. A single large component in one vector can dominate the result and drown out the contributions from all the other components. I had a neural network training run where one weight vector had a few extreme values due to an initialization bug, and the dot products between that vector and every other vector in the batch were misleadingly high. The fix was straightforward—clip the outlier values before computing—but catching the issue took longer than it should have because the symptom looked like normal convergence behavior at first. If you need to multiply matrices rather than vectors, that is matrix multiplication, which is different. The dot product is specifically for vectors producing scalars. Confusing the two is a common early mistake, and it usually shows up when people try to implement these operations from scratch without understanding the shape constraints.
Quick Reference for Implementation
In Python using NumPy, you can compute it with numpy.dot(a, b) or the @ operator as a @ b. Both give identical results. For large-scale work, the @ operator is slightly cleaner to read and marginally faster in recent NumPy versions due to optimized dispatch paths. If you are working in JavaScript without a library, just write a simple loop. Multiply corresponding elements and accumulate the sum. It takes about five lines of code and runs fast enough for most applications outside of GPU-bound workloads. For C or C++ developers, std::inner_product from the standard library handles this directly. It accepts iterators, so it works with arrays, vectors, and custom containers without modification.
The dot product is a fundamental tool, not a magic bullet. It gives you a quick measure of directional alignment and projection, but it ignores scale differences in ways that can mislead you if you are not paying attention. Know what you are actually measuring before you apply it to your problem.