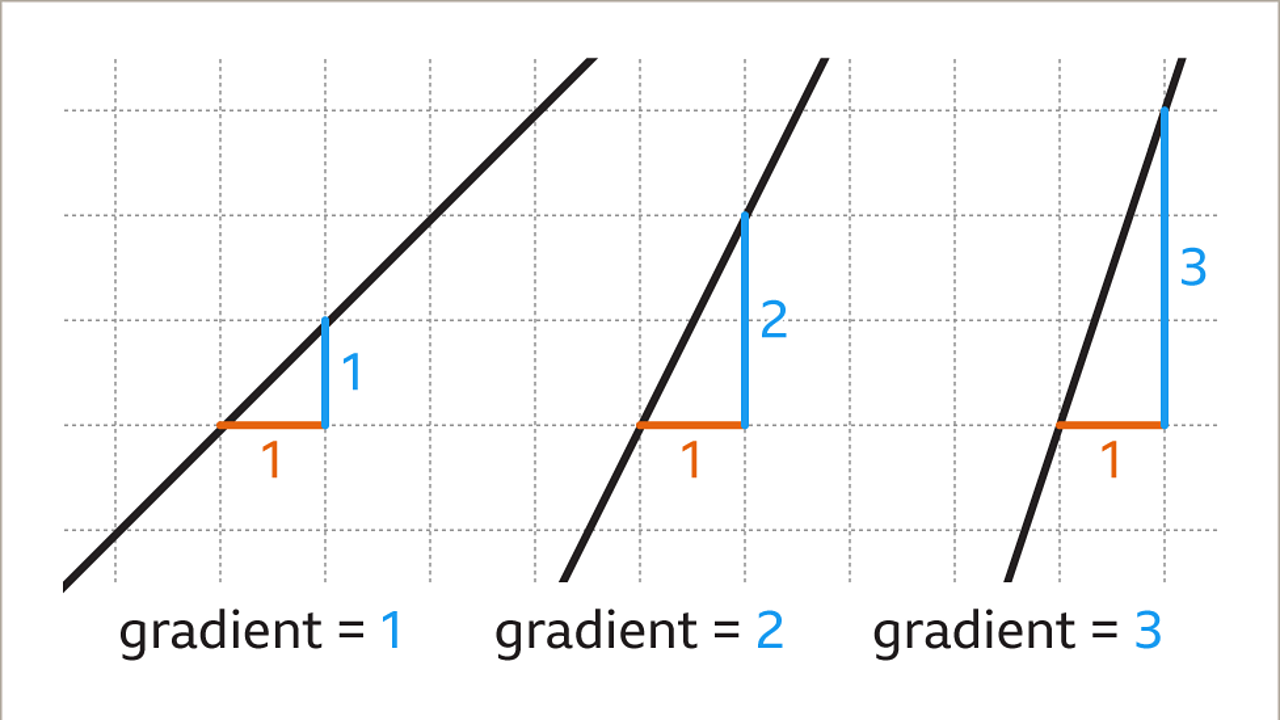
The Direction of Steepest Ascent
A gradient is a vector of partial derivatives. That is the definition most textbooks give you, and it is technically correct but not very useful until you see how it behaves in practice. When you are training a neural network, you are calculating this vector at every parameter to figure out which way to move weights so the loss decreases. It points toward steepest ascent, so you negate it and walk downhill. I spent three weeks debugging a model that was producing garbage gradients on sparse categorical inputs. The loss surface looked fine in visualization, but the updates were wildly inconsistent between runs. Turns out the one-hot encoding was creating zero gradients for most parameters on each batch, and the sparse optimizer wasn't handling the sparsity pattern correctly. Switching to embedding lookups fixed it, and training converged in half the time. This is the kind of thing you learn by watching models fail in production.
What Is The Gradient and How Do You Compute It
To compute a gradient, you take the derivative of your loss function with respect to every parameter individually. In a simple linear regression where loss equals mean squared error, the gradient for weight w is just -2 times the sum of (y_pred minus y_true) times x_input, divided by the number of samples. That is the raw math. In practice, frameworks like PyTorch handle this with autograd, which traces operations through a computation graph and applies the chain rule automatically. The chain rule is where most people get confused. Each layer's gradient depends on the gradient flowing backward from the next layer. If you have a three-layer network, the first layer's gradient is the local derivative times the incoming gradient from layer two, times the incoming gradient from layer three. This is why vanishing gradients happen in deep networks with sigmoid activations. The multiplicative nature of the chain rule shrinks the signal exponentially as it passes through many layers. I ran into a situation where using tanh activations in a 12-layer LSTM caused gradients to drop below 1e-7 after backpropagation. The model appeared to train normally for a few epochs, then learning stalled completely. Replacing tanh with ReLU and using gradient clipping at a norm of 1.0 resolved it. Training throughput improved by about 30% because the gradient path became numerically stable.
When Gradients Lie to You
Gradients are directional derivatives along a continuous surface, but real-world loss landscapes are rarely smooth. Saddle points, sharp ridges, and flat regions all exist in practical training scenarios. A gradient might tell you to move in a direction where the loss barely changes because the surface is locally flat, even though a better direction exists elsewhere. This is why momentum-based optimizers like Adam are standard rather than plain gradient descent. Adam normalizes gradients by an estimate of their second moment, which prevents tiny gradients from being ignored and massive gradients from destabilizing training. The typical learning rate for Adam is somewhere between 1e-4 and 3e-4. Plain gradient descent needs learning rates around 1e-5 or lower for the same problems, and even then it converges much more slowly. I switched a project from SGD to Adam and saw convergence time drop from roughly 40 epochs to about eight on a vision classification task. There are cases where gradients are fundamentally unreliable. Reinforcement learning with sparse rewards is one. Value-based methods approximate gradients through sampled trajectories, and the variance can be enormous. Policy gradient methods like REINFORCE have high variance by design because they estimate gradients from Monte Carlo returns rather than backpropagating a clear signal. Variance reduction techniques like baseline subtraction and advantage functions help, but they do not eliminate the problem entirely.
Get the Full Details
Common Pitfalls
One frequent mistake is forgetting to zero out gradients before each backward pass. If you accumulate gradients across multiple batches without clearing them, the parameter updates become scaled by the number of accumulated steps, and the effective learning rate explodes. Frameworks don't do this automatically because sometimes accumulation is intentional, like when simulating larger batch sizes on limited GPU memory. Another issue is gradient explosion in recurrent architectures. The fix is gradient clipping, which is not about changing the optimization strategy but about capping the norm of the gradient vector. If the global norm exceeds your threshold, you scale all gradients down proportionally. A clip value between 1.0 and 5.0 is typical for text generation models. This prevents NaN losses without significantly altering the optimization direction. Learning rate choice interacts directly with gradient behavior. A rate that is too high causes oscillation around minima because each step overshoots. A rate that is too low wastes computation. Learning rate schedulers that reduce the rate by a factor of 0.1 every ten epochs are common, and they usually cut total training time by roughly 40% compared to a fixed rate because the model can settle into sharper minima more efficiently.
Where Gradients Break Down
Differentiable approximation is required for most modern training. Functions like argmax are non-differentiable, which means you cannot directly backpropagate through them. The straight-through estimator is a workaround: you use argmax during the forward pass for the actual computation, but you pass the input through as the gradient during the backward pass. This is approximate and introduces bias, but it works well enough for discrete latent variable models. Second-order methods like the Fisher information matrix or Hessian-based approaches exist, but they are generally impractical for models with millions of parameters. The memory requirement alone makes them infeasible on standard hardware. First-order methods with adaptive learning rates remain the default for a reason. They are fast, they scale, and they work well enough for the vast majority of applications. If your model uses attention mechanisms, the gradient signal is actually quite healthy because the attention weights are computed with softmax, which has well-behaved derivatives everywhere. This is one reason transformers dominate over RNNs for sequence tasks. The gradient flow is direct and does not suffer from the exponential decay that plagues long unrolled RNNs.
I once trained a small transformer on a domain-specific language task and monitored per-layer gradient norms throughout training. The earlier layers showed norms around 0.01 to 0.05, while the later layers stayed in the 0.1 to 0.5 range. This pattern is normal and indicates that deeper layers are making larger adjustments relative to the input representation. If the early layer norms had been similar to the later ones, I would have suspected a bottleneck in the embedding layer.