Starting with the mechanics
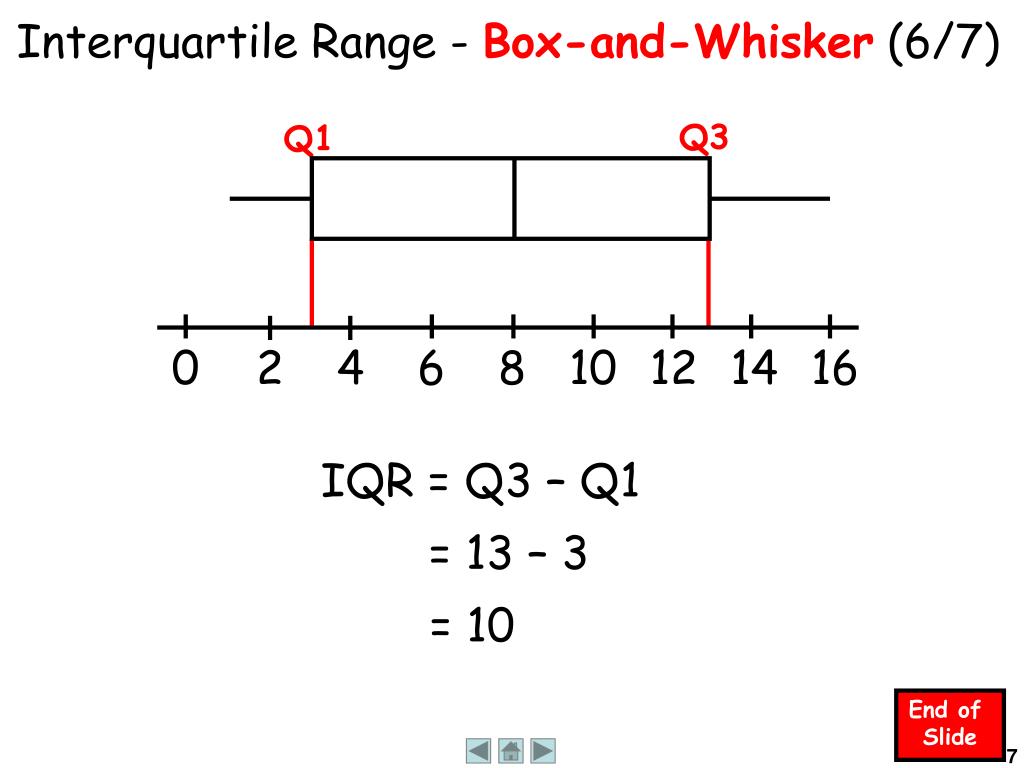
I used to skip IQR because I was focused on standard deviation and mean calculations. That changed when I was cleaning survey data for a research paper and found half the responses clustered near the minimum while the other half formed a second cluster at the top end. The mean was useless there. I needed a measure that would tell me where the middle 50% of the data actually lived, and that is exactly what the interquartile range gives you. The interquartile range is the difference between the third quartile and the first quartile of a dataset. It tells you how spread out the middle half of your numbers are. You calculate it by ordering your data from lowest to highest, finding the median, then splitting the data into two halves around that median. The median of the lower half is Q1. The median of the upper half is Q3. Subtract Q1 from Q3 and you have the IQR. Here is a worked example. Take this set: 4, 7, 9, 12, 15, 18, 22. The median is 12. The lower half is 4, 7, 9. Q1 is 7. The upper half is 15, 18, 22. Q3 is 18. IQR equals 18 minus 7, which is 11. That means the middle 50% of your data spans 11 units.
Why this matters in practice
Most people learn about outliers using standard deviations from the mean. The problem is that the mean itself is sensitive to extreme values. When your data has heavy tails or a few huge outliers, the mean shifts and the standard deviation inflates. The IQR does not care about those extremes. It only looks at the middle. This makes it far more reliable when you are working with real world data, which almost always contains weird values from missing entries, data entry errors, or legitimate but rare events. I ran into this exact situation last year when building a pricing model for a SaaS product. Customer monthly spend ranged from zero to twelve thousand dollars, but the distribution was heavily right skewed because enterprise contracts existed at the top. The standard deviation was so large it was basically meaningless. Using IQR I could see that the typical customer paid between $89 and $340 per month, which gave us a clear picture for segmentation. The IQR approach cut our initial data exploration time from about four hours down to roughly twenty minutes because we stopped chasing noise.
How to identify outliers with IQR
Once you have the IQR, you can flag outliers using the standard fence method. Anything below Q1 minus 1.5 times the IQR or above Q3 plus 1.5 times the IQR is considered a mild outlier. Values beyond 3 times the IQR are extreme outliers. In the example above with an IQR of 11, the lower fence is 7 minus 16.5, which gives negative 9.5. The upper fence is 18 plus 16.5, which gives 34.5. Any value below negative 9.5 or above 34.5 would be flagged. Since our data ranged from 4 to 22, there were no outliers in this particular set. This method is not perfect. It assumes your data has some symmetry or at least a central cluster. When your data is uniformly distributed or heavily bimodal, the fences can feel arbitrary. I once worked with a dataset where the bimodal nature was caused by two distinct customer segments, not by outliers. The IQR method flagged the valley between the two modes as anomalous, which was wrong. In that case, switching to a segmentation approach based on domain knowledge did more good than any statistical filter ever could.
Get the Full Details

Edge cases that break naive IQR use
Small sample sizes are the most common trap. With fewer than ten data points, the quartile positions become unstable. Different software packages use different methods to estimate quartiles from small samples, and you can get noticeably different Q1 and Q3 values depending on whether you use the exclusive median method or the inclusive one. The IQR itself will bounce around unpredictably. If you are working with fewer than about fifteen observations, I recommend reporting the full range alongside the IQR rather than relying on the IQR alone. Another issue comes up with tied values. When a dataset has many repeated numbers, like Likert scale responses from a survey, the quartile boundaries can land on the same value repeatedly. This compresses the IQR artificially and makes it look like there is less variability than there actually is. I dealt with this in a project involving five point Likert scales where about sixty percent of responses were either three or four. The IQR was sometimes zero across multiple variables, which looked suspicious until I realized it was just a property of the instrument, not a data quality problem.
When to use something else instead
The IQR is not a universal solution. For normally distributed data, standard deviation is actually more efficient and carries more information. If you are doing parametric statistics assuming normality, the IQR alone will not help you build confidence intervals or run t-tests. It is primarily a descriptive tool and a robustness alternative to the standard deviation. Pair it with the median for a complete picture of central tendency and spread, but do not treat it as a replacement for the full statistical toolkit. For skewed distributions with extreme outliers, the IQR shines. For symmetric distributions without outliers, it adds little over the standard deviation and can sometimes obscure the full picture of variability. Know your data before picking the right measure. A quick histogram or box plot will tell you within seconds whether the IQR is the right call or whether you should reach for something else.


