Understanding IQR in Practice
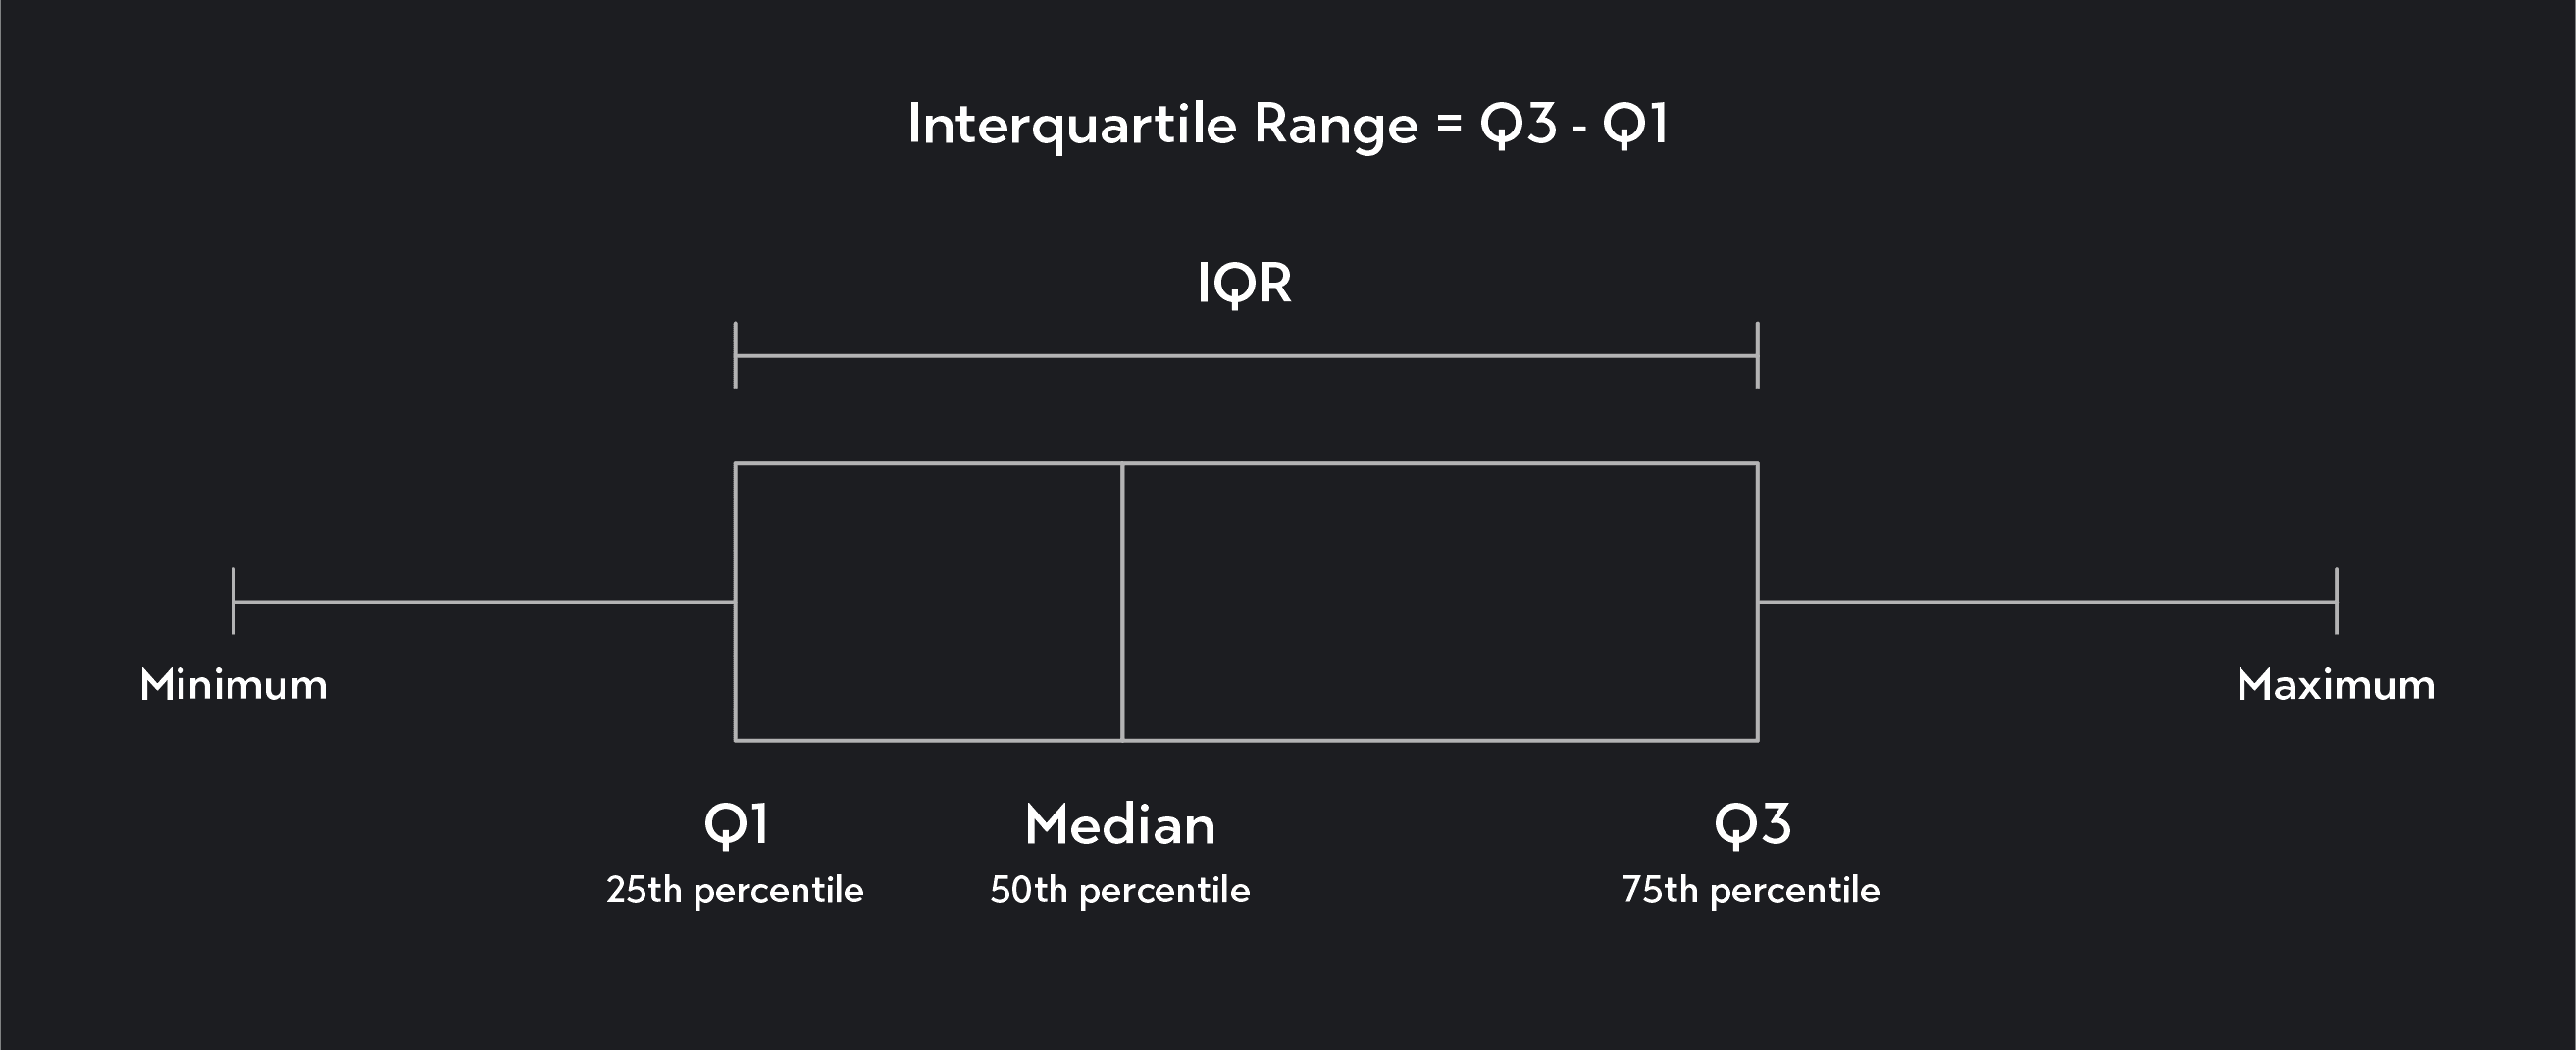
The interquartile range is simply the difference between the 75th percentile and the 25th percentile of a dataset. It measures the spread of the middle 50% of your data. That is all there is to the definition. To calculate it manually, sort your data from smallest to largest. Find the median, which splits the data in half. Then find the median of the lower half — that is Q1. Find the median of the upper half — that is Q3. Subtract Q1 from Q3. The result is your IQR. In practice, nobody does this by hand unless they are teaching it. I use Python's numpy.percentile function or R's quantile function. The key thing most people miss is that different software packages use different interpolation methods to calculate quartiles. Excel's old QUARTILE function and its newer QUARTILE.EXC function produce different results for the same dataset. This matters more than you would think when you are comparing results across tools or reproducing someone else's analysis.
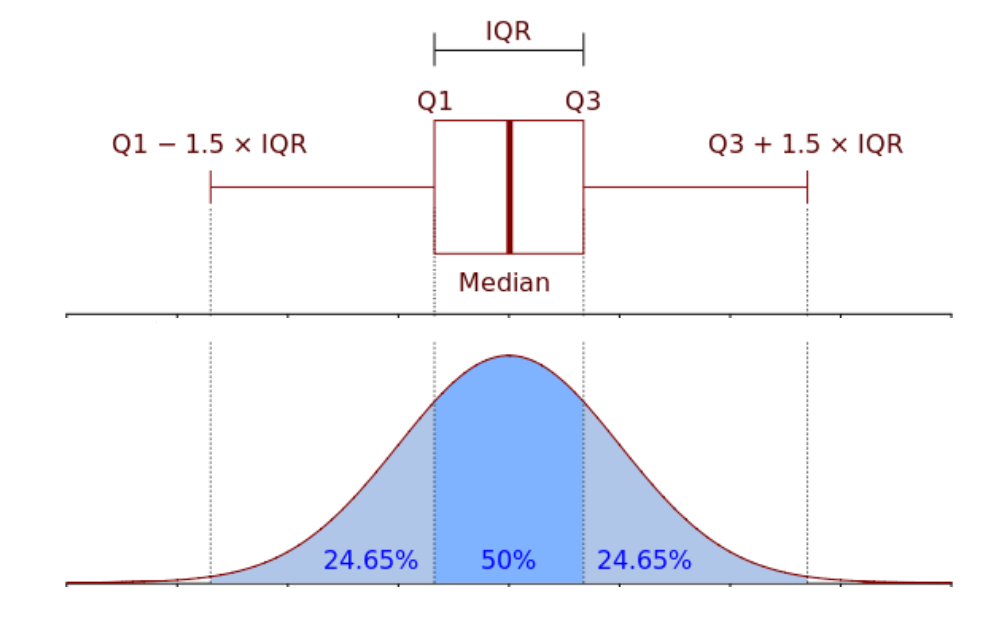
Here is a concrete example. Say you have these values: 3, 5, 7, 8, 9, 12, 15, 18, 20, 22, 25. The median is 12. Q1 comes out to 7 and Q3 to 20. The IQR is 13. Anything below 7 minus 1.5 times 13, which is -12.5, or above 20 plus 19.5, which is 39.5, would be flagged as an outlier using the standard Tukey fence method. I ran into a real problem with IQR a while back when cleaning a dataset of customer transaction amounts. The data was heavily right-skewed because a small number of high-value purchases existed alongside thousands of small ones. I applied the standard 1.5 times IQR rule and ended up flagging about 12% of what were clearly legitimate transactions as outliers. The IQR method assumes a roughly symmetric distribution around the quartiles, and this data violated that assumption badly. The workaround was straightforward — I logged-transformed the values first, calculated the IQR fences on the transformed scale, then mapped the results back. The false positive rate dropped to under 2%. There are two things beginners consistently get wrong about IQR. First, they treat it as a complete description of variability. It is not. Two datasets can have the same IQR and look nothing like each other. One could be tightly clustered in the middle with a long tail on one side, the other could be uniformly spread. Always pair IQR with a visual check — a histogram or box plot tells you things the single number conceals.
Second, the 1.5 multiplier is not a law. It comes from John Tukey's work on box plots and is meant to catch mild outliers in approximately normal data. If your domain has known measurement error rates or naturally heavy-tailed distributions, 1.5 is arbitrary. I have seen people use 2 or 3 in those cases, and it is defensible. You should pick the multiplier based on your actual error profiles, not because a textbook says so. The biggest weakness of IQR is that it completely breaks down with very small datasets. If you have fewer than about 10 observations, the quartiles become unstable and the IQR can be zero or near-zero regardless of how spread out the data actually is. In those cases, range or standard deviation is more honest, even though they have their own problems with outliers. Another limitation worth noting is that IQR is not robust to the presence of extreme outliers in the same way people assume. A single massive outlier does not affect Q1 or Q3 much, which is the whole point, but it does shift the median slightly. More importantly, if your dataset has a bimodal distribution, the IQR will span the gap between modes and give you a misleading sense of spread. The middle 50% of the data might be concentrated in two tight clusters with nothing in between, and the IQR would suggest a wide dispersion that does not exist in either cluster.
Get the Full Details

For quick calculations in a spreadsheet environment, the numpy approach is cleaner than relying on Excel's built-in quartile functions because it makes the interpolation method explicit. With numpy, you specify whether you want linear interpolation or another method. Excel chooses for you and changes its choice between versions, which is a quiet source of reproducibility problems I have encountered more than once. If you need a reference implementation, the scipy.stats.iqr function in Python handles most edge cases cleanly, including the interpolation method selection. For R users, the IQR function is built in but again the underlying quantile algorithm can be checked with the type parameter. Both are open source and free to use. IQR remains useful because it is simple and resistant to extreme values. But it is a tool with specific conditions where it works well and where it does not. Knowing those conditions matters more than knowing the formula.