Meaning of Mean in Mathematics
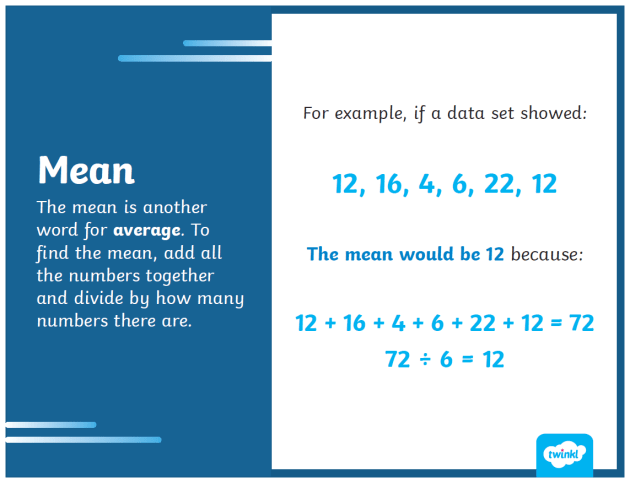
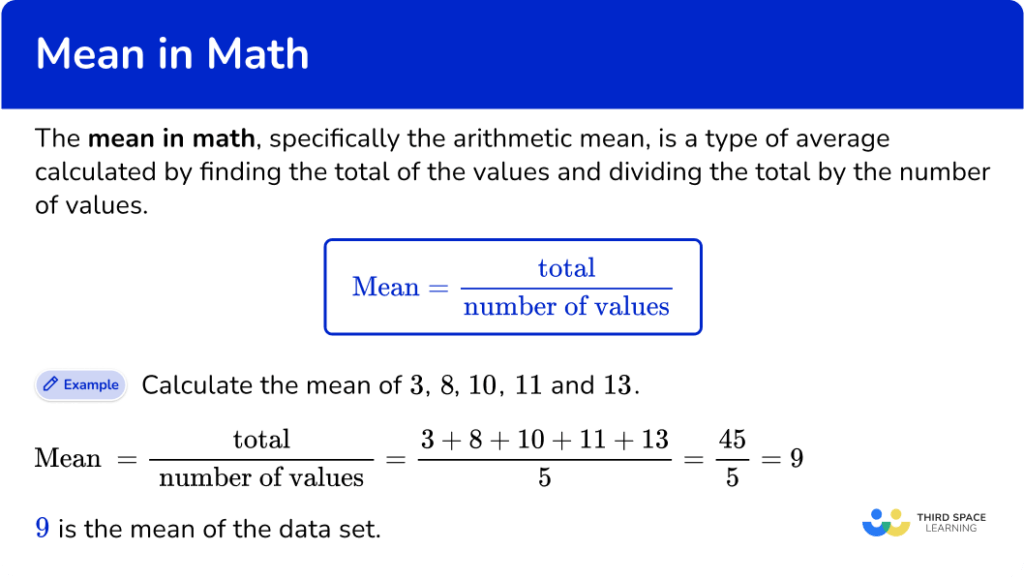
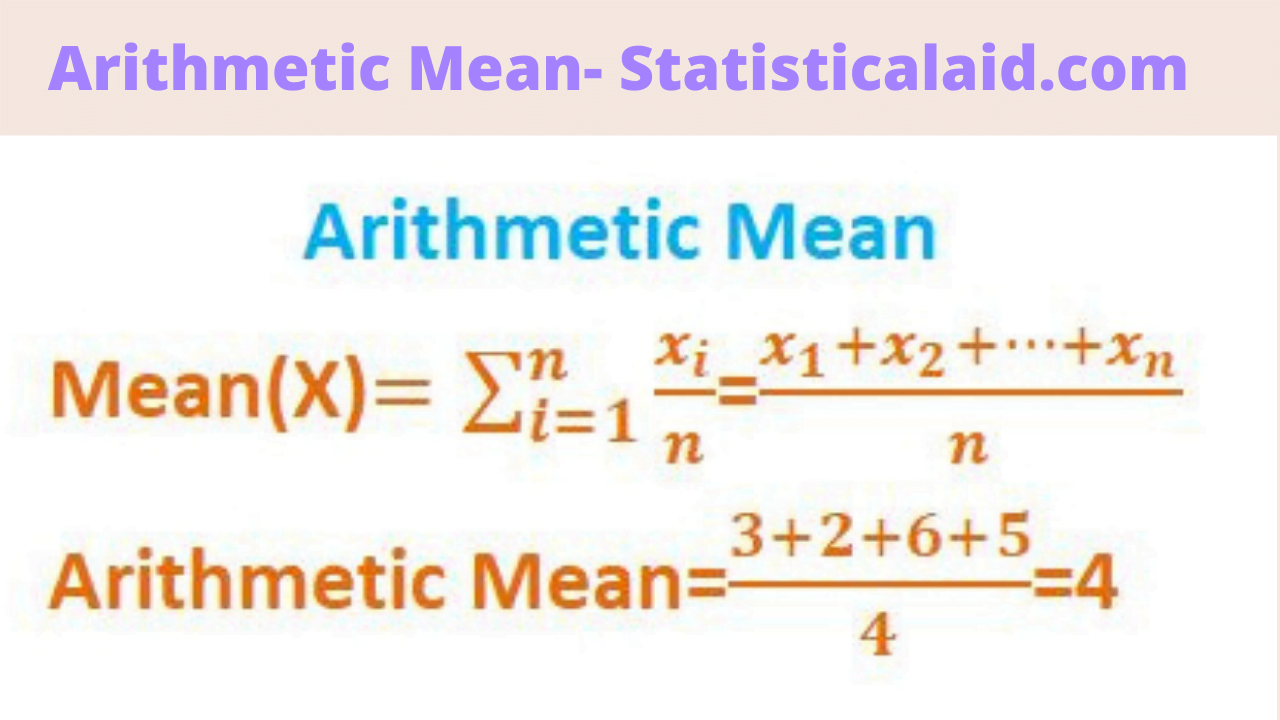
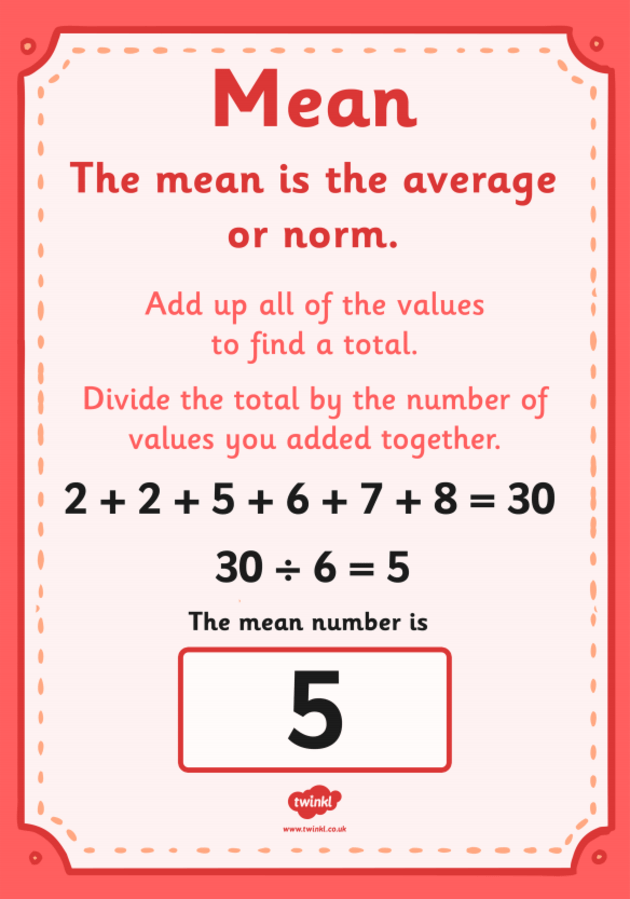
The word mean in mathematics has two completely unrelated definitions depending on the context. In everyday usage, it refers to a type of average you calculate from a set of numbers. In older or more formal mathematical language, mean describes something that is between two values or represents an intermediate relationship. The arithmetic mean, which is what most people mean when they say mean, is calculated by adding all values together and dividing by the count of values. Here is the formula: Mean = (Sum of all values) / (Number of values)
Take the numbers 4, 7, and 13. Add them to get 24. Divide by 3 and the mean is 8. That is straightforward enough. But the simplicity of that process hides a lot of practical problems, and I will get to those shortly. There are other types of means that show up regularly in real work. The geometric mean multiplies values together and then takes the nth root, where n is the count of values. You use it for growth rates, interest compounding, or anything involving multiplicative change rather than additive change. The harmonic mean is the reciprocal of the average of reciprocals. It comes up when dealing with rates, like average speed over a trip where each segment has a different velocity. I ran into this distinction head-on about three years ago while analyzing conversion funnel data for an e-commerce client. The client reported an average session duration of 4.2 minutes across their site. The arithmetic mean looked reasonable until I plotted the actual distribution. The median was 1.1 minutes. The mean was being dragged up by a small percentage of sessions lasting 20 to 40 minutes — mostly bots and people who left tabs open overnight. The reported 4.2 minute figure was technically correct but completely misleading for any business decision. I switched to reporting the median alongside the mean, and in some cases replacing it entirely with a trimmed mean that excluded the top and bottom 10 percent. That trimmed mean came out to 1.8 minutes, which was far closer to what a real human visitor experienced.
One thing beginners consistently miss is that the mean is extremely sensitive to outliers. A single extreme value can shift the mean dramatically without changing anything about the bulk of your data. If your dataset is {2, 3, 3, 4, 5, 100}, the mean is 18.5. The median is 3.5. The mode is 3. For this dataset, 18.5 tells you almost nothing useful about where most of the data actually sits. The mean is pulled toward the tail. This is called positive skew, and it is everywhere in real data — income, website traffic, transaction sizes, response times. Another nuance that does not get enough attention: the mean only captures central tendency. It tells you nothing about variance, spread, or the shape of the distribution. Two datasets can have the exact same mean and be completely different in every other way. Consider these two sets: {5, 5, 5, 5, 5} and {1, 3, 5, 7, 9}. Both have a mean of 5. The first has zero variance. The second has a standard deviation of approximately 2.83. Picking the mean as your only summary statistic throws away information. Always pair it with at least one measure of dispersion — standard deviation, variance, or interquartile range. The mean also breaks down in certain edge cases. With open-ended distributions, like age groups reported as "65 or older," you cannot calculate a precise mean because you do not know the upper bound. Some people approximate by assuming a value, but that introduces error. With zero or negative values in multiplicative contexts, the geometric mean becomes undefined or meaningless. If you have data containing negative numbers and you try to compute a geometric mean, you are going to hit complex numbers or errors depending on how many negatives there are.
Get the Full Details
Here is another practical scenario I deal with frequently. When aggregating ratios or rates across groups of different sizes, using a simple arithmetic mean of those rates gives you the wrong answer. Say Location A has 10 transactions with a 20% success rate and Location B has 1000 transactions with a 50% success rate. The simple mean of the rates is 35%. The true weighted average is much closer to 49.5%. This is why weighted means exist and why you need to think about what the weights should be before you calculate anything. The mean is also not appropriate for ordinal data. If you are rating something on a scale of 1 to 5, the mean is technically calculable, but it implies a level of precision that ordinal scales do not support. The median or mode is more honest for that type of data. I see this mistake constantly in survey analysis. People average Likert scale responses and report means to one decimal place, which sounds scientific but is statistically questionable.
Common Pitfalls and Workarounds
When working with real-world data, the main pitfalls revolve around assumption violations. The mean assumes your data is at least interval-scaled and that outliers are meaningful rather than erroneous. Neither assumption holds universally. Before calculating a mean, you should always check for data quality issues — entry errors, unit mismatches, duplicate records, and missing values that might be encoded as zeros or negative numbers. For skewed distributions, consider these alternatives depending on your goal: the median for robust central tendency, the trimmed mean for a balance between the arithmetic mean and median, or the mode if you need to identify the most frequent value. In financial modeling, I often use a combination — the mean for expected value calculations and the median for stress testing scenarios. The key takeaway is that the mean is a tool, not a truth. It is one specific way to summarize a dataset, and it has well-defined strengths and weaknesses. Understanding when it works and when it misleads is more important than knowing how to compute it.