Understanding the Median in Real Data Work
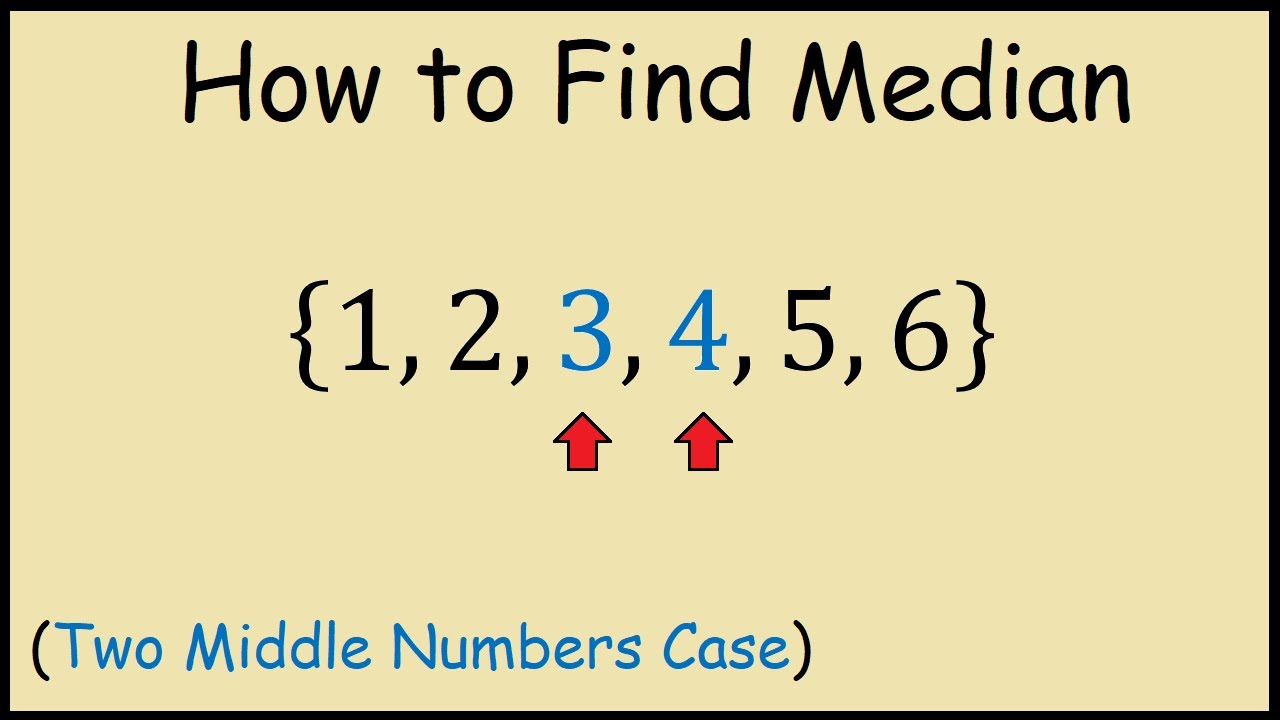
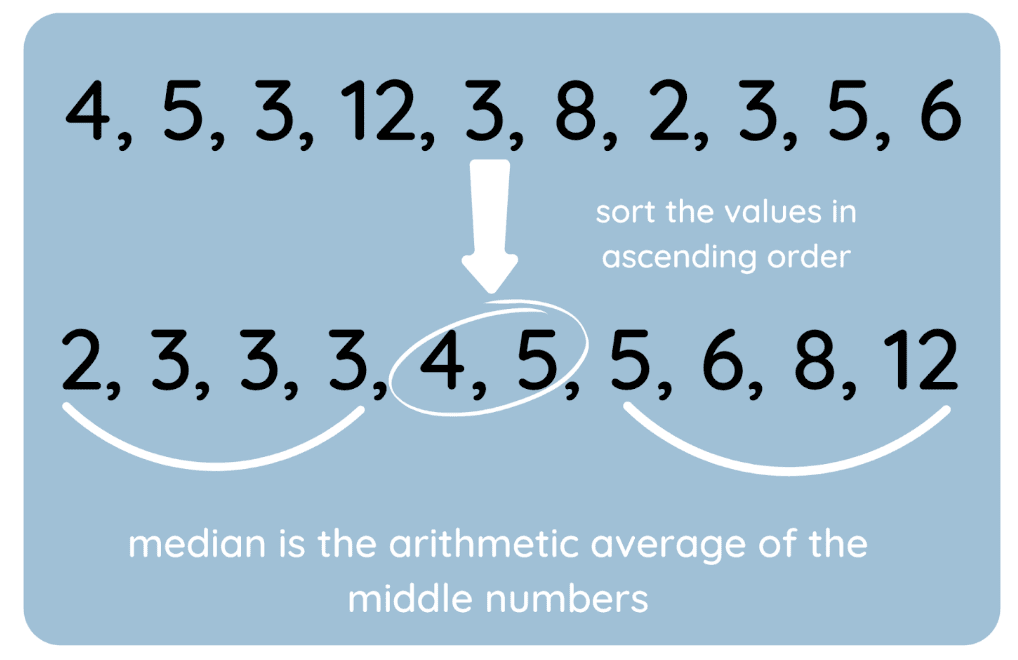
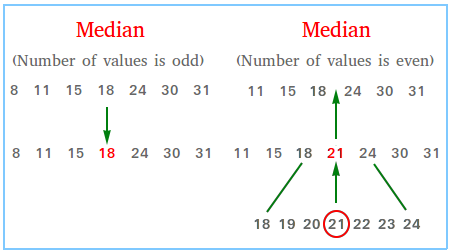
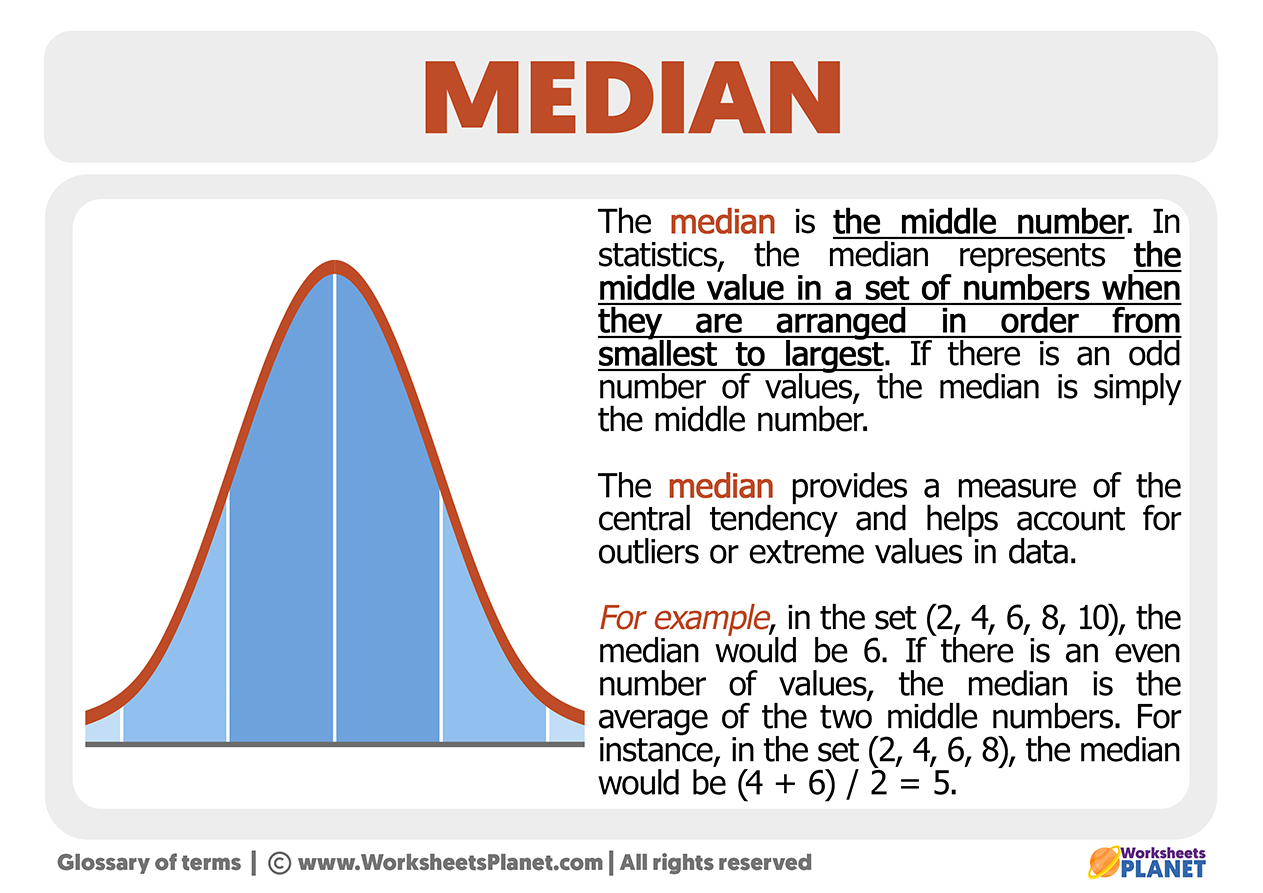
The median is the middle value in a sorted dataset. You arrange your numbers from smallest to largest, then pick whichever one sits in the center. If you have an even count, you average the two middle numbers. That's the textbook version. The practical version is messier. I've spent years cleaning and analyzing datasets for supply chain, healthcare, and finance teams. The median shows up constantly. It's the default go-to when means get dragged around by outliers. You'd be surprised how often people reach for the mean without thinking about it, then wonder why their dashboard numbers look wrong.What Is The Median
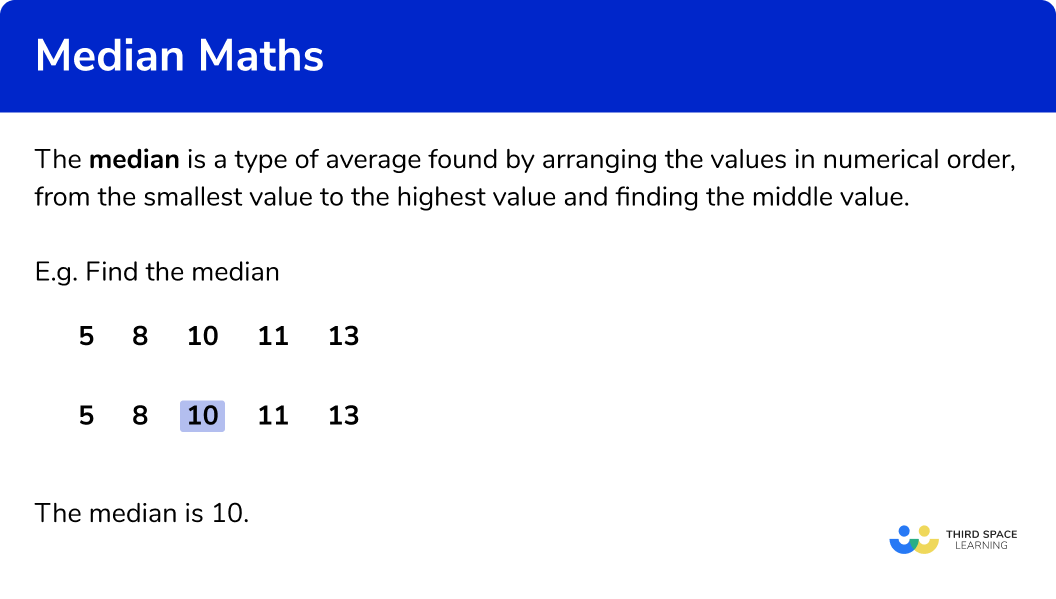
Let me walk through how this actually works in practice. Say you're looking at response times for a customer support ticketing system. You pull 15 timestamps, sort them, and find the eighth value. That's your median. Here's a quick example with a smaller set:3, 7, 9, 12, 15, 18, 22 3, 7, 9, 12, 15, 18 Tied values in small datasets. If you have something like 5, 5, 5, 5, 100, the median is 5. That's accurate, but it tells you almost nothing about the distribution. You're losing information. In these cases, reporting the median alongside a measure of spread — interquartile range, standard deviation, or just the full range — is essential.
Grouped or binned data. This is a common pitfall in business intelligence. When your data comes in buckets — say, age ranges like 18-24, 25-34, 35-44 — the median isn't directly computable from the bins alone. You need the raw data or at least the cumulative frequencies. I've seen analysts estimate the median by interpolating within the middle bin, which is acceptable as a rough approximation but introduces error that compounds when you're doing this repeatedly across thousands of segments. Very small samples. With fewer than five data points, the median is essentially arbitrary. One outlier shifts it noticeably. If you're working with N less than 10, the median probably isn't worth calculating on its own. Use it alongside other statistics or acknowledge the instability. Comparing medians across groups. Two datasets can have identical medians but completely different distributions. A common mistake in reporting is to highlight that "Group A and Group B both have a median of 42" and imply they're similar. They might not be. Always check the quartiles and the shape of the distribution.
Computing the Median Without Losing Your Mind
For small datasets, sorting by hand or in a spreadsheet is fine. For anything over a few thousand rows, you want automation. Here's what I actually use depending on the situation.Excel or Google Sheets: =MEDIAN(range). It's reliable for up to about 100,000 rows. After that, performance degrades noticeably. I learned this the hard way when a finance team tried running it on a 2-million-row dataset and waited four hours for a result that ultimately timed out. Python (pandas): df['column'].median(). This is fast, handles missing values automatically, and works on grouped data with a simple .groupby() call. A typical operation on a million-row dataframe takes about 0.3 seconds on standard hardware. SQL: There's no built-in MEDIAN() function in most databases. In PostgreSQL, you'd use a window function approach with ROW_NUMBER() and COUNT(). In SQL Server, you can use PERCENTILE_CONT(0.5). It's more verbose than the Python equivalent but gets the job done without exporting data.
Get the Full Details
R: median() does exactly what you expect. If you're working with the tidyverse, dplyr's summarise() with median() inside it chains nicely with other operations.