So You Keep Hearing About Outliers and It Keeps Breaking Your Analysis
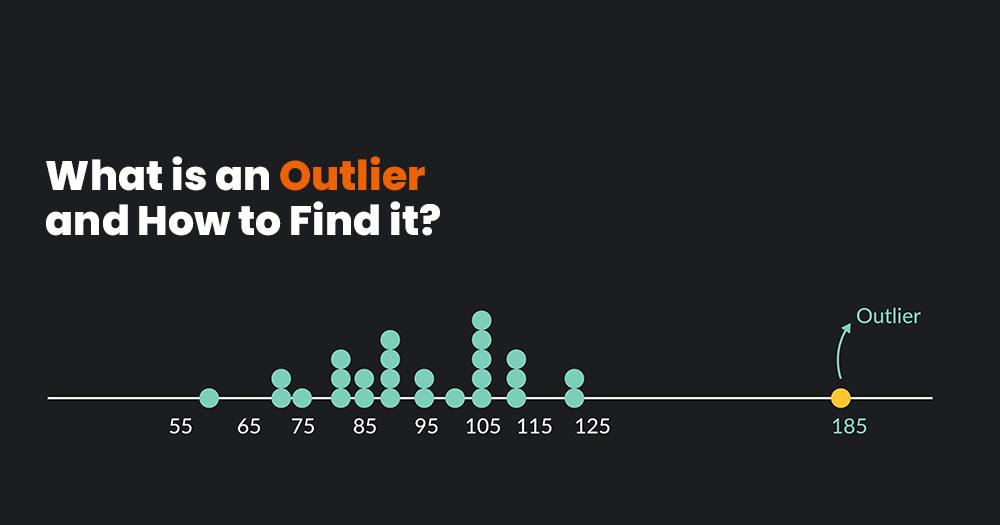
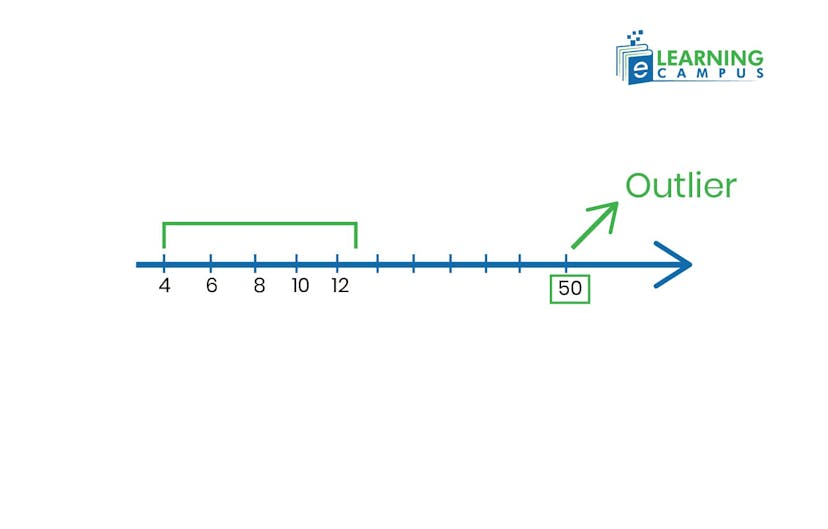
I spent six months trying to figure out why my regression models kept producing garbage results for manufacturing defect data. Turned out we had sensor drift happening during night shifts, and every third data point was completely normal but looked like noise to any standard detection method. I deleted the outliers, re-ran the model, and it suddenly made sense. But then another week came along and the same thing happened again with a different dataset. An outlier is simply a data point that sits far away from the rest of your dataset. That's it. That's the whole definition most textbooks give you. But the thing nobody tells you is that "far away" means something completely different depending on what distribution your data follows, and using the wrong criterion will either keep valid points you should discard or keep garbage you absolutely need to remove. The most common approach is the Interquartile Range method, sometimes called the IQR method or the Tukey fence approach. You calculate the first quartile, Q1, and the third quartile, Q3. The IQR is Q3 minus Q1. Any point below Q1 minus 1.5 times the IQR or above Q3 plus 1.5 times the IQR gets flagged. The 1.5 multiplier is arbitrary but it works reasonably well for roughly symmetric data. If you want a more aggressive filter, use 3.0. Some people call those extreme outliers and the 1.5 ones mild outliers.
Then there's the Z-score method, which assumes your data is normally distributed. You subtract the mean and divide by the standard deviation. A Z-score above 2 or below negative 2 is usually worth investigating, above 3 is almost always an outlier worth removing in most practical situations. The problem with Z-scores is they don't work when your data isn't normal. And most real-world data isn't normal. I learned that the hard way.
How to Actually Handle Them in Practice
Here's what I do now. First, I never just delete outliers blindly. I plot the data. A box plot gives you a quick visual check, but a scatter plot or time series plot tells you whether the outlier is random noise or a systematic problem. When I had that manufacturing issue, the box plot showed the outliers but didn't reveal that they all came from the same shift. That context changed everything. If your data has a clear bimodal or multimodal distribution, standard outlier detection will flag half your legitimate data points. In those cases, I split the dataset by mode first, then run detection within each cluster separately. This usually takes about 10 minutes for a small dataset and maybe 20 to 30 minutes for larger ones if you're doing it manually in Python or R. For normally distributed data, the modified Z-score is worth knowing about. Instead of using the mean and standard deviation, you use the median and the median absolute deviation. It's more robust and handles skewed distributions better. The formula is roughly 0.6745 times the absolute value of the difference between each point and the median, divided by the MAD. Values above 3.5 get flagged. This took me a while to pick up because most introductory courses don't cover it.
Get the Full Details
Counter-Intuitive Things That Trip People Up
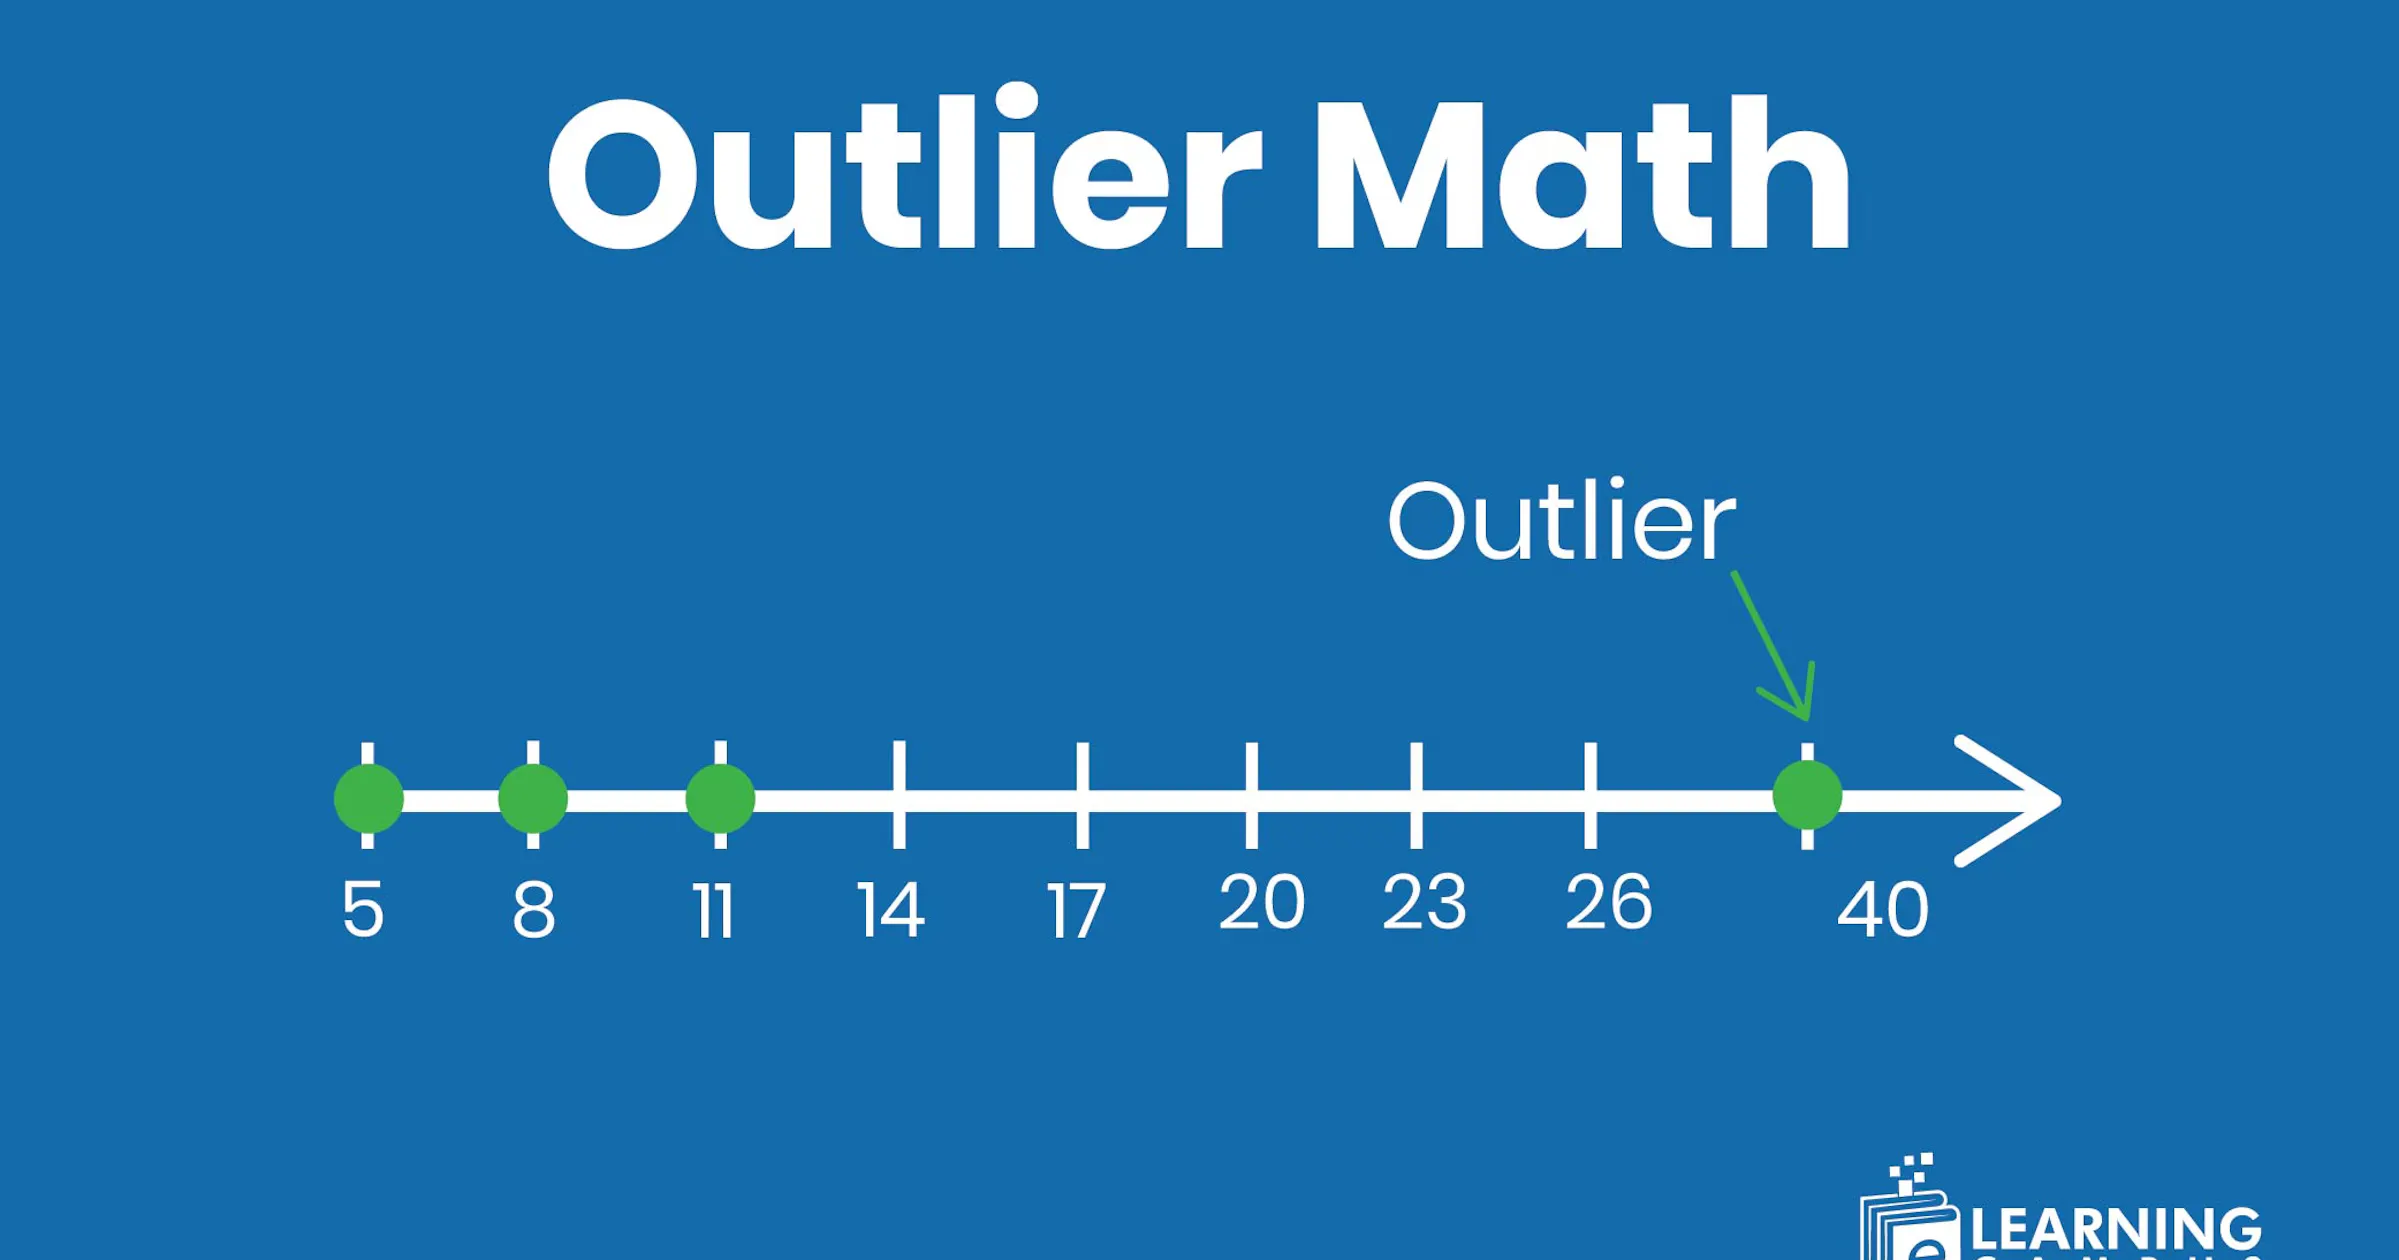
One thing that catches beginners off guard is that a single outlier can pull the mean and standard deviation toward it, which makes other legitimate points look like outliers by comparison. It's called masking. You end up with a cascade where the outlier distorts the statistics, and then the distorted statistics make normal points look extreme. The workaround is to use robust statistics like the median and MAD I mentioned, or to remove the most extreme point first, recalculate, and then check again. Another common pitfall is assuming outliers are always errors. Sometimes they're the most interesting part of your dataset. Fraud detection, fault prediction, network intrusion — in those cases, the outliers are the signal. Removing them would destroy the entire purpose of the analysis. You have to decide what question you're actually trying to answer before you decide what counts as an outlier. I worked on a project where we were analyzing customer churn. The outliers in our transaction data were the people who were about to leave. Standard deviation-based detection flagged thousands of them, but most weren't actually churners. We ended up using a combination of isolation forests and domain-specific thresholds. Isolation forests assign each point a score based on how easy it is to separate from the rest of the data. Points that are easy to isolate tend to be outliers. This method doesn't assume any distribution shape, which matters a lot when your features have very different scales and distributions.
When Standard Methods Completely Fail
Outlier detection breaks down in a few specific scenarios and it's worth knowing about them before you get blindsided. High-dimensional data is one of them. When you have dozens or hundreds of features, distance-based methods lose their meaning because everything ends up roughly equidistant from everything else. This is sometimes called the curse of dimensionality. Projection methods like PCA help but they introduce their own assumptions. In practice, I've found that reducing dimensions first and then applying IQR or Z-score methods on the principal components works acceptably for most datasets I've encountered. Time series data is another case where standard methods cause problems. Autocorrelation means each point is related to the previous ones, so a sudden spike might just be a delayed reaction to something that happened two weeks ago. Detrending and seasonally adjusting the data before running outlier detection prevents you from flagging perfectly normal cyclical behavior. I spent about three weeks debugging a model where the "outliers" were just predictable seasonal patterns that the detection algorithm mistook for anomalies.
My Go-To Workflow
Here's the practical sequence I follow, usually in a Jupyter notebook or RStudio: Load the data and check the shape and missing values first. Then plot a box plot for each numeric column. For each column that shows flagged points, plot the data against time or index to see if there's a pattern. Calculate the IQR fences and the modified Z-scores. Cross-reference the two methods — points flagged by both are more likely to be genuine outliers than points flagged by only one. Remove or cap the confirmed outliers. Re-run your analysis. Compare the results before and after. If the conclusions change substantially, document what you removed and why. This workflow typically takes me between 45 minutes and two hours for a medium-sized dataset with around 50 features. It's not fast but it prevents the kind of mistakes I made early on where I removed so much data that my sample size became unusable.

For automated outlier handling at scale, the IQR method with the modified Z-score cross-reference is the most reliable approach I've found. It doesn't require distributional assumptions and it handles both mild and extreme outliers reasonably well. The tradeoff is that it's not perfect and you still need to look at the data yourself. No automated method replaces visual inspection when you're dealing with anything more complex than a basic spreadsheet.