Understanding What A Punnett Square Actually Does
Most people encounter the Punnett square in a high school biology class and never think about it again. It is a simple grid used to predict the probability of offspring genotypes based on the genotypes of two parents. That is the textbook answer. The real answer involves a lot more nuance, especially when you start working with actual breeding programs or genetic counseling scenarios where the assumptions behind the square break down pretty quickly. I spent years helping people interpret pedigree charts and running through inheritance calculations for small animal breeders. The Punnett square shows up everywhere, but it also gets misused constantly. People treat it like a crystal ball instead of what it actually is: a visual shorthand for a probability calculation. There is a difference.
What Is The Purpose Of A Punnett Square
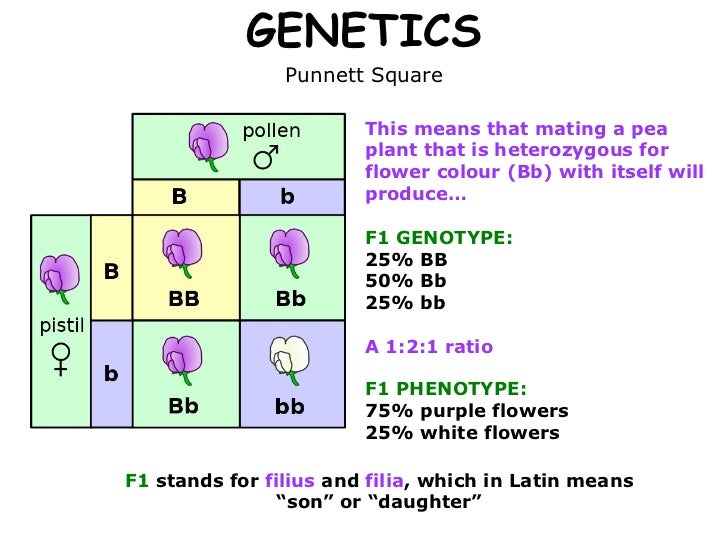
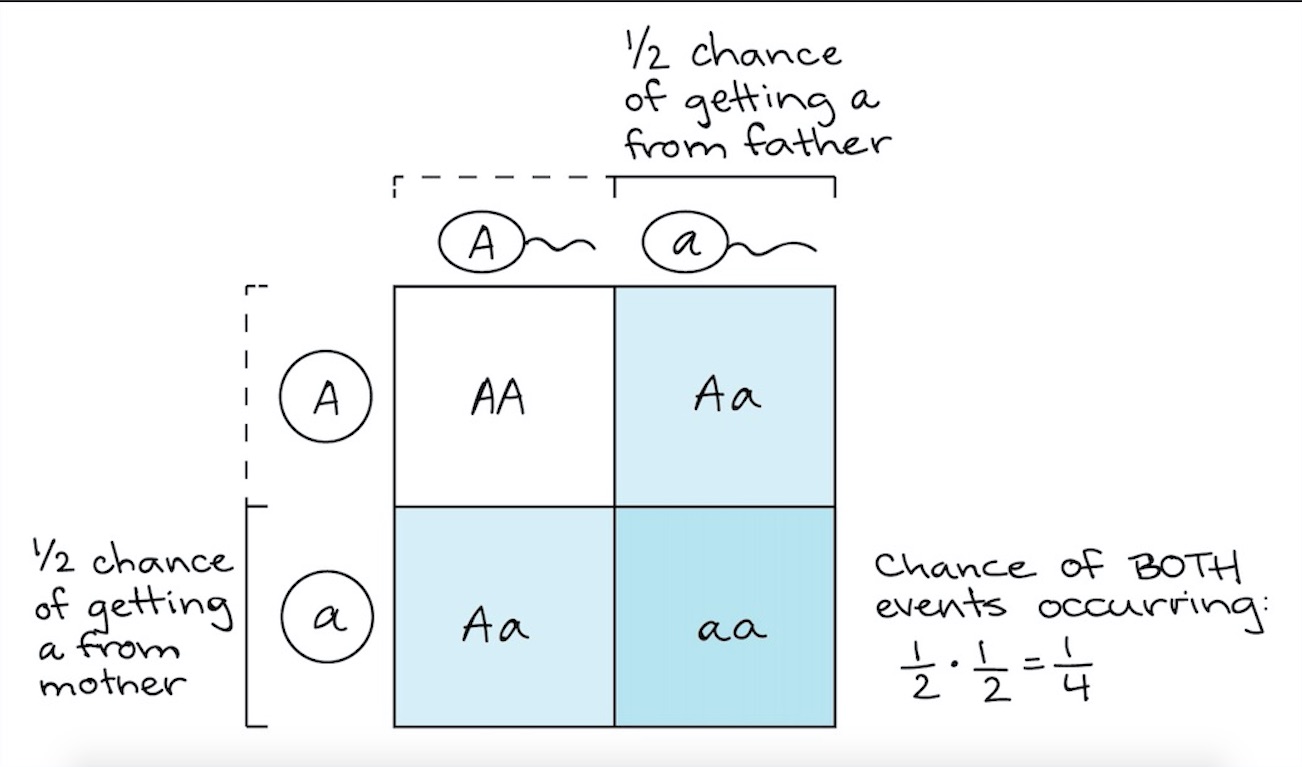
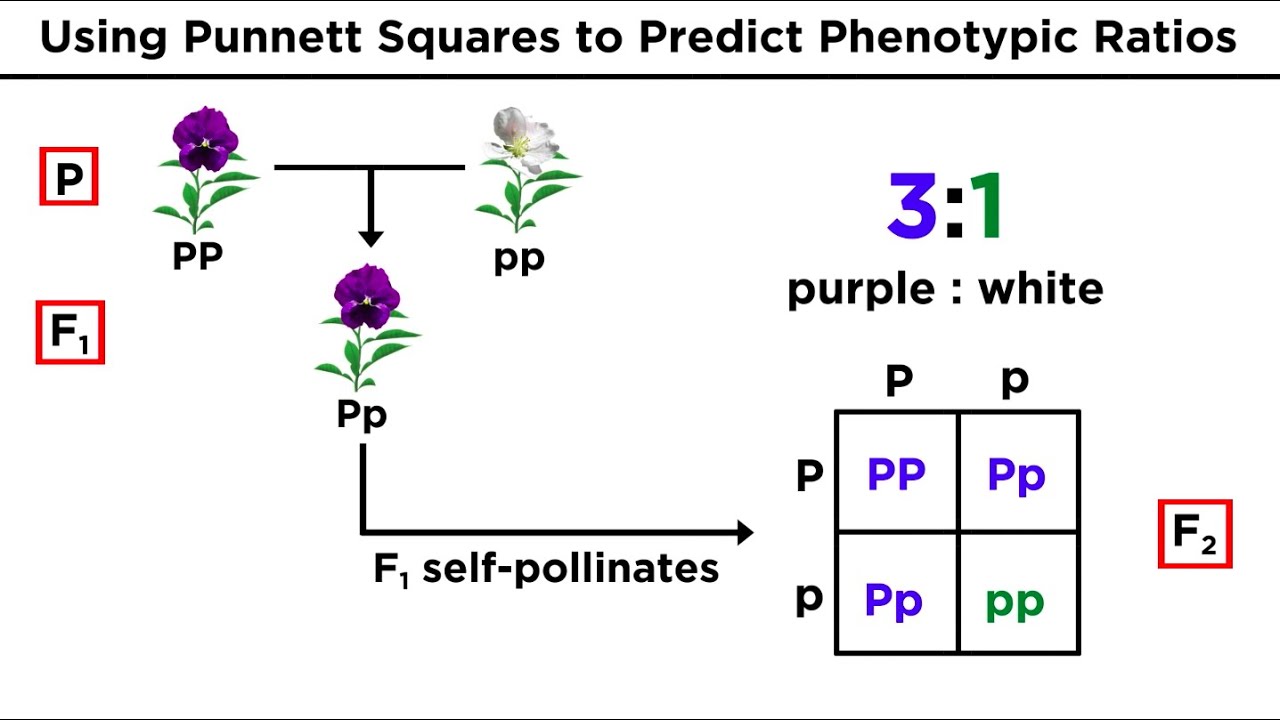
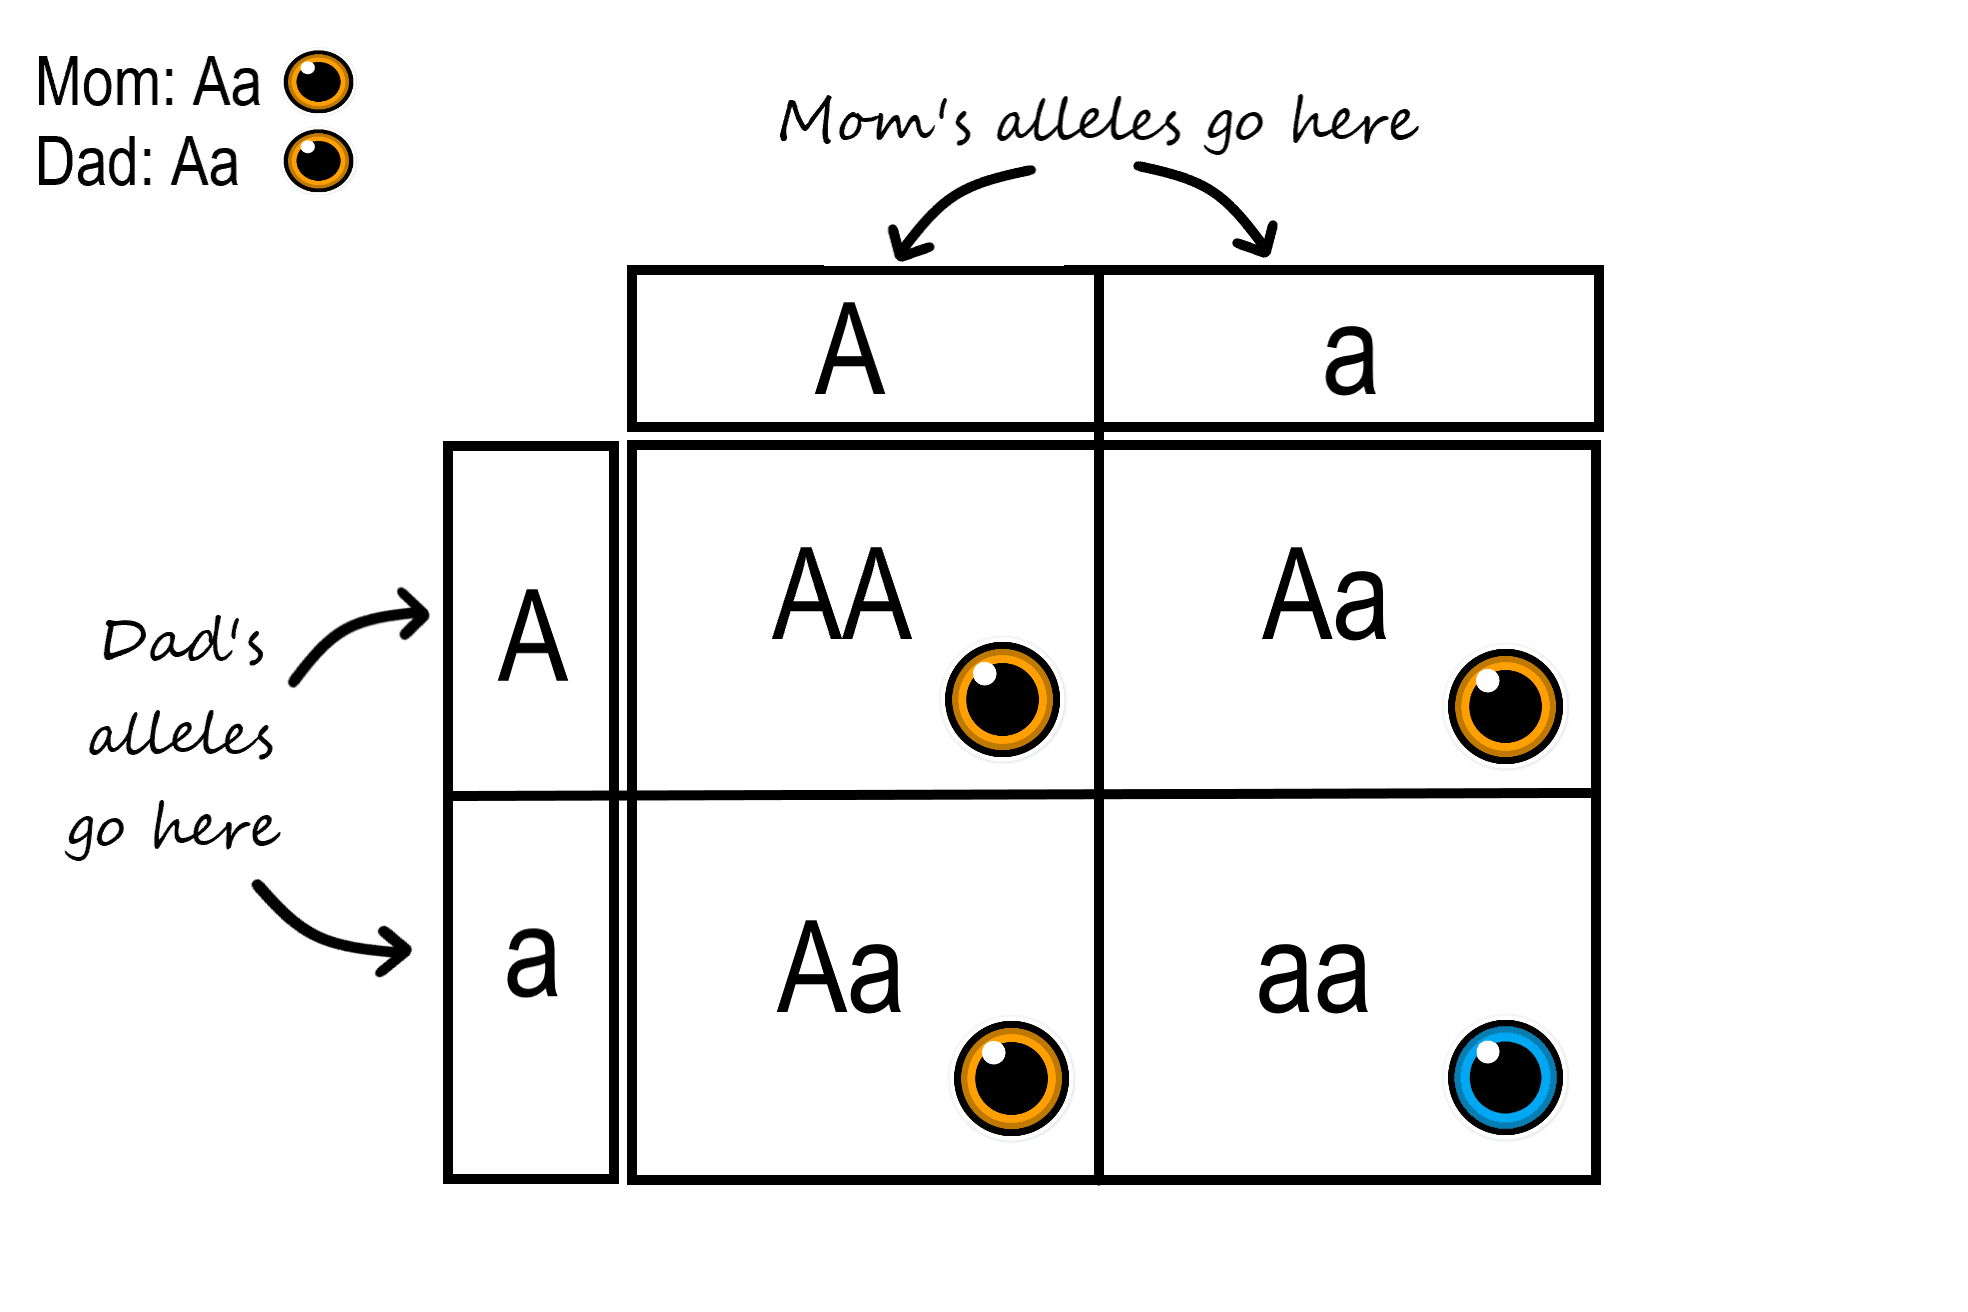
The purpose is straightforward once you stop treating it like a magic box. You are mapping out all possible combinations of parental alleles to see what genotypes can appear in the next generation and how likely each one is. A single gene with two alleles, like a basic dominant-recessive trait, creates a 2x2 grid. Four boxes. Each box represents a 25% chance outcome if both parents are heterozygous. That is all it is doing at its core. Here is how you set one up in practice. Write the alleles from one parent across the top. Write the alleles from the other parent down the left side. Fill in each box by combining the allele from the top with the allele from the side. For a cross between two heterozygotes, Aa x Aa, you get AA, Aa, Aa, and aa. One quarter homozygous dominant, one half heterozygous, one quarter homozygous recessive. The phenotypic ratio depends on whether the trait shows complete dominance, incomplete dominance, or codominance, which is where people start running into trouble. I remember working with someone trying to predict coat color in a litter of puppies. They had two parents that were both heterozygous for a recessive dilute gene. They knew the Punnett square gave them a 25% chance of a diluted pup in any given birth. But when their first litter came out with two diluted pups out of six, they thought the math was wrong. It was not wrong. Probability does not guarantee outcomes in small sample sizes. The square tells you what is likely over many generations, not what must happen in one litter. I had to explain that concept three times before it stuck. People want certainty from a tool that only provides likelihoods.
When The Punnett Square Works And When It Fails
The square assumes Mendelian inheritance: one gene, two alleles, independent assortment, no linkage, no epistasis, no environmental influence on expression. Any of those assumptions being violated and the square starts giving you answers that look precise but are essentially guesswork. That is the part most introductory courses do not emphasize enough. Linkage is one of the big ones. If two genes are close together on the same chromosome, they do not assort independently. A standard Punnett square will overestimate recombination frequency and give you ratios that do not match reality. I once ran calculations for a genetics project on fruit flies and got phenotypic ratios that were nowhere near what the square predicted. Turns out the two genes I was tracking were on the same chromosome about eight map units apart. The observed recombination rate was 8%, not the 50% the square assumed. I had to switch to a different method entirely and account for linkage distance. Polygenic traits are another place where the square falls apart. Height, skin color, disease risk for conditions like heart disease or diabetes — these involve multiple genes interacting in complex ways. A Punnett square with a few boxes cannot model that. You need quantitative genetics models instead. Using a Punnett square for polygenic traits is like using a ruler to measure the volume of a lake. The tool exists, it is just the wrong one for the job.
Get the Full Details

Incomplete penetrance and variable expressivity also break the simple model. A genotype predicted to show a dominant phenotype might not express it at all in some individuals, or it might express at wildly different levels. The square cannot account for that. It gives you genotypic ratios, and those ratios remain correct, but the phenotypic predictions become unreliable. I have seen people get tripped up by this in human genetics counseling situations where a parent carries a dominant disease allele and wonders why none of their children showed symptoms despite a 50% predicted chance per child.
Advanced Setups You Might Need
For dihybrid crosses involving two unlinked genes, you expand to a 4x4 grid with sixteen boxes. The classic 9:3:3:1 phenotypic ratio comes from this. Each parent produces four types of gametes, so you need sixteen combinations to cover every possibility. It gets tedious by hand, which is why some people use branching diagrams or the forked-line method instead. Both approaches give you the same answer faster once you know the process. Triploid organisms, sex-linked traits, and multiple allele systems require modifications to the standard square. For X-linked inheritance in mammals, you do not treat males and females the same way because males only have one X chromosome. A male with genotype X^h Y crossed with a carrier female X^H X^h requires a grid that accounts for the fact that sons inherit their X from the mother only. The square still works, but you have to be careful about how you set up the rows and columns. Set them up wrong and your results are nonsense. Mitochondrial inheritance does not use a Punnett square at all. Mitochondrial DNA is inherited maternally, so the father contributes nothing. The entire concept of combining two parental allele sets is irrelevant. I have seen this mistake come up repeatedly in introductory courses where students try to force a square onto problems that do not fit the model. Just recognize when the biology does not match the tool and move on.
Practical Workflow For Real Use
If you are working through a genetics problem, here is the process I actually use rather than the one most textbooks teach. First, write out the parental genotypes clearly with proper notation. Heterozygous is not the same as homozygous dominant and getting those mixed up invalidates the entire square before you even draw it. Second, determine the gametes each parent can produce. A heterozygote Aa produces A and a gametes. A homozygote AA produces only A gametes. This step is often skipped and leads to wrong grids. Third, draw the square and fill it in. Fourth, convert genotypes to phenotypes using the dominance relationships you established. Fifth, state the answer in terms of probability, not certainty. That fifth step matters more than people realize. Saying "there is a 25% chance" is completely different from saying "one out of four will show the trait." The first is accurate. The second implies a guaranteed distribution that does not exist in a single reproductive event. For problems involving three or more genes, the square becomes impractical. A trihybrid cross requires a 8x8 grid with sixty-four boxes. Nobody draws that by hand. The product rule handles these cases much faster. Calculate the probability for each gene independently and multiply them together. Three genes with simple dominance give you a 27:9:9:9:3:3:3:1 ratio, but you get there through multiplication, not by filling out a massive grid.
One thing I want to flag about using Punnett squares in modern contexts. With genome sequencing becoming cheap and accessible, breeding programs and clinical genetics often skip the square entirely and go straight to probabilistic models or even simulation software. The square is still useful as a teaching tool and for quick hand calculations on simple problems, but it is not the cutting edge of genetic prediction anymore. Understanding it is necessary though, because every advanced method builds on the same probability principles the square demonstrates visually.